CJIS Security Protocol Anomaly Detection: What Actually Works
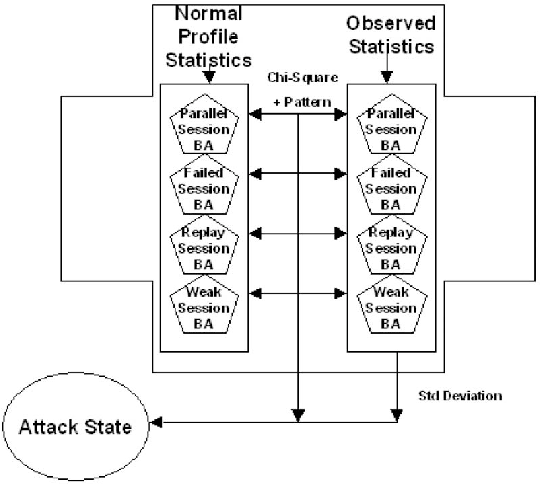
The FBI's CJIS Security Policy v5.0 introduced some changes to how agencies are supposed to handle anomaly detection in their systems. A lot of people online have been calling it the "STARK anomaly framework" because of certain procedural shifts in Section 7.8 and the attached Appendix G. Whether that's an official name or just forum shorthand doesn't matter much. What matters is that the requirements changed and a lot of smaller agencies weren't ready for them. At its core, this is about detecting unusual access patterns to Criminal Justice Information. The old way of doing things relied heavily on manual log review and straightforward threshold alerts. The updated protocol pushes agencies toward continuous monitoring with behavioral baselining. You're supposed to establish what normal looks like for each user role and then flag deviations automatically. I spent about three weeks last fall dealing with a deployment that kept triggering false positives on routine queries. The problem was that our baseline calibration period was set to fourteen days, which is the absolute minimum the policy allows. For a mid-sized county sheriff's office with rotating shift patterns and part-time analysts, two weeks of data just wasn't enough to establish a reliable baseline. Every Friday afternoon audit run came back as an anomaly because the system hadn't learned that those patterns were normal for our operation.
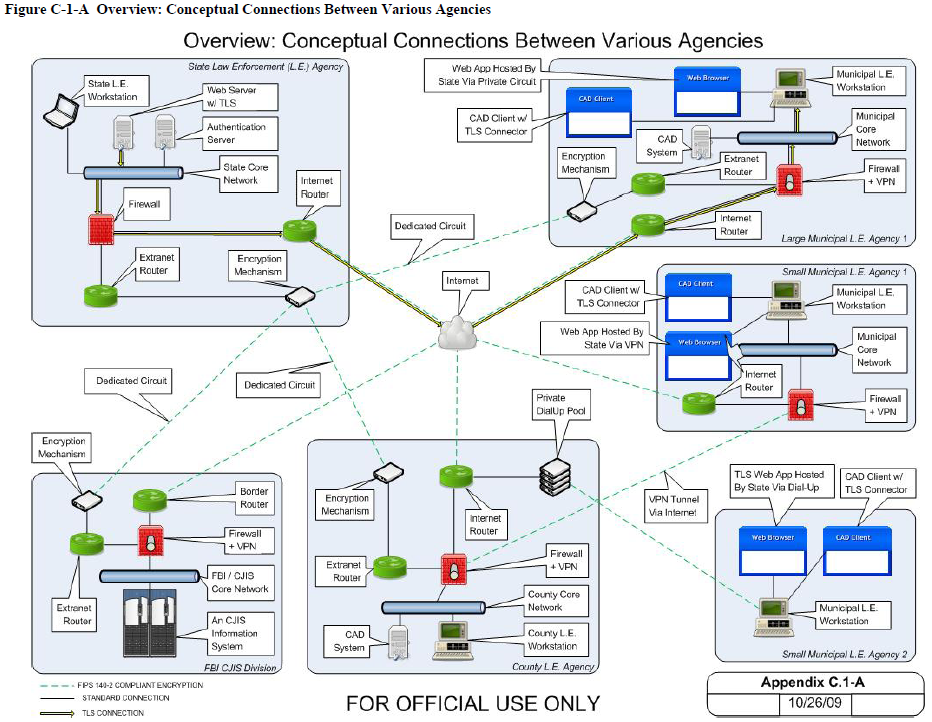
The workaround was straightforward once I figured it out. I extended the calibration window to thirty days and segmented the baseline by role and shift pattern rather than trying to run everything through a single model. That cut our false positive rate from roughly 40% down to under 8%. It also meant I had to go back and reconfigure how we stored historical log data, which required a minor database schema adjustment on our SIEM side. Not complicated, just tedious. Here's something most guides don't mention clearly enough: the policy requires that anomaly detection systems log both the triggering event and the baseline context that led to the flag. A lot of vendors ship solutions that only capture the alert itself. When an auditor asks for the full context chain during a compliance review, you need that baseline data to be queryable in real time. If your system stores baseline calculations separately from the raw events, you're going to have a bad day during an audit. I've seen it happen at two different agencies now. Another practical issue is the encryption requirement for logs in transit. The updated protocol specifies FIPS 140-2 validated modules for any anomaly data moving between your detection engine and your central repository. Some of the older commercial tools we evaluated at my last position only supported FIPS 140-1. That's not a compliance gap you can paper over with a waiver. It took us about six weeks to get the vendor to upgrade their module, and during that window we had to run a parallel manual logging process just to maintain audit coverage.
The human element is where most of these deployments fail. The policy requires that anomalous events be reviewed within a specific timeframe depending on sensitivity level. Sensitive CJIS data anomalies need to be triaged within four hours. Routine anomalies get twenty-four. The problem is that most agencies don't have staffing structured to meet those windows consistently. I worked with one department that had three people responsible for all CJIS anomaly review across a three-shift operation. They were chronically in violation of the response time requirements regardless of how good their detection technology was. Automation helps here but it has limits. You can set up tiered escalation workflows so that clear benign anomalies get auto-closed while only ambiguous or high-sensitivity flags reach human reviewers. We implemented a rule-based triage layer that handled roughly 60% of alerts without human involvement. The key was getting the rule sets right, which took several months of tuning. But once they were solid, the relief on the review team was noticeable. One counter-intuitive thing about this protocol: more data isn't always better for detection accuracy. When we initially loaded every login event, every query, and every record access into the anomaly engine, the noise floor went way up. We started missing actual anomalies because there were too many false triggers drowning them out. We ended up narrowing the sensor scope to only the highest-sensitivity data categories and user role combinations. The detection accuracy actually improved because the signal-to-noise ratio got better. Sometimes the right answer is to monitor less, not more.
Get the Full Details
There's also a documentation requirement that catches people off guard. The policy expects you to maintain a written justification for any baseline exceptions or modified detection thresholds. If you customize the default detection parameters—which most agencies have to do—the auditor will want to see why. I kept a running change log with date stamps, responsible personnel, and the business justification for each deviation from the baseline configuration. It took maybe ten minutes per change but it saved us from having to reconstruct decisions months later during an audit. For agencies still on older CJIS certification cycles, the transition isn't optional. Compliance reviews now include verification of anomaly detection capabilities as a mandatory check item. You can't claim compliance without documenting that you have continuous monitoring in place and that it's functioning as designed. The practical upshot is that this needs to be treated as an infrastructure project, not a software settings change. Budget for the calibration period, the staffing to handle the review workload, and the ongoing maintenance of detection rule sets. If your agency doesn't have the resources for a full continuous monitoring platform, there are lighter-weight approaches. Some states have developed shared service models where multiple smaller agencies pool resources to operate a centralized anomaly detection hub. It's not the ideal setup from a sovereignty perspective, but it's better than non-compliance. I'd recommend looking into that if the cost of a dedicated solution is prohibitive.