Sampling Distributions and Why Your Data Looks Normal
When you first encounter the Central Limit Theorem in a textbook, it reads like a mathematical promise. Take any distribution, pull enough random samples, and the means will cluster into a bell curve. That part is true, but the actual practice of using it in real analysis is messier than the theory suggests. I ran into this gap fairly recently when working with a logistics dataset. The delivery times were heavily right-skewed, nowhere close to normal, and the stakeholders wanted confidence intervals on the average turnaround. Standard error calculations assume normality, so I applied the CLT directly. The result was garbage. The sample sizes per route varied between 12 and 40 observations, and the skew was severe. The theorem was technically correct, but the approximation was poor at those sample sizes for that distribution. The fix wasn't complicated. I switched to bootstrapping the means. Resampled each route's data with replacement, ran 10,000 iterations, and took the 2.5th and 97.5th percentiles as the confidence bounds. It took about four minutes in R instead of the thirty seconds a textbook formula would have given me, but the intervals were accurate. The CLT still applies, it just needs a reality check on how big your n actually is relative to how non-normal your underlying distribution is.
The Central Limit Theorem Equation Unlocking The Secrets Of Statistical Analysis
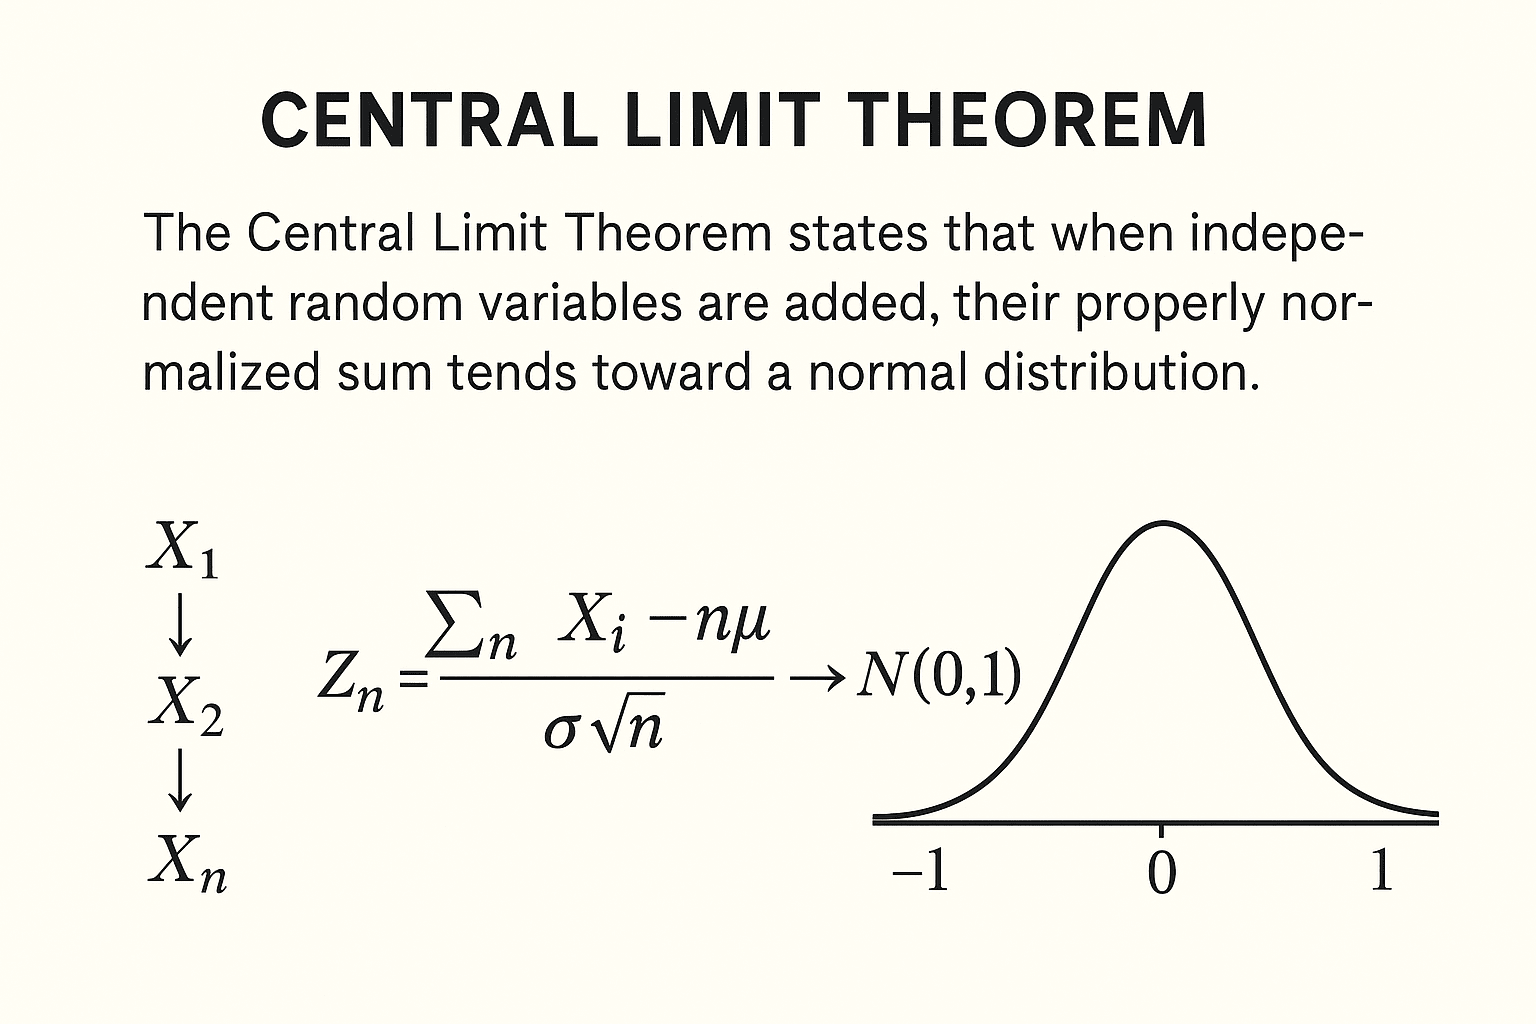
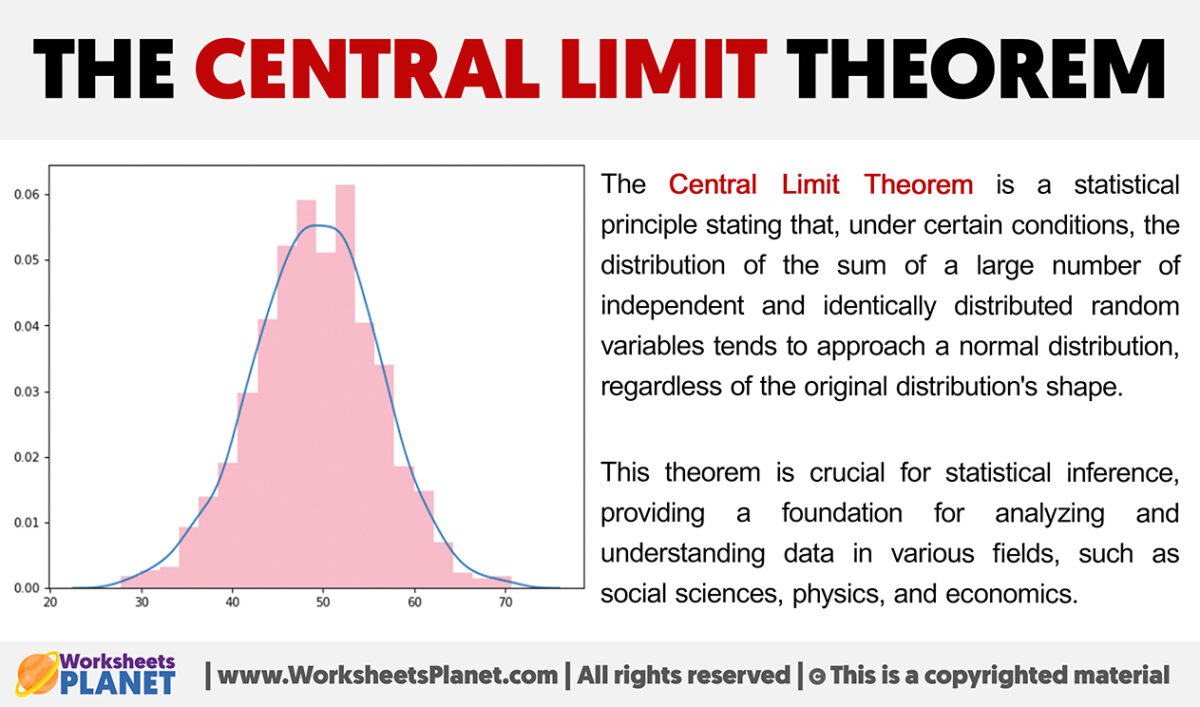
The formula most people memorize is standard error equals population standard deviation divided by the square root of the sample size. That's the shorthand version, and it's useful for quick estimates, but it leaves out the part that matters most: the sampling distribution of the mean approaches normality as n increases, regardless of the population shape. The speed of that convergence depends entirely on the population's skew and kurtosis. A uniform distribution reaches acceptable normality around n = 30. An exponential distribution needs n = 50 or more. A lognormal distribution with a high shape parameter can require several hundred observations before the sampling distribution of the mean looks remotely Gaussian. I've seen analysts treat n = 30 as a universal threshold. It isn't. There's no magic number that works across all distributions. The rule of thumb exists because it was convenient for textbook examples, not because it's a law. When your data has heavy tails or extreme outliers, the convergence drags. I learned this the hard way with a financial returns dataset where the population had fat tails from occasional market crashes. The sampling distribution of the mean stayed non-normal well past n = 100 per group. A Kolmogorov-Smirnov test rejected normality even at n = 150. What worked was switching to a t-distribution based confidence interval with estimated degrees of freedom from the data, which accounted for the excess kurtosis without requiring a transformation. The equation itself is straightforward, but the assumptions buried in it are where most people get tripped up. The samples need to be independent and identically distributed. That sounds obvious until you're dealing with time series data where observations are autocorrelated. If your data points influence each other, the effective sample size is smaller than the raw count. I worked on a project analyzing sensor readings from a manufacturing line where the readings were taken every second. The CLT would have overestimated precision dramatically if I'd used the raw n of 86,400 observations per day. After calculating the autocorrelation and adjusting the effective sample size, the true n dropped to roughly 2,000. That changed the confidence intervals substantially.
Another thing textbooks don't stress enough is that the CLT applies to the sampling distribution, not to your raw data. People routinely confuse the two. They take a small skewed sample, apply the CLT to justify a t-test, and call it done. The theorem says nothing about the distribution of individual observations. It says the distribution of sample means will approximate normality given sufficient repetitions. If you only have one sample of 25 skewed observations, the CLT doesn't rescue you. You need either a larger sample or a non-parametric approach. In practice, I default to checking three things before applying anything that relies on normality assumptions. First, I plot the histogram of the raw data and note the skew. Second, I look at a Q-Q plot of the sample means if I can generate them through simulation. Third, I run a Shapiro-Wilk test on the means, not the raw data. If the means pass that test, I proceed. If not, I switch to bootstrapping or a robust method. This takes maybe five extra minutes but prevents you from publishing results that fall apart under scrutiny. There are also edge cases where the CLT breaks down entirely. Distributions without a defined mean or variance, like the Cauchy distribution, will not converge to normality no matter how large your sample gets. The sample means from a Cauchy population remain Cauchy distributed. This came up when I was reviewing a paper that used CLT-based inference on a dataset with extreme values that effectively made the variance undefined. The authors never checked this assumption. The results were misleading.
Get the Full Details
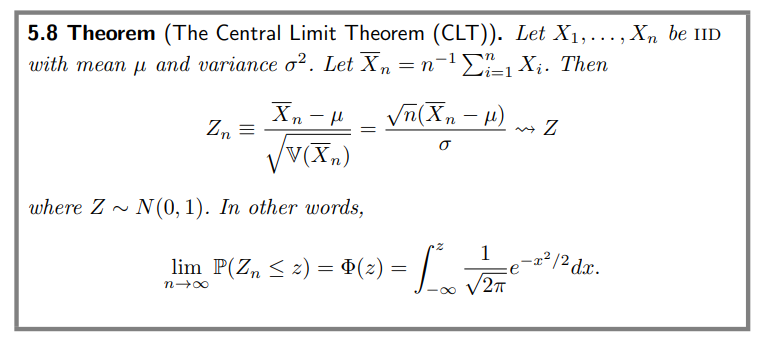
For most practical work, the theorem is reliable, but treating it as a blanket solution is where problems start. The equation itself is simple enough to write on a napkin. Understanding when it applies, when it applies poorly, and what to do instead when it fails is what separates people who use statistics from people who understand them. I've spent years watching the same mistakes repeat because the shortcut is easier than the check. It's worth doing the check.