Apache Cassandra and What It Actually Changed About How We Build Systems
Most people treat Cassandra like a museum piece now, but it still shapes how distributed systems are designed. The shift wasn't about being NoSQL first. It was about answering a question most database projects never asked: what happens when you need to write millions of operations per second across multiple geographic regions and you cannot afford to lose data during a network partition? The term refers to the ripple effect from a project Facebook began internally around 2008. They needed an inbox search system that could handle billions of messages without relying on a single master node. Existing relational databases at the time did not solve that particular failure mode well. That internal project used ideas from Amazon's Dynamo paper and Google's Bigtable paper, combined them, and released the result as an open source system called Cassandra. The effect was not that Cassandra itself became the default database for every company. The effect was that it proved a mature, production-grade system could be built around event-driven consistency, decentralised write paths, and repair mechanisms that operated asynchronously. After Cassandra gained attention, the entire category of NoSQL databases broadened. Systems like Couchbase, ScyllaDB, and later DynamoDB on AWS all borrowed design decisions directly from that era. The shift happened because Cassandra showed teams that you could build a database without a global master, distribute data using consistent hashing, and still make writes feel reliable by using a combination of quorum math and anti-entropy repair. Prior to that, many engineering teams assumed strong consistency and central coordination were non-negotiable. Cassandra made that assumption look like a habit instead of a law.
I do not recommend Cassandra as a general-purpose replacement for PostgreSQL or MySQL. The system has real limitations, and the wrong workload will make it painful. If you are building a simple application with moderate traffic, normal relational tables will serve you better. Cassandra is valuable when you need high write throughput, predictable latency under heavy load, and graceful degradation during partial outages. That combination is rare outside of messaging platforms, analytics pipelines, and systems where availability beats strict accuracy during network disruptions.
Core Concepts You Need Before Touching The System
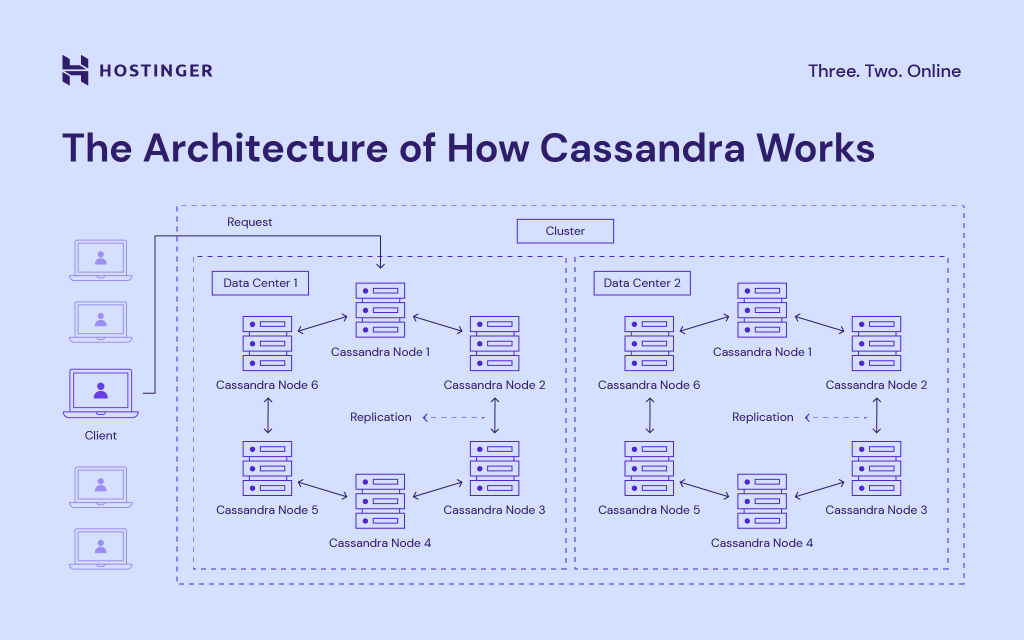
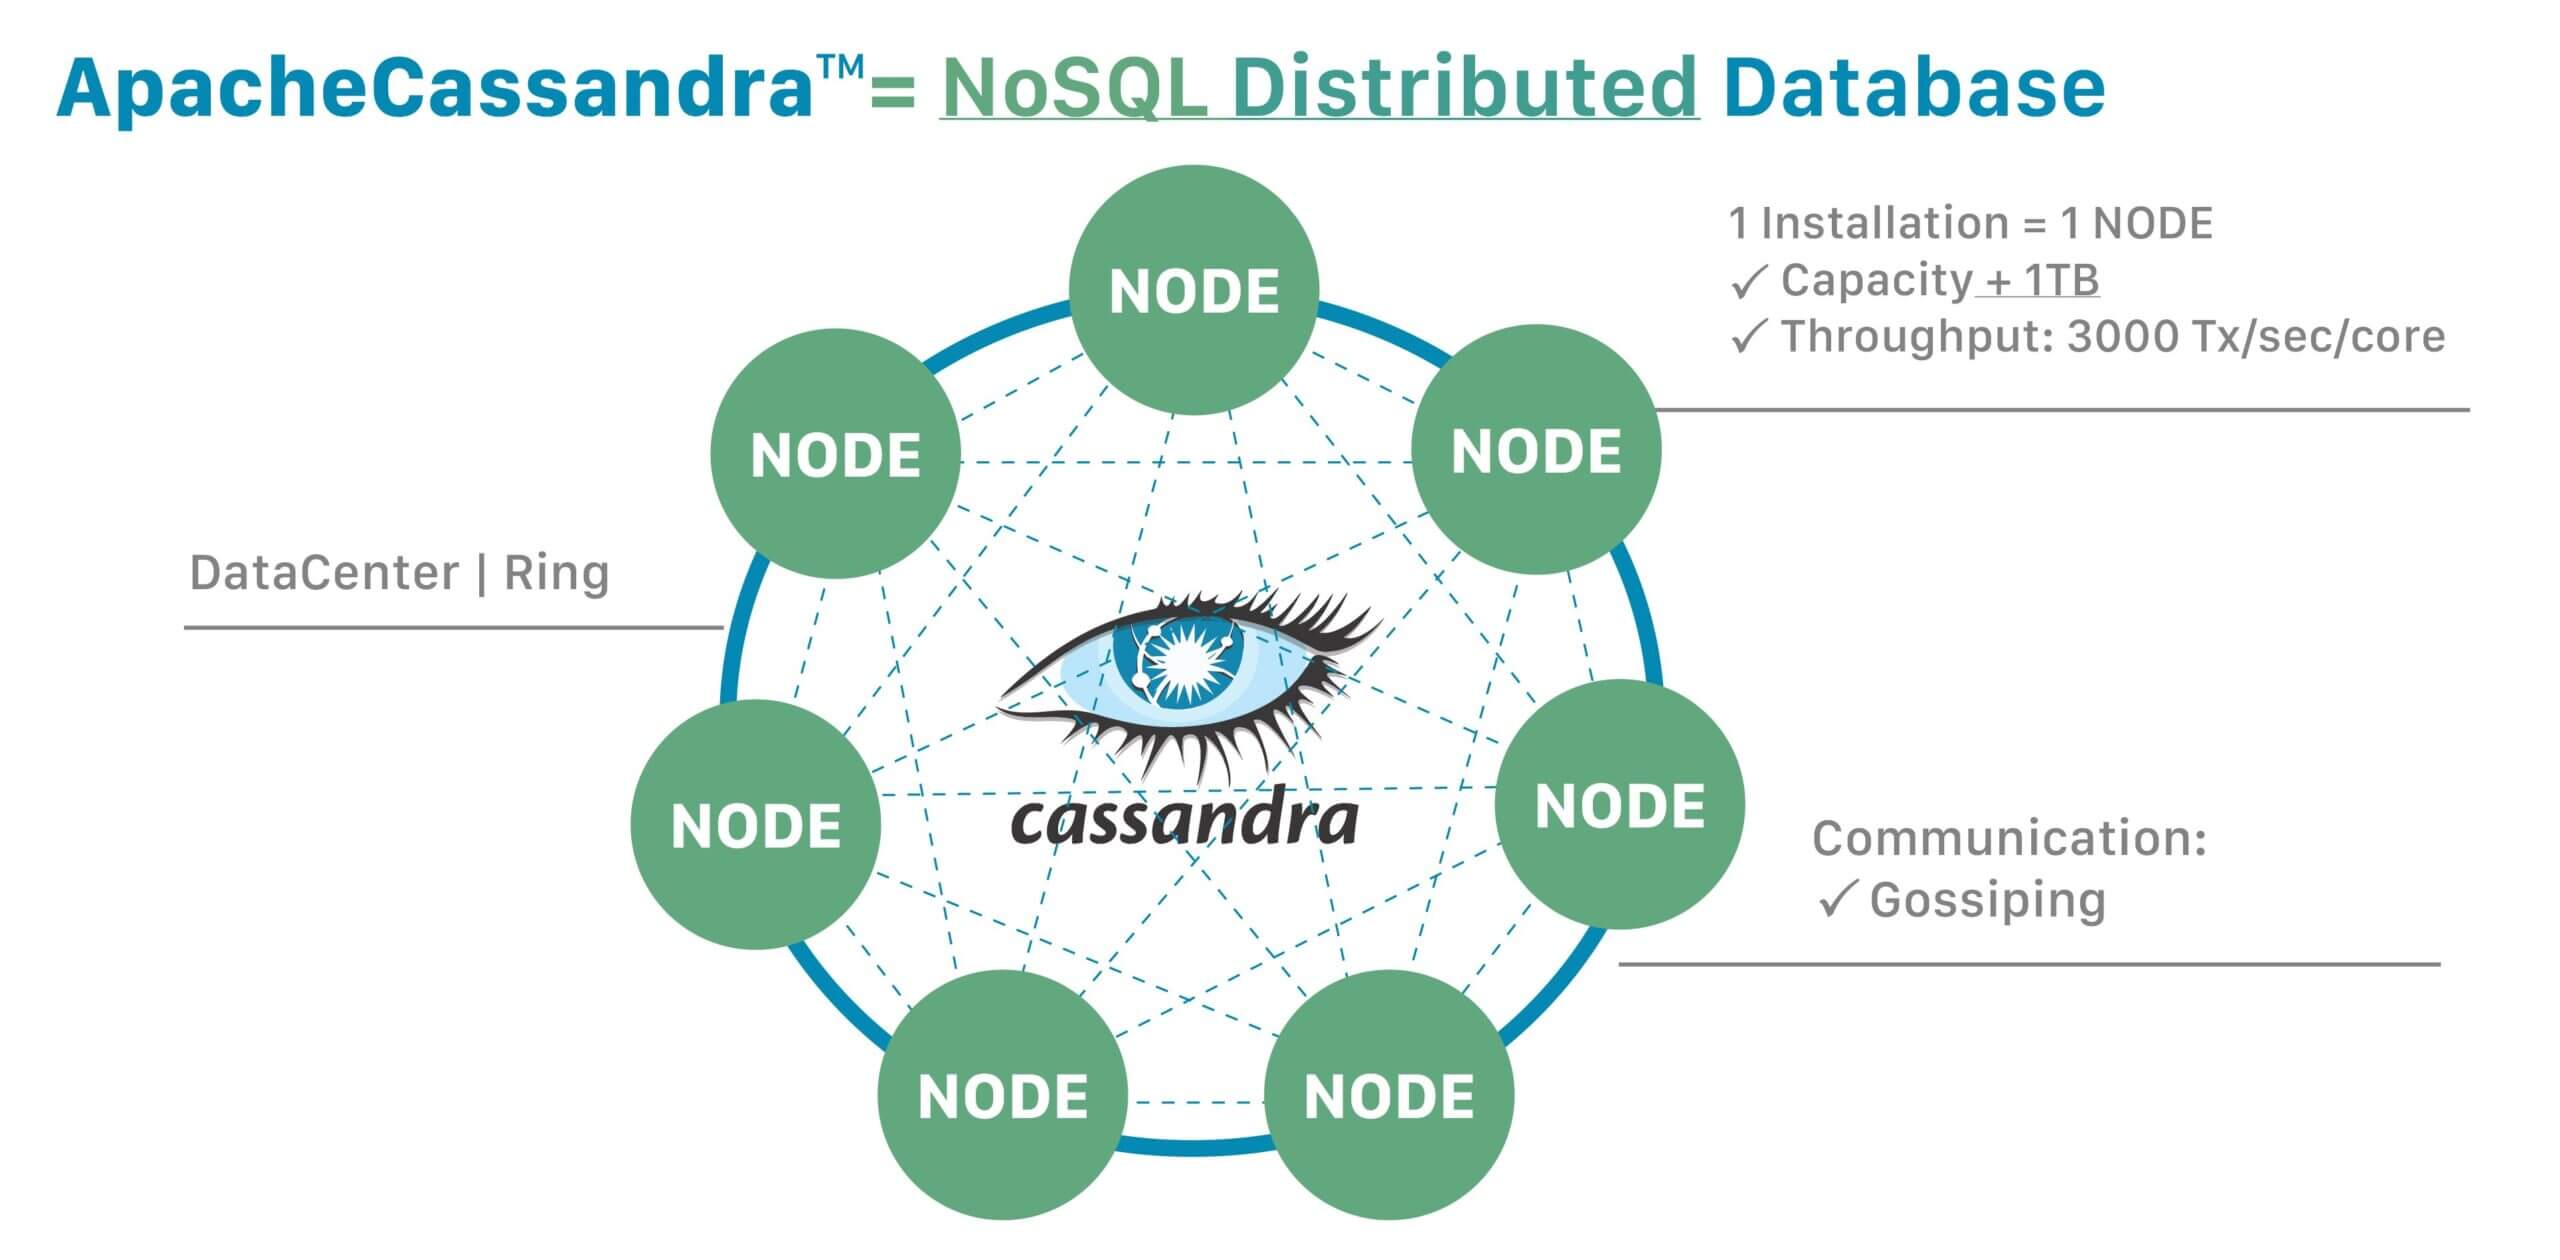
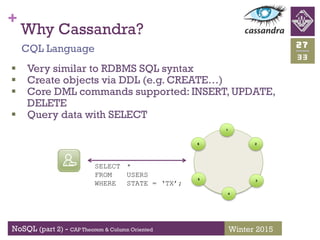
Cassandra uses a ring architecture. Every node in a cluster holds a segment of the key space, determined by a hash function. Data placement follows consistent hashing, so adding or removing nodes only reshuffles a small portion of the keys instead of moving everything at once. This design choice reduces repair time during scaling events and keeps write paths local. The storage model is column-oriented but not row-agnostic. You define a schema upfront, and each row consists of columns grouped by clustering order. The clustering key determines how data is sorted on disk within a partition. That sorting matters for read performance. If you query a partition without using the clustering key correctly, Cassandra may have to scan more rows than necessary. That is different from how relational databases handle index scans, and it catches people off guard. Consistency in Cassandra is configured per write and per read using quorums. The three main options are ONE, QUORUM, and ALL. Quorum means the majority of replicas involved in a key must acknowledge the operation. The formula is simple enough, but many engineers misapply it. Setting everything to QUORUM everywhere can slow writes significantly without preventing all consistency problems. You often get better results by combining different consistency levels with tuning the read repair settings and scheduling anti-entropy checks.
Get the Full Details
Writes in Cassandra are append-heavy. Each mutation becomes a commit log entry and a memtable update. The memtable flushes to disk as an SSTable periodically. Compaction then merges SSTables to remove expired data and tombstones. Tombstones are markers left behind when you delete rows. They cause problems if you delete large ranges frequently, because reads still encounter them during compaction. This is one of the less obvious pitfalls. People assume deleting a million rows is harmless until they see read latency spike during major compactions.
What Happens During Real Failures
One of the reasons teams choose Cassandra is that it handles partial failures predictably. If a rack loses power, the remaining nodes continue serving reads and writes. Requests routing to missing replicas fall back to other replicas, depending on your consistency level and the token allocation. This behavior is not automatic magic. You have to understand your replication factor, your data center topology, and how your client library routes requests. I ran into a specific problem during a production migration where a custom token distribution created an imbalanced ring. Some nodes held far more keys than others because the cluster had grown through rolling upgrades with inconsistent parameter changes. The result was hot spots that looked like single-node failures under heavy load, even though the cluster itself was healthy. The fix involved rebalancing the tokens and re-seeding the overburdened nodes from peers that held cleaner splits. That process took about six hours for a twenty-node cluster, and I learned to monitor per-node latency distributions more carefully after that. Normal average metrics masked the skew entirely. Another common issue appears with time-series data models. Using timestamps as part of the partition key is straightforward at first, but it creates singleton partitions that defeat Cassandra's strength. Singleton partitions remove parallelism and make compaction inefficient because each partition becomes its own file. A better pattern for time-series workloads is to bucket timestamps into larger windows, like hour-level or day-level partitions, and store related measurements within those buckets. This approach reduces the number of partitions and keeps data locality sane. It also changes how you write queries, which is intentional. Cassandra forces you to model queries around access patterns instead of relational joins.
Practical Setup And Operational Details
Installing Cassandra today usually involves either the official distribution or a managed option like DataStax Enterprise or ScyllaDB. The installation itself is straightforward. The hard part is configuration. The default settings work for development. They do not work well for production without adjustments to JVM heap size, gc_gen_inc_mode, and network settings. The recommended heap is generally between four and eight gigabytes. Going much higher introduces long garbage collection pauses that kill latency numbers. Monitoring is essential. Tools like Prometheus with cAdvisor-style metrics, or DataStax's own monitoring stack, help track compaction throughput, repair progress, and node health. Without these, you are flying blind. I track write_coalescing_count, memtable_flush_queue_size, and native_transport_requests_handled. Those three give a quick read on whether the cluster is accepting work efficiently or falling behind. Backups rely on snapshotting and incremental repair. You create snapshots through nodetool, copy them to offsite storage, and restore from them during recovery. Incremental backups reduce the window of data loss but increase disk usage. The tradeoff is worth it for production systems that store customer-facing data. Point-in-time recovery is possible if you combine snapshots with commit log archival, though the exact process depends on your version and compaction strategy.
When Cassandra Fails Completely
Cassandra is not suitable for every scenario. It struggles with complex ad-hoc queries, multi-table joins, and reporting workloads that require aggregations across arbitrary dimensions. If your application demands analytical flexibility, you are better off using a data warehouse or a purpose-built OLAP system. Cassandra can feed such systems with CDC streams, but it should not sit at the center of the analytics pipeline. Consistency guarantees also weaken under certain conditions. If you set read and write consistency below quorum, you may receive stale data. The system does not warn you explicitly. It returns whatever the chosen consistency level allows. This behavior is documented, but it surprises teams that expect automatic conflict resolution at every layer. Conflict resolution in Cassandra is ultimately a business logic problem. The database provides tools like last-write-win timestamps, vector clocks in some configurations, and application-level merge strategies, but it does not resolve semantic conflicts for you. Another hard limit involves schema changes. Altering a schema in Cassandra is slow and can block operations if not planned carefully. Rolling schema migrations across large clusters require staged rollouts and thorough testing. This is a known constraint, and the community has improved the tooling around it, but it remains a factor in capacity planning. Do not treat schema changes as cheap operations.
Alternatives Worth Considering
If your requirements resemble Cassandra's but you want easier operational overhead, managed offerings from major cloud providers abstract much of the infrastructure complexity. They trade flexibility for convenience. ScyllaDB is an open source alternative that shares Cassandra's data model but uses C++ instead of Java, which improves throughput and reduces latency for the same hardware. It is not a drop-in replacement due to driver compatibility nuances, but it handles many workloads well. For teams that need strong consistency and relational features alongside distributed scale, a modern relational database like CockroachDB or YugabyteDB provides a different tradeoff profile. These systems use distributed SQL architectures that preserve ACID semantics across nodes, which Cassandra deliberately relaxes for availability. Neither approach is universally superior. The choice depends on whether your application values consistency or partition tolerance more heavily under failure conditions.
What To Do Next
If you want to explore this further, the official Apache Cassandra documentation is the primary reference. You can download the latest release from the Apache website, where the source and binary distributions are hosted directly. The documentation includes installation guides, configuration references, and operational procedures. For hands-on practice, running a local three-node cluster using Docker images helps you understand ring behavior and replica placement without committing to production infrastructure. Start with a simple key-value workload. Model a single entity with clear partition keys, observe how writes distribute across nodes, and watch compaction happen in real time. Then move to a time-series pattern and measure how query performance changes when you adjust clustering keys. These exercises reveal the practical implications of the design choices faster than reading about them. The Cassandra Effect was never just about one database. It was about proving that a different set of assumptions could produce systems capable of surviving real-world failures at scale. That lesson remains relevant, even if the ecosystem has moved on to newer implementations and abstractions.