How AI Face Swap Actually Works Under the Hood
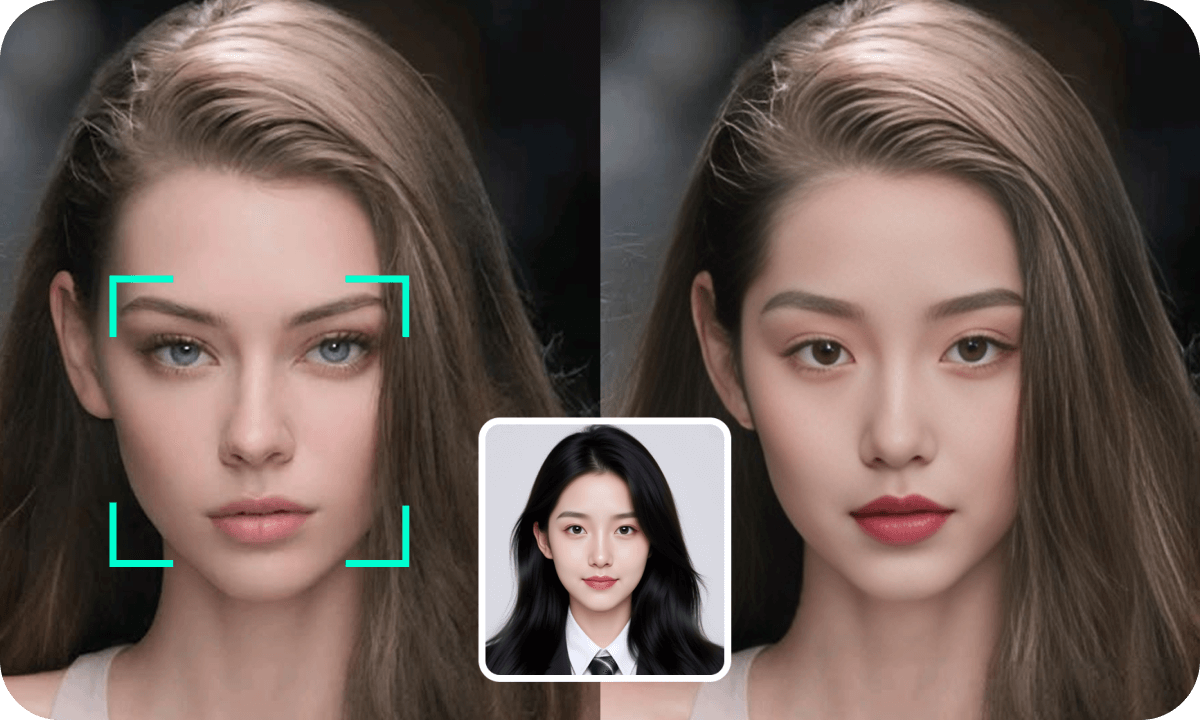
The process starts with a detection step. The model identifies a face in the source image and another face in the target image. Then it maps facial landmarks—corners of the eyes, tip of the nose, the jawline, the contour of the lips. These landmarks get turned into a geometric alignment that warps the source face to match the pose, angle, and scale of the target face. After that comes the actual replacement, where a neural network blends the skin tones, lighting conditions, and texture details so the swapped face doesn't look like a sticker pasted onto someone else's head. This is what most people mean when they talk about face swap technology, and it's mostly driven by encoder-decoder architectures trained on millions of face images. I've spent years working with these tools across production pipelines, and the gap between what the marketing materials claim and what actually works cleanly is considerable. The easy part is running a demo and getting something that looks passable. The hard part is getting consistent results across dozens of images under varying lighting, angles, and resolutions. That requires understanding how the models handle edge cases rather than just pressing a button and hoping for the best. The core technology behind most modern face swaps relies on a few well-established architectures. InsightFace's ArcFace encoder extracts a 512-dimensional embedding from a source face, capturing identity information while discarding attributes like expression and lighting. DeepFaceLab and its derivatives use autoencoders where the encoder compresses facial features into a latent space and the decoder reconstructs the face with the swapped identity. Then there's the diffusion-based approach, which has become more common recently. Instead of directly replacing a face, these models iteratively denoise an image conditioned on both the target face and the source identity embedding, producing results that are often more photorealistic but require significantly more compute time.
One thing beginners consistently miss is that landmark detection quality matters more than the actual swap algorithm. If your landmark detector fails on a side-profile face at a sharp angle, no amount of tuning the model will fix it. I spent three days debugging an issue where half my output faces looked distorted, only to realize the Dlib landmark detector was misaligning profiles past about 45 degrees. Switching to MediaPipe's face mesh, which provides 468 points instead of the standard 68, completely resolved the distortion problem. The additional points around the jaw and neck area give the warping algorithm much better guidance for extreme angles. Another common pitfall involves lighting mismatches between the source and target images. A face swapped from a studio-lit portrait onto a candid outdoor photo will look wrong even if the geometric alignment is perfect. The human visual system is incredibly sensitive to inconsistent shadows and highlights on faces. I found that applying a simple color transfer using Reinhard's method after the swap but before final blending reduced the artificial appearance significantly. You take the mean and standard deviation of the RGB channels from the target face region and normalize the swapped face to match those statistics. It's a five-line addition to any pipeline and it dramatically improves realism without requiring any additional training. For practical implementation, you have a few paths depending on your comfort level and technical requirements. The most accessible option is using a pre-built GUI tool like FaceFusion or Roop. These run locally on your machine and handle most of the preprocessing automatically. They typically use InsightFace for identity extraction and a lightweight GAN for the actual swap. A decent GPU like an RTX 3060 or better will process a single image in roughly 2 to 5 seconds. Without a GPU, expect several minutes per image on CPU alone, which makes batch processing impractical.
If you need more control over the output, working with the raw Python libraries is the way to go. InsightFace provides the face analysis and ID extraction modules. OpenCV handles the geometric transformation and blending. FFmpeg can be used for video face swapping by processing frames individually and then reencoding. For video specifically, you need to maintain temporal consistency, which means tracking faces across frames rather than processing each frame independently. FaceFusion handles this internally using a tracking system that follows facial landmarks through a sequence, but if you're building your own pipeline, you should use DeepSORT or a simpler Kalman filter to associate detected faces across frames. The download and setup process for a local installation is straightforward but has some prerequisites. You need Python 3.9 or later, pip, and CUDA installed if you want GPU acceleration. The core dependencies include PyTorch with CUDA support, OpenCV, numpy, and onnxruntime for running the pretrained models. Most projects provide a requirements.txt file that handles the dependency installation. After cloning the repository, you typically install with pip install -r requirements.txt and then download the pretrained model weights separately since they're not included in the repo. The InsightFace prerecognized models alone are about 100 megabytes. Here is the basic command structure for running a face swap with a tool like FaceFusion: you specify a source image containing the face you want to extract, a target image or video containing the face you want to replace, and an output path. The tool handles the rest. For a single image, the command looks like facefusion.py --source source.jpg --target target.jpg --output result.jpg. For video, it's essentially the same command with video files. Processing time for a 60-second 1080p video on an RTX 4090 takes approximately 3 to 4 minutes. On a laptop with integrated graphics, the same video might take 45 minutes or more and the quality will be noticeably worse due to lower resolution handling and reduced memory bandwidth.
Get the Full Details
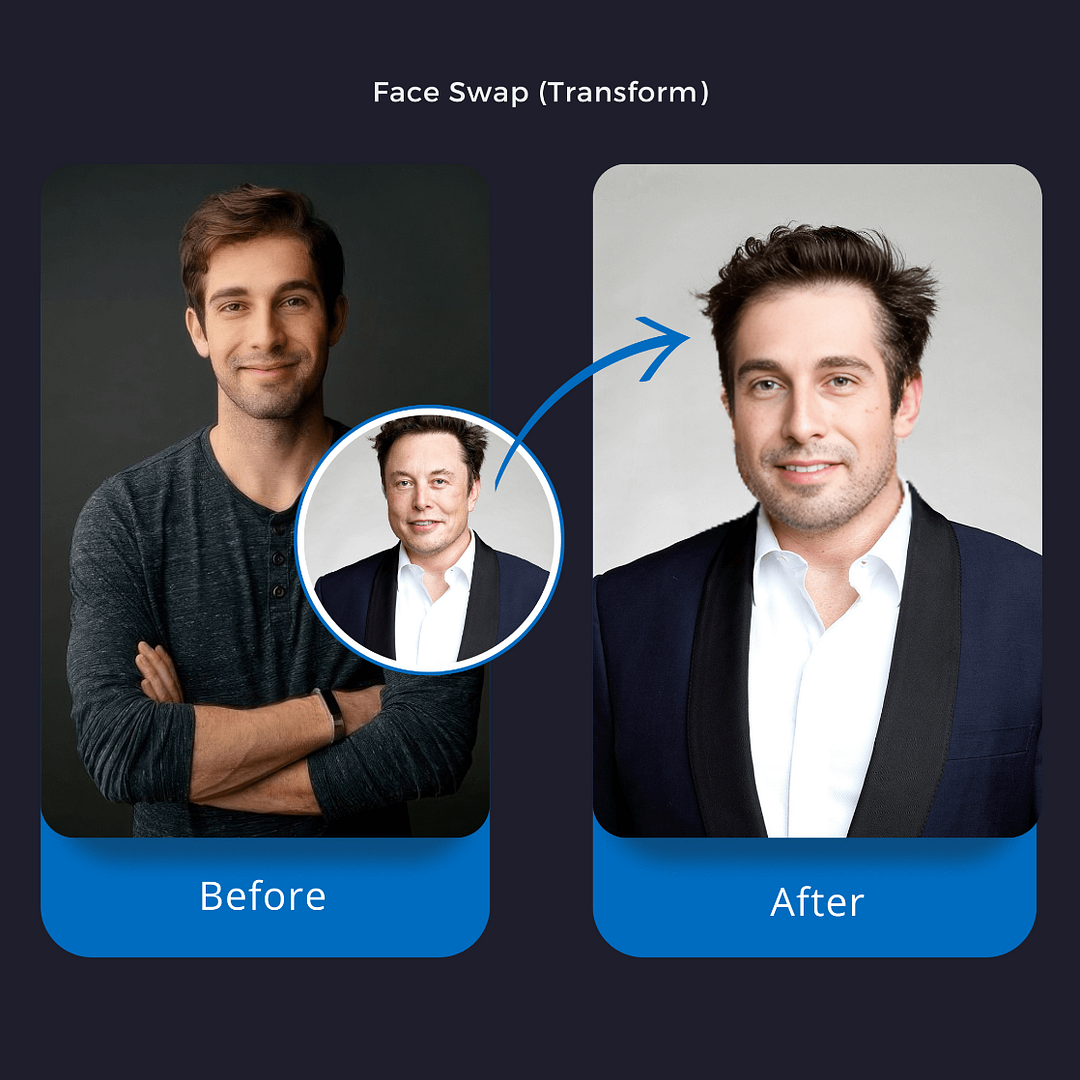
For developers who want to integrate face swapping into their own applications, the InsightFace library on GitHub is the most reliable starting point. It provides a clean API for face detection, landmark extraction, and embedding generation. From there you can connect it to any decoding architecture. Several open-source implementations of the SwanLab and SimSwap architectures are available if you want something beyond the basic demo code. The key insight is that you rarely need to train your own model from scratch. The pretrained weights on these platforms are trained on large datasets like FFHQ and FaceScratch and perform well across diverse demographics. Fine-tuning is only necessary if you have a very specific use case that the general models don't handle well. The limitations of current face swap technology are worth stating plainly because they matter in practice. Low-resolution source faces produce blurry results regardless of how good the target image is. A 64-pixel-wide face in the source image will not swap cleanly into a 4K target. The model simply does not have enough identity information to work with. Extreme facial expressions also cause problems. A source face with an open mouth and raised eyebrows swapped onto a neutral target face will create uncanny results around the jaw and cheek areas because the geometry doesn't match. Partial occlusions like sunglasses, hands covering the face, or hair blocking part of the face are handled inconsistently. Some tools mask out the occluded regions gracefully, while others produce messy artifacts around the sunglasses frames. Video face swapping introduces additional challenges that static image swapping does not have. Frame-by-frame processing without proper temporal smoothing creates a flickering effect where the swapped face subtly shifts position and brightness between consecutive frames. Even with tracking, rapid camera movements or quick head turns can cause the tracker to lose the face for several frames, resulting in the original face briefly reappearing in the output. Post-processing with temporal smoothing algorithms like temporal median filtering or optical flow-based interpolation can reduce this but adds processing time and may introduce slight motion blur.
Legal and ethical considerations are not optional when working with this technology. Most jurisdictions now have laws around deepfakes and unauthorized use of someone's likeness. Using face swap technology on someone without their consent, especially for commercial purposes or content that could be considered defamatory, carries real legal risk. Even benign uses like creating parody content can escalate quickly if the subject feels harmed. Reputable platforms and tool providers have built-in safeguards like requiring you to confirm ownership or authorization of the source and target faces, but these are self-enforced and not universally reliable. If you're building a tool for others to use, implementing explicit consent verification is the responsible approach. For most people who just want to experiment with face swapping without dealing with installation and configuration, online services exist as an alternative to local installation. Services like Reface, Faceswap.ai, and similar platforms run the processing on their servers. The tradeoff is privacy—you're uploading your images to someone else's infrastructure—and quality control, since these services often compress outputs to reduce bandwidth costs. For personal use with non-sensitive images, this is a reasonable option. For professional work or batch processing of large numbers of images, local installation is the better path despite the initial setup effort. The quality of your input images is the single biggest factor in output quality. Use source images where the face is clearly visible, well-lit, and facing forward or at a moderate angle. Avoid heavily filtered or edited photos as the filter artifacts interfere with the landmark detection and embedding extraction. For target images, faces that are relatively front-facing and well-lit produce the most reliable results. Side profiles, backlit subjects, and images with heavy shadows require additional manual adjustment or post-processing to look acceptable. Taking these factors into account before you even start the swap process saves considerable time compared to generating poor results and then trying to fix them afterward.