What Actually Happens When Automation Tools Start Growing Faster Than Your Team Can Handle
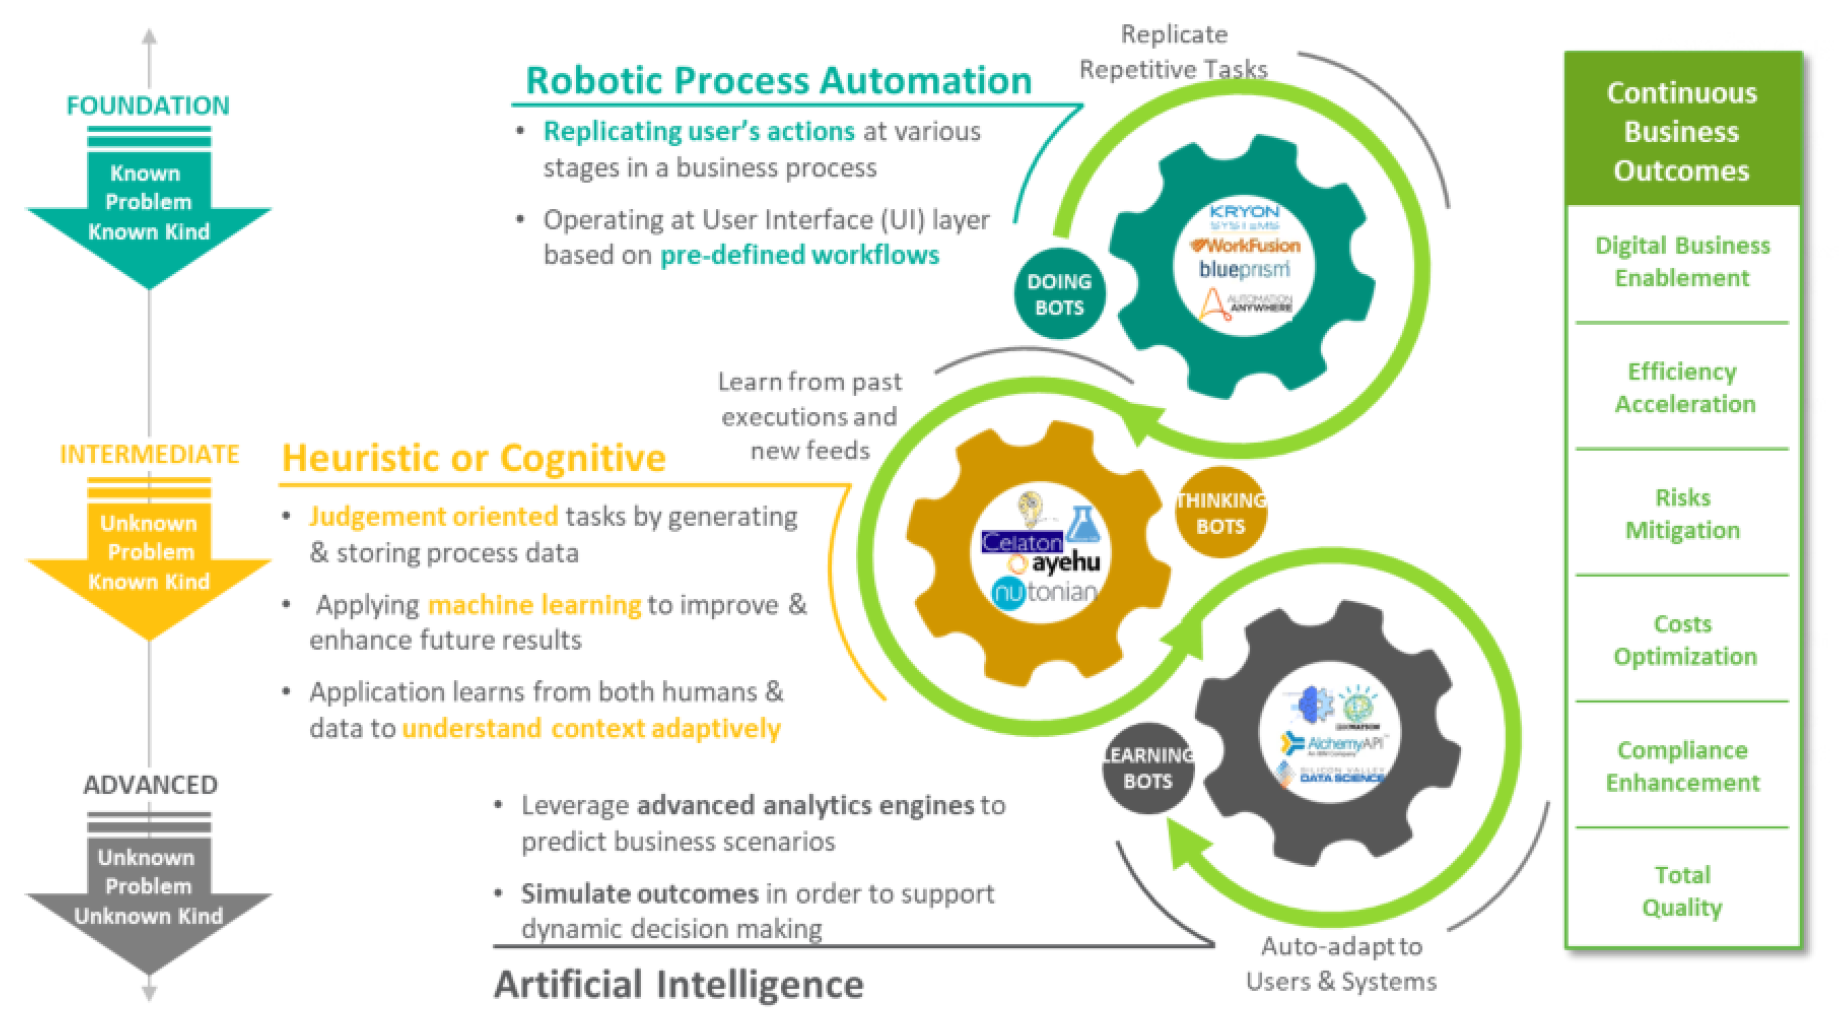
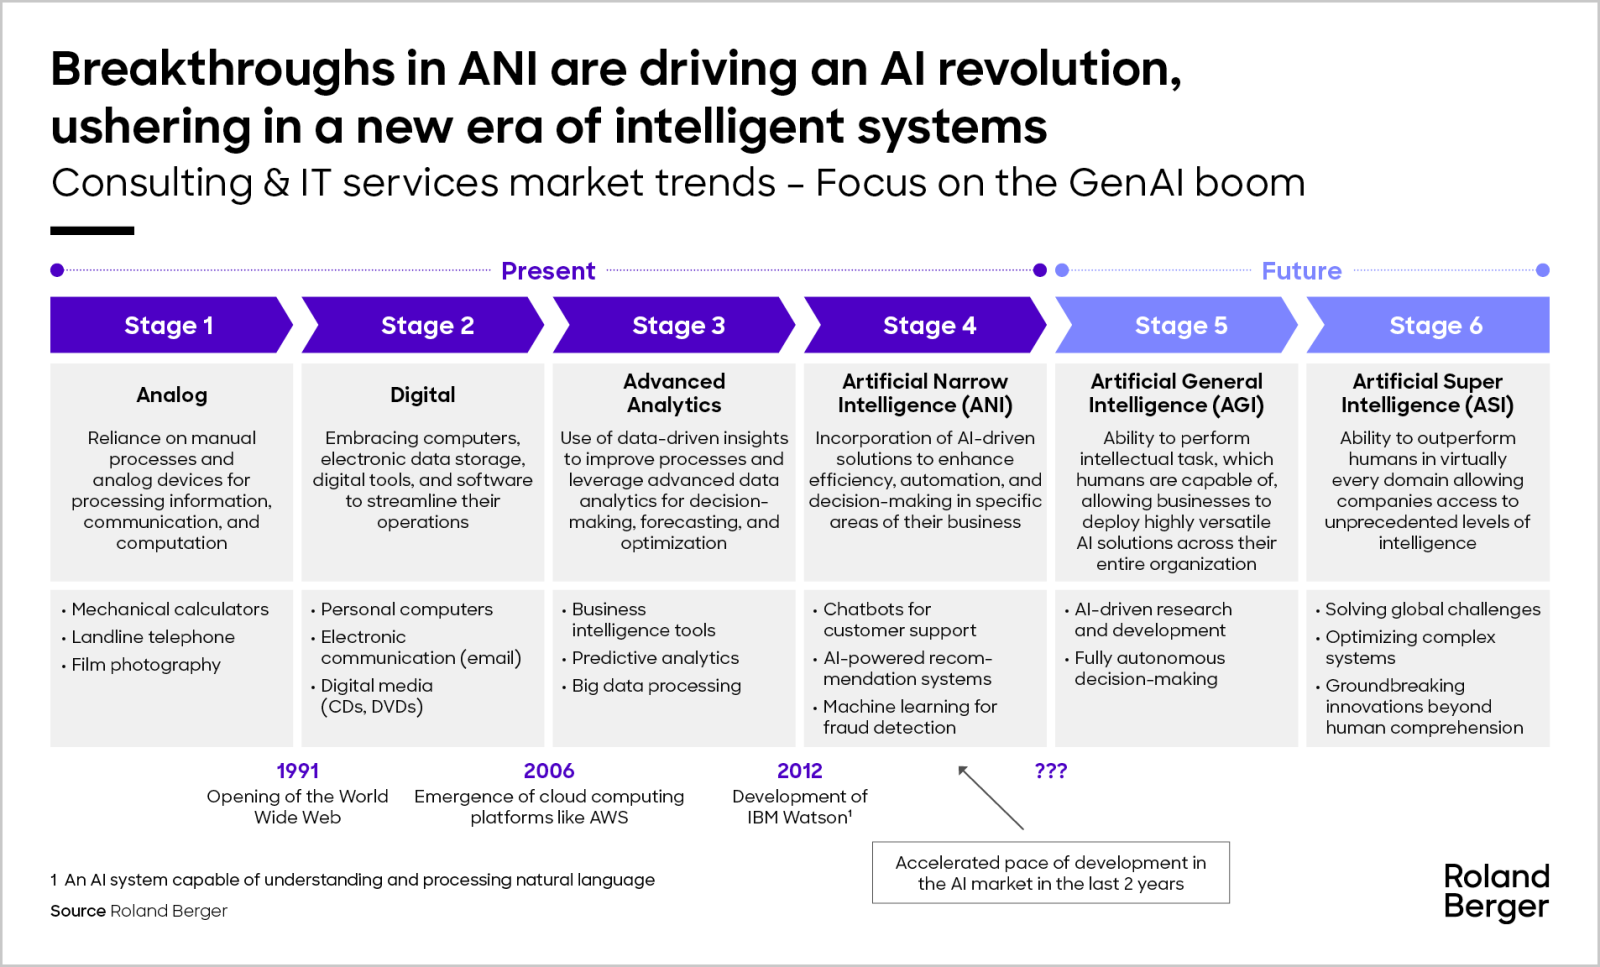
I keep seeing new vendors pitch their platforms as if intelligent automation solved every problem it was supposed to solve. It didn't. The last three years have been messy. Systems integrate poorly with legacy databases. RPA bots break when a UI element moves by three pixels. Machine learning models trained on clean data fail in production because the real input stream contains garbage from the source system. The Bosa Age Understanding The Rapid Growth Of Intelligent Automation isn't a product. It's a period. People started calling it that roughly 18 months ago after Gartner reclassified the market segment. Before that, everyone just called it "intelligent automation" and charged $200,000 a license for software that did the same thing a $3,000 Python script could do. The rebranding pushed every major vendor into the same positioning statement: your old RPA tool plus a large language model equals "the future." It doesn't. But the sales decks look better now. The actual shift happened around 2022 when model-as-a-service pricing dropped below the cost of running custom Python pipelines. That changed the math entirely. A mid-size operations team could now call an API for $0.003 per processed document instead of hiring two data analysts to build and maintain an extraction pipeline. The economics flipped overnight. That's when the growth curve went vertical. It wasn't innovation. It was just cheaper compute meeting existing demand.
How To Set Up A Working Pipeline Without Breaking Everything
Start with the data source, not the automation tool. I see this mistake constantly. Teams pick a platform first, then look for use cases. The platform dictates what problems you solve. You end up automating a bad process because the tool happens to support PDF ingestion. That's backward. Pick a process first. Map the exact input type, expected volume, and quality of the source data. Then select the stack that handles that specific input. For document extraction, I use a combined approach: an OCR layer (typically Tesseract or AWS Textract for scanned material) feeding into a prompt-based extraction step. The prompt goes to a model like Claude or GPT-4o-mini, depending on throughput needs and budget. I keep the output in a structured JSON format and validate it against a simple schema before it enters any downstream system. The validation step is non-negotiable. LLMs will confidently hallucinate fields. I wrote a Pydantic validator that checks every output document against required fields and reasonable value ranges. If the confidence score drops below 0.92 on any field, it routes to a human review queue instead of proceeding automatically. This usually catches about 4 percent of edge cases that slip through first-pass extraction. In one implementation for a logistics company, this single step reduced downstream error correction time from roughly 6 hours per day to about 45 minutes per day.
Orchestration is where most implementations stall. I recommend Temporal or AWS Step Functions for workflow management. They handle retries, timeouts, and state tracking without requiring custom code. A typical pipeline I set up last quarter processes supplier invoices through a three-stage flow: ingest and classify, extract with validation, then push to the ERP via API. The entire process takes about 90 seconds per invoice at a compute cost of roughly $0.07 each. The previous manual process took 14 minutes per invoice at a fully loaded labor cost of about $3.20.
Get the Full Details
Edge Cases That Actually Matter
Here's the problem most guides don't mention: multi-column tables in PDFs. A standard text extraction routine reads left-to-right, top-to-bottom. Tables break that assumption entirely. I spent two weeks debugging a healthcare claims processing pipeline where the model kept merging adjacent columns into single fields because the PDF used invisible table structures rather than actual text delimiters. The fix was converting the PDF to an image layer first, running table detection with a library like Camelot or Tabula, then passing the structured table data to the model instead of raw OCR text. Another issue: version drift in vendor APIs. The GPT-4o-mini pricing changed three times in six months. Each change forced me to recalculate unit economics for existing pipelines. I stopped treating API costs as fixed and built a cost estimation module into each workflow that recalculates expected spend per transaction based on current rates. It sounds trivial but it saved us from an unexpected $18,000 bill when one vendor quietly changed their pricing tier.
When It Fails Completely
Intelligent automation does not work for processes that require genuine judgment. Contract interpretation involving legal liability is one example. Another is anything that depends on understanding company culture or interpersonal dynamics. These systems can assist with those tasks but cannot own them. I've seen teams try to automate vendor negotiation emails with LLMs. The results were passable on the first draft, but they lacked the subtle positioning that experienced procurement staff develop over years. Adding a human review step brought the success rate from about 60 percent acceptance to roughly 85 percent. Not a bad number, but far from the "fully autonomous" claim in the sales deck. Legacy mainframe integration is another hard boundary. If your core system only accepts fixed-width file formats through a proprietary middleware layer, no amount of intelligent automation changes that constraint. You'll spend more time building bridges than automating anything meaningful. In these cases, a straightforward RPA tool with screen scraping may be the faster path to value, even if it's less elegant.
What To Watch For Next Year
Agent-based workflows are replacing monolithic pipelines. Instead of separate extract, validate, and route steps, you're seeing single agents that handle the full transaction. The tradeoff is cost and unpredictability. A single agent invocation runs through multiple model calls internally, so you pay more per transaction. But the development time drops significantly because you're writing fewer integration points. For small teams with well-defined processes, this is often worth the premium. Another trend: retrieval-augmented generation moving from research documents into operational data. Feeding live database records into prompts instead of static knowledge bases reduces hallucination rates and keeps outputs grounded in current information. The implementation requires careful prompt engineering to avoid token limits, but it's becoming standard practice for customer service automation and internal knowledge queries. The growth in this space will continue. The question isn't whether it grows further. It's whether the teams deploying it understand what the technology actually does and doesn't do. Most don't. That's where the gaps are.