Population Dynamics Are Messy — Here's How I Deal With It
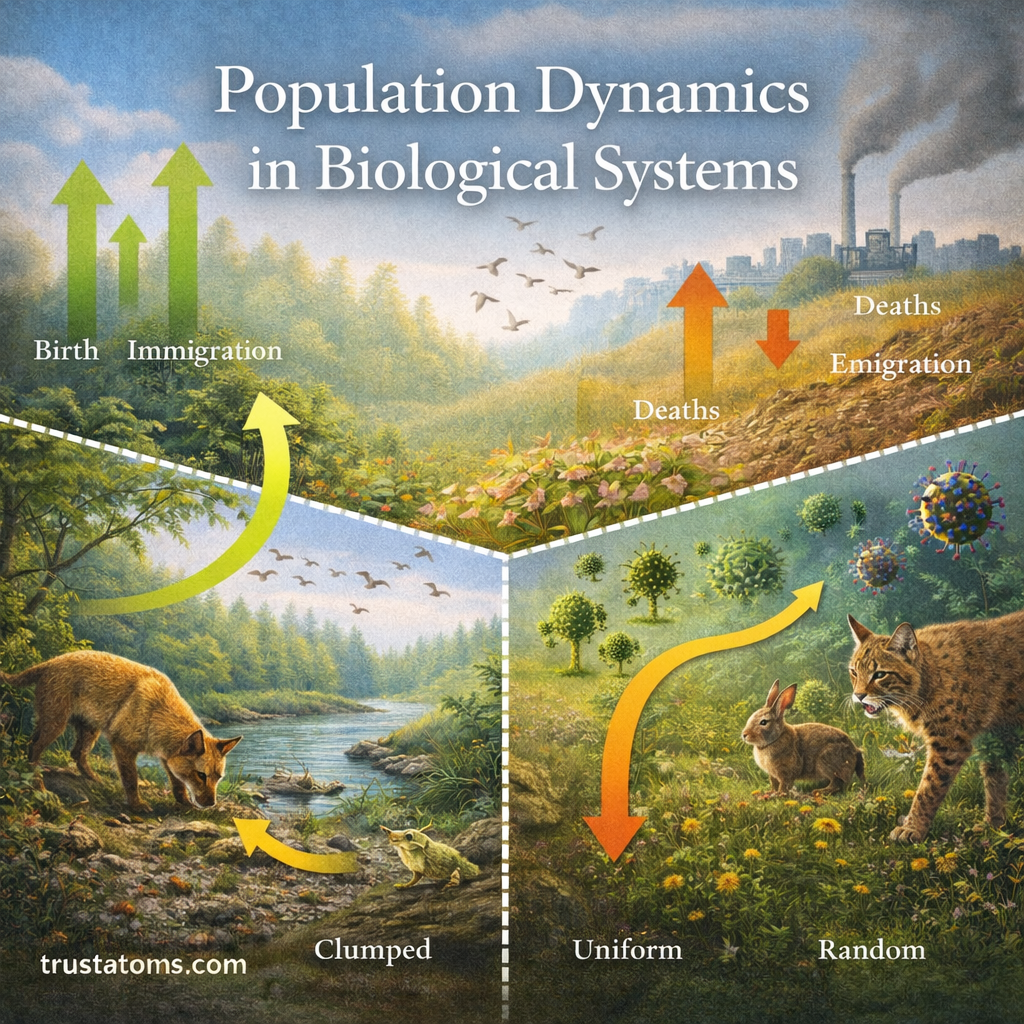
I spent seven years trying to model population viability for a small mammal species before I stopped pretending the math would ever match reality. The short version: populations are not closed systems, they are not stable, and they absolutely do not follow nice exponential curves when you actually look at field data. What follows is the approach I settled on after burning through two grant cycles on flawed assumptions. At its core, population biology tracks how the size and structure of a group of organisms changes over time within a given environment. That sounds simple. It isn't. You're looking at births, deaths, immigration, emigration, age structure, sex ratios, genetic drift, density dependence, and stochastic environmental events all happening simultaneously. Any single-model approach will miss at least three of those factors. I learned this the hard way. The standard textbook introduction starts with the exponential growth equation and the logistic model. Both are useful as baseline frameworks. The exponential model assumes unlimited resources and a constant per capita growth rate. The logistic model adds a carrying capacity term that slows growth as the population approaches an environmental limit. In practice, carrying capacity is not a fixed number. It shifts with rainfall, temperature, competitor abundance, disease prevalence, and human land use. Treating K as a constant is one of the most common mistakes I see in published population studies.
Setting Up a Realistic Monitoring Protocol
Before you build any model, you need data that actually represents what's happening. Standard transect counts tend to underestimate cryptic species and overestimate conspicuous ones. I switched to a combination of mark-recapture with individual recognition and environmental DNA sampling. The mark-recapture component gave me survival and movement estimates. The eDNA component caught individuals I would have otherwise missed because they were transient or too shy to enter traps. Using both methods together cut my detection error in roughly half compared to relying on either alone. Sampling frequency matters more than most people admit. Monthly surveys worked for the seasonal breeders in my study system, but a winter-overswintering species I worked with later required biweekly effort during the breeding window. Missing a two-week pulse can wipe out your ability to detect a genuine population decline versus a temporary fluctuation. I now schedule surveys based on known phenology, not convenience.
Building the Model Without Trapping Yourself
I used to rely heavily on deterministic matrix population models. They are clean, they publish well, and they give you a nice lambda value. The problem is determinism. Real populations face environmental stochasticity that deterministic models smooth over entirely. I moved to stochastic integral projection models that incorporate year-to-year variation in vital rates. The computational cost is higher, but the output actually reflects uncertainty rather than pretending it doesn't exist. One thing that surprised me during model development: parameter uncertainty often matters more than model structure. I ran sensitivity analyses that showed my results were far more sensitive to small changes in juvenile survival estimates than to whether I used a Beverton-Holt or Ricker functional form for density dependence. In other words, getting the vital rate data right outweighed picking the fancier density-dependence equation. Most researchers do the opposite. They invest heavily in model complexity while using rough literature values for key parameters.
Get the Full Details
My Specific Problem With Transient Dynamics
Here is a concrete example of where everything went wrong for me and how I fixed it. I was studying a fragmented population of a rodent species across seven patches. My initial population viability analysis predicted a stable metapopulation with moderate extinction risk. The model assumed the population was at demographic equilibrium. In reality, the focal patch had been colonized only five years prior by a small founder group. The population was deep in transient dynamics — age and stage structure had not yet stabilized to the reproductive value distribution that the model assumed. This meant my predictions were fundamentally wrong. The transient phase amplifies short-term growth rates in ways equilibrium models completely miss. I revised the approach by running a transient analysis alongside the long-term projection. I used the actual stage distribution from the field data as the initial condition instead of the stable stage distribution. The revised projection showed a much higher near-term extinction risk than the equilibrium model had suggested. Within three years of the revision, the population crashed for reasons the original model had buried under its equilibrium assumption. The transient dynamics analysis would have flagged that risk months earlier. If you are working with recently established, recently disturbed, or recently reintroduced populations, always check whether transient effects are likely to dominate your time horizon. A quick stability analysis of the projection matrix will tell you how many years until the system approaches equilibrium. If that timeframe exceeds your management or study window, the equilibrium model is misleading you.
When Models Fail Completely
I should be blunt about the limitations here. Population models break down in several scenarios that nobody likes to talk about. First, when dispersal rates are asymmetric and poorly understood. I once modeled a coastal bird population where immigrants came from an unsampled source population. My model treated the system as closed. It was not. The unsampled immigration was rescuing a declining subpopulation, and my viability estimate was catastrophically pessimistic. Second, when ecological communities shift rapidly. Climate-driven range shifts, invasive species establishment, and novel disease pressures can restructure a system faster than your model parameters can be estimated. Third, when data quality is low. There is no statistical trick that recovers a reliable estimate from five years of sparse count data for a slow-lived species. In those cases, the best alternative is often a heuristic or rule-based framework paired with adaptive monitoring. Models like RAMAS Metapop or VORTEX can incorporate some of these complexities if you feed them realistic uncertainty ranges rather than point estimates. They are not magical solutions, but they handle stochasticity better than simple matrix models when your data is thin.
Practical Steps That Actually Work
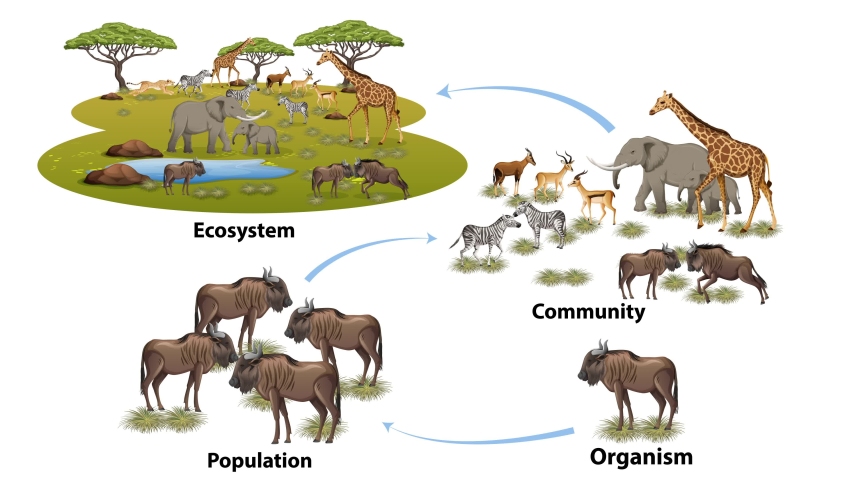
Start with a clear spatial and temporal boundary for your study population. Define what counts as immigration and emigration before you collect a single data point. Write that definition down. Most method sections I read leave this ambiguous, which makes replication impossible and meta-analysis nearly worthless. Estimate detection probability before you estimate abundance. Distance sampling, occupancy modeling, or robust-design mark-recapture will all give you a detection parameter. If you skip this step, every abundance estimate you produce is confounded with detectability. I have seen entire management decisions hinge on uncorrected count data that turned out to reflect a change in observer behavior rather than a change in population size. Use life table response experiments when you want to know which vital rates matter most. This technique compares matrix entries across populations or treatments and tells you directly which parameters drive differences in growth rate. It prevents you from wasting effort measuring traits that have negligible effect on population dynamics. In my experience, survival of subadults often drives differences between populations more than fecundity, which contradicts what most ecology students expect.
Report confidence intervals on everything. Point estimates without uncertainty bounds are essentially decorative. When reviewers or managers ask for a single number, give them the point estimate and then show them the interval. If the interval spans extinction probability thresholds or management targets, the point estimate is useless for decision-making.
A Note on Software and Implementation
I use R for most of my work. Packages like popbio, IPMR, and merl handle the standard matrix and projection model work. For spatially explicit individual-based models, I have used NetLogo for prototyping and custom C++ code for production runs. The learning curve is steep but necessary if you want to simulate age-structured dispersal with variable habitat quality. Python is viable for simpler models, but the ecological modeling ecosystem in R remains more mature for demography-focused work. If you are new to this, start with a simple discrete-time matrix model for an annual organism before attempting anything with overlapping generations or continuous time. The conceptual foundations are the same, but the math compounds quickly once you add age classes and environmental stochasticity together. The field does not need more equilibrium models applied to non-equilibrium systems. It needs honest uncertainty quantification and a willingness to admit when the data cannot support the conclusions the model suggests. I wish I had learned that sooner than I did.