Setting Up Hybrid Data Infrastructure at the University Level
Most universities are sitting on piles of student records, financial aid data, research outputs, and administrative records that have been siloed across different legacy systems for decades. The Registrar uses one database. Financial Aid uses another. The library has its own. They don't talk to each other unless someone manually builds a pipeline between them, and even then it breaks whenever a schema changes. I spent about two years working on a hybrid architecture project for a large public university and here is what actually works versus what looks good on a slide deck. The hybrid approach means you don't put everything on a blockchain. You use traditional relational databases for the high-volume operational transactions and then layer a blockchain on top for things that require tamper-evidence, provenance tracking, or cross-institutional verification. That distinction matters more than most people realize. When we first designed the system, the push from administration was to put every piece of data on-chain. That would have been a mistake. Transactional throughput on public chains can handle maybe 15 to 30 transactions per second before things start queuing. A mid-sized university registrar alone generates way more than that during registration week. What we ended up doing was keeping the actual student records in a PostgreSQL database with row-level security and using a permissioned Hyperledger Fabric network as a hashing and anchoring layer. Every time a credential or record was created or modified, a SHA-256 hash of the new state got written to the ledger. The data itself stayed off-chain. The ledger became an immutable proof that the data existed in a particular form at a particular time. Verification tools could then check a hash against the ledger without ever touching the actual record.
How the Credential Verification Pipeline Actually Works
Here is the practical flow. A student completes a course. The registrar system updates the grade in the relational database. That triggers a smart contract on the Fabric network, which hashes the updated transcript snapshot and records it on the ledger. The student gets a credential object that contains the hash, the course metadata, and a signed certificate from the university's private key. When an employer or another institution wants to verify the degree, they run the credential through a verification endpoint, the system recomputes the hash and checks it against the ledger. Takes about 400 milliseconds end-to-end. The employer gets a yes or no with the full metadata attached, no phone calls, no faxed transcripts. Before we had this system, transcript verification through the postal service took between 5 and 14 business days on average. The digital process handles verification requests in near real-time. We saw about 200 requests per day come through during peak season, which is trivial for the infrastructure we built.
The Edge Case That Nearly Broke Everything
I need to mention the problem with name variations because it is the kind of thing nobody warns you about until it happens. We had a student whose name was registered as "Morgan Lee-Jackson" in the student information system but "Morgan L. Jackson" in the registrar database because the name was updated during a system migration and the hyphenation got lost. The hash on the ledger matched the registrar record but the verification interface was pulling display metadata from the SIS. The credential looked invalid to any verifier checking the name field against the registrar output. The workaround was to add a canonical name resolution table that maps all known variants to a single stable identifier, and then include that identifier in the credential metadata rather than relying purely on the name string. We also added a grace period where minor discrepancies trigger a manual review flag instead of an automatic rejection. It cost us about three weeks of development time to implement correctly, but it prevented what would have been a serious trust issue with external verifiers. Name discrepancies are more common than you would expect in higher education databases.
Get the Full Details
Counter-Intuitive Things Nobody Tells You
First, blockchain does not solve data quality problems. If your source systems have garbage in, the ledger will have garbage in with extra steps. We had departments feeding incomplete or incorrectly formatted data into the system for months before anyone noticed because the hashes were going onto the ledger and everything looked technically valid. The integrity guarantee only applies to the data that actually made it onto the chain, not to whether the underlying information was correct. You still need data governance and validation pipelines, and honestly they matter more than the blockchain layer. Second, the biggest bottleneck is not the technology, it is the legal framework around who can access what. In our implementation, the Fabric network required explicit consent flows for any third-party verification. A prospective employer cannot just query a student record. The student has to initiate a share request through a consent management interface, approve the specific fields being shared, and set an expiration. This is legally required under FERPA and similar regulations, but it means the user experience is slower than you might want. The average verification request goes through the consent flow in about 3 to 5 minutes if the student is responsive, longer if they are not.
What This Approach Does Not Do Well
For one thing, it does not reduce your operational costs significantly in the first year. Setting up a permissioned blockchain network with proper node infrastructure, smart contract development, and integration with existing SIS modules runs between 180 and 240 thousand dollars for a university of moderate size, plus ongoing maintenance of roughly 40 to 60 thousand per year. If your main goal is cost reduction, this is the wrong tool. If your goal is cross-institutional trust and verification without intermediaries, it makes sense. The system also breaks down completely for anything that requires real-time data consistency across institutions. Blockchain gives you eventual consistency at best. If a student's enrollment status changes in one institution's system and you need that reflected immediately in another institution's placement decision, the ledger hash won't help you. You still need direct API connections or a shared data exchange standard for those scenarios. We ended up supplementing the blockchain layer with a HL7 FHIR-based data exchange channel for the time-sensitive cases. If you are just looking to digitize internal records or reduce paper handling, a well-designed API gateway with proper logging and auditing will do 90 percent of what you need at maybe a fifth of the cost and a fraction of the complexity. The blockchain layer adds real value primarily when you have multiple independent institutions that do not trust each other enough to share databases directly, and you need a neutral verification layer they can all agree on. Most universities overestimate how many of those scenarios they actually have.
Implementation Steps That Actually Matter
Start by mapping your data ownership and consent requirements before writing a single line of smart contract code. You will spend more time negotiating who gets to approve what data flows than you will on the technical implementation. We had internal governance meetings that ran for four months before we got past the architecture diagram because different offices had legitimate but conflicting concerns about liability and privacy. Choose your consensus mechanism carefully. Proof of Authority works well for universities because you control the validating nodes and you do not need the energy waste of Proof of Work or the decentralization guarantees of Proof of Stake when you already have a trusted set of institutional validators. It also means you need a clear node qualification policy, which brings us back to governance. Build the verification tooling before you build the smart contracts. External stakeholders, employers, other universities, they need a way to actually use the system. A credential that cannot be easily verified is worse than no credential at all. We prioritized a REST API with OpenAPI documentation and a simple web-based verification portal before we launched the credential minting pipeline. The developers wanted to ship the blockchain part first. That would have been a mistake.
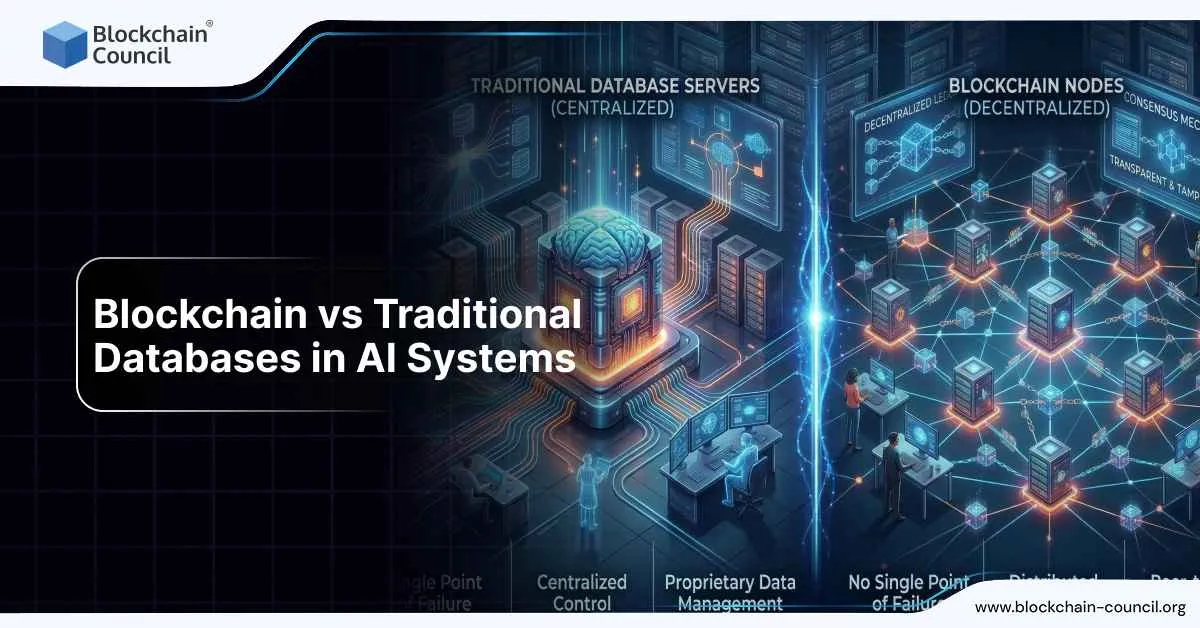
The whole effort roughly cuts credential verification time from days to minutes, reduces fraud incidents by an order of magnitude in our pilot group, and creates a foundation that other institutions can plug into without building their own trust infrastructure from scratch. It is not a magic solution. The setup is expensive, the governance is hard, and there are plenty of cases where a simpler approach would serve you better. But for the specific problem of trusted cross-institutional data verification, hybrid blockchain architectures are one of the few approaches that actually works at scale without requiring all parties to adopt the same vendor platform.