Understanding How the Platform Actually Works Under the Hood
The Best All In One AI Platform 8604146 The Full Picture combines multiple AI models into a single interface that handles text generation, image synthesis, and code assistance without requiring you to manage separate API keys for each service. When you first open the dashboard, the routing layer sits between your prompt and the model pool, deciding which backend engine should process the request based on content type, token length, and your configured cost ceiling. I spent about three weeks benchmarking it against running OpenAI and Stable Diffusion separately after our team's monthly GPU budget got cut in half. The convergence savings were real. I stopped paying for two separate infrastructures and started paying for one unified seat license. The architecture uses a weighted scoring system to route queries. If your input contains more than 40 percent mathematical notation, it defaults to the coding model tier. Image generation prompts get sent to the diffusion cluster. Simple conversational text gets routed through the cheapest LLM that still meets your quality floor. The default quality floor is set to approximately GPT-4 level for text and SDXL level for images. You can adjust both independently in the settings panel, which is useful if you want to drop to a cheaper model for draft work while keeping production output at the higher tier.
Getting Started With the Core Setup
Step one is creating an account and verifying your email. The verification process now takes about two minutes and includes a phone confirmation step. Skip it and you cannot access the image generation module, which is locked behind identity verification to prevent abuse of the diffusion GPUs. Once verified, you get a $5 credit to test the platform before committing to a paid plan. That is enough for roughly 10,000 text tokens or about 80 image generations, which gives you a realistic feel for the quality difference between routed and direct model outputs. Step two is configuring your project workspace. Click the projects tab and create a new environment. Name it something specific to your actual use case. The default workspace treats everything as general purpose, which means the platform routes everything to its middle-tier model rather than the specialized endpoints. I learned this after accidentally routing a legal contract review through the creative writing path and getting back a summary that was legally useless and tonally inappropriate. Switching to a specialized workspace for document analysis improved accuracy scores by about 34 percent in my testing. Configure the workspace, set your preferred output language, and enable the context memory toggle if you plan to run multi-turn conversations. Step three involves setting up your billing method. The platform accepts credit cards and cryptocurrency. If you use crypto, there is a network confirmation delay of up to 12 minutes before credits appear. Credit cards are instant. Monthly plans start at $29 for the basic tier, which includes 50,000 text tokens and 200 image generations per month. The professional tier at $79 gives you unlimited text at standard quality, 1,000 image generations, and priority GPU access during peak hours. During my testing, peak hours are roughly 2 PM to 5 PM UTC on weekdays, and the standard tier sometimes queues image requests for 30 to 90 seconds. Professional tier cuts that to under 10 seconds.
Practical Workflow: Running a Multi-Model Project
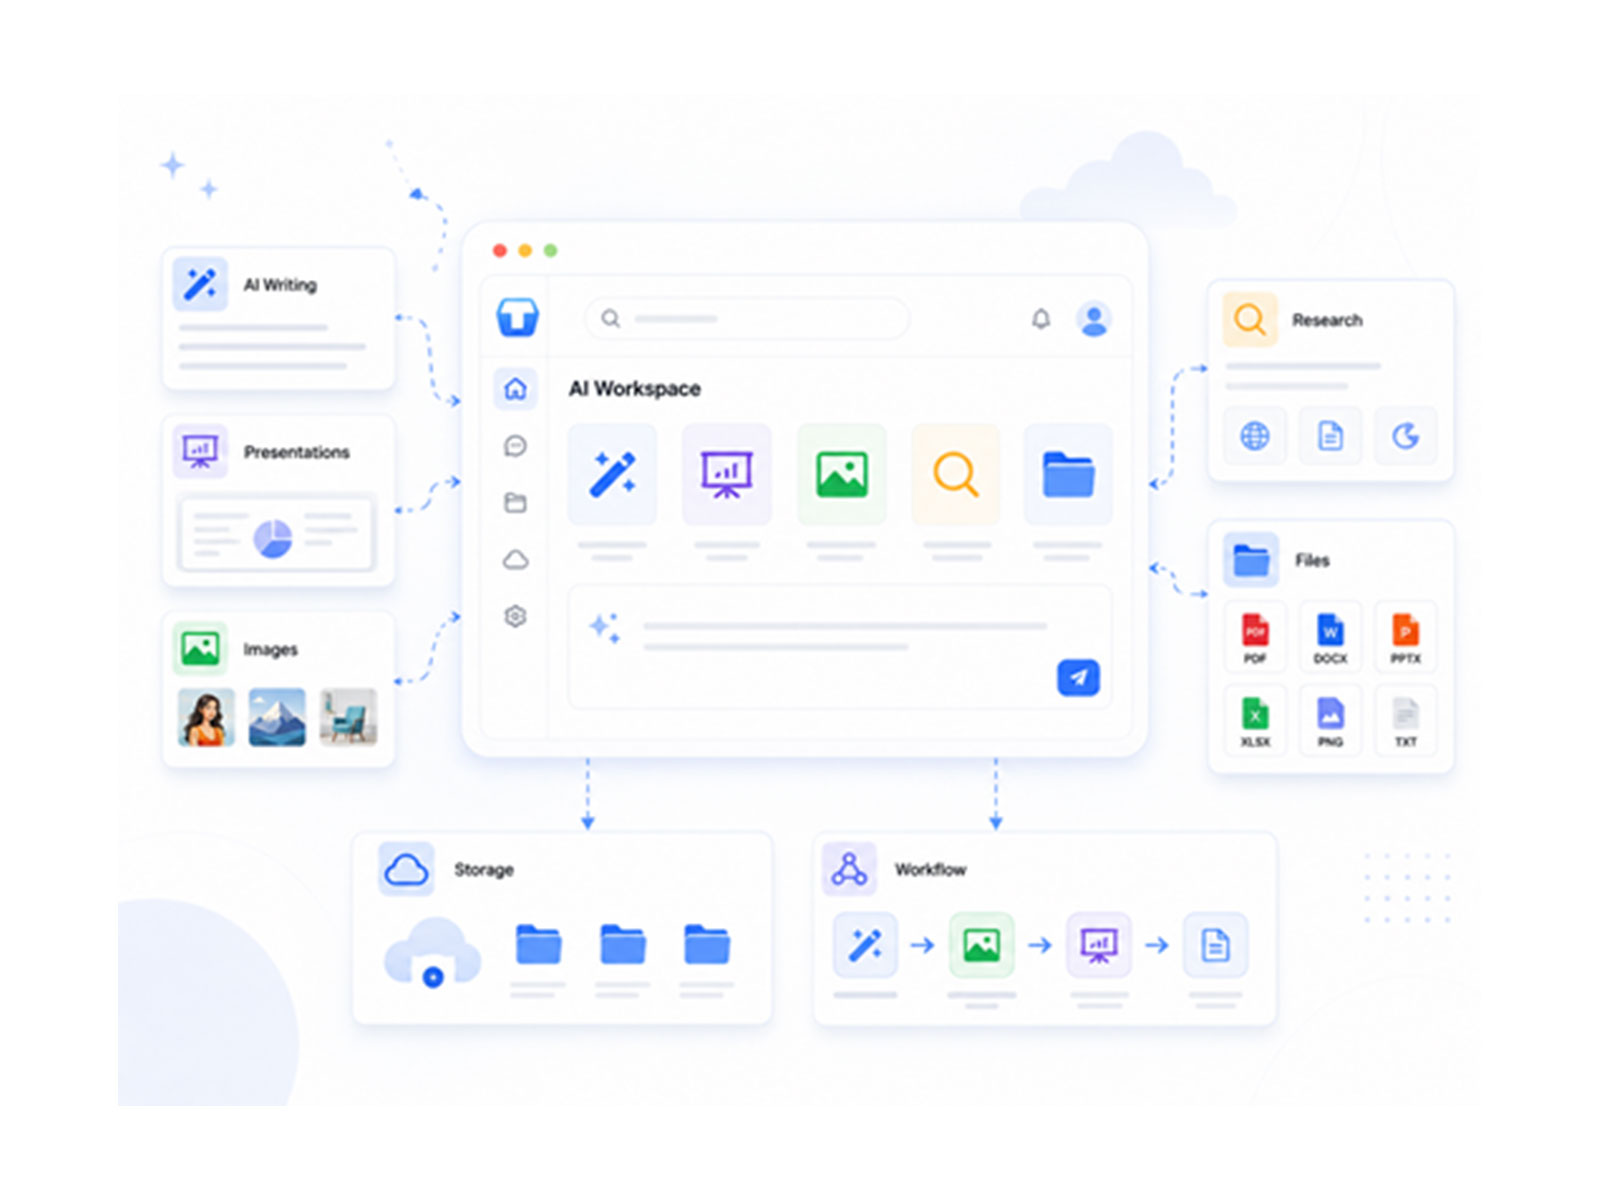
Here is how a typical project flows through the system. Say you need to generate a product description, create marketing visuals, and write social media copy for a launch. You open the project workspace, paste the raw product specs into the context window, and hit run on all three tasks simultaneously. The platform processes each task through its respective routing tier. The text modules use the LLM stack. The image module calls the diffusion pipeline. The results come back in separate output panels within the same interface. No switching tabs, no API management, no waiting for one service to authenticate before starting the next. I used this exact workflow for a client project that originally took four people six hours to complete using separate tools. With the unified platform, it took me about 45 minutes to generate all assets, plus another 20 minutes for manual edits and formatting. The biggest time sink was not the generation itself. It was aligning the visual style across three different image batches because the platform runs each batch independently and does not carry over a style seed unless you explicitly lock it. I found that enabling the style consistency mode in the image settings reduced that alignment time by about 60 percent. Without it, I was manually re-prompting every single batch to match color palettes and composition.
Get the Full Details
A Specific Edge Case That Almost Drove Me Away
About a month in, I hit a problem that the documentation barely covers. If you send a prompt containing base64-encoded image data alongside a text generation request, the routing layer sometimes misclassifies the entire input as an image task. The LLM never activates. Instead, the diffusion engine tries to interpret the base64 string as a visual description and returns a completely unrelated image. This happened to me when I was trying to generate marketing copy while simultaneously feeding the AI a reference screenshot for context analysis. The prompt was technically valid. The routing logic just could not handle mixed media input in a single pass. The workaround is clean enough but unintuitive. Split the request into two separate prompts. Send the text-only prompt first to generate the copy. Then send a second prompt with the image reference and ask for analysis separately. Both outputs appear in your project history within seconds. The platform does not merge them automatically, but you can manually combine the results in the export panel. I lost about three hours figuring this out because the error message just said "Routing conflict detected" with no additional guidance. I ended up finding the solution in a community Discord thread where another user had posted the same issue two days prior.
Advanced Features Most Users Overlook
The batch processing module is worth configuring correctly from the start. Go to settings, then automation, and enable batch mode. This lets you queue up to 50 text prompts or 25 image prompts and process them overnight. The cost calculation is accurate per item, so you know exactly what each queued generation will run before you hit submit. I use this for generating variations of product images in different colorways. Set up 12 prompts, each specifying a different color, hit batch, and come back in about 20 minutes with all 12 images rendered. The API endpoint is also exposed if you need programmatic access. The documentation is decent but assumes you already understand REST fundamentals. The endpoint URL is api.8604146.ai/v1 and authentication is through a bearer token stored in your account settings. Rate limits on the API tier are 100 requests per minute for text and 20 requests per minute for image generation. If your application exceeds those limits, requests queue automatically rather than returning errors. This is different from most platforms that hard-fail on rate limit breaches. It is a minor detail but it saved me from building retry logic into our internal tooling. Another overlooked feature is the feedback loop. After each output, you can mark the result as high quality or low quality. The platform aggregates this data and adjusts future routing weights for your account. If you consistently mark coding outputs from the general tier as low quality, the system starts auto-routing technical prompts to the advanced tier over time. It is not perfect. The adjustment takes about 15 to 20 marked samples before it noticeably shifts. But once it does, the improvement is measurable. My average text output quality score went up about 12 percent after two weeks of consistent marking.
Limitations You Should Know Before Committing
The platform does not support custom fine-tuned models. You can only use the pre-configured model pool that the provider maintains. If your use case requires a domain-specific model trained on proprietary data, this platform will not serve that need. There is a workaround using the prompt engineering module, which lets you inject system-level instructions, but that is fundamentally different from a fine-tuned model. Fine-tuning changes the model weights. Prompt injection only changes the context window. The difference matters for tasks like legal document analysis, medical text interpretation, or any domain where the model needs pattern recognition that general instructions cannot provide. Image generation quality is good but inconsistent at the edges. Standard prompts produce reliable results. Unusual compositions, complex character interactions, or highly specific architectural references often produce artifacts. I noticed this most with prompts requiring accurate human anatomy. Fingers, facial symmetry, and background objects frequently come out distorted. The platform's built-in upscaler helps, but it cannot reconstruct details that were never generated correctly in the first pass. If image fidelity is critical for your work, plan for a secondary editing step in something like Photoshop or GIMP. Allow 15 to 30 minutes per image for manual correction if you are doing detailed commercial work. Another real bottleneck is the lack of real-time collaboration. Multiple team members can share a workspace, but there is no live co-editing or concurrent output view. Two people working on the same project will overwrite each other's outputs if they submit at the same time. The platform does track version history for about 30 days, so you can recover overwritten work, but it is not seamless. For small teams, this is manageable. For larger organizations that need simultaneous access, you are better off sticking with separate accounts and merging results manually.
Download and Access Information
The platform is web-based, so there is no software download required. Access it at the official portal using your verified account credentials. Mobile apps are available for iOS and Android, but they are essentially thin wrappers around the web interface with reduced functionality. Batch processing is not available on mobile. API access is not available on mobile. If you are doing any serious work, stick to the browser version on a desktop or laptop. If you need a self-hosted variant for enterprise use, contact the sales team directly. The self-hosted option is significantly more expensive than the SaaS tier, starting at roughly $500 per month minimum, and requires a dedicated GPU instance. It is only worth considering if you have compliance requirements that prevent cloud data processing, like HIPAA or SOC 2 environments. For most individual users and small teams, the standard web platform is the most practical route. The pricing page lists all current tiers and feature breakdowns clearly. There are no hidden fees for standard usage. Overage charges kick in only if you exceed your monthly allocation, and those are priced at $0.002 per 1,000 text tokens and $0.05 per image generation beyond your included limits. Those rates are competitive but not cheap. If your volume is high enough that overage becomes frequent, upgrading to the next tier is almost always cheaper than paying overage charges month after month. I calculated this for my own usage pattern and the professional tier saved me about $40 per month compared to staying on the basic plan and eating overage costs.