Why Your Controls Keep Failing and What It Actually Means
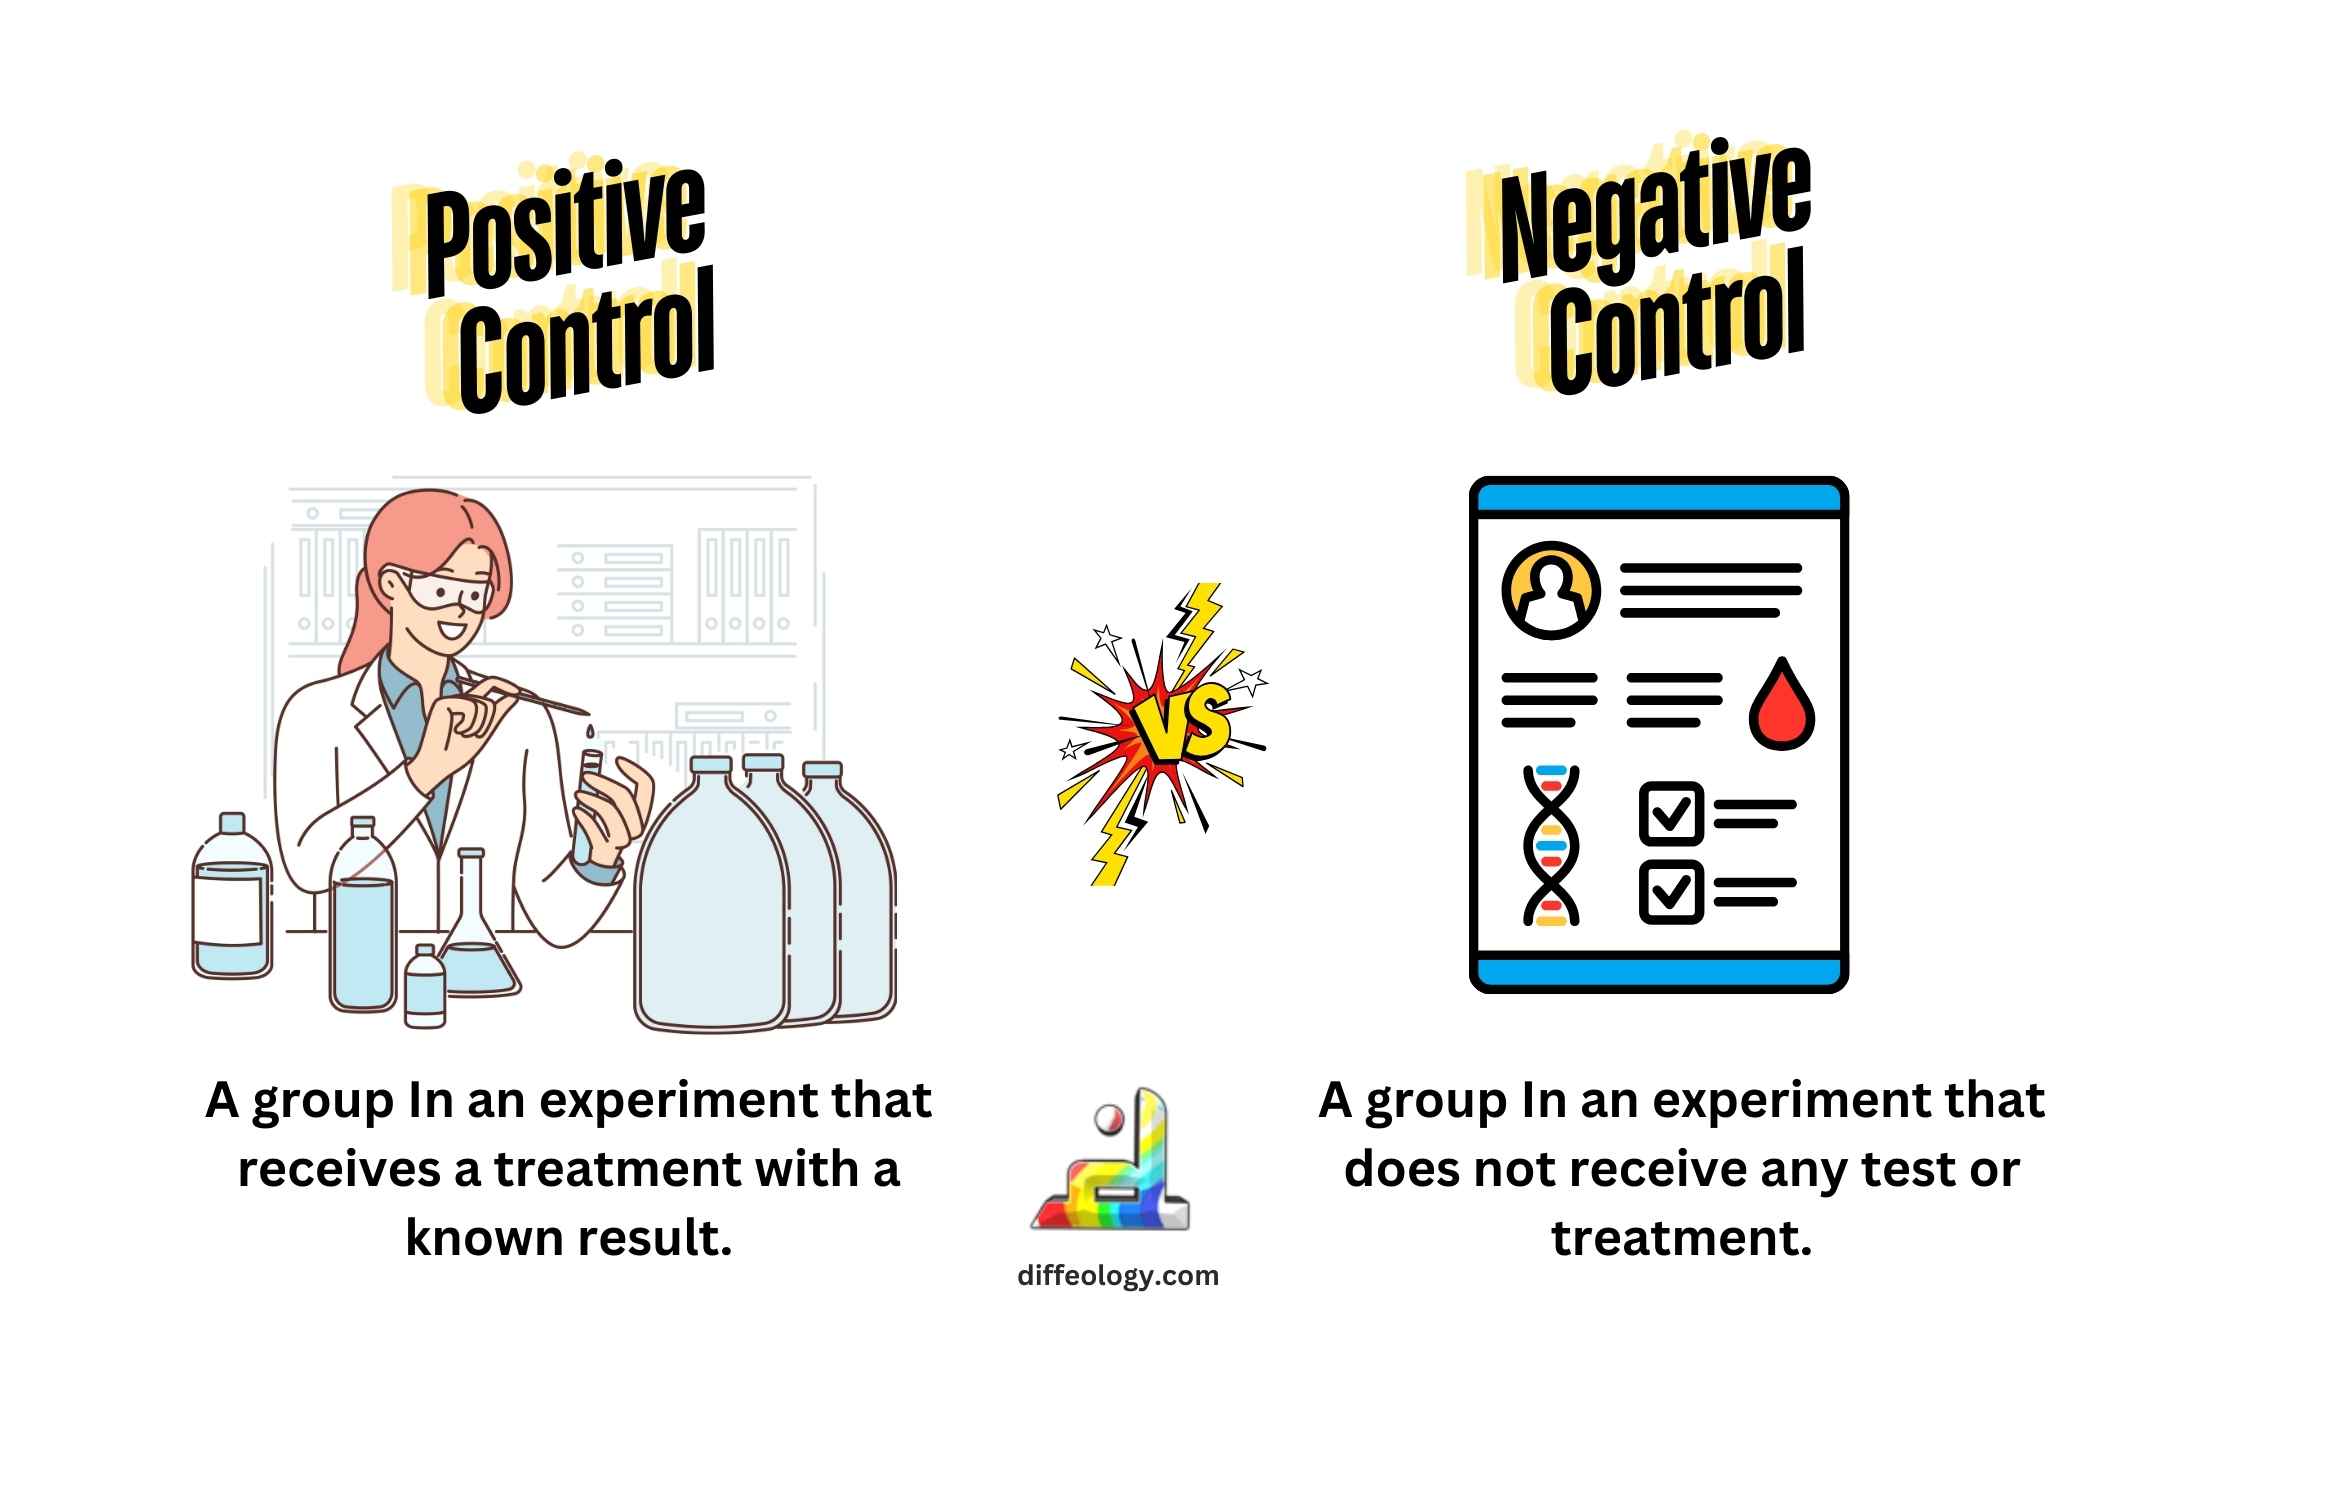
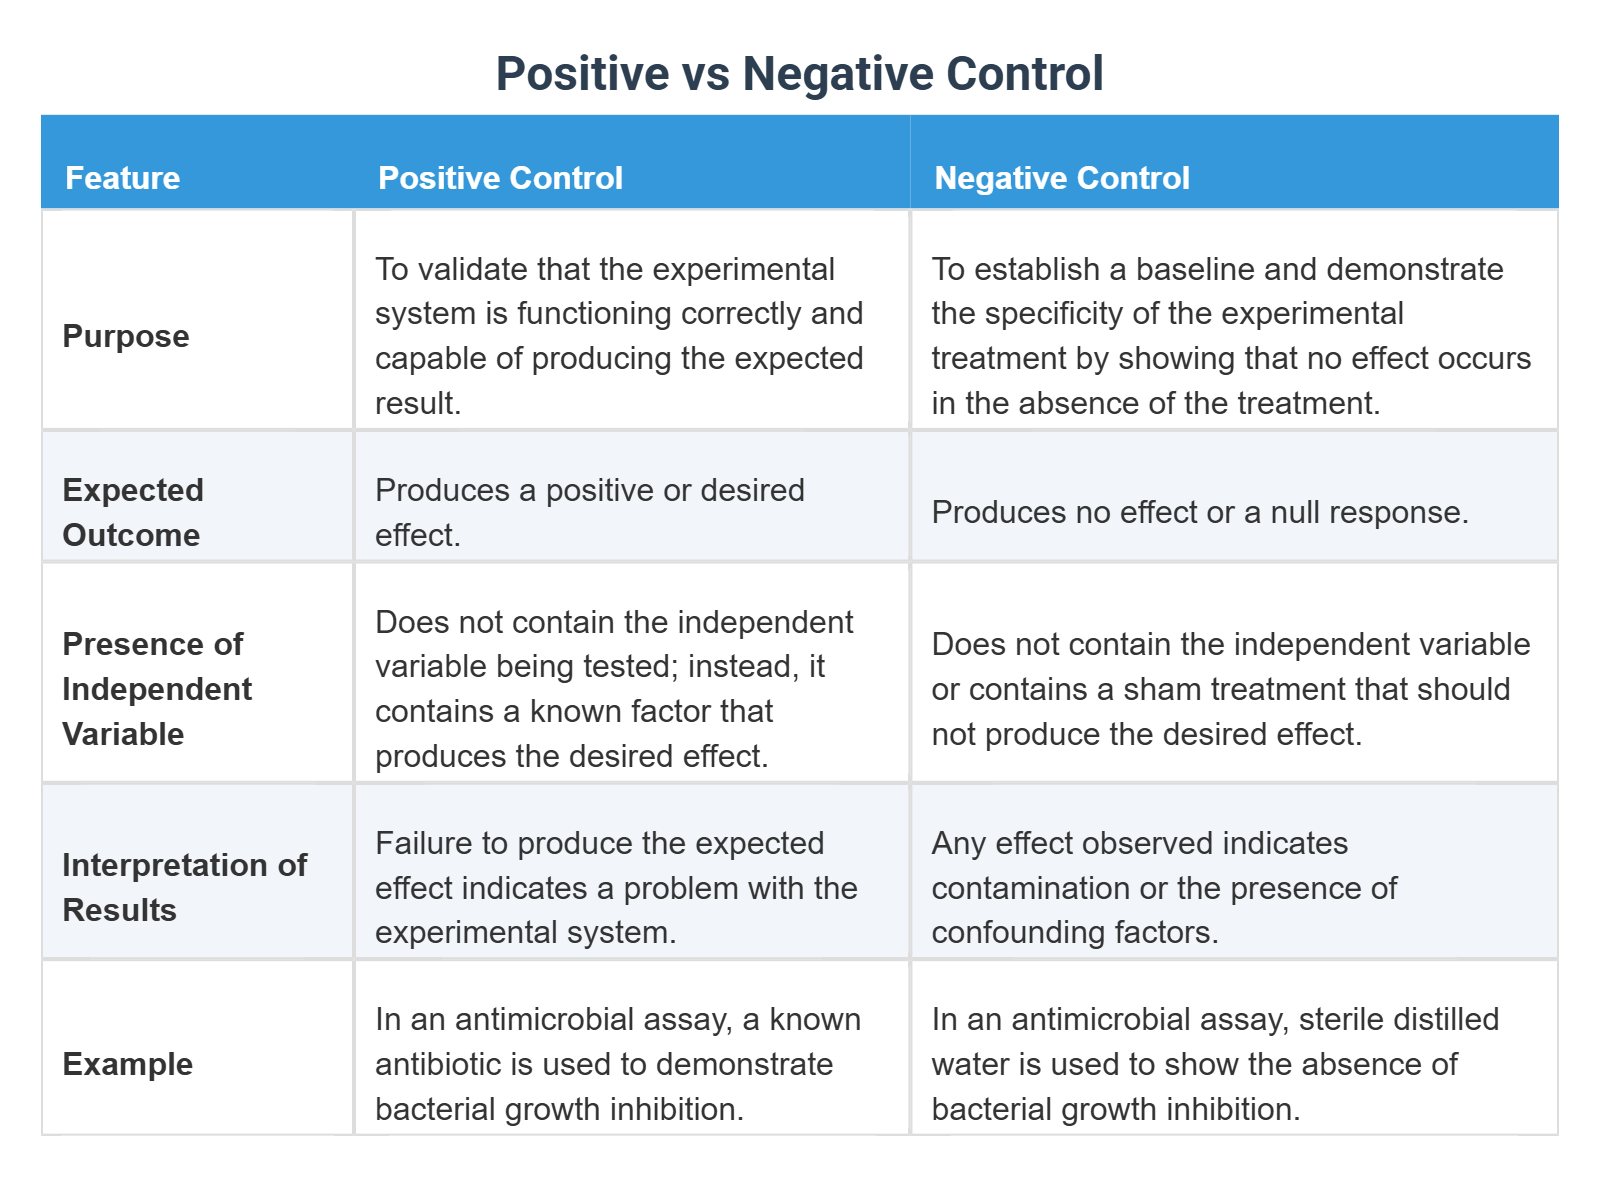
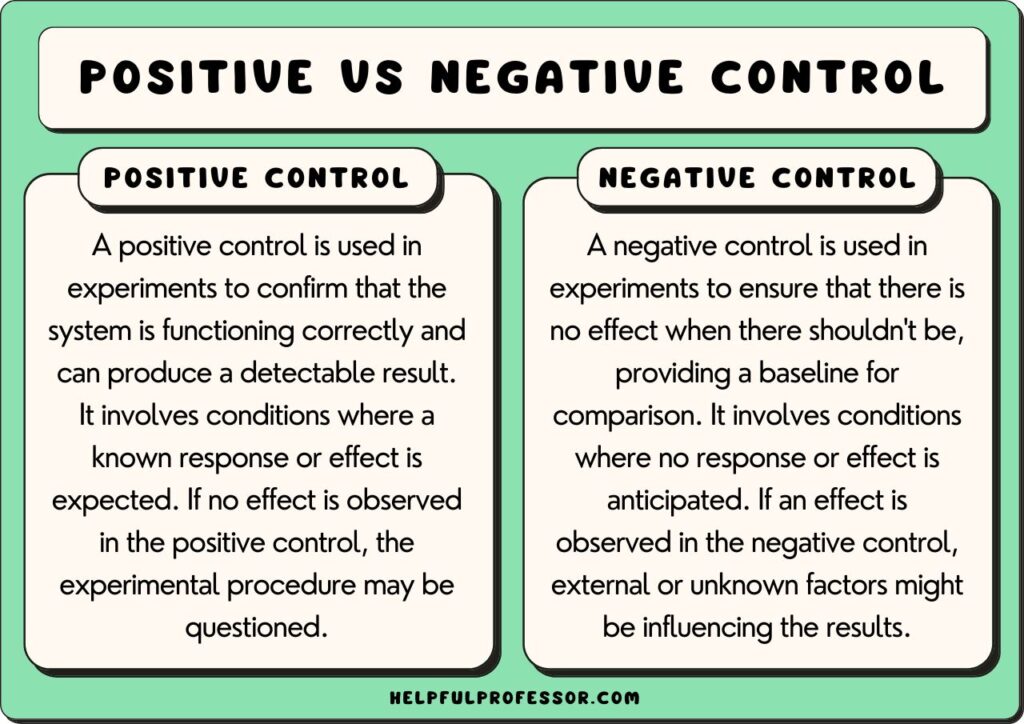
Positive and negative controls are the most misunderstood parts of any experiment. People treat them as afterthoughts, then wonder why their data looks like garbage. I have seen researchers skip them entirely, or run them on different days with slightly different reagents, and then draw conclusions from results that are essentially uninterpretable. The core concept is straightforward, but the practical execution is where everything falls apart. A negative control is a setup where you expect nothing to happen. It establishes your baseline noise. If your negative control shows a signal, you do not have a positive result, you have a contaminated or flawed experiment. A positive control is the opposite, it is a setup where you know something should happen, and it proves your system is capable of producing a detectable result when it should. The method you use determines everything. In PCR, your negative control is a no-template reaction with just water instead of DNA. If you get amplification there, your reagents are contaminated with someone else's DNA, probably from aerosolized carryover from a previous open tube. Your positive control would be a known template that reliably amplifies at the expected cycle threshold. In western blotting, your negative control might be a knockout lysate where the target protein is absent. Your positive control is a sample from a tissue or cell line where that protein is known to be abundantly expressed.
I spent three weeks troubleshooting a qPCR assay that kept giving false positives in the no-template control. The cycling conditions looked fine, the primers checked out on the in silico analysis, and the master mix was fresh. The issue turned out to be the pipette tip box I was using. I had been opening it repeatedly throughout the day, and the tips themselves were contaminated with trace amounts of plasmid DNA from a clone I had been preparing the week before. The contamination was sitting on the inside surface of the tips. Switching to filtered barrier tips and keeping the box closed between uses eliminated the problem completely. False negatives in the positive control are even worse because they make you think your assay failed when it might have actually worked, and you have no way to know which sample is reliable and which is not.
How to Design Controls That Actually Work
The first rule nobody follows is that controls must run in the same batch as your experimental samples. If you run your negative control on Monday and your test samples on Friday, you have not controlled for anything. Reagent lots degrade. Ambient temperature fluctuates. The thermocycler's block uniformity changes between sessions. Everything that could go wrong will go wrong differently on different days. Your negative control should challenge your assay, not coddle it. A dilute buffer alone as a negative control for an ELISA is mostly useless because it tells you nothing about cross-reactivity or non-specific binding. A better negative control uses a matrix that mimics your actual samples but lacks the analyte. If you are measuring a cytokine in serum, use heat-inactivated blank serum from a knockout animal or a cell line that does not express the target. This reveals background signal from the matrix itself, which is often where the real problems hide. For the positive control, use a sample that gives you a strong, clean signal at a concentration well within your standard curve's linear range. I recommend running it at multiple concentrations so you can verify linearity across your dynamic range. A single positive control at one concentration only tells you that the assay works sometimes, which is not especially useful information.
Get the Full Details
In cell-based assays the control strategy gets messier. A DMSO-only vehicle control is mandatory if your test compound is dissolved in DMSO, but it is not sufficient on its own. I once had a dataset where the positive control appeared to work perfectly, but the negative control showed unexpected apoptosis at a rate that was statistically indistinguishable from the treatment group. The cell line had been subcultured too many times and was undergoing replicative senescence. The apoptosis was happening regardless of treatment. The positive control masked this because it drove a much stronger effect, making the background noise look acceptable. Running a proliferation curve before starting the actual experiment would have caught this immediately.
Common Mistakes That Ruin Your Data
Using the wrong control type for your question is the most frequent error. A negative control does not prove causality. If you are testing whether inhibiting protein X reduces tumor growth, your negative control confirms the inhibition works, but it does not tell you whether the growth reduction is specific to that mechanism or a downstream effect of cellular stress. You need a rescue experiment or a second independent target to establish specificity. Another mistake is assuming that a passing control validates the entire experiment. Controls only validate what they are designed to detect. A clean negative control in a Bradford assay proves you do not have protein contamination in your reagents. It does not tell you whether your samples are degraded, whether your spectrophotometer is calibrated, or whether the protein in your samples is interfering with the dye binding. Each potential source of error needs its own control. Sample size for controls matters too. Running a single replicate of your negative control and five replicates of your treatment groups creates a statistical imbalance that invalidates most comparison tests. Controls should have the same n as your experimental groups, or you need to account for the difference explicitly in your statistical model. A common threshold is at least three independent replicates for each control condition, run on separate days if possible.
Documentation is where most people fail. You need to record the exact lot numbers of every reagent used in your controls, the date and time of the run, the operator, and the environmental conditions. When a control fails unexpectedly, this information is the only thing that will help you trace the problem. I lost two weeks of work once because my positive control suddenly dropped to half the expected signal, and I could not figure out whether it was the antibody, the substrate, or the plate I was using because I had not written down which lot of blocking buffer I had opened that morning.
When Controls Are Not Enough
No amount of controls can fix a fundamentally flawed experimental design. If your hypothesis requires a dose-response relationship and you only test one concentration, a perfect positive control will not save you from publishing an inconclusive result. Controls verify the technical performance of your assay, they do not verify the biological relevance of your approach. Sometimes the ideal control is simply not available. Knockout cell lines for certain proteins do not exist. Clean antibodies that show no cross-reactivity are rare. There is no standard reference material for many newly discovered biomarkers. In these cases, you need to be explicit about what your controls can and cannot tell you. A partial validation with whatever controls you have is better than no controls, but you should state the limitations clearly rather than implying a level of rigor that your experiment does not support. Blinding during control execution is another area where people cut corners. If you know which well contains the negative control, you are more likely to inadvertently exclude outlier values from it while retaining outliers from your treatment groups. This introduces selection bias that skews your results in a direction that looks like a positive finding. Randomize your plate layout and blind your sample IDs before you start any measurements.
The bottom line is that controls are not a box you check before you publish. They are an ongoing quality assurance process that should inform every decision you make during an experiment. When they behave unexpectedly, that is usually the most important data point you have, even if it means you need to redo three weeks of work.