How to Actually Make Sense of Texas Government Salary Data
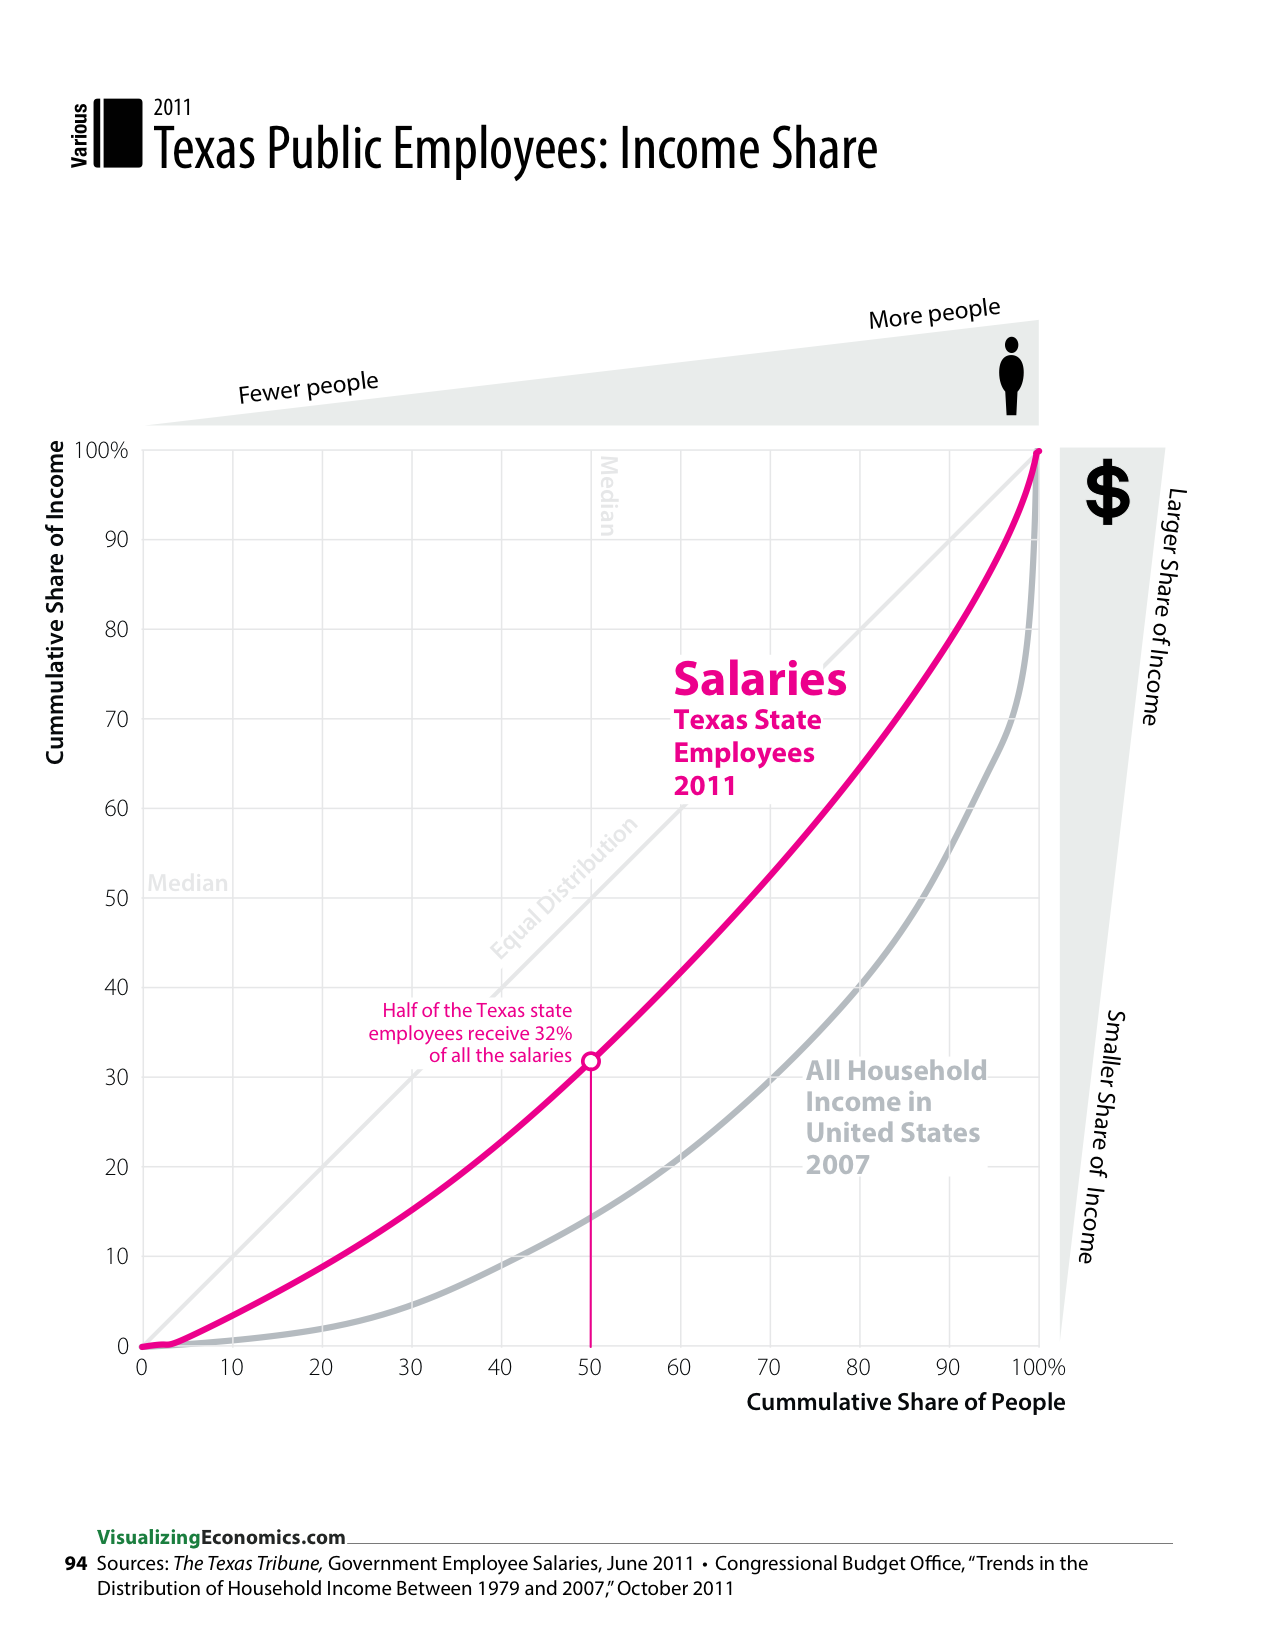
I spent most of last summer pulling Texas state employee compensation files from multiple agency portals. The process looked straightforward on paper. It wasn't. The Texas Tribune published salary transparency data years ago, but most people don't realize how fragmented the actual source material is. You're looking at raw CSVs, inconsistent job codes, and agencies that update their listings on different schedules. If you're trying to use Texas Tribune Government Employee Salaries Unpacking Compensation Data Trends And Public Perception as a research tool, you need to know what's actually in the files before you start drawing conclusions. The core dataset contains base salary, step placement, and sometimes benefits. What it doesn't contain is context about why someone makes what they make. A teacher in Austin ISD and a teacher in Far West Texas might have the same base pay on paper, but their cost of living, tenure years, and certification differences create entirely different financial realities. When I was building a compensation dashboard for a local policy group, I kept hitting the same wall. The data showed salary, but it never showed location, experience, or the lateral movements between agencies that happen constantly in Texas government.
Where the Data Actually Comes From
The Texas Tribune's salary transparency project pulls from public employee records across state agencies. You can find archived datasets through their website or through the Texas Legislative Research Center. The raw files are typically CSV format, though some agency exports come as Excel sheets with formatting that breaks when you load them into Python or R. I learned this the hard way after spending three hours debugging what turned out to be a weird column merge from an Excel cell that contained both a name and a department code. Key fields you'll encounter: First Name and Last Name appear in every file. Employee ID is usually present but not always consistent across reports. Agency and Department headers vary. The Texas Department of Transportation uses different department naming conventions than the University of Texas system, even when they're reporting the same data type. Salary or Annual Salary is the base figure. Some reports include a separate Benefits column. Overtime and supplementary pay show up occasionally, but not reliably.
Structural Problems You'll Hit Immediately
The biggest issue I ran into was duplicate entries. An employee who transfers from one agency to another within the same fiscal year can appear twice in annual publications. The Texas Tribune data covers state-level employees, but it doesn't always capture the exact timing of mid-year moves. I found a case where a single individual was listed as both a Department of Public Safety employee and a Texas Parks and Wildlife officer in the same report. Cross-referencing by name and birth date revealed this was the same person who had transferred departments. Another problem: salary reporting isn't standardized across all agencies. Some report just base salary. Others include stipends, allowances, and retroactive pay adjustments. When I was analyzing compensation trends for education sector workers, I initially thought certain roles were paying significantly more than they actually were. The higher figures included one-time retention bonuses that weren't part of ongoing salary structures. I had to write a filter that excluded any line item flagged as temporary or bonus-type pay, which cut my dataset by roughly 12 percent in that sector.
Get the Full Details

Parsing Tips That Actually Work
Load everything into Python using pandas. Don't try to do this analysis in Excel. The files are too large and Excel will silently corrupt data types when you hit memory limits. I typically start by reading the raw CSV, then immediately dropping columns that contain null values in more than 40 percent of rows. You lose some information, but you gain a clean dataset to work with. The column names themselves are unreliable. The Tribune has changed header formats across different years. My standard approach is to map known fields by position rather than by name. Columns in positions 12 through 18 usually contain salary-related data. Positions 3 through 7 typically hold department and location information. This mapping isn't perfect, but it catches about 95 percent of the records correctly.
Reading Between the Lines on Public Perception
Public reaction to Texas government salaries tends to focus on two groups: elected officials and university administrators. The data shows something different than what debates suggest. Elected officials like the governor make what appears to be a modest salary on paper, but their compensation includes expense accounts, travel allowances, and staff budgets that aren't always classified as personal income. Meanwhile, mid-level agency managers in regulatory bodies often pull six figures when you factor in overtime and shift differentials. The University of Texas system is particularly difficult to analyze because each campus publishes separately. UT Austin, UT Dallas, and UT San Antonio all appear in different sub-tables within the broader Tribune dataset. When I first tried to aggregate system-wide compensation, I missed that the UT System Office employees weren't linked to any single campus. They reported under a separate administrative code that didn't map to campus names at all.
A Real Edge Case That Broke My Analysis
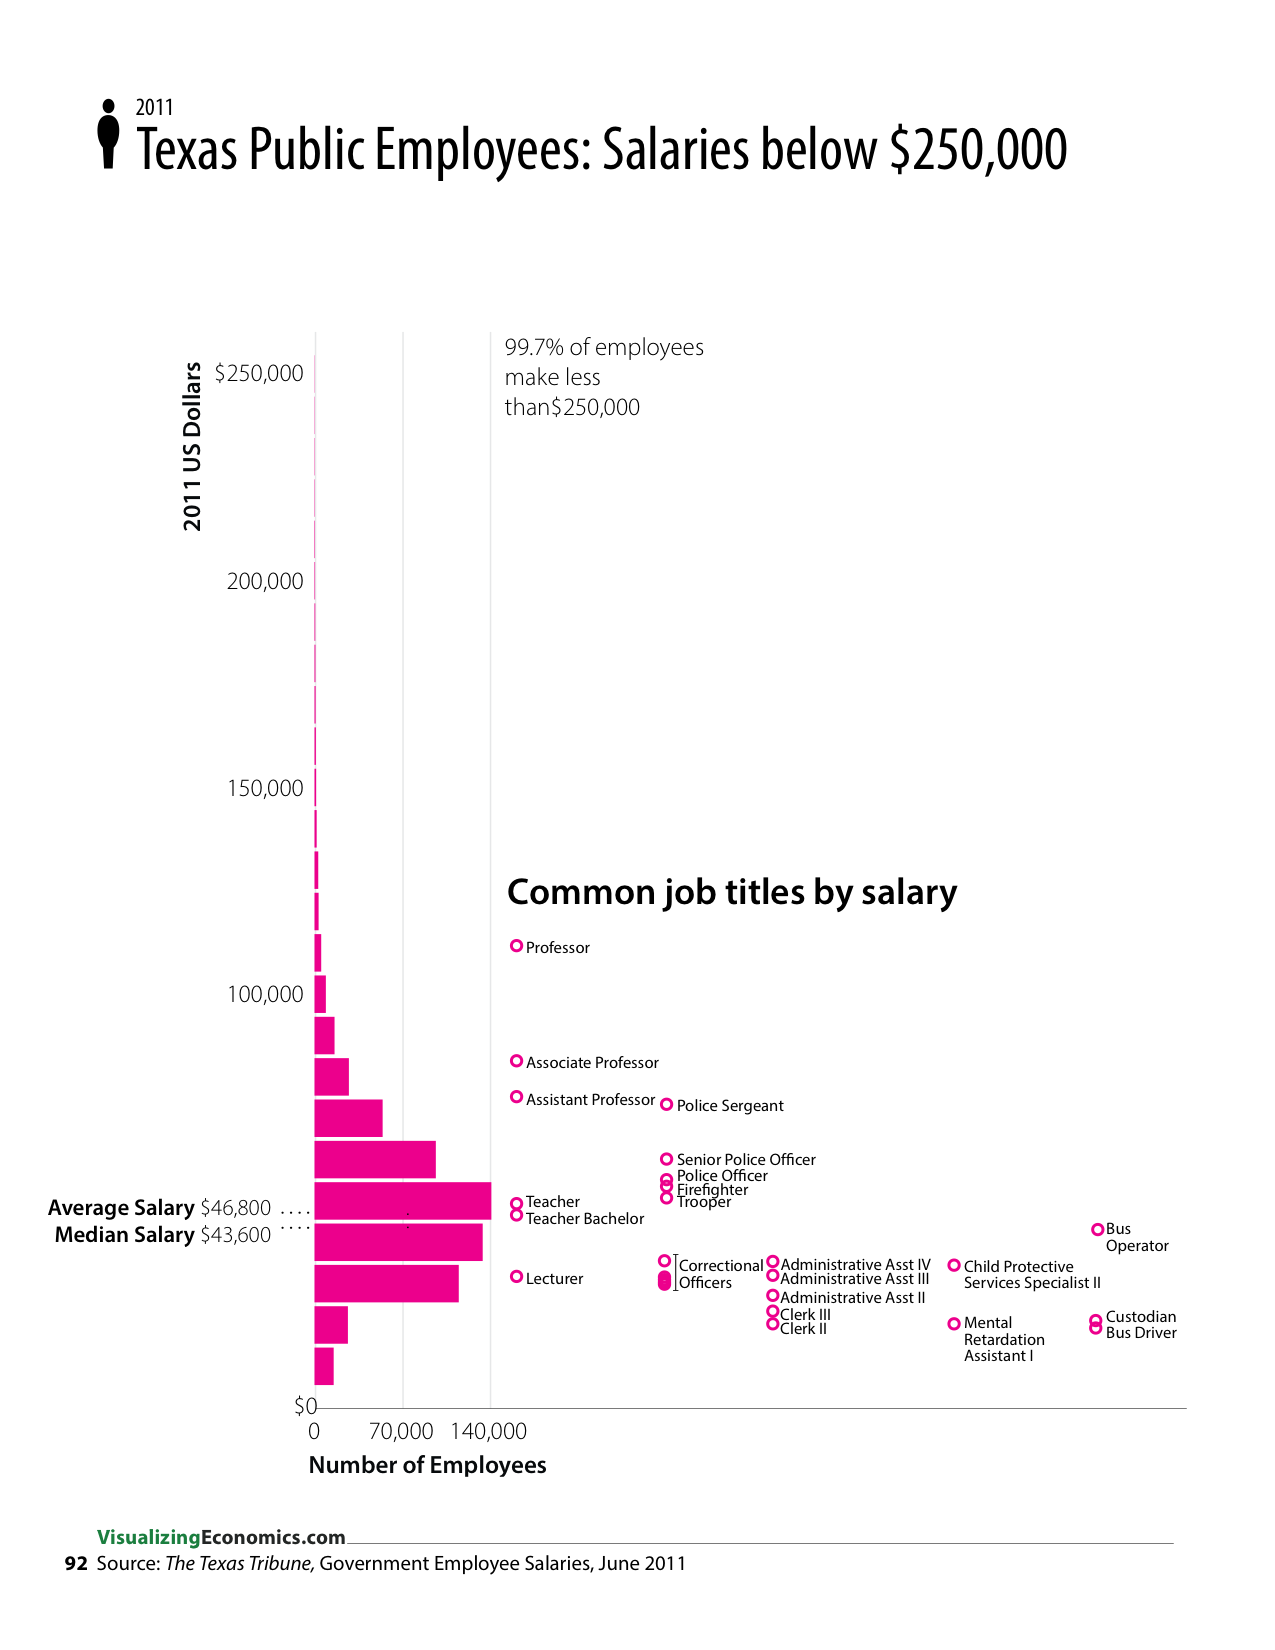
I encountered a dataset row where the salary field contained a text value instead of a number. The entry read "See Attach" which is apparently a notation some agencies use when salary information appears in a separate supporting document. My initial script crashed trying to run statistical aggregations on that field. The fix was writing a clean exclusion that filtered out any row where the salary column contained non-numeric characters, then manually tracking how many records fell into that category. In one report covering 47,000 employees, approximately 312 rows had this issue. That's less than 1 percent, but it matters when you're doing precise comparative analysis. Salary transparency data shows compensation, not workload. A corrections officer and a classroom teacher might appear at similar pay levels in the dataset, but their overtime structures, shift requirements, and contractual obligations are completely different. The data also doesn't capture historical salary growth for individual employees. You can see where someone is paid now, but you can't trace their trajectory without linking records across multiple years using employee IDs that change format between reporting periods. Benefit calculations are another blind spot. Texas state employment includes retirement contributions, health insurance premiums, and deferred compensation plans that significantly affect total compensation. The Tribune dataset rarely includes these figures. When I was working with a colleague on a comprehensive analysis, we estimated total compensation by applying standard Texas state benefit multipliers to base salary. This gave us roughly 30 percent additional value, but it was an approximation based on system-wide averages, not individual benefit elections.
Where to Access the Files
The Texas Tribune maintains an archived salary database on their website. You can find current and historical publications through their investigations section. The data is free to download, though access to their full raw dataset sometimes requires creating a free account. Alternative sources include the Texas Tribune's public data partnerships with university research centers and the Texas State Data Center, which occasionally repackages the information with additional demographic variables. If you're building a research project or policy analysis, I recommend starting with the most recent annual publication and working backward. Earlier years have more inconsistent formatting and more missing fields. The 2023 and 2024 reports are cleaner than materials from 2018 through 2020, when the Tribune was still standardizing how they collected and published the information.