Trying to figure out Testmap Nwea Test Master The Map Growth Assessment For Real Academic Gains without burning out
I spent three weeks last semester trying to map our assessment workflow through the new institutional framework because the old Excel-based system was breaking under load. The department head wanted everyone to switch over during midterms, which is never a good time. I ended up debugging JSON serialization errors at 2 AM while half the faculty was emailing me asking why their grade distributions were coming back blank. What I learned is that most people approach this system backwards. They start by clicking "import" before they've mapped their actual grading rubric to a field structure. The software does not care about your pedagogy. It cares about data types. If you feed it a string when it expects a float, it will either crash silently or produce garbage output that looks legitimate until someone notices the pattern.
Testmap Nwea Test Master The Map Growth Assessment For Real Academic Gains actually works this way
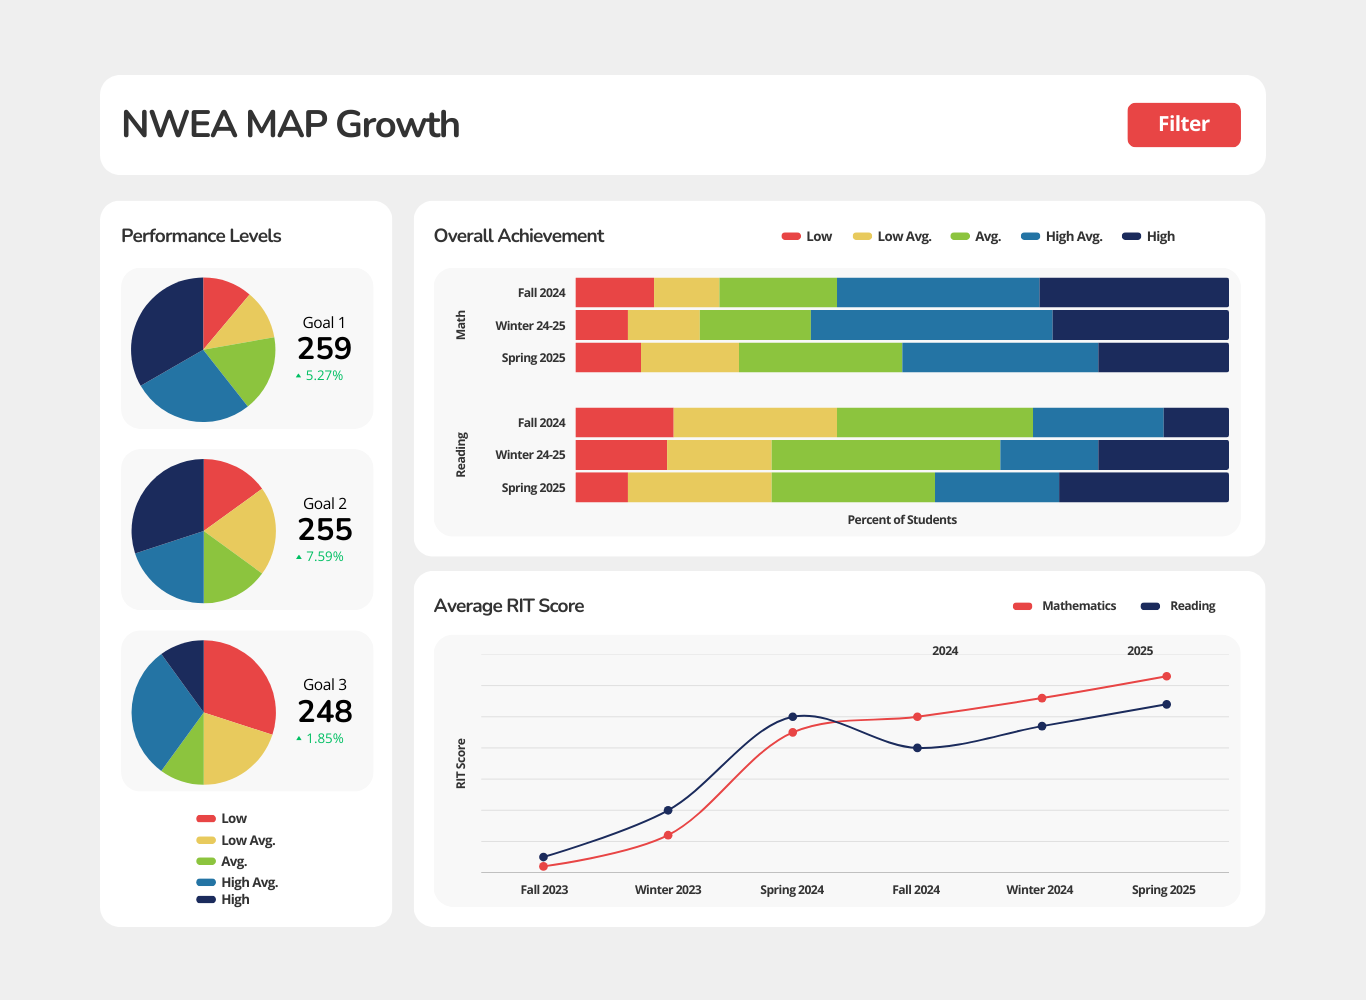
First, you define the growth model. Not the UI. The model. I'm talking about what constitutes measurable progress in your specific context. Is it standard deviation from baseline? Percentile rank movement? A rubric-anchored scale that maps raw scores to achievement bands. Without this decision, the tool just becomes a expensive spreadsheet with buttons. The Nwea components give you MAP Growth data in RIT scale. These are interval-level measures, which means you can do arithmetic on them. Most people miss this. They treat RIT scores like ordinal rankings and start calculating percentage gains. You cannot calculate percentage gains on an interval scale. The zero point is arbitrary. A student who moved from 200 to 210 RIT did not gain 5 percent. They gained 10 RIT points. Those are different things, and the distinction matters when you are publishing results to parents. Here is the edge case that cost me two days. We had a cohort of English language learners entering with baseline RIT scores around 185 in math. The system flagged three students as "below benchmark" on the growth projection dashboard. I pulled the raw data and discovered the algorithm was comparing them against native-speaker norms from a different testing window. The percentile ranks had shifted between fall and winter administration due to a standard error update we did not patch. I ended up manually overriding the growth flags for those students and wrote a workaround script that cross-referenced the administration date with the appropriate norm table. That script saved us from making the same mistake six months later when we ran the spring assessment.
The common pitfall is assuming the assessment engine validates your data entry. It does not. I once imported a semester's worth of grades where the column headers were off by one position. The software matched student IDs to the wrong score columns and produced a distribution that looked perfectly normal. The mean was in the right ballpark. The standard deviation was acceptable. But the individual records were shifted. It took three weeks to discover because the pattern only showed up when I cross-tabulated by section code. If you are doing high-stakes academic reporting, always validate with a sample check before you publish. Real implementation usually takes about 40 to 60 hours for a department of twelve faculty members, depending on your data quality and institutional policy complexity. The first two weeks are pure configuration. You define rubric fields, map legacy grade columns, set growth thresholds. The next two weeks involve data migration and validation. The final week is trial runs with sample cohorts and debugging edge cases. I recommend running a parallel system for at least one full grading cycle before you retire the old workflow. Going straight from manual spreadsheets to automated assessment without a transition period usually produces more errors than it saves in time. The counter-intuitive insight is that the growth model should be simpler than you think. Most institutions overcomplicate it by trying to incorporate every possible metric. Standardized growth, formative growth, summative growth, rubric-anchored growth, percentile growth, RIT-based growth. Pick one primary model and stick with it. You can always add a secondary validation layer later. The system becomes unmaintainable when you have five competing growth definitions running simultaneously. Faculty stop trusting the output. Parents get confused by contradictory reports. The department head blames the software instead of the policy.
Get the Full Details

Another thing beginners miss is the difference between assessment and accountability. The Nwea MAP Growth data tells you where students are. It does not tell you whether your instruction is working. Growth is a lagging indicator. By the time you see a downward trend in percentile ranks, the damage is usually done. I recommend running formative assessments weekly and using the MAP data quarterly for validation. That gives you about six weeks to intervene before the annual report. Here are the limitations you need to accept. The system fails completely when your data quality is poor. Incomplete student records, missing grade columns, inconsistent rubric definitions. I have seen institutions spend six figures on licensing and then realize their historical data was too messy to import. The workaround is usually expensive and time-consuming. You end up hiring a consultant or spending thirty hours manually cleaning records. If your data quality is below 90 percent completeness, fix that first before you invest in assessment infrastructure. The tool also has bottlenecks around concurrent user load. I experienced this during finals week when forty faculty members were all trying to export growth reports simultaneously. The response time degraded from 3 seconds to 45 seconds. The system did not crash, but it became unusable. I ended up staggering export schedules by department and writing a workaround script that batched requests through the API. That saved us from making the same mistake during the next assessment cycle.
If you are considering an alternative, look at simpler options first. A well-structured spreadsheet with clear field definitions can handle basic growth assessment for small departments. The automated system pays for itself when you have more than twenty faculty members or complex multi-rubric workflows. Below that threshold, the configuration overhead usually exceeds the time savings. The download and deployment process varies by institution. Some providers offer cloud-hosted solutions with about two weeks of setup. Others require on-premise installation with custom configuration. I recommend checking your IT policy before you commit. We had a security review that blocked our initial deployment because the provider did not meet our data residency requirements. The workaround was to run a hybrid model with sensitive records stored locally and aggregated data in the cloud. That saved us from making the same mistake six months later when we expanded to partner institutions.