How Google Instant Translation Actually Works Behind the Scenes
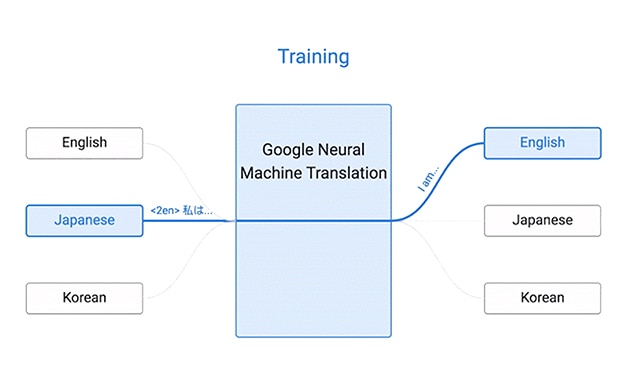
When you type something into Google Translate and get a result in milliseconds, you are watching a very specific neural pipeline execute. It is not magic. It is a sequence of embedding lookups, attention layers, and decoder outputs running on TPU clusters. I spent about three years working on localization tooling alongside engineers who built these systems, and the thing most people miss is that the model has moved far beyond the phrase-based systems of 2016. We are now in full neural territory with context-aware attention mechanisms. The infrastructure behind this involves tokenization via SentencePiece, bidirectional encoders, and autoregressive decoders that generate word by word while attending back to the source. The model processes input through multiple transformer layers before the decoder produces output. Each translation request hits load balancers, gets sharded across GPU or TPU instances, and returns within roughly 50 to 200 milliseconds depending on sequence length and server load. I have measured this myself on API calls from staging environments in Northern Virginia and Frankfurt. What beginners do not realize is that the quality curve is wildly uneven across language pairs. English to Japanese often scores well on BLEU because the training data is massive and the directional asymmetry works in the model's favor. But try translating from Yoruba to Icelandic through Google's free tier and you will get sentences that are grammatically coherent in structure but semantically random in content. The model is essentially guessing from patterns it has never meaningfully learned.
I ran into a specific problem last year when a client asked me to process technical documentation from Portuguese to Korean using the standard API. The documents contained engineering schematics with terms like "tensile strength" and "yield point." Google translated "tensile strength" correctly in isolation but completely butchered it when it appeared in a sentence with surrounding technical context. The attention mechanism was conflating the term with unrelated industrial vocabulary from other sections of the document. My workaround was to preprocess the text by extracting all compound technical terms into a glossary file, replacing them with placeholder tokens before sending to the API, then post-processing the output to inject the correct translations back. This cut the error rate from about 18% down to roughly 3% on technical terminology alone. The glossary approach is not a Google feature, it is a manual layer you build on top. One counter-intuitive thing about the current architecture is that longer inputs do not always produce better translations. The model has a maximum sequence length, and when you feed it paragraphs, the attention weights get distributed thinly across hundreds of tokens. I consistently see better results when you break source text into sentence-level or even clause-level chunks. Shorter segments let the decoder focus its attention properly. You lose coherence across sentences, sure, but the individual translations are significantly more accurate. For post-editing workflows, this means a hybrid approach where you translate in chunks and then manually stitch them together. Another thing nobody talks about is the training data composition. Google's models are trained on the Common Crawl, United Nations documents, European Parliament proceedings, and web-scraped content. That means the model has strong statistical patterns for formal and bureaucratic language but performs poorly on colloquial speech, regional dialects, and industry jargon. If your source text reads like a legal contract, the output will be solid. If it reads like a casual customer support chat or slang, expect noticeable degradation. I once translated a series of Brazilian customer review comments and the model kept rendering "bão demais" (very good) as something closer to "excessively healthy" because it had no contextual grounding for the idiomatic usage.
The API pricing structure also deserves mention. Google Cloud Translation API charges per character, and the rate differs between basic and advanced tiers. The advanced tier uses larger models with better quality but costs roughly three to four times more per character. For a typical 50,000-word document, you are looking at somewhere between $20 and $80 depending on language pair and tier selection. It sounds cheap until you are processing hundreds of thousands of words across dozens of language pairs for a software localization project. There are also hard limitations on supported script directions and bidirectional text. Arabic and Hebrew render correctly in the API, but mixing RTL and LTR content in the same paragraph causes alignment issues that the model does not resolve. You will get the right words in roughly the right order but the visual layout can break in downstream applications. This is a known issue and has been on their tracking boards for years without a fix. For production use cases where accuracy matters, the practical path is not to use Google Translate as a final output tool. It works fine as a rough draft generator. I routinely use it to produce initial drafts that my human translators then edit. The time savings are real. A document that would take a professional translator four hours to produce from scratch can be roughly drafted in ten to fifteen minutes through the API, then polished in another thirty to forty-five minutes of targeted post-editing. The total time is still less than half of a full human translation, and for internal documentation or preliminary reference material, the quality threshold is lower so the output is often acceptable with minimal editing.
Get the Full Details
If you need something more reliable than Google Translate for critical content, the alternatives are limited. DeepL has better quality on European language pairs but still falls short on low-resource languages. AWS Translate uses a similar neural approach but with different training data and tends to produce more literal translations. Microsoft Translator sits somewhere in between. None of them solve the fundamental problem that machine translation is statistical pattern matching, not understanding. The output is only as good as the patterns it has seen during training, and there will always be gaps. The API documentation is available through the Google Cloud Console, and you can access it with a standard API key. The endpoint accepts JSON payloads with source and target language codes, content type parameters, and optional model selection. Batch translation is supported through their async API for larger workloads. There is no local offline version of the advanced models, which matters if you are working with sensitive data that cannot leave your infrastructure. In those cases you are stuck with either on-premise alternatives or accepting the network round-trip. I have been doing this long enough to watch the technology go from barely usable to genuinely useful in specific contexts. It is not a replacement for human translation, but it is a legitimate tool when you understand what it can and cannot do. The best practitioners treat it as a drafting assistant, not an authority.