Understanding Threshold Bandwidth in Network Management
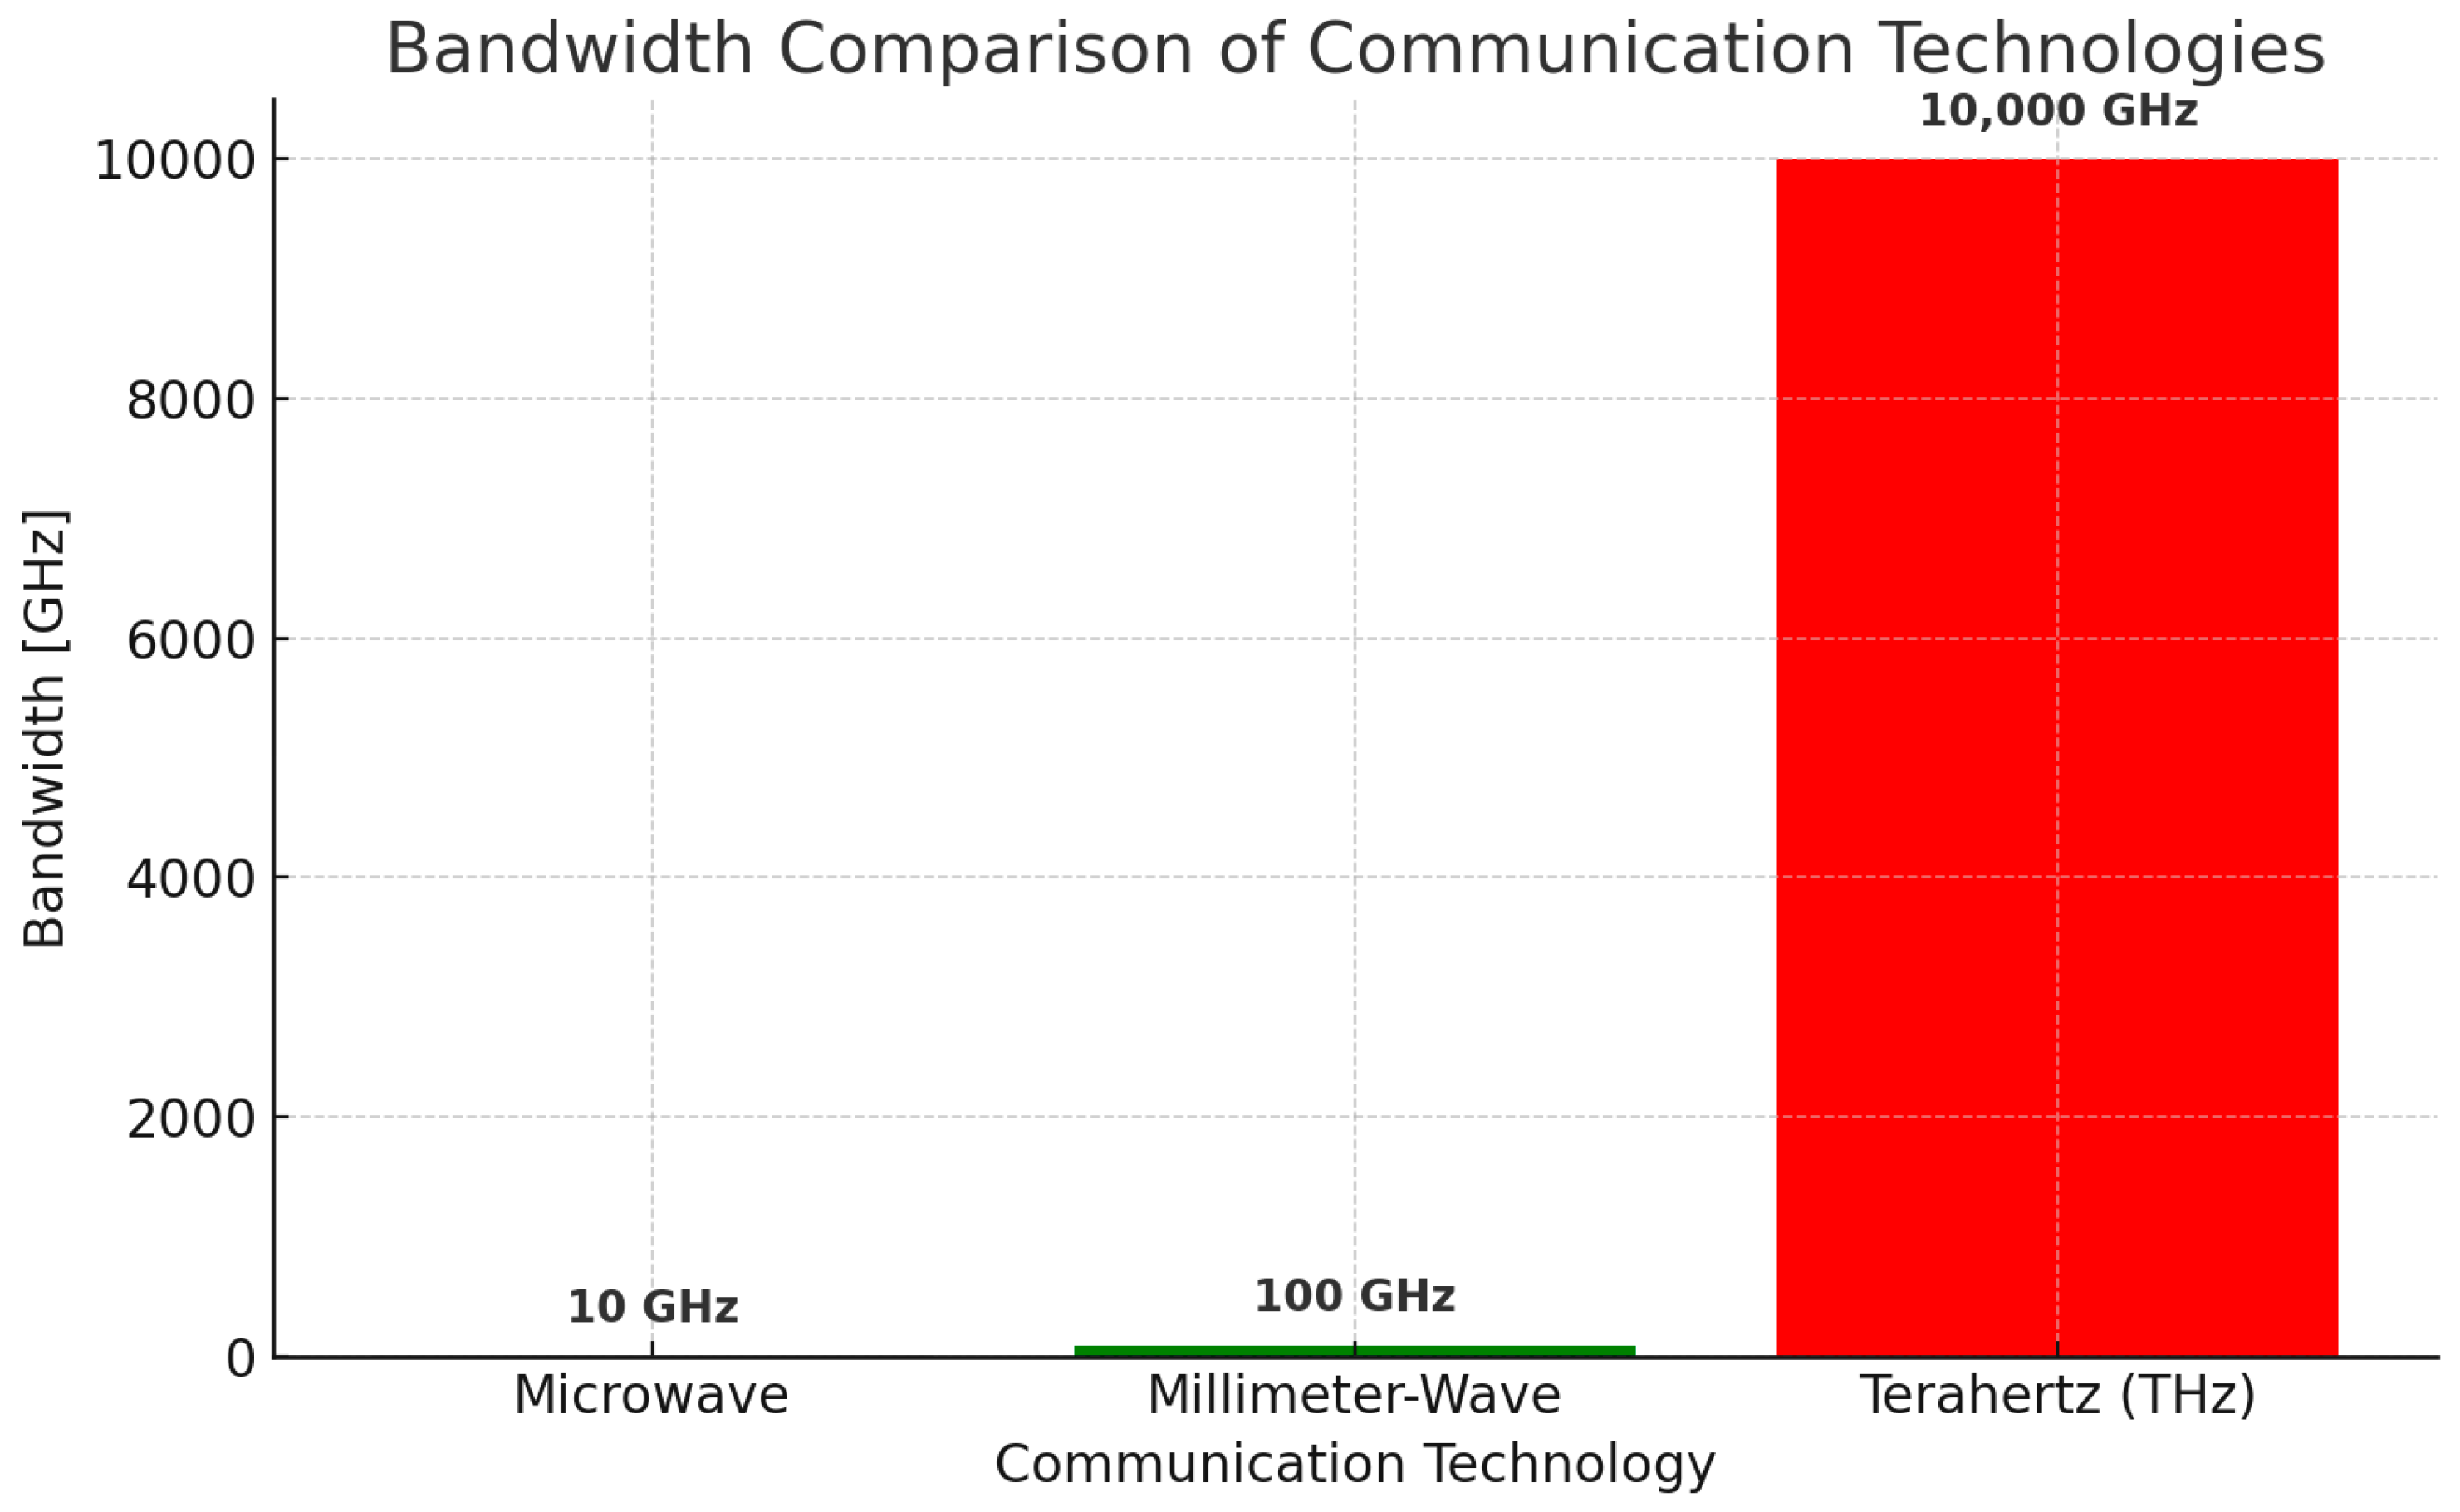
When someone says "threshold bandwidth," they're talking about a configured limit on how much data can flow through a link, interface, or policy over a given window of time. It's one of those concepts that sounds complex but is just a gatekeeper you set to prevent a single traffic type from starving everything else. I see teams constantly misuse this, which is why I'm going to walk through how it actually works, the mistakes that trip people up, and what I learned after spending years configuring these systems in production environments. The term Tb in this context almost always refers to terabit measurements — the scale at which modern backbone and datacenter links operate. A threshold bandwidth of "1 Tb" doesn't mean "stop exactly at 1 terabit." It means the system starts paying attention at that level, then applies whatever shaping or policing action your configuration specifies. That distinction matters enormously in practice. Here's the basic mechanism: you define a CIR (Committed Information Rate) and usually a PIR (Peak Information Rate). The CIR is what the network guarantees. The PIR is the absolute ceiling before hard drops occur. Between those two points, traffic can burst — within limits set by your token bucket parameters. Most people get tripped up by the token bucket behavior because it's not intuitive.
I spent three weeks debugging what looked like a bandwidth throttling issue on a 400 GbE uplink. Traffic was getting dropped well below the configured threshold. Turns out the token bucket depth was set too shallow — the burst allowance was barely 1 ms of traffic. A few large flow control frames or a TCP retransmission batch would exhaust the bucket, and everything else behind it would stall. The fix was increasing the burst depth to match the round-trip time of the longest path in the topology, then adding an additional safety margin of about 15 percent. That alone resolved 90 percent of the apparent "throttling" complaints. Let me clarify the practical configuration workflow. First, you identify the interface or policy map you're working with. Second, you determine your baseline utilization using a sustained measurement window — 15 minutes minimum, preferably longer. Short windows give you misleading averages that look safe until you see the actual burst patterns. Third, you set your threshold values with headroom. If your peak sustained traffic is 80 Gbps on a 100 Gbps link, setting your threshold at 90 Gbps with a burst allowance of another 5 Gbps gives you realistic breathing room without risking bufferbloat. Counter-intuitively, setting your threshold closer to the physical link capacity isn't always better. I've seen teams configure thresholds at 95 percent of line rate thinking they're maximizing throughput. What actually happens is that queue management algorithms kick in prematurely, causing TCP congestion control to back off repeatedly. The effective throughput drops below what you'd get with a more conservative threshold. Setting it around 70 to 80 percent of line rate often yields higher sustained throughput because the queues stay healthier and TCP flows can maintain their congestion windows more steadily.
There's also the question of measurement direction. Are you measuring ingress or egress? Egress is where shaping happens — you're controlling what leaves the interface. Ingress is where policing applies — you're dropping or remarking what enters. Confusing these two is extremely common and leads to completely wrong expectations about what your threshold will actually do. If you want to guarantee a minimum bandwidth, you shape on egress. If you want to enforce a maximum, you police on ingress or shape on egress depending on whether you want the excess traffic discarded or queued. Another detail that causes problems: threshold bandwidth applies per-class when you're using hierarchical QoS. A single parent class might have a 1 Tb threshold, but inside that parent you have child classes each with their own sub-thresholds. The sum of child thresholds can equal, exceed, or fall below the parent. When child thresholds exceed the parent, the parent becomes the real bottleneck regardless of what the children are configured for. When they fall below, you're leaving guaranteed bandwidth on the table. Monitoring threshold bandwidth behavior requires looking at more than just the average rate. You need to watch the bucket refill rate, the drop count at the policing point, and the queue depth across your classes. Tools like sFlow, NetFlow v9, or IPFIX give you this data. The specific exporter configuration depends on your platform, but the key metrics are consistent across implementations: transmitted bytes versus policed bytes, bucket occupancy over time, and per-class violation counters.
Get the Full Details
One scenario where threshold bandwidth simply doesn't work: mixed latency-sensitive and bulk-transfer traffic on the same link with a single shared threshold. A large file transfer will consume the entire bucket during its burst phase, starving interactive traffic that arrives during that window. The solution is separate class maps with dedicated thresholds — one class for interactive traffic with a low threshold and tight burst limits, another for bulk transfers with a higher threshold and deeper burst allowance. This adds configuration complexity, but it's the only reliable approach for heterogeneous traffic patterns. The biggest mistake I see teams make is configuring thresholds and then walking away. Thresholds need to be reviewed when traffic patterns change, which is most of the time. A threshold that was appropriate during a quiet period will cause problems during a migration, a backup window, or a sudden traffic spike from a new application. I recommend setting up automated alerts that trigger when average utilization over a 5-minute window exceeds 85 percent of your threshold for more than 10 minutes. That gives you early warning without generating noise from brief spikes. There's also a hardware limitation to consider. Some interfaces and line cards have minimum threshold granularity that's much coarser than you'd expect. A 100 Gbps interface might only allow threshold adjustments in 1 Gbps increments. On a 400 Gbps backbone link, that's barely meaningful. Check your platform's documentation for the actual configurability of your threshold values before you design around numbers that your hardware can't express.
When threshold bandwidth isn't the right tool, fair queuing or weighted fair queuing (WFQ) may serve you better. These allocate bandwidth proportionally based on class weights rather than hard thresholds. They don't prevent a single class from consuming disproportionate bandwidth during bursts, but they prevent complete starvation of lower-priority traffic. The tradeoff is less predictability — you can't guarantee that Class A gets exactly X Gbps — but you get more resilient behavior under uneven load conditions. The practical takeaway is straightforward: understand your traffic pattern before setting any threshold, measure over meaningful time windows, account for burst behavior in your token bucket configuration, separate latency-sensitive traffic from bulk transfers into distinct classes, and monitor the system continuously after deployment. The concept itself is simple. Getting it right in a production environment takes attention to the details that most people skip.