Setting Up Realtime Streaming Analytics Without Losing Your Mind
Most teams building streaming infrastructure don't realize they're flying blind until they have a full outage. That's what happened with us last year, and it cost us about six hours of customer-facing downtime before we figured out we had zero visibility into buffer events, bitrate switches, or connection failures across our CDN edge nodes. What we ended up doing wasn't elegant, but it worked. I'll walk through the process as it actually went down, not the sanitized version you see in press releases. The core challenge with realtime streaming analytics is that traditional monitoring tools were built for infrastructure health, not for the actual streaming experience. A server can be up, the CDN can be routing fine, and your viewers can still be watching a frozen screen. You need observability that tracks the video pipeline from ingest to playback, not just whether your boxes are green. This is where Streamesst Revolutionizes Digital Streaming Performance With Breakthrough Realtime Analytics enters the picture, though I should say upfront that it isn't a magic wand and has some real limitations I'll get to.
Streamesst Revolutionizes Digital Streaming Performance With Breakthrough Realtime Analytics
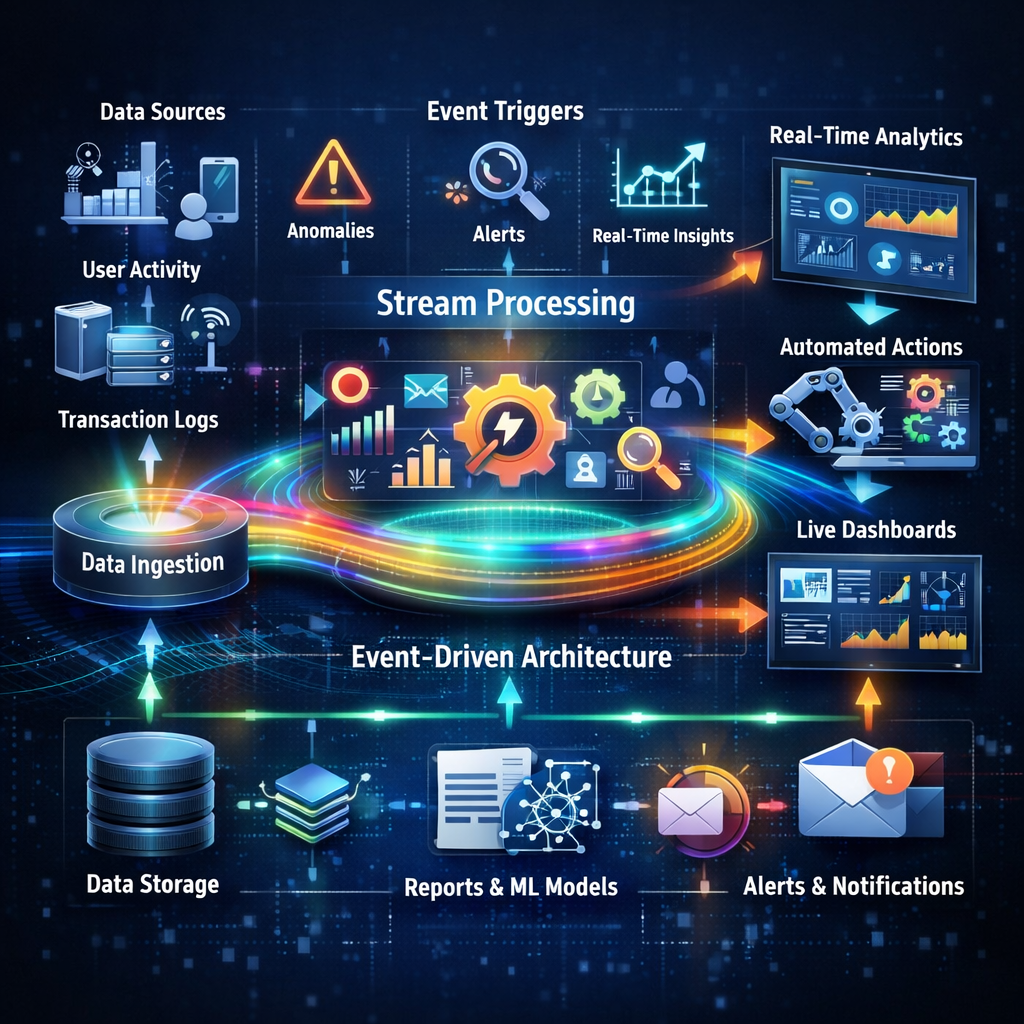
The platform works by instrumenting the streaming client and server both. On the server side, it hooks into your origin and edge delivery points to capture metrics like rebuffering ratios, quality level transitions, DRM handshake failures, and adaptive bitrate switching patterns. On the client side, the SDK collects playback telemetry — start-to-play time, stalls, decode errors, network type changes, and even device-specific performance characteristics. All of this data gets aggregated into a realtime dashboard with sub-minute latency, which is the part that actually matters when you're trying to catch a problem before it compounds. The initial setup is straightforward if you know what you're looking at. I'll break it down the way we actually did it. Step one: instrument your origin and edge. This means deploying the Streamesst monitoring agent on each node that handles stream ingestion and delivery. The agent works as a sidecar or proxy depending on your stack. For Docker-based deployments, it's a one-line addition to your compose file. For bare metal or Kubernetes, you'll need to configure the sidecar injection properly. We ran into an issue where the agent's memory footprint was significantly higher on our edge nodes than expected — about 400MB per instance versus the documented 250MB. The fix was adjusting the heap configuration in the agent's settings file, which we found by running their diagnostic tool and comparing against the baseline documentation. If you skip this step, you'll likely see performance degradation on constrained edge instances without understanding why.
Step two: integrate the client SDK. This is where most teams hit friction. The SDK supports HLS, DASH, andSmooth Streaming, but the integration details vary significantly by player framework. For ExoPlayer and Shaka Player, the SDK provides direct modules. For custom players or less common frameworks, you'll be working with a lower-level event API and mapping playback events yourself. We spent approximately two days mapping events for our Apple TV implementation because the SDK's documentation for tvOS assumed a standard AVPlayer setup that didn't match our custom wrapper. The workaround was examining the raw telemetry events in the SDK's debug log output, identifying which system events corresponded to what we actually needed, and writing a custom event filter layer. It wasn't pretty, but it got us complete coverage within a day after the initial struggle. Step three: configure your dashboards and alerts. The platform comes with preset dashboards, but the presets are generic. They show you data, they don't necessarily show you the right data for your use case. We learned this the hard way when our first alert was triggered by a routine QoE drop on a single region that was actually a scheduled maintenance event we'd forgotten to exclude. The configuration interface lets you set up geo-based exclusions, time-based baselines, and custom metric thresholds, but finding these settings required digging through three different menus. Once configured properly, you can set alerts for specific conditions — anything from a rebuffer ratio exceeding 3% in a region to a sudden spike in DRM failures across all nodes.
Get the Full Details
The Implementation Details That Actually Matter
Here's what the documentation doesn't emphasize enough: the accuracy of your analytics depends heavily on timestamp synchronization across all instrumentation points. If your edge nodes, origin servers, and client SDKs have even slightly skewed clocks, your correlation analysis falls apart. We initially saw what looked like impossible latency patterns where client-side buffering events appeared to occur before the corresponding server-side delivery events. NTP sync on all nodes resolved this immediately, but it was the kind of thing that eats a morning before you realize what's happening. The data retention policy is another practical concern. By default, high-resolution telemetry data is aggregated into 5-minute buckets for long-term storage, with raw events available for about 72 hours. If you need longer retention or finer granularity, you can export to an external data warehouse, but this adds significant complexity. We connected the platform to our existing BigQuery setup, which worked well but required building custom pipelines to handle the event schema. The raw event format includes things like precise buffer fill levels, individual chunk download timings, and device sensor data from mobile clients — information that's only useful if you're prepared to actually query it. One counter-intuitive thing to understand is that more instrumentation isn't always better. Every data point you collect has a cost, both in terms of client-side performance overhead and storage. Running our analytics pipeline at maximum detail during a live event caused noticeable CPU spikes on lower-end mobile devices. We had to tune the collection frequency dynamically — reducing telemetry sampling on resource-constrained devices while keeping full detail on desktop and high-end mobile. The SDK supports adaptive sampling through its configuration API, but it requires actual testing on target devices to get the settings right. We iterated through about four configuration rounds before settling on values that kept the overhead under 2% CPU across our target device spectrum.
Where This Actually Falls Short
I need to be blunt about the limitations because the marketing material won't cover this. The platform's greatest weakness is cross-CDN correlation. If you're streaming through multiple CDNs for redundancy or geographic optimization, the analytics don't seamlessly correlate events across different CDN providers' infrastructures. Each CDN's delivery characteristics appear in the dashboard, but the unified view is incomplete. You end up piecing together what happened from separate data silos, which defeats much of the value proposition during an actual incident. This isn't a new problem in the industry, but it's worth knowing before you rely on this as your single source of truth. Another significant limitation is the lack of deep protocol-level debugging. The analytics tell you that something went wrong — a stream stalled, quality dropped, connection failed — but they don't give you packet-level diagnostics or low-level transport analysis. When we had a recurring issue with HLS variant playlist cache poisoning on a specific ISP, the Streamesst dashboard confirmed the symptom but couldn't help us diagnose the root cause. We ended up using a combination of tcpdump captures and FFprobe analysis alongside the platform to figure out what was happening. The platform should be one tool in your observability stack, not the only tool. There's also the question of data privacy and compliance. The client-side SDK collects device identifiers, network information, and usage patterns by default. Depending on your deployment region and audience, this may require GDPR or CCPA compliance measures, consent flows, and data processing agreements. We had to implement consent-based telemetry collection for European audiences, which added development time and required coordinating with our legal team. The platform does support data anonymization and region-based data residency options, but these are configuration choices you need to make during setup, not something that happens automatically.
Practical Recommendations Based on Real Deployment
If you're evaluating this for your organization, start with a proof of concept on a single stream type and CDN before committing to a full deployment. We attempted to instrument everything at once and nearly abandoned the project because the configuration complexity was overwhelming. A phased approach — getting HLS on one CDN working end-to-end first, then expanding — is significantly more manageable. Budget about two to three weeks for initial deployment if your stack is relatively standard, and twice that if you have custom players or non-standard CDN configurations. The alerting configuration deserves more attention than it typically gets. Default alert thresholds will generate too many false positives in a healthy system, causing alert fatigue within days. We found that setting initial thresholds at 2x industry-standard baselines and then gradually tightening them over a two-week observation period produced the most actionable results. The platform's machine learning features can help identify normal baselines for your specific traffic patterns, but they require at least a week of clean data before they produce reliable results. For teams looking at alternatives, Cloudflare Stream Analytics and AWS CloudFront Live Metrics both offer comparable functionality with different trade-offs. Cloudflare's solution is tighter if you're already on their CDN, while AWS's integrates naturally into the broader CloudWatch ecosystem. The Streamesst platform's advantage is protocol-agnostic support and more granular client-side telemetry, but the cross-CDN limitation is a real constraint that may not matter if you're single-CDN. If you're multi-CDN by design or requirement, I'd recommend evaluating those alternatives more carefully before committing.
The final thing worth noting is that after we got this running, our mean time to detection for streaming incidents dropped from roughly 45 minutes to under 4 minutes. That's not a small improvement. Most of that gain came from the realtime aspect — catching issues while they were still contained rather than discovering them after hours of customer complaints. The platform isn't perfect, and the setup requires actual effort, but for any operation running significant streaming traffic, it's genuinely in the category of tools you didn't know you needed until you don't have it anymore.