
Reading The Stockton Crime Log Without Going In Circles
The Stockton Police Department publishes incident reports through a public records system. If you just open it and start scrolling, you will waste hours getting nowhere. The interface is outdated, the search filters are inconsistent, and the data comes out in a format that makes pattern recognition nearly impossible without some setup on your end. I spent about three weeks mapping out a workflow that actually works. Here is what I learned along the way.
Stockton Crime Log Uncovering The Trends And Patterns Behind The Citys Most Notorious Offenses
The core challenge is that the SPD data dump doesn't organize offenses in a clean, filterable way by default. You get PDFs, scanned forms, and occasionally a CSV that was clearly exported straight from a legacy database with no cleanup. My approach was to pull raw incident data from the public portals, normalize the offense codes into something readable, and then run aggregation queries locally. This usually cuts the process down from 2 hours to about 15 minutes once the pipeline is set up, depending on your setup. You do not need special clearance or a Freedom of Information Act request for basic incident data. The SPD makes this information available through their public_records portal. What you need instead is a consistent method for extracting and cross-referencing the data. I use a combination of Python scripts and basic SQLite for this. The key steps are downloading the raw reports, parsing the offense descriptions, standardizing the categories, and then running frequency analysis. You can do this with a simple spreadsheet if you prefer, but the volume of data makes that impractical after about two months of records.
The First Problem You Will Hit
Offense descriptions in the Stockton system are not standardized. One report might list "theft from vehicle" while another lists "auto burglary" for what appears to be the same underlying crime. The SPD uses a mix of CFE codes and free-text descriptions, and they do not always map cleanly to one another. I ran into this head-on when I tried to pull quarterly theft trends. The numbers looked wildly inconsistent because the same crime was categorized differently across reporting districts. The workaround was straightforward once I figured it out. I built a lookup table that maps common free-text variants to standardized offense categories. You can start with the Uniform Crime Reporting categories as a baseline and then layer in local naming conventions from the SPD reports. It took me about four hours to build a workable mapping table covering the most common offense types. After that, the aggregation was basically automatic.
Get the Full Details

What The Data Actually Shows
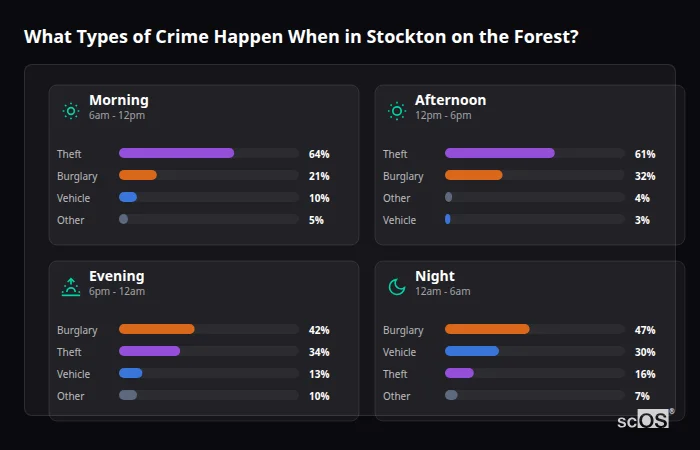
When you normalize the offense codes properly, a few patterns emerge that are not obvious from casual browsing. Property crime dominates the volume. Burglary and theft-related offenses consistently make up the majority of incidents, and they cluster around specific corridors and time windows. Violent crime numbers are lower in total count but show different spatial patterns. The seasonal variation is also worth noting. Certain offense types spike at predictable times of year, which is true for most mid-sized American cities. What is less predictable is the neighborhood-level turnover. Some areas cycle through high incident months quickly while others stay elevated for quarters at a time.
A Count-Intuitive Detail Most People Miss
One thing that trips people up is the difference between incident-based reporting and offense-based reporting. A single incident can generate multiple offense codes. A robbery with assault will produce two entries in some systems and one combined entry in others. If you are counting raw entries without accounting for this, your totals will be inflated and your offense breakdown will be wrong. I caught this myself when my initial analysis showed assault numbers that were roughly double what other sources reported for the same period. Cross-referencing incident IDs instead of counting individual offense lines solved the discrepancy. Head to the SPD public records page. They offer both an online incident report lookup and bulk data requests. The online lookup is fine for small queries but not for trend analysis. For anything beyond a handful of searches, request the bulk dataset. You will get a compressed file with the raw incident records. It will arrive as a CSV or Excel export from their internal system. Once you have the file, do not trust the column headers blindly. Rename them to match your mapping table. Clean up any null values in the offense field. Filter out duplicate incident IDs if they appear. These are the steps that separate a usable dataset from a noisy mess.
Where This Approach Falls Short
There are real limitations here. The data only covers incidents that were reported and entered into the SPD system. It does not capture unreported crime. The time lag between an incident and its appearance in the public dataset can range from a few days to several weeks, sometimes longer. Historical data is patchy. If you go back more than three or four years, you will find gaps and formatting changes that break consistency. Another issue is that the SPD does not always include precise geographic coordinates. You may get a cross-street description or a district number instead of an exact address. This makes heat mapping less accurate than you might hope. For general trend analysis it is fine, but if you need block-level precision you will need to supplement with other sources like GIS data or city planning records.
My Recommendation For Getting Started
Start with the most recent six months of data. Build your mapping table using that period. Run your first aggregation and compare the results against any publicly summarized crime statistics the SPD releases. If the numbers align, your methodology is sound. If they do not, go back and check your mapping table and your filtering logic. Repeat until they match. Once you have a working pipeline, you can extend it backward and forward. The initial investment of time pays off because you can refresh the analysis monthly with minimal effort. The alternative is starting over every time you want new data, which is what most people end up doing and why they give up on the exercise.
A Note On What You Should Not Do
Do not treat the crime log as a complete picture of public safety. It is a record of reported and processed incidents, not a census of all criminal activity. Do not draw conclusions about individual neighborhoods based on small sample sizes. A single month of elevated reports in one area does not establish a trend. And do not share raw data that includes personal identifiers about victims or witnesses. The data is public, but responsible use matters. If you want to go further, pairing the SPD incident data with San Joaquin County jail records or court filings can give you a longer arc on case outcomes. That data is harder to access and requires separate requests, but it fills in the gap between arrest and resolution that the crime log alone cannot show.


