Why The Cincinnati Doppler Site Matters More Than You Think
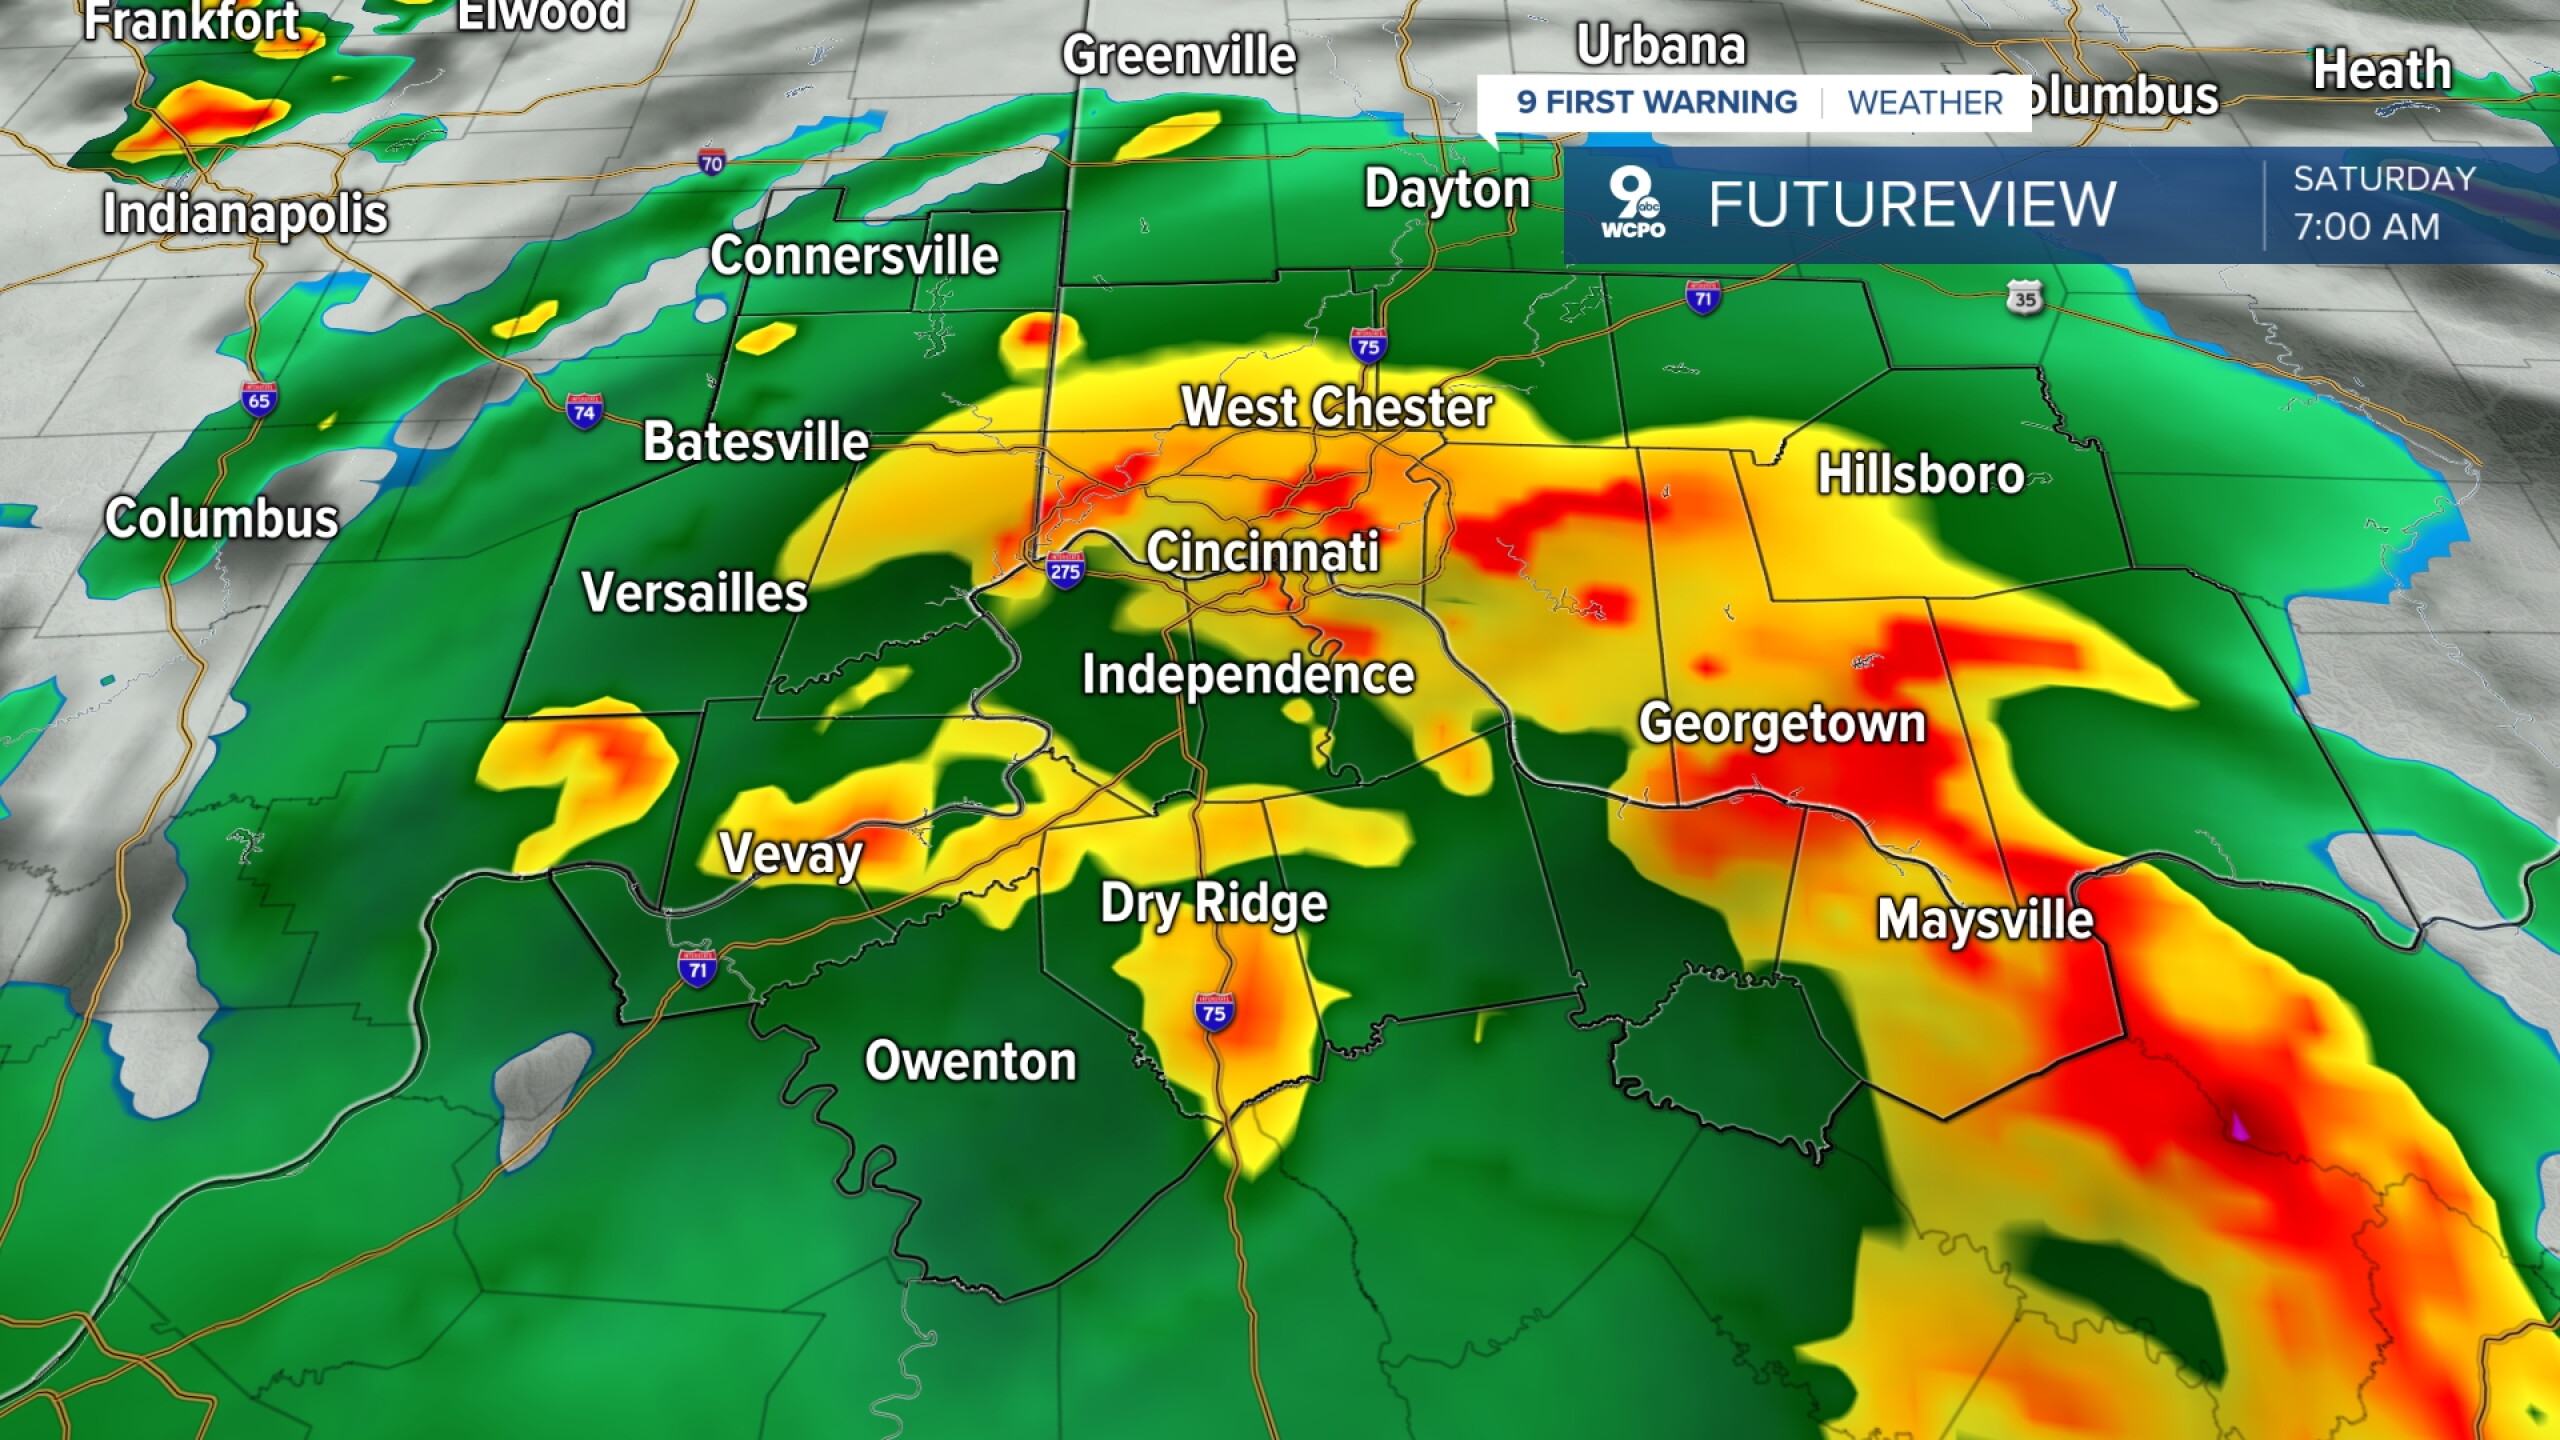
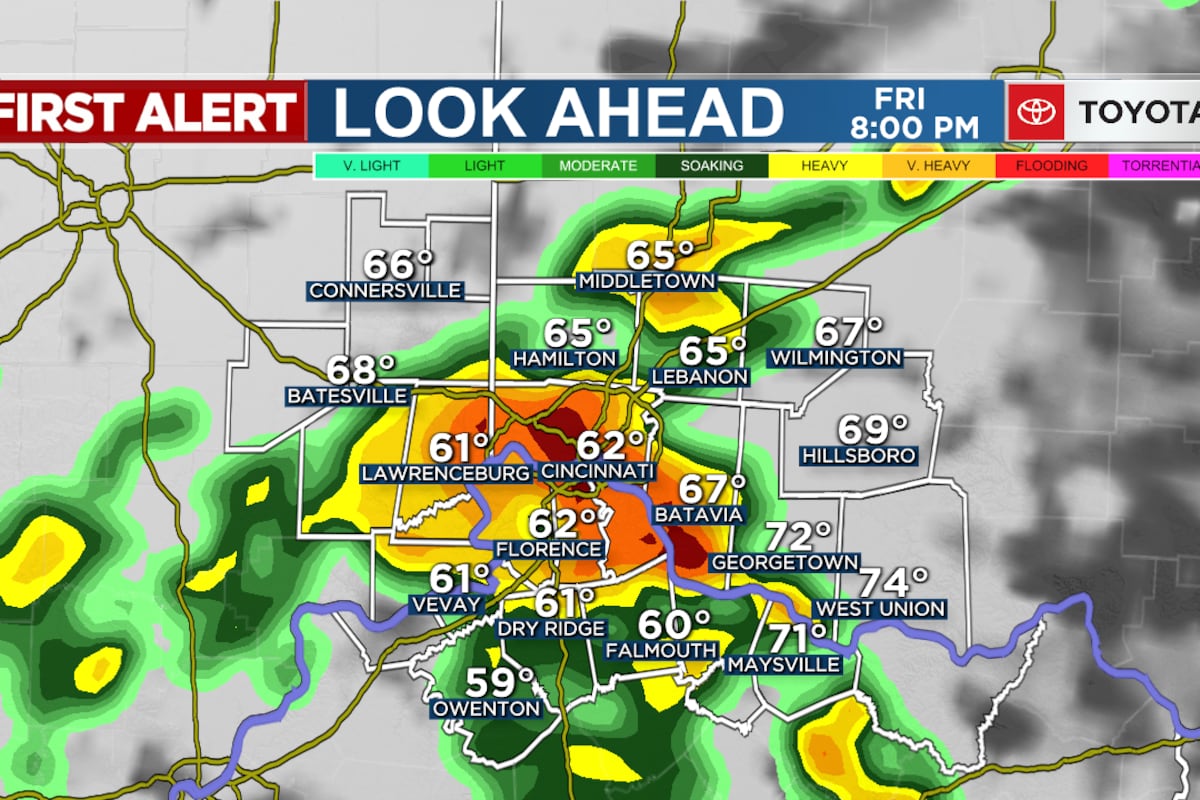
The NEXRAD site at KILN sits near Hamilton, Ohio, and it is one of the most heavily relied upon radar facilities in the entire continental United States. If you work in meteorology, emergency management, aviation, or even insurance risk modeling, you already know that. But knowing it exists and actually understanding how to pull useful data from it are two different things. Most people just look at the animated radar loops on their phone and call it a day. That will get you through a casual Sunday hike. It will not get you through a real decision-making window when a squall line is moving fast through the Ohio Valley. I spent years working with operational radar data during severe weather seasons, and the Cincinnati site comes up constantly because of what it covers. You have the tri-state area right there — southern Ohio, northern Kentucky, southwestern Indiana — all sitting in a corridor where storms can develop quickly and move unpredictably. The geography itself complicates things. The Ohio River valley creates microclimate effects, and the terrain around the Blue Ridge escarpment causes beam blockage at low elevations. These are not theoretical issues. They show up in the data every time.
Staying One Step Ahead Of The Storm The Power Of Cincinnati Doppler Weather Radar
Accessing raw data is easier than it used to be, but the quality of your output depends entirely on what you do after you pull it. The National WindStorm Insurance Exchange hosts a mirror of NEXRAD data, and the National Data Center in Omaha feeds everything through SPC's servers. The standard product format is Level II, which gives you volumetric scans with base reflectivity, velocity, and spectrum width at multiple elevation angles. You can download these directly from the NOAA archive if you know the file naming convention, or you can use APIs that wrap the raw data into something more manageable. One practical workflow I have used repeatedly involves pulling the last six hours of reflectivity and velocity data from KILN, running it through a script that flags areas where velocity data shows significant spectral broadening — that is usually where you have turbulence or debris, depending on the weather mode. From there, a simple correlation check against storm reports from SPC's mesoanalysis database tells you whether the echoes are producing anything real. This usually takes about twenty minutes from start to finish if your data pipeline is set up properly. A manual check using individual volume scans can easily eat up an hour and a half with worse results.
How The Radar Actually Works In Practice
The WSR-88D at KILN operates in the C-band equivalent, which means a wavelength of about ten centimeters. That is a sweet spot for precipitation detection without the excessive attenuation you get at higher frequencies. The site runs a fixed set of elevation tilts during clear air mode and switches to a more aggressive scan pattern once severe weather is in the forecast. The default operation uses nine to fourteen elevations depending on the mode, and each full volume scan takes roughly four to six minutes. That is fast enough to track storm development, but not so fast that you can catch everything happening below the lowest tilt. The lowest elevation angle is typically 0.5 degrees, and at that angle the radar beam is already about a kilometer above the ground at a distance of sixty kilometers from the site. By the time you reach two hundred kilometers out, the beam is roughly three kilometers up. That leaves a gap in coverage that matters a lot when you are trying to detect low-level rotation or a gust front near the surface. I learned this the hard way during a case in spring 2014 when a bow echo segment was producing damaging winds near the Kentucky border. The velocity couplet was visible on the second and third tilts, but the lowest tilt showed nothing because the beam had overshot the shallow feature. We missed it by maybe five minutes until the next volume scan came around. Since then, I always cross-reference the lower tilts with nearby surface observations and lightning data before making any calls based solely on the radar.
Get the Full Details
Common Pitfalls People Miss
The biggest mistake I see is treating raw reflectivity as if it is rain rate without any adjustment. The Z-R relationship varies significantly depending on drop size distribution, and a stratiform drizzle event and a convective downburst can produce identical reflectivity values while having completely different impacts on the ground. A second common error is ignoring range ambiguity. At longer distances from KILN, specifically past the first Nyquist velocity fold point, velocity data becomes unreliable without unfolding. The unfold algorithms are decent but not perfect, and they occasionally introduce artifacts that look like real features if you are not checking carefully. A third issue that catches people off guard is beam blockage. The terrain around Butler County is mostly flat, but there are localized rises and forested ridges that create partial shadow zones. The NWS Cincinnati has published blockage maps for the site, and those should be factored into any analysis where you are looking for weak echoes near the horizon in certain directions. During one of my assessments, I noticed a persistent low-reflectivity gap in the southeast sector that did not match the surrounding storm structure. It turned out to be a persistent blockage zone from a ridge about twenty kilometers away. If I had not checked the blockage data first, I would have misidentified it as a rain-free gap inside a larger system.
What The Data Can Not Tell You
No amount of Doppler processing will give you accurate rainfall estimates in a heavy hail core. The radar overestimates rainfall when large hail melts and produces high reflectivity without proportional liquid water content. It also underestimates in cold rain events where the drop size distribution skews toward smaller drops. If you need precipitation totals, you should combine radar-derived estimates with gauge data from the Cooperative Observer Network or the NWS radar mosaic products that blend multiple sites. The multi-radar mosaic from the National Centers for Environmental Information is usually sufficient for regional analysis, but it smooths out fine-scale detail that a single site can resolve if you are working close to the radar. Another hard limitation is the inability to detect non-meteorological targets with confidence. Birds, insects, and ground clutter all produce signals that look like weather on reflectivity. The velocity and spectrum width products help distinguish them, but only sometimes. During migration seasons in the fall, the KILN radar will show widespread weak echoes at low to mid-levels that have no relation to precipitation. I have seen junior forecasters flag these as stratiform rain bands before. A quick check against visibility reports and surface humidity data usually resolves the confusion, but it is worth keeping in mind.
Where To Get The Data
The primary source for raw NEXRAD Level II data is the NOAA National Centers for Environmental Information archive. You can request files by site identifier and time range, and the standard format is a binary record with product headers that describe each sweep. For most practical purposes, though, you will want a processed layer rather than raw files. Several platforms provide visualized NEXRAD data with overlay tools. The SPC map room offers free access to current and archived radar imagery. Some commercial meteorological services provide API access to de-aliased velocity and corrected reflectivity products if you need higher fidelity for modeling work. If you are doing this programmatically, there are open source libraries that can parse NEXRAD Level II data and extract the fields you need. The Python environment is the most common setup, and packages exist for reading the binary format, converting to netCDF, and computing derived products like storm-relative motion and helicity estimates. Processing a single volume scan through a typical pipeline takes somewhere between thirty seconds and two minutes on a standard workstation, depending on your configuration. That is fast enough for near-real-time applications if you batch the work correctly.

A Word On Timing And Latency
Operational data from KILN is available through the National Weather Service with a latency of roughly four to six minutes from the end of the volume scan. That is acceptable for most warning and decision support purposes. Historical data, however, can take longer to appear in some archives due to quality control procedures and file reformatting. If you need timely access for an operational system, you should plan around the known delay rather than assuming instantaneous availability. During severe weather days, the scan frequency may increase, which improves latency slightly but also increases the volume of data you need to handle. The Cincinnati site has been operating since the early 1990s, and the hardware has been upgraded several times since the original WSR-88D deployment. The current configuration includes digital signal processing improvements and better de-cloud filtering than the earlier versions. None of these upgrades eliminate the fundamental physics limitations, but they do reduce noise and improve the reliability of the lower-tilt data. If you are comparing older data to current data from the same site, be aware that product characteristics may shift slightly between upgrade cycles, and that can affect long-term trend analysis if you are not accounting for it.
Practical Steps For Getting Started
Start by defining what you actually need from the radar. A general awareness of storm position and intensity is a different request than extracting quantitative rainfall estimates or detecting rotational signatures for a warning decision. Once you have that, pick a data source that matches your requirements and build a simple pipeline that pulls the relevant products. Test it with historical cases from the region where you know what happened. Compare your radar interpretation against the actual storm reports and damage surveys. The gap between your analysis and reality is where you learn what the data can and cannot do in this specific coverage area. Keep a log of false alarms and misses. I found that tracking my own errors over a full season was the most effective way to improve my radar interpretation skills. The Cincinnati site covers a region with mixed terrain and frequent landfalling Gulf moisture, which means the same echo type can behave differently depending on atmospheric instability. No single rule applies across all cases, and learning to read the context around the radar returns is what separates reliable analysis from guessing. The technology gives you a lot of information, but it does not replace judgment. It just raises the baseline for what you can reasonably be expected to see.