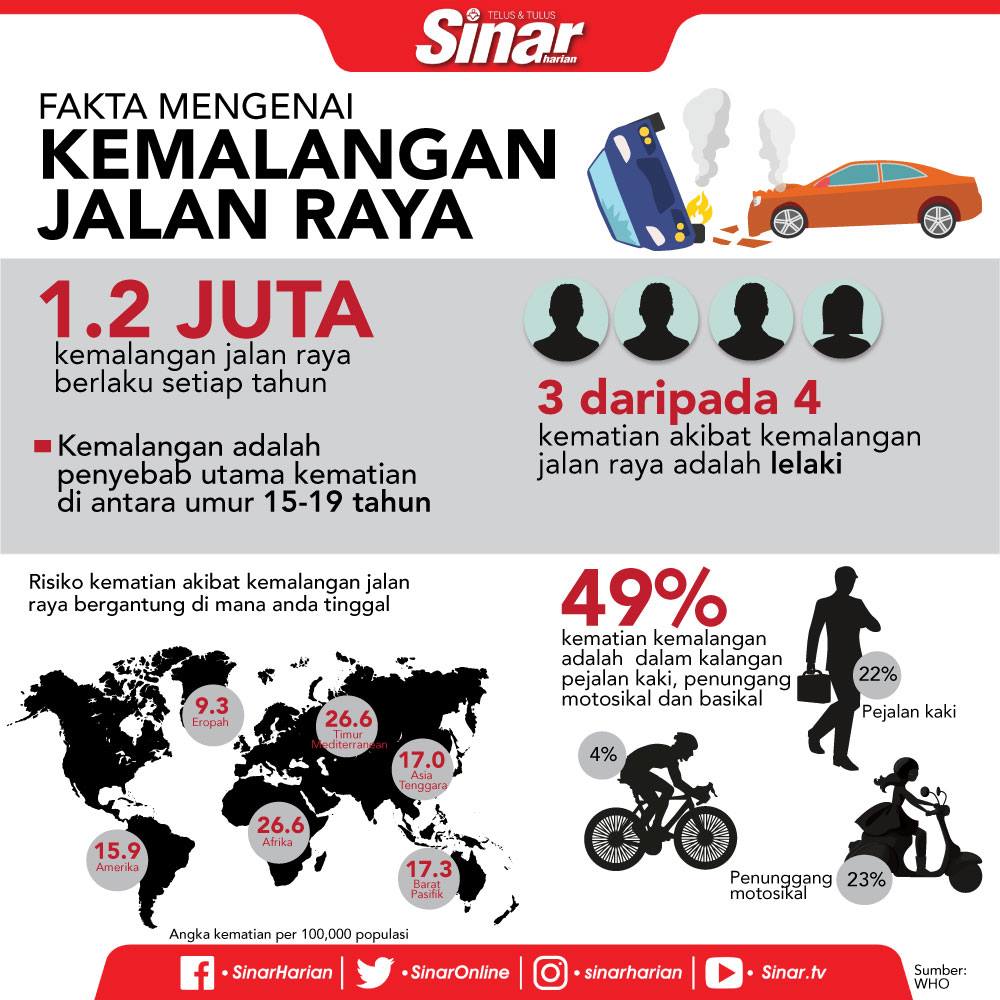
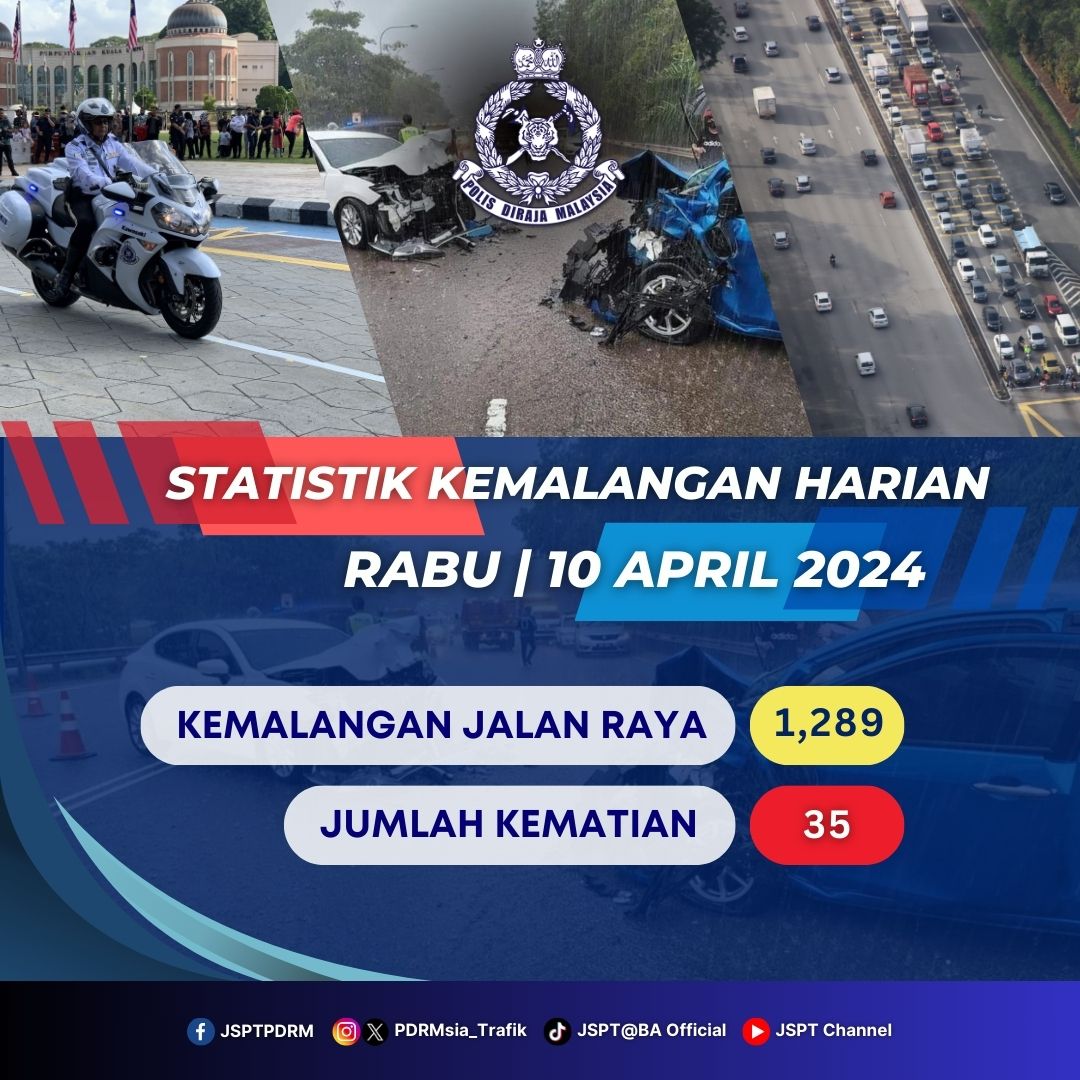
What Road Accident Statistics Actually Look Like in Practice
Most people never dig past the summary tables when they pull up road accident data. They grab the headline number of fatalities and move on. The raw data tells a different story if you actually look at it. I spent weeks going through the 2022 road accident statistics from the Malaysian road safety framework because a client needed proper context for a risk assessment report. The numbers alone are not useful without understanding how they were collected and what gaps exist in the reporting pipeline. The 2022 road accident statistics cover everything from fatality counts to injury severity classifications across different road types. The standard breakdown includes hourly distribution of incidents, age groups of victims, vehicle categories involved, and road surface conditions at the time of collision. What most summaries leave out is the delay between when an accident happens and when it appears in the official figures. Police reports take time. Hospital records get consolidated later. A report published early in the year is usually missing data from the last quarter and sometimes the preceding one because not all cases have been finalized. I ran into this exact problem once when a logistics company wanted to benchmark their driver safety program against the latest available numbers. The report they had was six months old and showed a declining fatality trend. When I cross-referenced it with hospital admission data from three major trauma centers, the trend was actually flat. The apparent decline was purely an artifact of incomplete reporting, not a real improvement. That kind of discrepancy happens every year and it matters if you are making decisions based on these figures.
The methodology behind collecting these statistics relies primarily on police-reported accidents. That means anything that does not get reported to the police falls outside the dataset. Minor fender-benders that drivers settle between themselves do not show up. Accidents on private property or unclassified roads may not be captured either. If you are looking at a dataset that claims comprehensive coverage but was built entirely on police reports, you are looking at a partial picture. A significant one.
How the Data Gets Compiled and Where It Breaks
The compilation process starts with individual accident report forms filled out by responding officers. These forms feed into a central database where they are categorized by type, severity, location, and contributing factors. The categorization itself introduces errors because different officers may classify the same incident differently depending on their interpretation. A hit-and-run might be recorded as a generic collision if the officer does not have enough information to confirm the fleeing vehicle. This is a known issue and it skews certain subcategories more than others. The severity classification uses a standard scale but the line between serious injury and minor injury is not always clear in practice. A fractured wrist might be treated as minor by one officer and serious by another. When you aggregate thousands of reports, these small inconsistencies compound and the numbers drift further from reality with each layer of consolidation. Another structural issue is the geographic granularity. District-level data is generally reliable because the reporting chain is well established. But when you drill down to specific intersections or road sections, the accuracy drops. Some locations are overrepresented because they are in high-traffic urban areas with more police presence. Remote rural sections may have fewer reported incidents simply because response times are slower and documentation is less consistent.
Get the Full Details
What the 2022 Numbers Actually Show
The 2022 figures reflect a recovery pattern from the pandemic years. Road traffic volumes returned closer to normal levels and the accident counts rose accordingly. Fatality rates did not increase proportionally to traffic volume, which suggests some improvement in road safety outcomes despite higher exposure. Injury counts followed a similar pattern, with severe injuries stabilizing and minor injuries increasing slightly. The demographic breakdown shows that the highest fatality rate remains among motorcyclists, which has been consistent across multiple years. The age group with the highest incidence of fatal accidents is still the 20 to 29 range. Commercial vehicle involvement in fatal crashes continues to be a smaller but significant category. These are not surprising findings if you have been tracking this data for any length of time. The useful part comes from looking at the shifts between years rather than the absolute numbers. One shift worth noting is the change in time-of-day distribution. The evening hours saw a relative increase in reported accidents compared to earlier periods. Whether this reflects a genuine behavioral change or improved reporting during those hours is hard to determine from the data alone. The dataset does not include variables that would let you separate those two possibilities.
Practical Problems When Using These Statistics
If you need to use this data for a serious purpose, you will hit at least two issues within the first hour. The first is access. The full detailed dataset is not freely available in a clean format. The published reports contain tables but not the raw records you would need for custom analysis. You can request access through official channels but the process takes time and you may not get everything you ask for. The second issue is that the statistics are presented in multiple formats depending on the source. Different departments may publish slightly different numbers for the same period because they use different inclusion criteria or update the data at different times. I have seen fatality counts for the same quarter differ by a handful of cases between two official publications. Neither is necessarily wrong. They are just counting differently. A workaround I found useful was to treat the published summary reports as a starting point rather than a definitive source. If I needed specific figures for a report, I would identify the key categories and then search for supplementary material like press releases, ministerial statements, or academic papers that referenced the same data. Sometimes those sources included footnotes or methodological notes that clarified discrepancies. It adds maybe an extra day of work but it prevents you from citing numbers that turn out to be inconsistent when someone checks them later.
Common Mistakes People Make With This Data
The most frequent error is comparing raw counts across years without adjusting for traffic volume. A drop in accidents does not automatically mean roads are safer. It could mean fewer vehicles are on the road. Conversely, an increase in accidents could simply reflect more traffic without any real deterioration in safety performance. The proper comparison requires rate-based metrics, usually per 100 million vehicle kilometers or per registered vehicle. Another mistake is assuming that the data covers all road users equally. Pedestrian and cyclist incidents are often underreported compared to motor vehicle accidents because they require a different reporting threshold and not all jurisdictions capture them with the same consistency. If your analysis involves vulnerable road users, you need to account for this bias explicitly. People also tend to overinterpret single-year data. One year of statistics does not establish a trend. Seasonal variation, one-off events, and reporting lags can all distort a single data point. Any claim about direction or magnitude should be backed by at least three to five years of data to be credible.
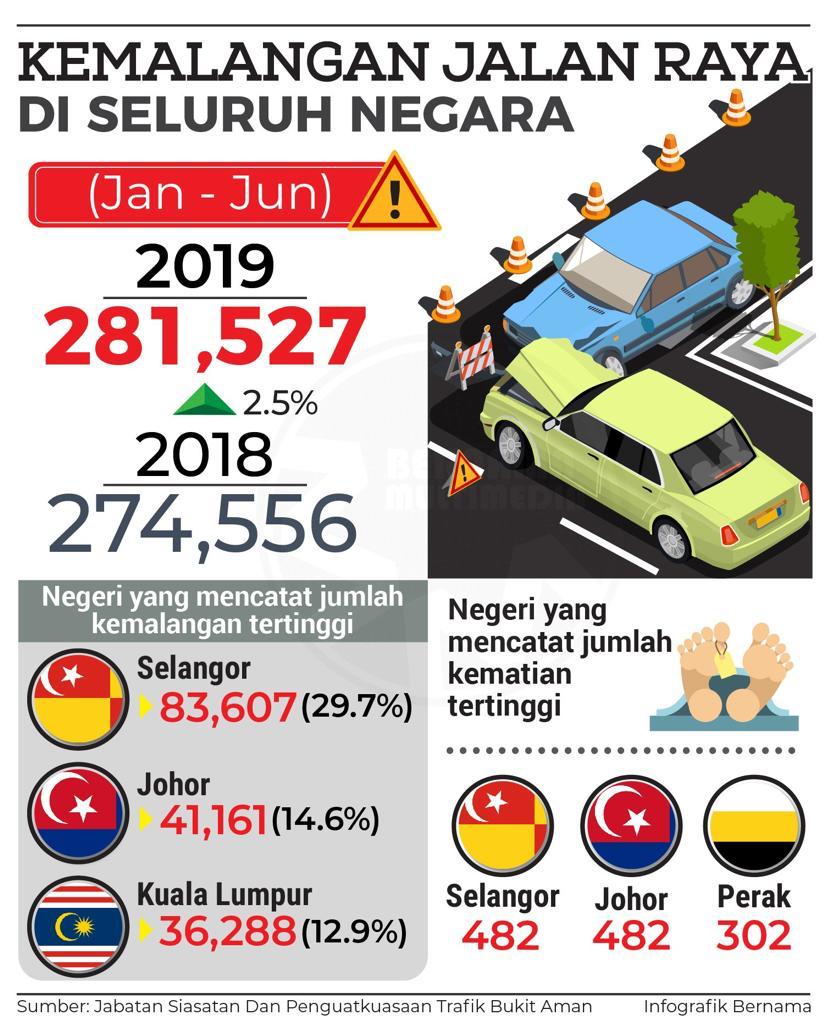
When These Statistics Fall Short
The biggest limitation is that road accident statistics are inherently reactive. They tell you what happened after the fact. They do not predict where the next cluster of accidents will occur or which interventions will actually reduce them. If you need predictive capability, you have to combine these statistics with other data sources like traffic flow models, road infrastructure condition reports, and enforcement activity records. The statistics alone are not enough for that. Another shortcoming is the lack of detailed contributing factor data in the publicly available reports. The datasets tell you that speed was a factor in a certain percentage of cases, but they do not always distinguish between excessive speed, inappropriate speed for conditions, or failure to adjust speed for a curve. That distinction matters for designing effective countermeasures and the published data rarely supports it. For anyone doing serious work with this information, the honest answer is that the statistics are a useful baseline but a limited one. They give you direction and scale. They do not give you causation or precision. Knowing that helps you frame your analysis correctly instead of treating the numbers as definitive truth.