How We Actually Count Stars in the Milky Way
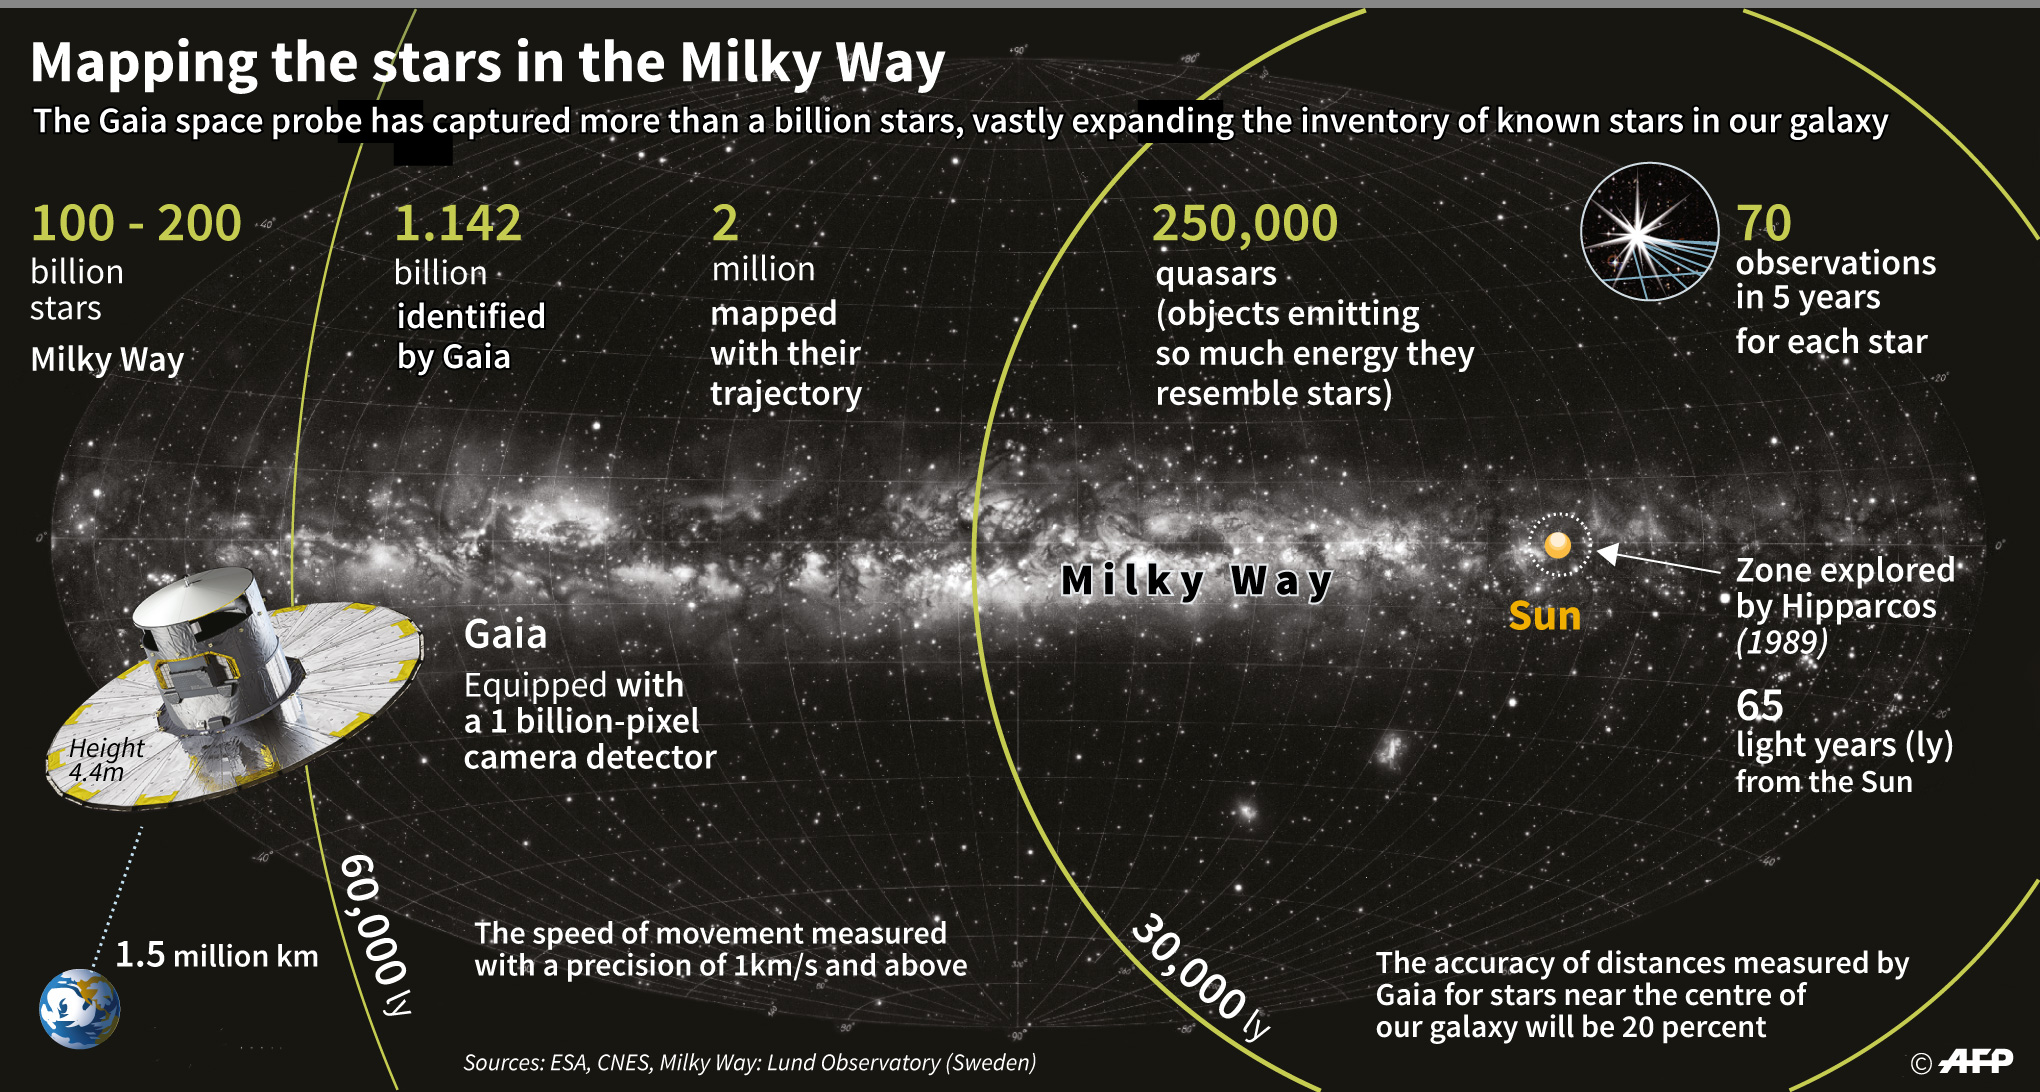
You can't count every star in the Milky Way. Nobody can. The number everyone throws around — 100 to 400 billion — is a guess based on modeling, not a headcount. I've spent years working with stellar population data, and the first thing you learn is that any specific number you see is really an estimate wrapped in assumptions about the parts of the galaxy we simply cannot observe. The standard approach starts with volume-limited samples. Pick a region of sky, draw a sphere around the Sun out to some distance — say 100 parsecs — and catalog everything down to a certain brightness limit. The Red Dwarfs and Brown Dwarfs survey did this kind of thing systematically. You count what's there, derive a density, then multiply by the estimated volume of the Milky Way's disk and halo. That multiplication step is where the uncertainty balloons. Here's the practical part that trips people up. Parallax measurements from Gaia give us distances for over a billion sources, but the catalog is heavily biased toward brighter stars within roughly 10,000 parsecs of us. Beyond that, even Gaia's best measurements lose precision fast. The thin disk extends maybe 15,000 parsecs from the center, the bulge adds more, and the halo stretches way out. We're essentially extrapolating from a noisy local sample into regions we can barely resolve.
Spectroscopic parallax and isochrone fitting are the workhorses for stars too distant for reliable trigonometric parallax. You measure a star's spectrum, classify it, infer its absolute magnitude from the spectral type, compare that to the apparent magnitude, and derive a distance. It works, but interstellar extinction messes it up badly near the galactic plane. Dust absorption varies wildly from line of sight to line of sight. I spent weeks once trying to reconcile distance estimates for a cluster in Sagittarius because the extinction map we were using didn't match the actual conditions along that particular path. The workaround was cross-referencing three separate extinction catalogs and using color excess from multiple passbands to build a custom correction. It added maybe two days of work but saved the whole analysis from being off by a factor of two. Photometric surveys like SDSS, 2MASS, and now Gaia DR3 provide the raw data. The trick is knowing which corrections to apply. Photometric calibration drifts across detectors and over time. Proper motions get mixed with instrumental artifacts if you're not careful. Variable stars contaminate your counts unless you flag and remove or separate them. A beginner will just pull magnitudes from a catalog and start counting. An experienced person knows to check the variability flags, apply proper extinction corrections for the specific field, and understand the selection function before trusting any density estimate. One counter-intuitive thing about stellar population studies: the majority of stars by far are M-type dwarfs, and they dominate the mass budget in a way most people don't expect. But they're also incredibly faint. The Gaia catalog, for all its scale, is still incomplete for the lowest mass stars beyond a few hundred parsecs. That means your count of "visible" stars is skewed heavily toward O, B, A, and F types — the ones that are rare but bright. When you correct for the IMF, the number jumps dramatically, and that's where the 100 to 400 billion range comes from. Without that correction, you'd dramatically underestimate the total.
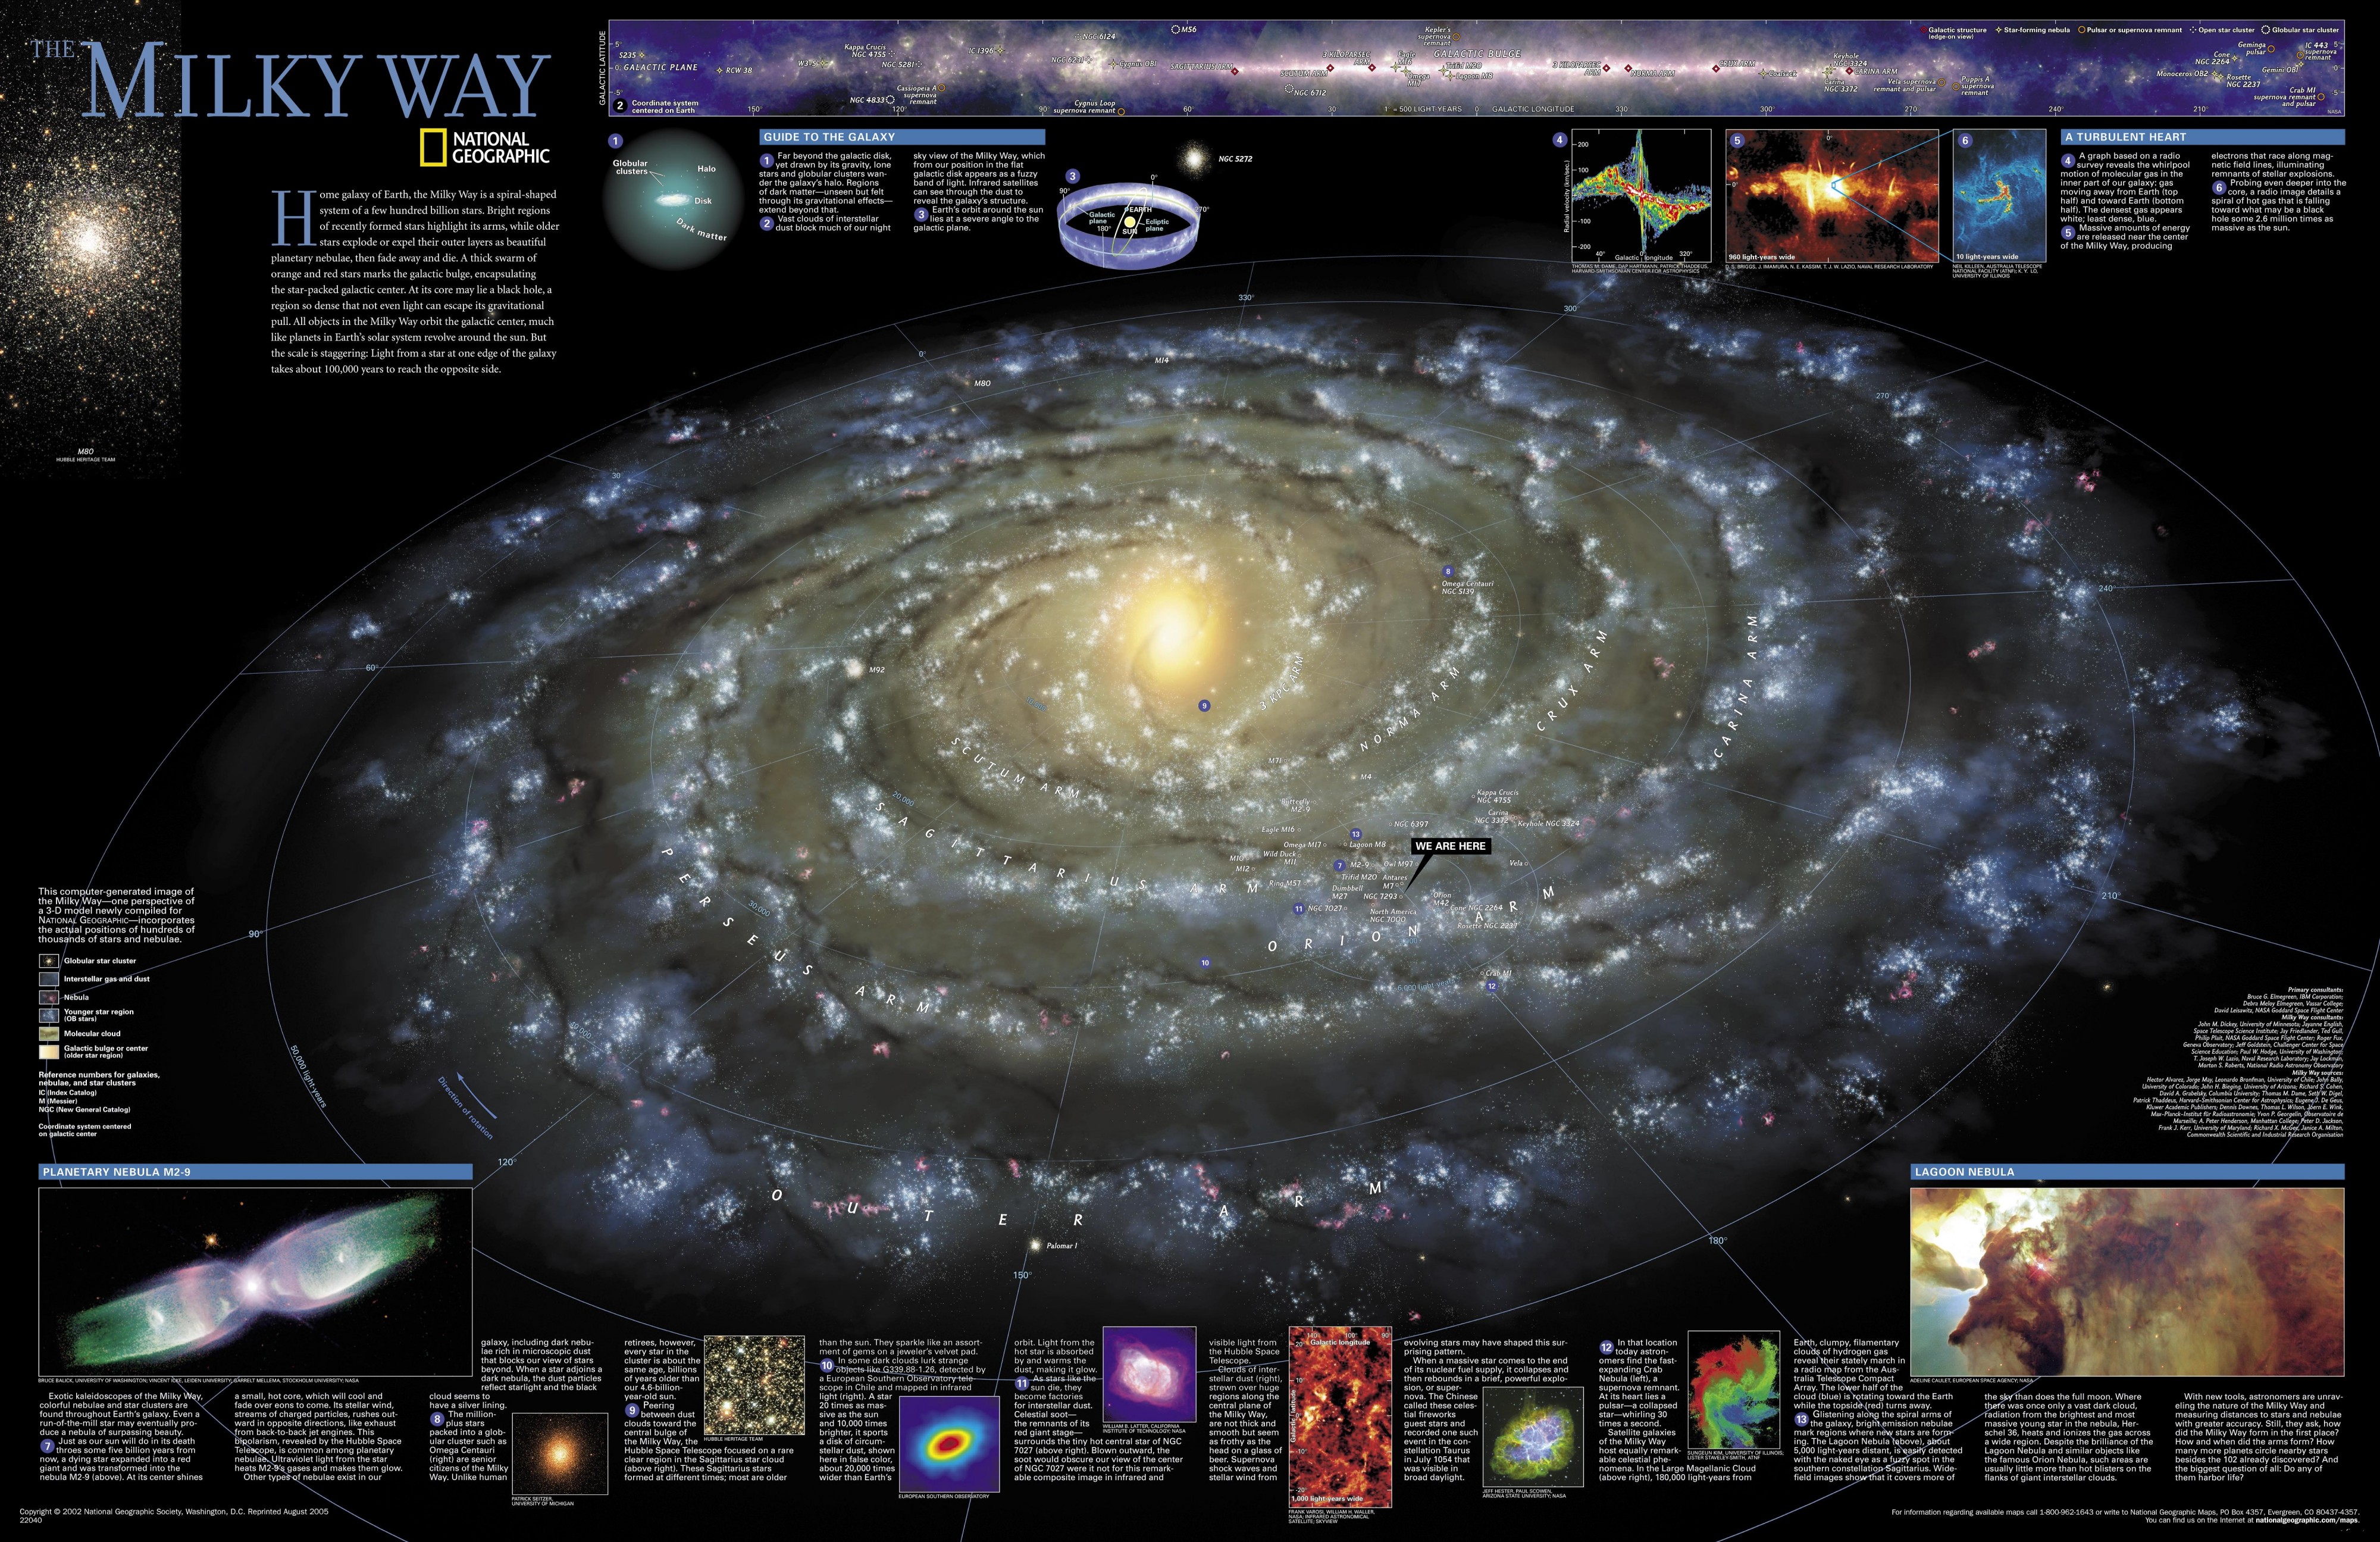
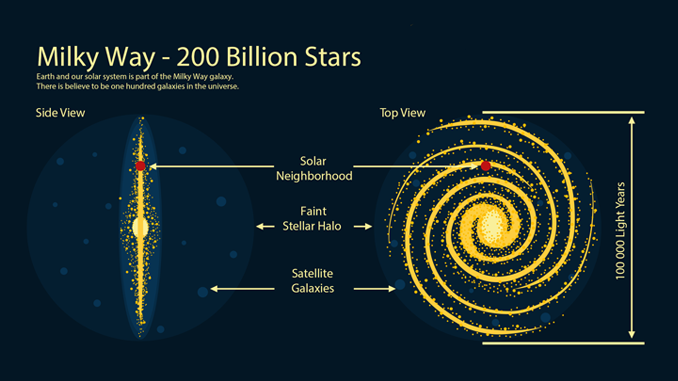
Another pitfall is the assumption that the solar neighborhood is representative. It's not. The spiral arms, the bar, the central bulge — all of these have different stellar densities, different metallicities, different age distributions. A density measured near the Sun doesn't cleanly scale to the inner galaxy. I've seen papers that did exactly that and got numbers that were nowhere close to what subsequent modeling showed. The fix is to weight your local measurements against galactocentric distance and use structural models of the disk, bulge, and halo separately. If you want to get your hands on actual data, Gaia's archive at gaia.esac.esa.int is the primary source. You can query by position, magnitude, parallax, spectral type — all of it. The ESO archive also has useful spectroscopic data. For extinction maps, the Schlegel, Finkbeiner, and Davis reconstruction updated by Schlafly and Finkbeiner is widely used, though newer all-sky maps from Planck and 2MASS are improving on it. The Besançon model of the Galaxy is another tool you'll see referenced — it's a synthetic stellar population model that predicts what we should see given different assumptions about structure and evolution. It's useful for sanity-checking your own estimates. The bottom line is that charting our galaxy's stellar population is an exercise in managing uncertainty, not eliminating it. The techniques are solid. The data keeps getting better every year. But the fundamental problem remains: we're embedded in the system we're trying to count, looking through dust, with instruments that have limits. The 100 to 400 billion figure isn't a measurement. It's a range that acknowledges what we know and what we don't. Anybody who tells you otherwise is either selling something or hasn't looked closely enough at the error bars.
Get the Full Details