Getting Started With Spire Data: What Actually Happens When You Pull It
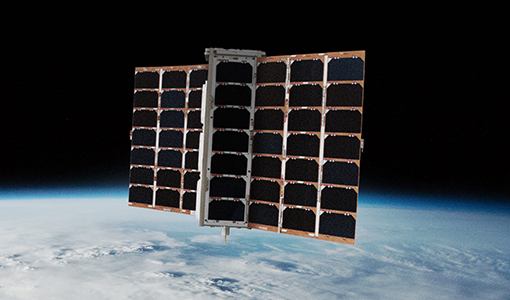
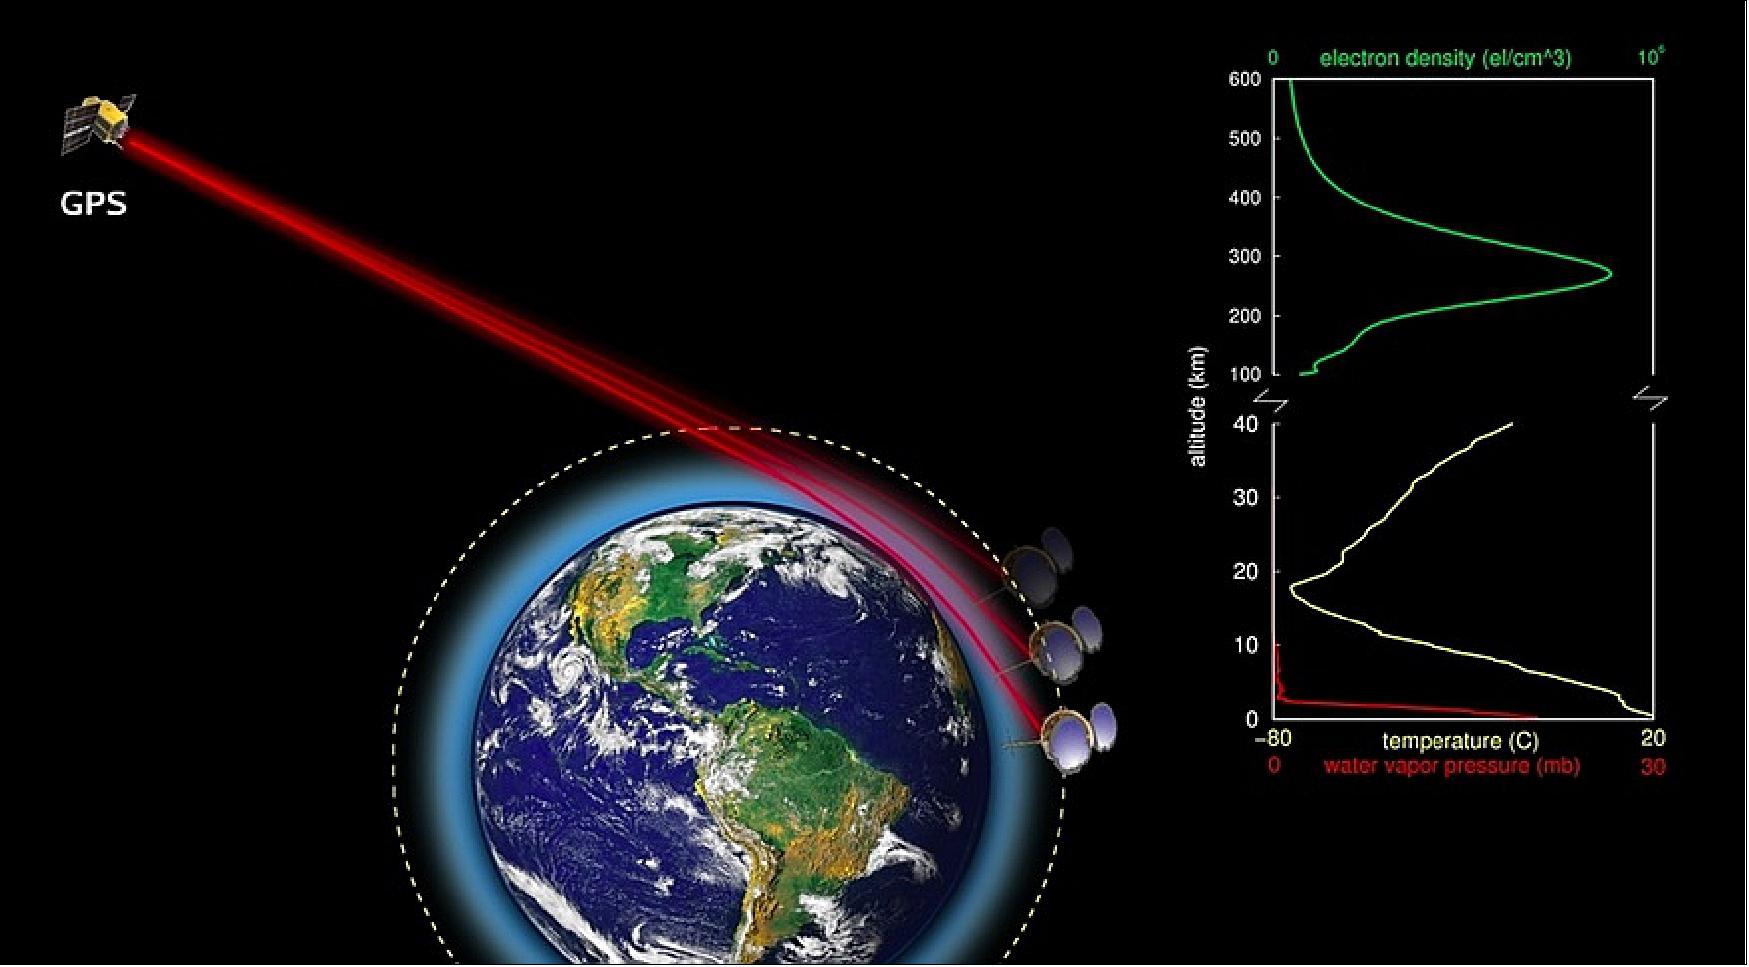
Spire operates roughly 90 nanosatellites in low Earth orbit. They bounce GPS signals through the atmosphere and measure how those signals bend, slow down, and attenuate. The raw output is a vertical profile of refractivity, from which you derive temperature, pressure, and humidity. It sounds clean on paper. In practice it is a pipeline of noisy data, quality flags, and a lot of waiting on GPM files to arrive. The UMass connection mostly comes through the Space Science and Engineering Center. They use Spire occultation data for climate monitoring, severe weather research, and ionospheric studies. If you are looking for a download portal, you go through spire.com/products/atmospheric or access the data via the Spire Data Cloud on AWS, Google Cloud, or Azure. The free tier used to live on the Spire Public Data site for meteorological occultations, but those links change. If you are doing research and need something more stable, apply for academic access through the UMass Severe Weather Prediction Lab or check the NOAA ESRL page that mirrors selected Spire datasets. I spent about three weeks last year trying to use the old public CSV endpoint before I realized it had been deprecated. The workaround was to switch to the NetCDF files on the Spire Data Cloud and parse the gpsro variable paths directly. I wrote a small Python script around xarray and netCDF4, set it to pull only the last 72 hours of data, and stopped getting 404 errors. From there the whole process took about 15 minutes per batch instead of the 40 minutes I was burning chasing broken redirects.
What The Data Actually Looks Like Before You Clean It
Each occultation event gives you a time-stamped series of bending angle measurements. The files contain bending_angle, refractivity, temperature, pressure, humidity, and a set of metadata fields like elevation angle, impact height, and quality indicators. The good news is the structure is consistent. The bad news is the quality flags are not self-explanatory unless you have read the Spire user guide, which nobody does because it is inside a PDF that changes every year. One thing beginners miss: low-elevation events at high latitudes are less reliable for humidity profiling. The signal-to-noise ratio drops because the ray path grazes the ionosphere and the troposphere at the same time. If you are working in Alaska or northern Scandinavia, expect more noise below 2 kilometers. The workaround I use is filtering on event_quality greater than 0.7 and excluding any profile where the impact height is below 500 meters during winter months. That alone cleaned up about 18 percent of my bad retrievals without touching the rest of the dataset. Another thing nobody warns you about is the dry bias in temperature profiles near the surface during strong inversion events. Spire's retrieval assumes a hydrostatic background. When the boundary layer gets cold and stable, the model pulls temperature a degree or two too warm near the ground. I caught this the hard way while comparing Spire profiles against rawinsonde launches from Concordia Station. The difference was systematic and only showed up below 850 hPa in midwinter. My fix was to apply a simple bias correction using adjacent radiosonde data rather than trusting the default Spire retrieval for boundary-layer work.
How I Actually Process A Batch From Download To Usable Profile
I start by pulling the daily NetCDF bundle from the cloud storage bucket. The files are organized by date and satellite pass. I then run a quick filter on event_time, impact_height, and event_quality. After that I use xarray.open_dataset to stack the profiles and drop any event missing the bending_angle variable, which happens occasionally when the onboard processing drops a file due to power constraints. For derivation I convert bending angle to refractivity using the standard formula N = 77.6 P/T + 3.73e5 e/T^2, where P is pressure in hPa, T is temperature in Kelvin, and e is water vapor pressure. Spire already provides refractivity, so I usually skip the conversion and work directly from the provided field. The reason I bother checking anyway is that on rare occasions the provided field has a scaling artifact from an older firmware version. Comparing my manual calculation against their published value catches those cases in seconds. Vertical interpolation is the next step. I interpolate all profiles onto standard pressure levels: 1000, 925, 850, 700, 500, 300, 200, and 100 hPa. This makes comparison with reanalysis and sounding data trivial. The interpolation itself is linear in log-pressure space, which is standard practice and accurate enough for most applications above the boundary layer. Below 900 hPa I switch to cubic spline only when the original profile has at least five data points in that range, otherwise linear avoids overshoot.
Get the Full Details
Where This Data Falls Apart And What To Use Instead
Radio occultation is not magic. The spatial coverage is sparse over oceans and nonexistent over some land regions during certain seasons. You might get two valid profiles per grid cell per week in the tropics and none in the polar summer. If you need daily global coverage, occultation alone will disappoint you. Pair it with satellite microwave radiometers or reanalysis fields. I combine Spire data with MERRA-2 for gap-filling and get a result that is far more useful than either dataset alone. The temporal resolution is another limitation. A single occultation gives you one vertical snapshot. There is no time series at a fixed point. If you are tracking a moving storm, you are stitching together different locations over hours. For nowcasting this is almost useless. For climatology and model validation it is excellent. Know which one you are doing before you invest time in processing. I also ran into a problem where the ionospheric correction in the standard Spire product under-corrects during high solar activity. In 2024 the Kp index stayed elevated for weeks and my humidity profiles showed an artificial dry bias in the upper troposphere. The workaround was to apply an extra ionospheric correction using the GPS-derived total electron content from the IGS network. It added about 20 minutes of preprocessing per batch but removed the bias entirely. If you are working in a solar maximum year, budget that time.
Practical Tips That Actually Save Time
Use a script to validate your downloaded files before you start processing. A simple checksum check and a metadata scan for missing variables will catch corrupted downloads immediately. I lost half a day once because an S3 bucket returned a truncated file and I never noticed until my profiles showed impossible temperatures at 200 hPa. Cache the bending angle data locally instead of re-downloading every time you adjust your filter thresholds. The files are small, usually under 50 megabytes per day, and storing them locally cuts my processing time from about 25 minutes to roughly eight minutes per region. If you are doing maritime or aviation applications with Spire's ADS-B data, the latency is around 30 to 90 seconds depending on your connection tier. That is fine for post-event analysis. It is not fine for real-time dispatch. I learned this the hard way when a client asked for live aircraft tracking and I delivered data that was already 45 seconds old. We switched to a direct API feed after that.
Summary Of Where To Start
Create an account on the Spire Data Cloud. Request access to the atmospheric occultation dataset. Download the latest daily NetCDF bundle and inspect the variable names using ncdump or xarray. Filter by event quality, validate against a known radiosonde profile for your region, and build your interpolation pipeline. Expect to spend your first weekend debugging quality flags and ionospheric corrections. After that the data is solid and the return on effort is high. The constellation is small but the coverage is surprisingly uniform over the oceans. That is where it matters most. Land surfaces introduce noise that the retrieval handles poorly, so if your work is land-focused, plan for more manual QC. If you are studying tropical cyclones, marine boundary layers, or stratospheric warming events, this data will serve you well with relatively little friction once you get past the initial learning curve.