
Why Your Switches Need STP and What Happens When It Breaks
I spent three years troubleshooting a campus network where Layer 2 loops were occurring on what I thought was a fully managed, redundant design. The issue came down to misconfigured BPDU guard on edge ports. The entire building lost connectivity for forty-five minutes before I isolated the problem. This is exactly why Spanning Tree Protocol The Silent Guardian Preventing Network Chaos In Every Enterprise isn't just some academic concept from a certification textbook. It is the mechanism that keeps your switches from broadcasting packets into an infinite loop that brings your entire LAN to a halt. Before we get into the configuration details, let me explain what STP actually does in plain terms. It takes a network with redundant paths, intentionally blocks some of those paths, and leaves you with a loop-free topology. When something fails, it unblocks an alternate path. That's it. Nothing magical about it. The protocol elects a root bridge, then determines the best path from every other switch to that root. Each non-root port gets placed into either a forwarding state or a blocking state. Blocking ports don't pass traffic. They only listen to Bridge Protocol Data Units from neighboring switches.
Understanding the Core Mechanism of Spanning Tree Protocol The Silent Guardian Preventing Network Chaos In Every Enterprise
STP runs on IEEE 802.1D. The original standard is over thirty years old now, and it still powers most enterprise LANs. RSTP, or IEEE 802.1w, is the faster version that most people actually use today. It reduces convergence time from the old thirty to fifty seconds down to roughly six seconds or less. PVST+, or Per-VLAN Spanning Tree, is Cisco's implementation that runs a separate spanning tree instance for each VLAN. This is important because if you're running multiple VLANs over a switched fabric, having a single tree for all of them means your blocking decisions are identical across every VLAN, which wastes bandwidth and limits load balancing options. Here's the part most people skip when they first learn this: STP doesn't block a port to save you from loops out of kindness. It blocks ports because if two switches have two physical links between them, broadcast frames will duplicate endlessly. ARP requests, DHCP discoveries, link-layer discovery protocol packets, every multicast frame bounces back and forth until switch buffers fill up and everything stops. I've seen a single misconfigured trunk between two distribution switches flood a core with duplicate frames. Bandwidth dropped to zero for about twelve minutes before I spotted the problem in Wireshark. The switch CPU was pegged at one hundred percent because it had to process every duplicate frame individually.
How STP Election Actually Works
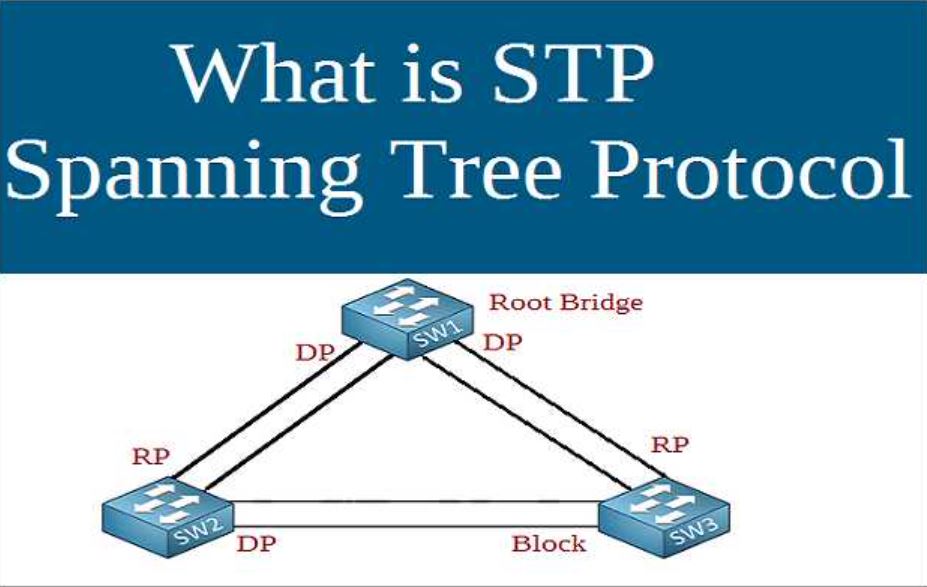
The root bridge election is the first thing that happens when switches boot up and discover each other. Every switch starts by assuming it is the root bridge. It sends out BPDUs with its own bridge ID as the root. When it receives a BPDU from another switch that claims to be root with a lower bridge ID, it concedes and updates its own topology database. The bridge ID is made up of two parts: a priority value and a MAC address. The default priority is three thousand two thousand seven hundred and sixty-eight. Lower is better. If priorities match, the switch with the lowest MAC address wins. This means you should always manually configure the root bridge priority rather than letting it happen by accident. I once found a network where a cheap access layer switch with a lower MAC address had become the root bridge for an entire floor because nobody had set priorities. All traffic from that floor was being routed through a suboptimal path up to the core and back down, adding latency and creating unnecessary load on uplinks that should never have carried that kind of traffic. Setting the root bridge to your intended devices with a priority like four thousand or even two thousand prevents this without much effort. Port roles come next. Each switch determines which of its ports are designated ports and which are alternate or backup ports. A designated port is the port on a segment that has the best path to the root bridge. It forwards traffic. An alternate port is a backup path to the root that isn't currently needed. A backup port is a redundant link on the same switch that connects to the same segment. Both alternate and backup ports go into a blocking state. Only designated ports and root ports forward traffic.
Get the Full Details

Port states in traditional STP are disable, listening, learning, and forwarding. Listening and learning both last for the forward delay interval, which defaults to fifteen seconds. That's eighty percent of your convergence time right there sitting in port states that don't actually do anything useful. RSTP compresses this dramatically by introducing discarding, learning, and forwarding states and by treating alternate and backup ports as discarding immediately rather than sending them through a timer-driven waiting period.
Configuration Walkthrough
On Cisco switches, which is what I'm using as the example since they dominate the enterprise space, the configuration is straightforward. You enter global configuration mode and set the priority on your intended root bridge. spanning-tree vlan 1,10,20,30 priority 4096 On your secondary root bridge for redundancy, set a higher priority so it takes over if the primary fails.
spanning-tree vlan 1,10,20,30 priority 8192 The secondary root bridge will only take over if the primary goes completely offline. A degraded primary with a higher priority will never lose root status to a secondary with lower priority unless the primary's BPDUs stop arriving entirely. This is intentional behavior. It prevents flapping between root bridges when a link degrades but doesn't drop. For edge ports that connect to end devices like workstations, servers, and IP phones, you should enable PortFast. This skips the listening and learning states and moves the port directly to forwarding. Without PortFast, a device that connects to a switch port has to wait thirty seconds before it can send DHCP requests or ARP traffic. That thirty-second delay shows up as a noticeably slow login on workstations and causes temporary DNS failures on boot. PortFast is safe on edge ports because end devices don't send BPDUs. If they somehow did, that would indicate another switch is connected where it shouldn't be.
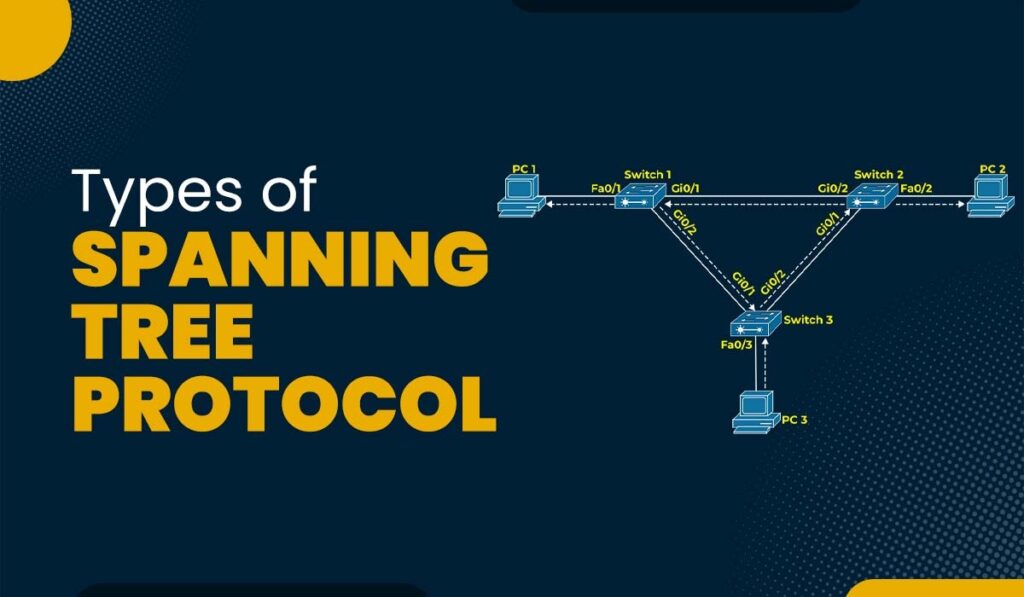
That leads to BPDU guard, which you should enable on every PortFast port. When BPDU guard is active and a port that receives a BPDU, it immediately puts that port into an error-disabled state. This prevents someone from accidentally plugging a switch into a wall jack in the office. I've dealt with that scenario twice in my career. The first time took me three hours to track down because the rogue switch was creating a loop that only affected a small department and nobody could figure out why their network was intermittent. The second time was faster because I had already enabled BPDU guard everywhere after the first incident. The port went error-disabled immediately and I got a syslog message telling me exactly which jack someone had misused.
Common Pitfalls and Edge Cases
One issue that catches people off guard is asymmetric cost configuration. If you manually set link costs on one switch but not on its neighbor, the two switches will disagree about the best path to the root. Switch A thinks the path through Switch B is cheaper. Switch B thinks the path through Switch C is cheaper. Both ports end up in forwarding state on both sides of the link, creating a loop despite STP being enabled. Always set path costs consistently across all switches in the same bridged domain. Use the same method whether that's the legacy cost values from 802.1D-1998 or the revised values from 802.1D-2004. Mixing them is a guaranteed way to get unpredictable blocking behavior. Another pitfall involves link aggregation and spanning tree. If you bundle two physical links into an EtherChannel and then configure spanning tree on the port-channel interface instead of the individual member ports, you can run into a situation where one member of the channel fails and spanning tree doesn't recalculate properly because it's only looking at the port-channel as a single logical link. Make sure your channel group configuration is consistent and that spanning tree is treating the port-channel as one interface, not two separate paths that need to be blocked. Here's a realistic scenario I ran into that illustrates how subtle STP problems can get. We had a data center with two core switches running VSS, which makes them appear as a single logical switch to the rest of the network. Underneath VSS, each physical chassis had its own separate spanning tree instance. A fabric link between the two chassis failed due to a bad SFP module. The VSS control plane stayed up, so the two chassis still talked to each other at the control level. But the data plane between them was isolated. Every downstream switch saw both chassis as valid designated bridges for different parts of the topology. Traffic destined for one chassis would arrive at the other and get dropped because the destination MAC didn't exist on that chassis. The network appeared partially working. Some VLANs were fine. Others were completely down. It took me about two hours to realize the VSS link was degraded because the symptoms didn't match a typical STP loop or a typical link failure. The workaround was swapping the SFP module and verifying the fabric link came back up before clearing any spanning tree counters. I also added a check to the monitoring system that alerts when VSS fabric throughput drops below a certain threshold, which would have caught this in under a minute the next time it happens.
When STP Isn't Enough
Spanning tree has hard limitations that you need to accept upfront. It blocks paths. That means unused bandwidth on redundant links is just sitting there. In a typical access layer design with two uplinks per switch to the distribution layer, only one uplink carries traffic at any given time. The other is blocked. This is inefficient by design. Modern alternatives like TRILL, IETF standardized multipath transparent interconnection of lots of links, and SPB, shorter path bridge, were created specifically to solve this problem. They allow equal-cost multipath forwarding at Layer 2 without creating loops by using link-state routing principles instead of spanning tree. But here's the practical reality. TRILL and SPB are not widely deployed in enterprise environments. Most network engineers will never configure them. STP, or more accurately RSTP and PVST+, is what your equipment ships with, what your vendors support out of the box, and what every network automation tool understands. If you're designing a new data center and you have the budget and the expertise, look into TRILL. For everything else, which is most organizations, STP is the tool you're working with and you need to know how to use it correctly rather than hoping a newer protocol will fix your problems. Another limitation is convergence time under scale. Even with RSTP, a large network with hundreds of switches and thousands of VLANs can take anywhere from ten to thirty seconds to fully converge after a major topology change. During that window, traffic is blackholed or misrouted. If your network carries real-time voice or video, that convergence event will cause audible gaps and video stuttering. The workaround is to keep your spanning tree topology as flat and simple as possible. Minimize the number of layers. Avoid long chains of switches where a single failure forces recalculations to propagate across many hops. Design with clear boundaries between access, distribution, and core layers so that a failure in the access layer doesn't trigger a full topology recalculation across the entire network.
Verification Commands and Monitoring
Show spanning-tree detail gives you the full state of every port on every VLAN. Show spanning-tree root gives you the current root bridge and cost information. Show spanning-tree interface status tells you which ports are forwarding and which are blocked. Run these commands regularly, not just when something breaks. I keep a baseline document that records the expected blocking ports for each VLAN. When I come in to a new job or a new network section, the first thing I do is verify the expected topology matches what STP is actually doing. Ninety percent of the time I find discrepancies that have been hiding in plain sight for months or years. SNMP polling of bridging MIB objects lets you build dashboards that track topology changes over time. A spike in topology change notifications is a strong indicator that something is wrong, whether it's a flapping link, a misconfigured port, or a failing piece of hardware. Set alerts for more than three topology change events in a five-minute window on any single switch. That almost always means a physical problem rather than normal operational variation. The protocol itself isn't complicated. The engineering discipline comes from understanding how your specific topology interacts with the protocol's behavior and catching misconfigurations before they cause incidents. Most networks that have stable spanning tree implementations are boring. The ones that aren't boring are the ones you get called in to fix at two in the morning because someone connected a personal switch to a conference room jack and took down the entire building's network. STP is there to prevent that. Making sure it's configured correctly is the only way to actually benefit from it existing.


