Sorting Nucleotide Building Blocks by Name or Classification
When you're working with genomic data or pulling sequences from a database, you eventually hit the problem of figuring out what you have and getting it into a consistent format. The standard four bases show up fine, but once you start dealing with sequencing artifacts, modified bases, or synthetic oligonucleotides, things get messy fast.Sort These Nucleotide Building Blocks By Their Name Or Classification The Molecular Alphabets Of Life
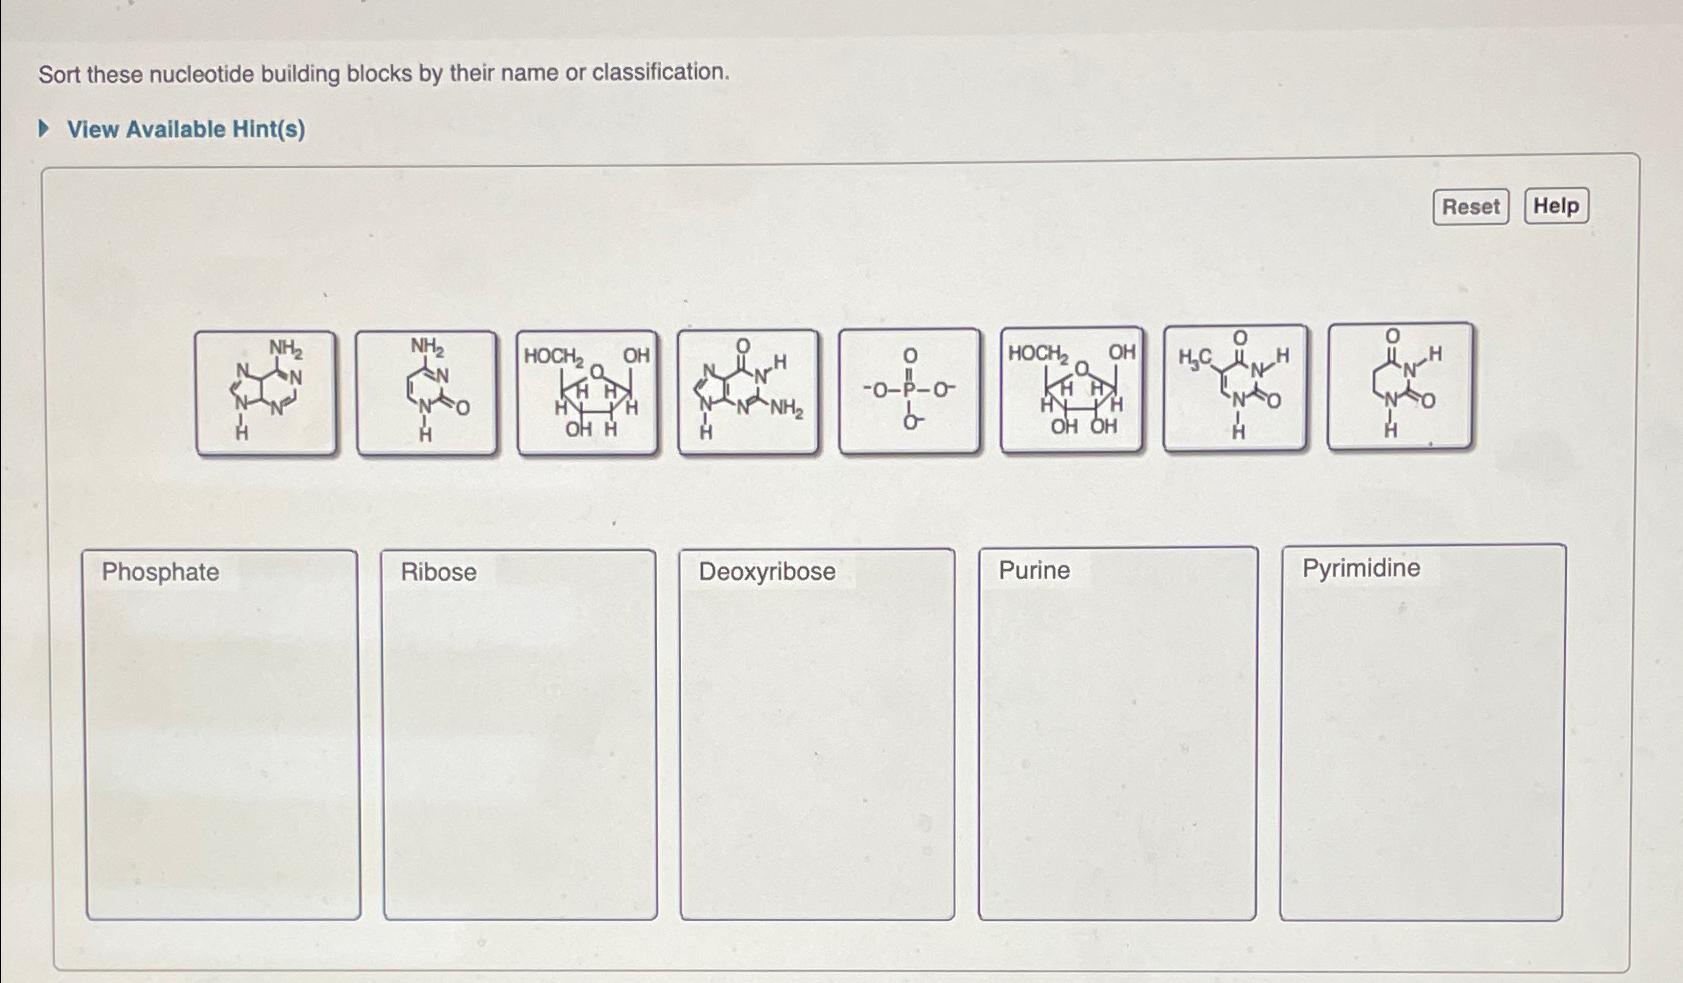
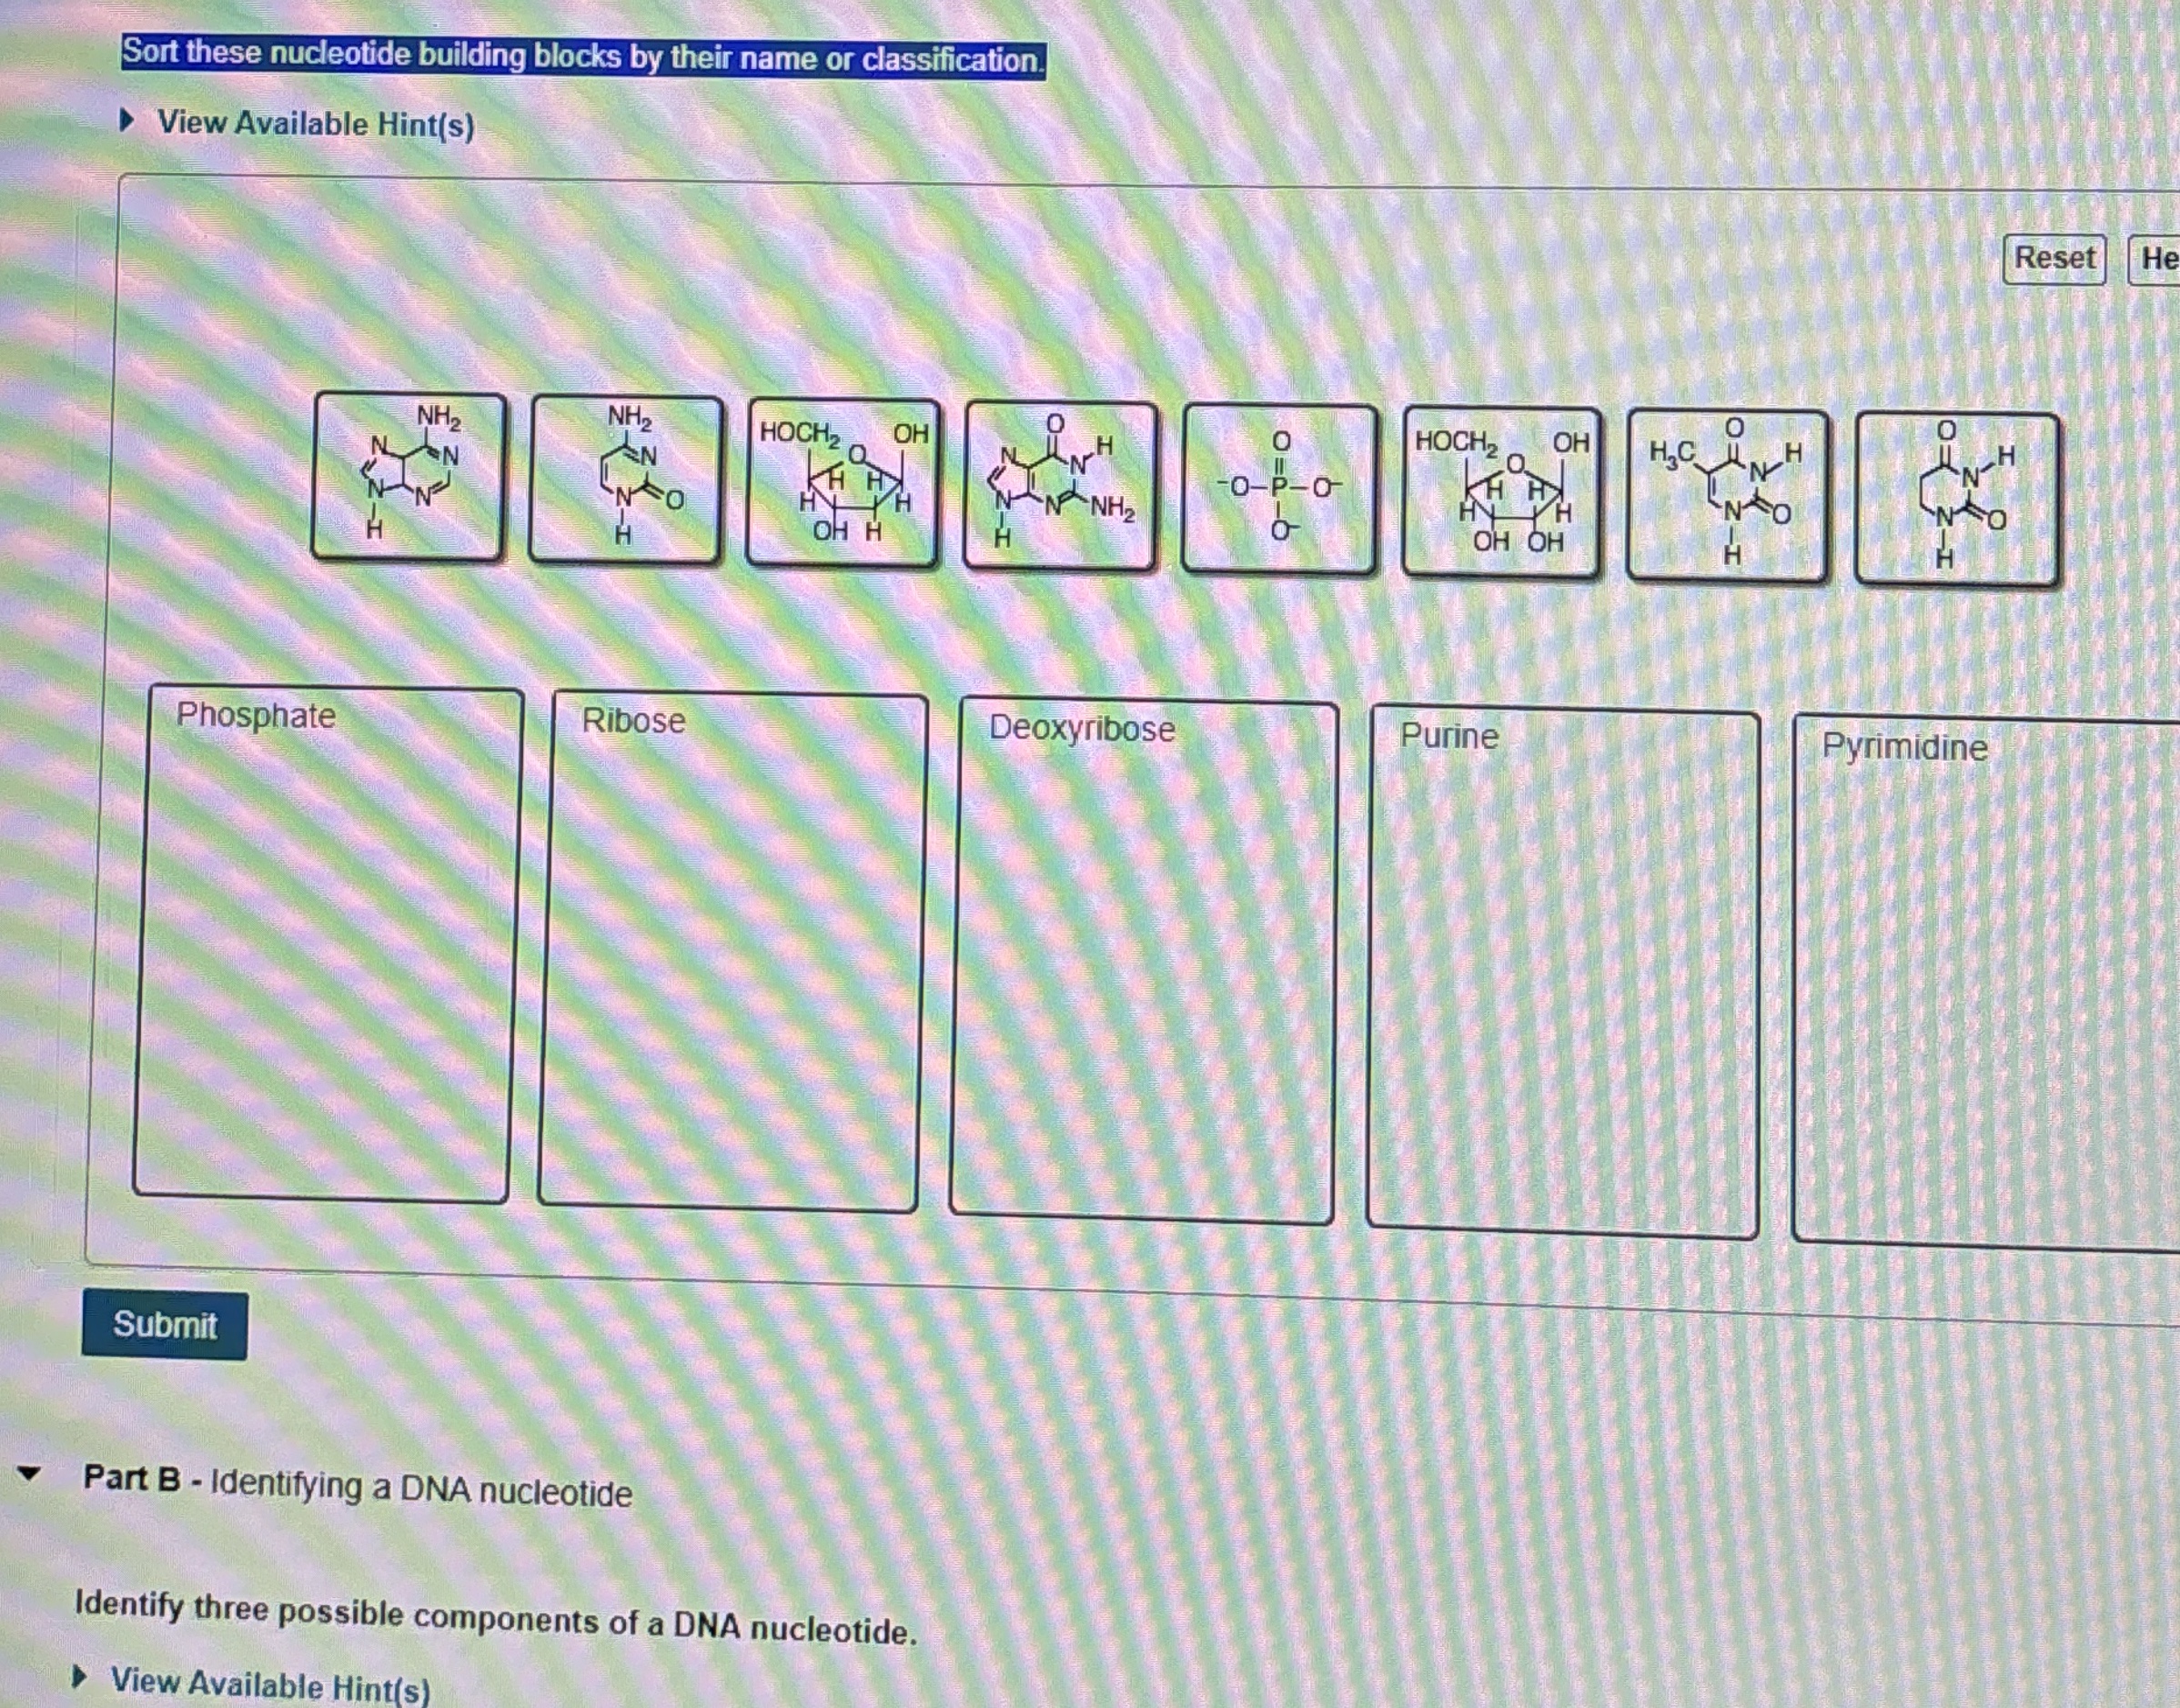
The foundation is the purine and pyrimidine split. Purines—adenine and guanine—have a double-ring structure. Pyrimidines—cytosine, thymine, and uracil—are single-ring. This isn't just taxonomy for its own sake. It matters when you're writing validation code or trying to catch sequencing errors, because a purine-to-pyrimidine transversion is a different class of mutation than a transition, and your sorting logic should reflect that distinction. Standard nomenclature uses single-letter codes: A, G, C, T for DNA and A, G, C, U for RNA. That's the easy part. The hard part starts when you encounter the IUPAC ambiguity codes. These are legitimate IUPAC-standard letters that represent positions where multiple bases are possible. R means A or G (purine). Y means C or T (pyrimidine). S means three hydrogen bonds—G or C. W means two—A or T. K is keto, so G or T. M is amino, so A or C. B stands for not-A (G, C, or T). D is not-G (A, T, or C). H is not-C (A, T, or G). V is not-T (A, G, or C). N is any base. These show up constantly in consensus sequences, degenerate primer designs, and mixed-read alignments. Beyond ambiguity codes, there are modified nucleotides that appear in real data. Inosine, often just written as I, shows up in tRNA and sometimes in sequencing reads where deamination has occurred. 5-methylcytosine is frequently relevant in methylation studies, though most standard FASTA output just writes it as C unless you're looking at bisulfite-converted data. Pseudouridine appears in RNA but rarely in standard sequence files unless you're specifically working with modified transcriptome data.
Here's a practical breakdown of how I organize this when I'm actually doing the work. First pass: map everything to IUPAC single-letter codes. Second pass: group by standard vs. modified vs. ambiguous. Third pass: if you need structural classification, tag each as purine or pyrimidine based on the letter's meaning, even for ambiguity codes. R and D and V are all purine-bearing. Y, H, and B are pyrimidine-bearing. S and K and M and W and N contain both types, so they don't cleanly sort into either category without additional context. I ran into a concrete problem a while back with a dataset from a nanopore sequencing run where the basecaller was outputting I (inosine) at positions where the reference had G. The pipeline I was using treated I as an unambiguous base and tried to align it directly, which produced nonsense results. The fix was straightforward but tedious: I wrote a quick translation step that converted all I's to G's before alignment, since inosine pairs with cytidine the way guanine does in most practical contexts. Without that preprocessing, any downstream sorting by classification would have been garbage because inosine doesn't neatly fit into the standard purine/pyrimidine framework without that biological context. Another thing people miss is the distinction between nucleosides and nucleotides. A nucleoside is a base plus a sugar—adenosine, guanosine, cytidine, thymidine, uridine. Add one or more phosphates and you get adenosine monophosphate (AMP), adenosine diphosphate (ADP), adenosine triphosphate (ATP), and the same for the others. When someone hands you a FASTA file, you're looking at just the base letters. But when they hand you a Metabolite or energy dataset, you might see ATP, GTP, cAMP, and other forms that have nothing to do with sequence sorting and everything to do with biochemical function. Mixing those up in your classification is a common beginner mistake.
The standard set is clean. DNA has four bases. RNA has four bases with uracil replacing thymine. But the edge cases are where real problems live. Synthetic nucleotides used in antisense therapies—locked nucleic acids, peptide nucleic acids, morpholinos—don't always fit standard classification schemes. Your sorting system will break if it assumes every input is one of the canonical letters. You need fallback handling for unknown characters rather than just flagging them as errors. If you're building a tool to do this, I'd recommend a simple lookup table approach. Map every recognized character to its classification first—standard base, modified base, ambiguity code, or invalid. Then add a secondary tag for purine versus pyrimidine where applicable. The whole process for a typical batch of sequences should take under a minute on modern hardware if you're doing character-by-character mapping rather than regex-heavy pattern matching. Anything slower suggests you're overcomplicating it. One more nuance worth noting: the IUPAC codes aren't just for DNA sequencing. They're used in primer design, consensus motif representation, and even protein coding sequence annotations where degeneracy matters. If you're only handling clean reference genomes, you might never need the full ambiguity code set. But the moment you work with real experimental data—which always has some level of ambiguity—the full IUPAC set becomes essential.
Get the Full Details