What Exactly Slendy Tubbies Are and Why They Spread So Fast
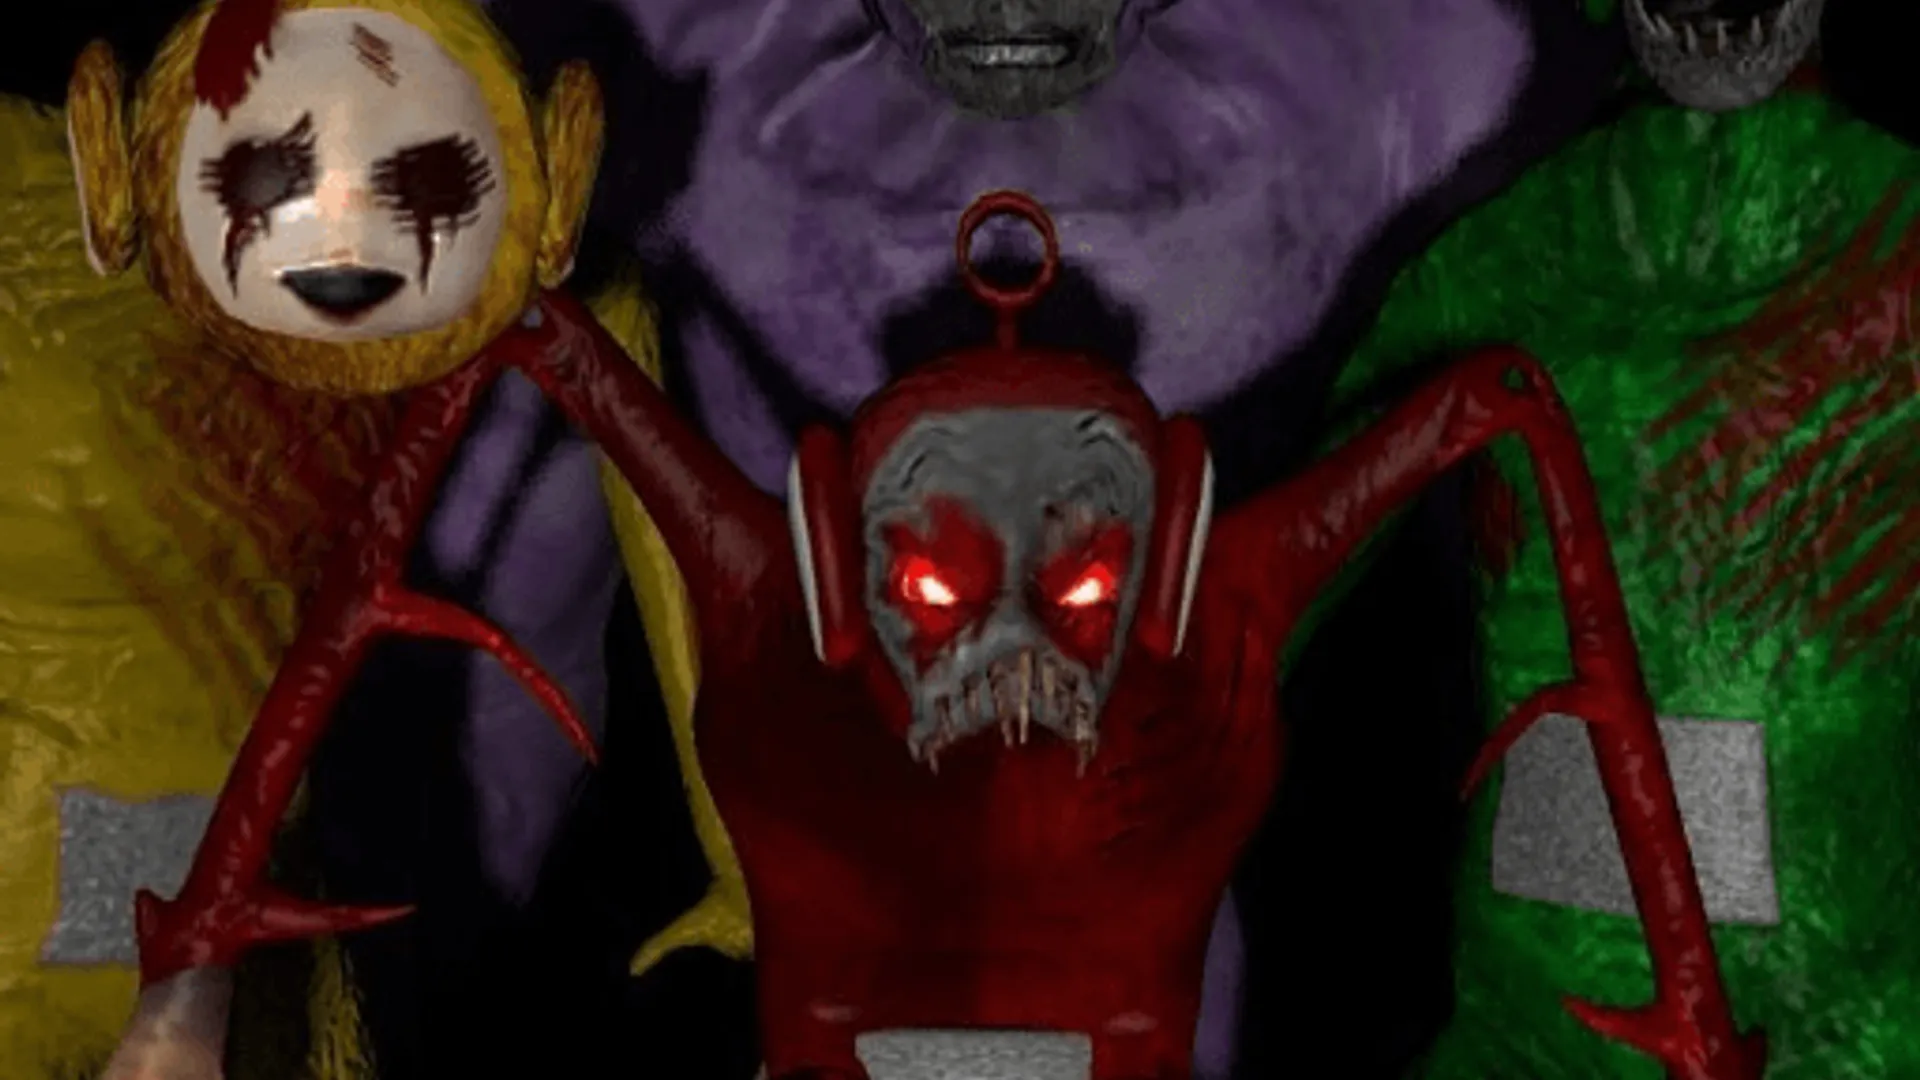
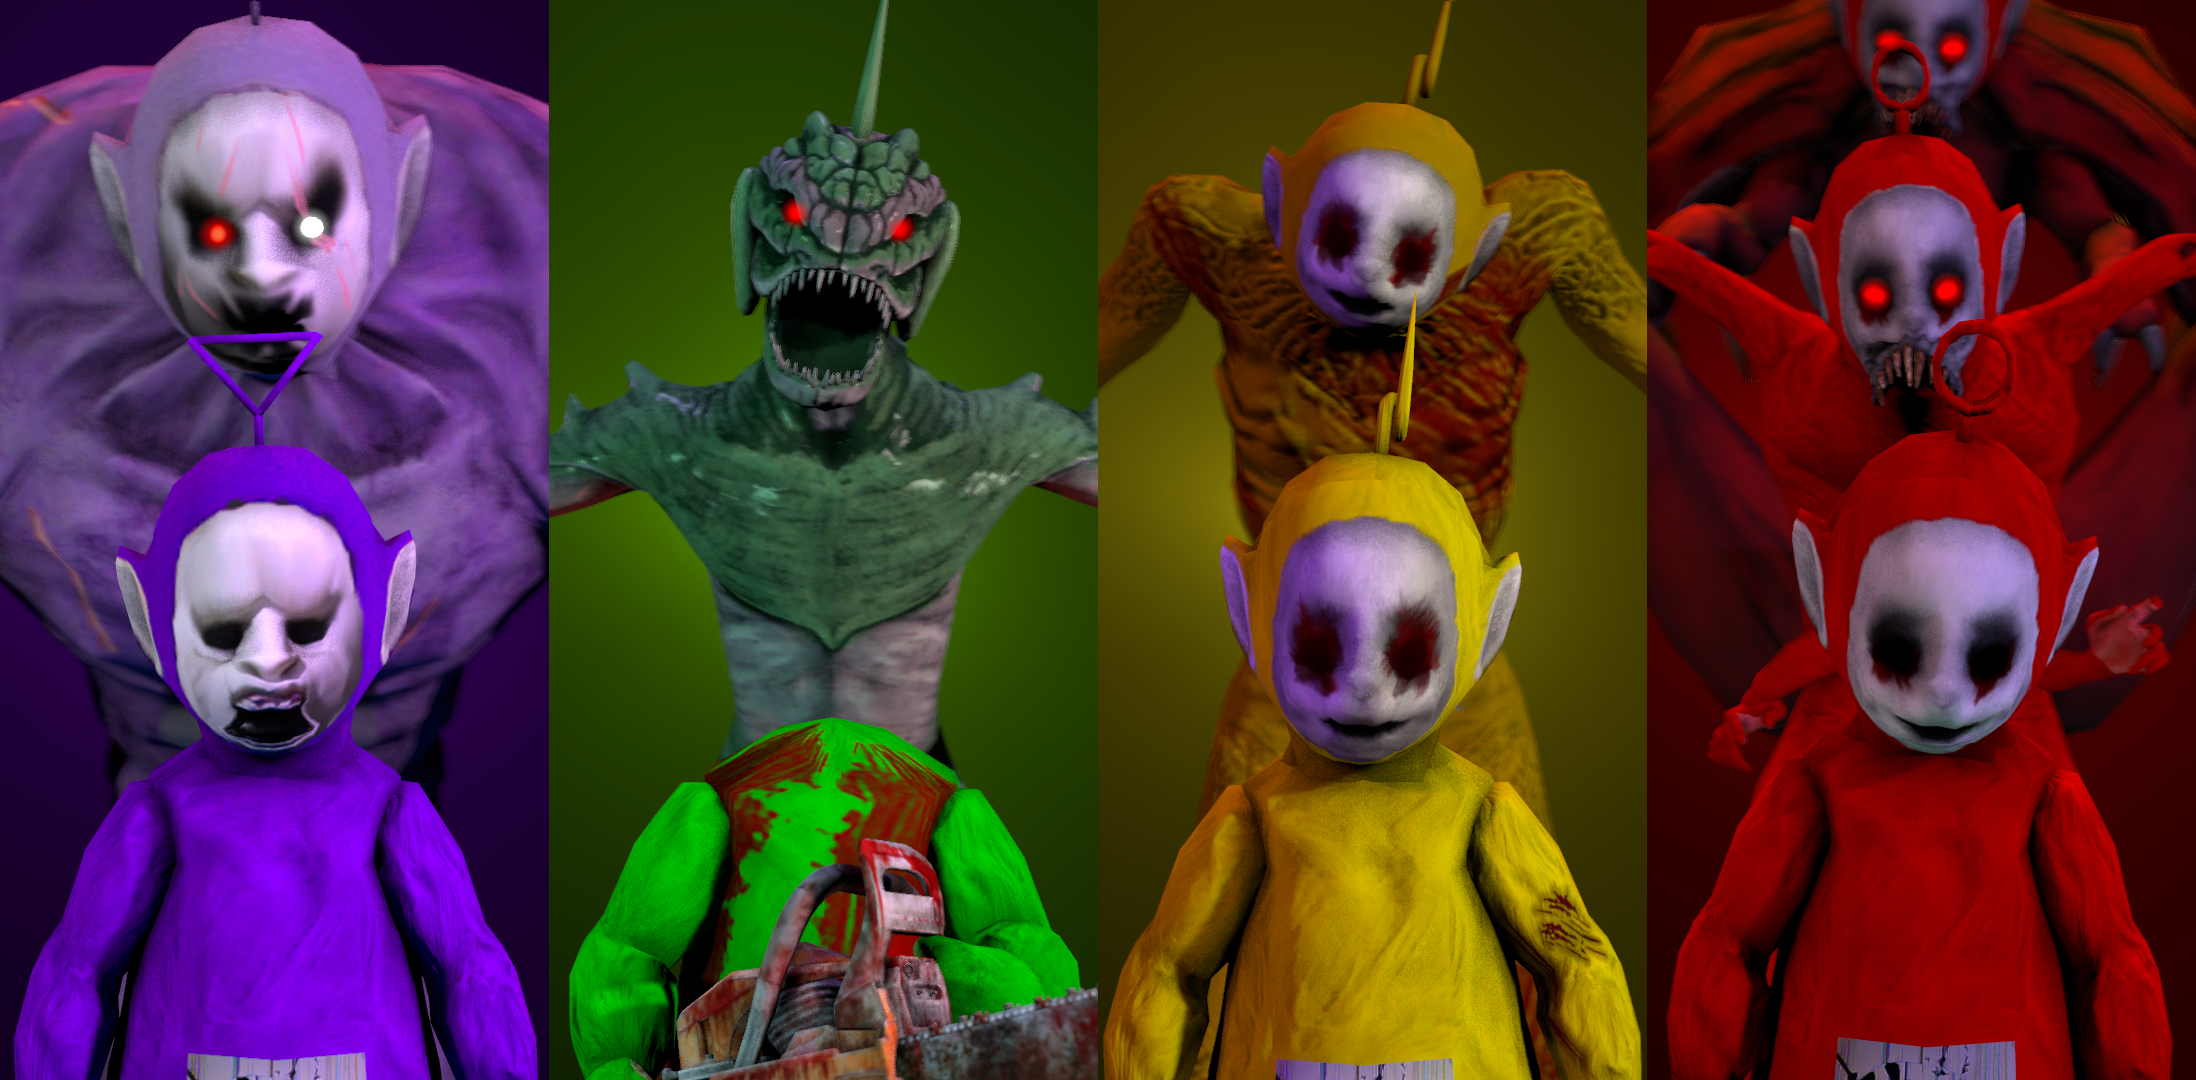
You open TikTok or YouTube Shorts and suddenly there it is again. A distorted, low-resolution image of a Teletubby with too-long limbs standing in a dark forest. The audio is some warped synth noise. The comments are full of people asking where the image came from. This is the current wave of Slendy Tubbies content, and it has been recycling through the internet for a while now. The original Slendy Tubbies concept dates back to around 2015-2016 when early creepypasta artists started photoshopping the bright Teletubbies characters into dark, Slender Man-style settings. The name comes from combining "Slender" with "Tubbies." What started as a few Reddit posts and DeviantArt uploads has grown into a full micro-genre of creepy fan content. Here is the practical breakdown of how this phenomenon works and how you can engage with it if you want to. The content revolves around AI-generated orPhotoshopped images of Teletubbies rendered as uncanny, elongated, almost skeletal figures placed in abandoned or dark environments. Some creators make short horror videos with them. Others just post single unsettling images. The characters you will see most often are a twisted version of Po, Tinky Winky, Dipsy, and Laa-Laa, but stripped of their cartoon innocence. Their colors are desaturated or completely wrong. Their proportions are off. That deliberate wrongness is what drives the whole trend. I spent a few weeks tracking where these images actually originate. Most of them come from a handful of AI image generators. The process is straightforward. People use tools like Stable Diffusion with specific checkpoints trained on creepypasta aesthetics, or they run prompts through Midjourney or similar platforms. The prompts themselves are usually simple. Words like "slendy tubbies," "creepy teletubbies," "uncanny valley teletubbies," "dark forest teletubby," and "horror animation still" tend to surface the right results. I noticed that adding negative prompts like "cute," "bright," "cartoon style," and "happy" drastically improves the output quality. Without those negatives, the AI just gives you regular Teletubbies with a filter applied, which looks amateurish and kills the effect.
The real problem I ran into was consistency. When I tried generating a series of images that looked like they belonged together, the AI kept changing the character designs between frames. One image would have Po with normal proportions but dark lighting, and the next would have an entirely different body shape. I solved this by using ControlNet with a depth map or edge detection pass. You generate a basic silhouette first, lock it in, and then feed that structure into subsequent prompts. It takes about ten minutes extra per image, but it keeps the character design stable across a whole set. If you skip that step, you end up with five images that look nothing like each other and nobody believes they are from the same series. Another thing beginners get wrong is the audio. A lot of people posting Slendy Tubbies content slap any random scary soundtrack over their images. It does not work well because the audio clashes with the visual tone. The best versions use either complete silence with a low ambient hum or audio that sounds like it is coming from a damaged VHS tape. You can find free VHS degradation sounds on Freesound.org. Layer a subtle tape hiss, lower the pitch by about eight percent, and add a barely audible reversed voice sample. That combination makes the images feel genuinely uncomfortable rather than just edgy for the sake of being edgy. Where to actually find and download these images
The main hubs are still Reddit communities like r/CreepyTubbies and r/Slendytubbies, TikTok accounts that post carousel slideshows, and YouTube channels dedicated to analog horror content. Pinterest is also a surprising source. A lot of creators repost there and it tends to get wider reach than Reddit. For actual downloads, most high-quality versions end up on DeviantArt or ArtStation under tags like "slendy tubbies" or "teletubbies horror." I use a simple browser extension called Image Downloader to grab batches from those pages rather than saving them one by one. It saves maybe twenty minutes per session if you are building a reference library. If you want to make your own, the most accessible route is using a free Stable Diffusion web interface like Tensor.art or Clipdrop. Neither requires a powerful GPU. You can run generations directly in the browser. Set your resolution to 512 by 768 for portrait orientation since most of the existing content follows that format. Use the SDXL checkpoint if you want higher detail, or stick with SD 1.5 if you want that chunkier, more intentionally low-fidelity look that fits the aesthetic better. I usually go with SD 1.5 because the slight softness reads as more unsettling than crisp HD output. There is a downside to this whole workflow that nobody talks about enough. The internet is already flooded with mediocre Slendy Tubbies AI images. Posting another generic creepy Teletubby in a dark forest will not get traction unless you add something genuinely different. I tried posting standard generated images on Twitter and got maybe thirty impressions. The accounts that are actually doing well right now are the ones adding narrative context. They are framing the images as found footage, or creating mock documentarians, or presenting them as evidence from a fictional paranormal investigation. The visuals alone are not enough anymore. The packaging matters more than the generation quality.
Get the Full Details
Also be aware that NBCUniversal owns the Teletubbies IP. You will not see takedowns on small AI-generated images because nobody is going to waste legal resources on that. But if you plan to sell merchandise or build a commercial project around these characters, you will get a cease and desist. That has happened to bigger channels before. Keep it as fan content if you want to stay clear of that issue. The trend will probably fade within six to eight months. It always does. But the current wave is strong enough that posting quality content now will still catch an active audience. Focus on consistency in your character design, invest time in the audio component, and add a narrative layer instead of just posting raw images. That is what separates the accounts getting genuine engagement from the ones blending into the noise.