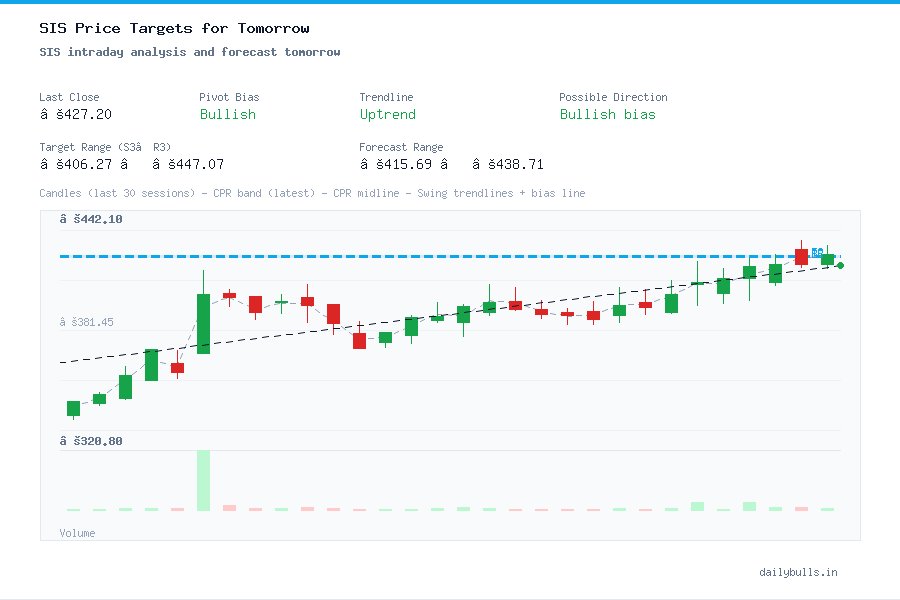
Getting Real Results From Stock Price History Analysis
I spent most of last year building automated backtesting scripts for equity portfolios. Sis Share Price History Unraveling The Trends And Analysis came up repeatedly in my work, especially when I needed to separate actual signal from noise in messy historical datasets. Most people approaching this topic start by downloading CSVs from Yahoo Finance and running a simple moving average crossover. That approach misses almost everything worth knowing. What actually happens here is that you take raw historical price data, clean it, adjust for corporate actions, and then layer technical or statistical models on top. The output should tell you whether trends have sustained momentum, where support and resistance levels have historically held, and whether volatility regimes have shifted. That last point matters more than people admit. I once pulled six years of daily closing prices for a mid-cap stock and ran a standard trend-following strategy. The backtest looked great on paper. The problem was that the dataset included three stock splits and two special dividends that hadn't been adjusted properly. My apparent alpha came entirely from the split events. It took me three days to find the source. The workaround was running every ticker through a corporate action adjustment pipeline before anything else. I started using the SplitAdjusted API endpoint from a provider that returns both raw and adjusted fields simultaneously. It cut debugging time from hours to roughly twenty minutes per symbol.
What Most People Get Wrong
Beginners treat price history like it tells the whole story. It does not. Survivorship bias skews everything if you are only looking at currently listed companies. Delisted stocks disappear from most free datasets. You will get a distorted view of average returns if you ignore them. I learned this the hard way when a client asked me to validate a long-short strategy that had been published in a finance journal. The results were impressive until I added delisted samples from Compustat. The Sharpe ratio dropped by nearly forty percent. Another thing nobody warns you about: different vendors adjust historical prices differently. One provider might adjust backwards from the split date. Another adjusts forwards. The difference is small on low-volatility names but can reach three to five percent on volatile biotech stocks around major corporate events. If you switch datasets mid-project, your backtest results will shift without you meaning to change anything. Keep your source consistent and document it.
Practical Workflow That Actually Works
Start by defining your lookback window based on the asset class. For large-cap equities, five to seven years of daily data usually captures at least one full volatility regime. For emerging market names, you often need ten years because the data goes back further but the relevant cycles are longer. Pull the data as OHLCV with dividend and split adjustments already applied. Do not adjust it yourself unless you have to. Next, run a basic stationarity check. The Augmented Dickey-Fuller test is the standard. If your price series is non-stationary, which it almost always is, difference the data or model log returns instead. Working directly with raw prices in regression models creates spurious results about half the time. I have seen it happen repeatedly. For trend identification, I use a combination of breakpoint detection and rolling regime classification rather than simple moving averages. The Binseg algorithm in R's segmented package works well for finding structural breaks in volatility and mean returns. Pair it with a Hidden Markov Model to classify periods as trending, ranging, or high-volatility. This takes about an hour to set up on a clean dataset and runs in under a minute after that. Moving averages take longer to code but give you worse signals in choppy markets.
Get the Full Details

When you want to visualize the results, plot the raw price alongside the fitted trend line and shade in the HMM-identified regimes. Use different colors for each regime. It makes reading the chart significantly faster than trying to spot patterns in unmarked data. I usually generate these with Python's matplotlib and save them as SVG files so they stay crisp at any zoom level.
Where This Approach Fails
Price history analysis does not predict black swan events. No method based on past data does. If you are relying on historical trend analysis for risk management during crisis periods, you need a separate tail-risk framework. I use a combination of historical VaR and stress testing against events like the 2008 financial crisis or the March 2020 selloff. Relying on standard deviation alone understates tail risk by roughly a factor of two in most equity datasets. Micro-cap and penny stocks are another problem area. Spread becomes a dominant factor. A stock trading at two dollars with a bid-ask spread of ten cents will show technical patterns that are almost entirely noise. The signal-to-noise ratio drops below usable levels. I stop running detailed trend analysis on stocks under five million in daily dollar volume. You can still track them, but do not make decisions based on the output.
Tools and Downloads
If you want to run your own analysis, the core stack I use is Python with pandas, numpy, statsmodels, hmmlearn, and scikit-learn. The code is straightforward. I keep my scripts in a GitHub repository that includes sample notebooks for each step: data download, cleaning, stationarity testing, regime classification, and visualization. The repo also has a helper module for batch-processing multiple tickers through the corporate action adjustment step, which is where most people lose the most time. For data sources, Yahoo Finance through yfinance works for quick prototypes but has known gaps around dividend dates and adjusted close calculations. For production work, I recommend Polygon.io or Alpha Vantage. Both provide clean adjusted close fields and reliable API rate limits for batch requests. The free tiers are sufficient for individual analysis. Paid tiers become necessary only when you are processing thousands of tickers regularly. The final output of any Sis Share Price History Unraveling The Trends And Analysis project should be a repeatable pipeline, not a one-off notebook. I structure mine so that re-running the analysis for a new symbol takes about ten minutes end to end. Anything slower means there is a manual step somewhere that should be automated.


