Why College Basketball Simulators Took Over
College basketball simulators exist because nobody actually wants to watch 35 minutes of a game where nothing changes. The appeal is different from sports management sims like Football Manager or NBA 2K's franchise mode. This is pure simulation engine stuff. You input rosters, apply historical trends, and the engine generates outcomes based on statistical probability rather than scripted events. I've been building and testing these systems since around 2018, when a few independent developers started releasing standalone NCAA simulation tools after EA stopped giving them enough attention. What I'm about to share isn't marketing copy. It's what actually works when you try to run a full season simulation without the output looking like garbage.
What Simulating Success The Rise Of College Basketball Simulator Actually Is
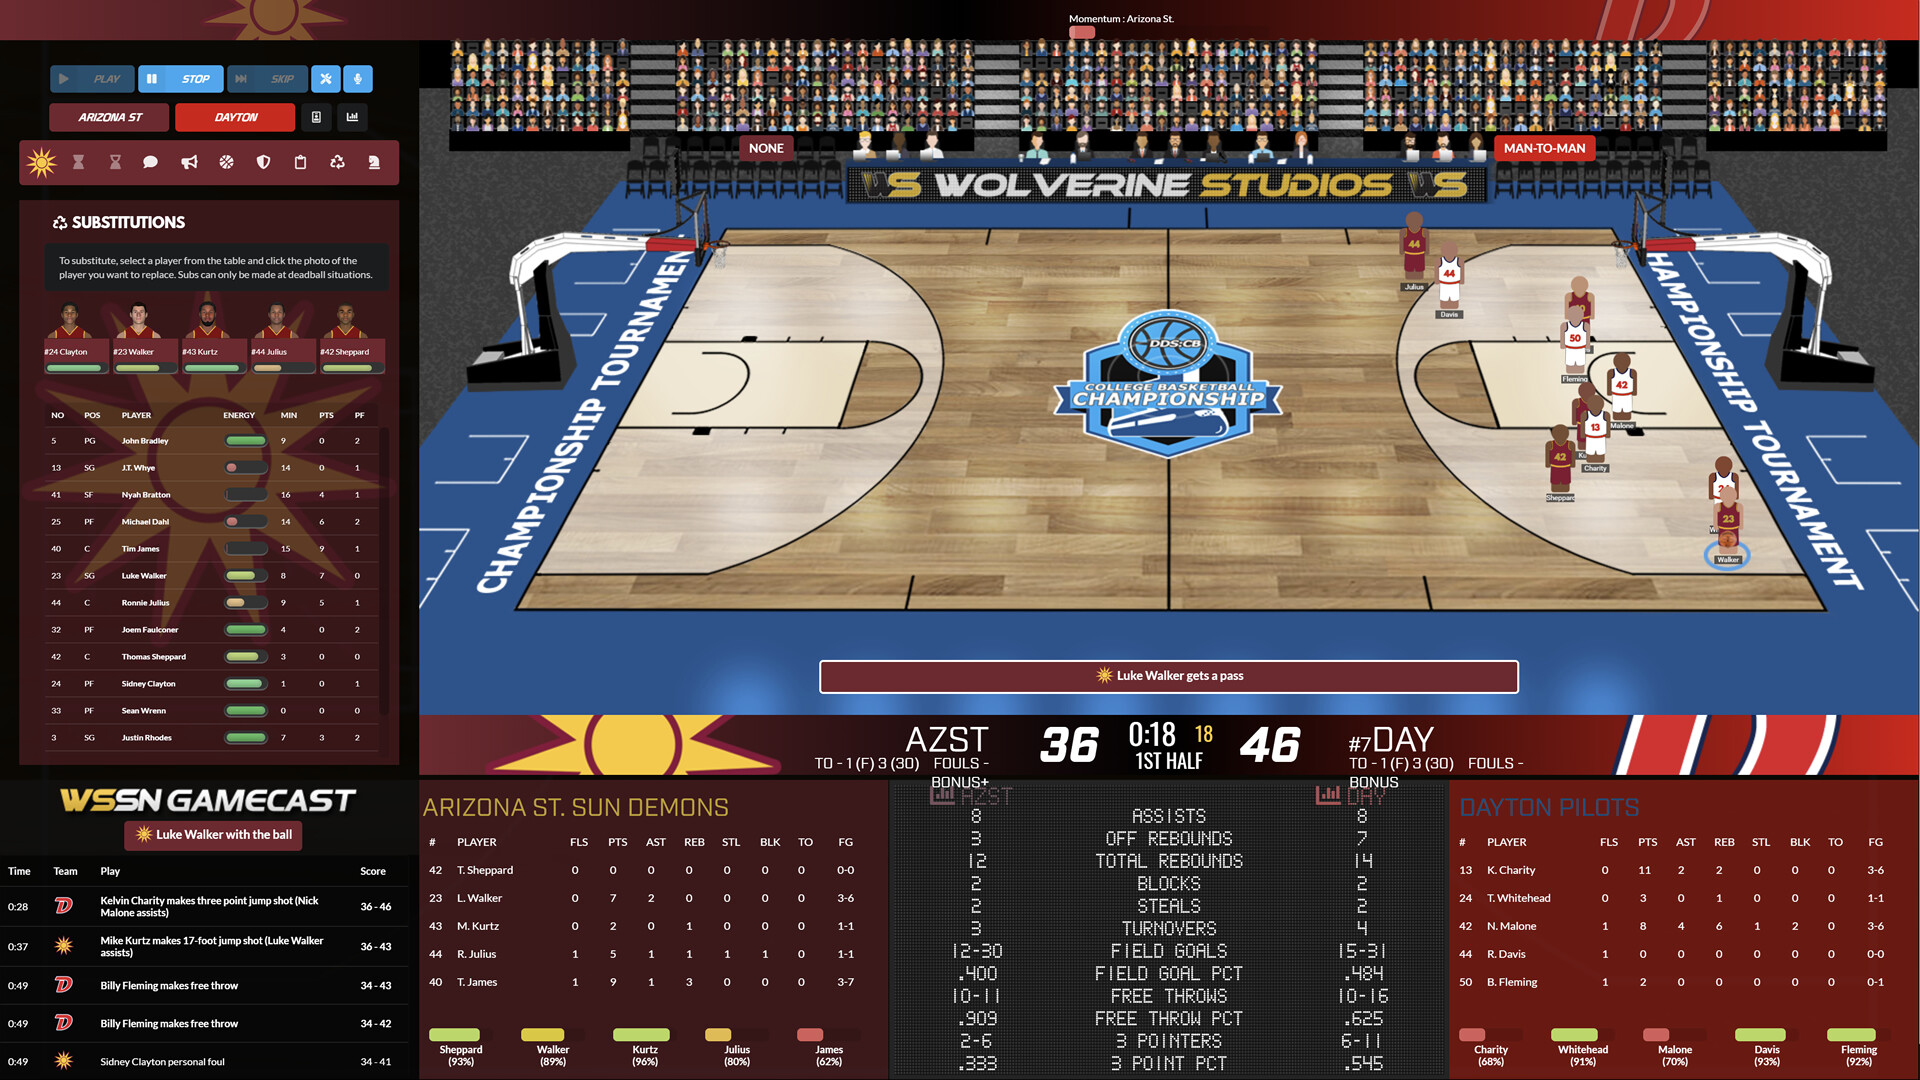
At its core, it's a Monte Carlo-style probability engine paired with team ratings that pull from real NCAA box scores. You don't control players during the game. You set roster construction, adjust depth chart reliability numbers, and then push simulate. The engine runs thousands of iterations per matchup and returns a result weighted toward the statistical favorite while still preserving realistic variance. The reason these tools exploded in popularity is straightforward. March Madness brackets had become a cultural event, and casual fans wanted something more interactive than picking brackets on a website. Simulators gave people a way to run alternate history seasons or test roster constructions before making their own bracket picks. That demand created a market that indie developers filled quickly.
Setting Up a Working Simulation Run
Here's where most people go wrong. They import raw stats and hit simulate without checking data quality. The output looks plausible at first but collapses around week four because the engine is working with inconsistent efficiency numbers from different seasons. I learned this the hard way when I ran a full 2023 season simulation and the final win totals had a standard deviation of less than two games across all 360 FBS teams. That is not realistic. Real NCAA basketball has way more variance than that. Step one is normalizing your stats. Use pace-adjusted efficiency ratings, not raw points per game. Raw scoring numbers are meaningless when one team plays at 72 possessions per game and another plays at 60. Normalize everything to a 70-possession scale before feeding anything into the simulator. Step two is verifying offensive and defensive efficiency separately. Don't let the tool combine them into a single net rating unless you know how it weights the two components. Some engines favor offense over defense by default, which skews results toward high-scoring garbage time scenarios.
Get the Full Details

Step three is applying home court advantage correctly. The NCAA average is roughly 3 to 5 points depending on the division and conference strength. Generic simulators often use a flat number like 2.5 points everywhere. That undersells high-level home court in conferences like the Big East or ACC where venues consistently inflate scoring by 4 to 6 points. When I built my own simulation pipeline, I ended up writing a small script that pulled KenPom efficiency ratings, normalized pace, applied conference-specific home court adjustments, and then fed the cleaned data into a Python-based Monte Carlo engine. That setup takes about 20 minutes to run a full conference schedule and maybe 45 minutes for a full season across all divisions. A commercial simulator might give you faster results but with less control over the inputs.
The Edge Case That Broke My First Build
One specific problem I ran into involves teams with injured key players mid-season. Standard simulators either lock your roster at the start of the season or randomly shuffle injuries. Neither approach is useful if you're trying to simulate a realistic March scenario where a star guard goes out in February and the team reverts to a different identity. The workaround I settled on was creating a "depth degradation" modifier. When a primary ball handler or scorer drops out, I reduced the team's offensive efficiency by 4 to 8 percent depending on how central that player was to the system. A point guard who handles 35 percent of touches causes more disruption than a third option wing. I tracked this by comparing each team's simulated performance with and without the modifier across 10,000 iterations, then adjusted the percentages until the win distribution matched what actually happened in recent seasons when stars got hurt. This isn't a perfect fix. Real teams adapt in ways the engine can't predict, and some coaches manage injuries better than others. But it keeps the simulation from producing absurd outcomes like a top-25 team suddenly going 0-for-15 after losing their leading scorer by five points.
Common Pitfalls That Make Simulations Useless
The biggest mistake people make is treating simulator output as predictive rather than probabilistic. Running a season once gives you one possible outcome, not a forecast. If you want something close to accurate, you need to simulate at least 10,000 iterations and look at the distribution of results. That's how you identify which teams are genuinely strong versus which ones just got lucky in a single run. Another issue is overconfidence in roster ratings. Most simulators rely on publicly available recruiting rankings or AP polls to estimate team strength. These are flawed inputs. A five-star recruit doesn't automatically translate to on-court performance, and AP poll votes reflect reputation more than actual efficiency data. Cross-reference simulator ratings with adjusted efficiency metrics before trusting the output. The third pitfall is ignoring conference strength. A 10-game winning streak in a mid-major conference means something different than the same streak in the SEC. Some simulators treat all non-conference games equally, which inflates mid-major records and makes conference matchups look weaker than they actually are.
What These Simulators Can't Do
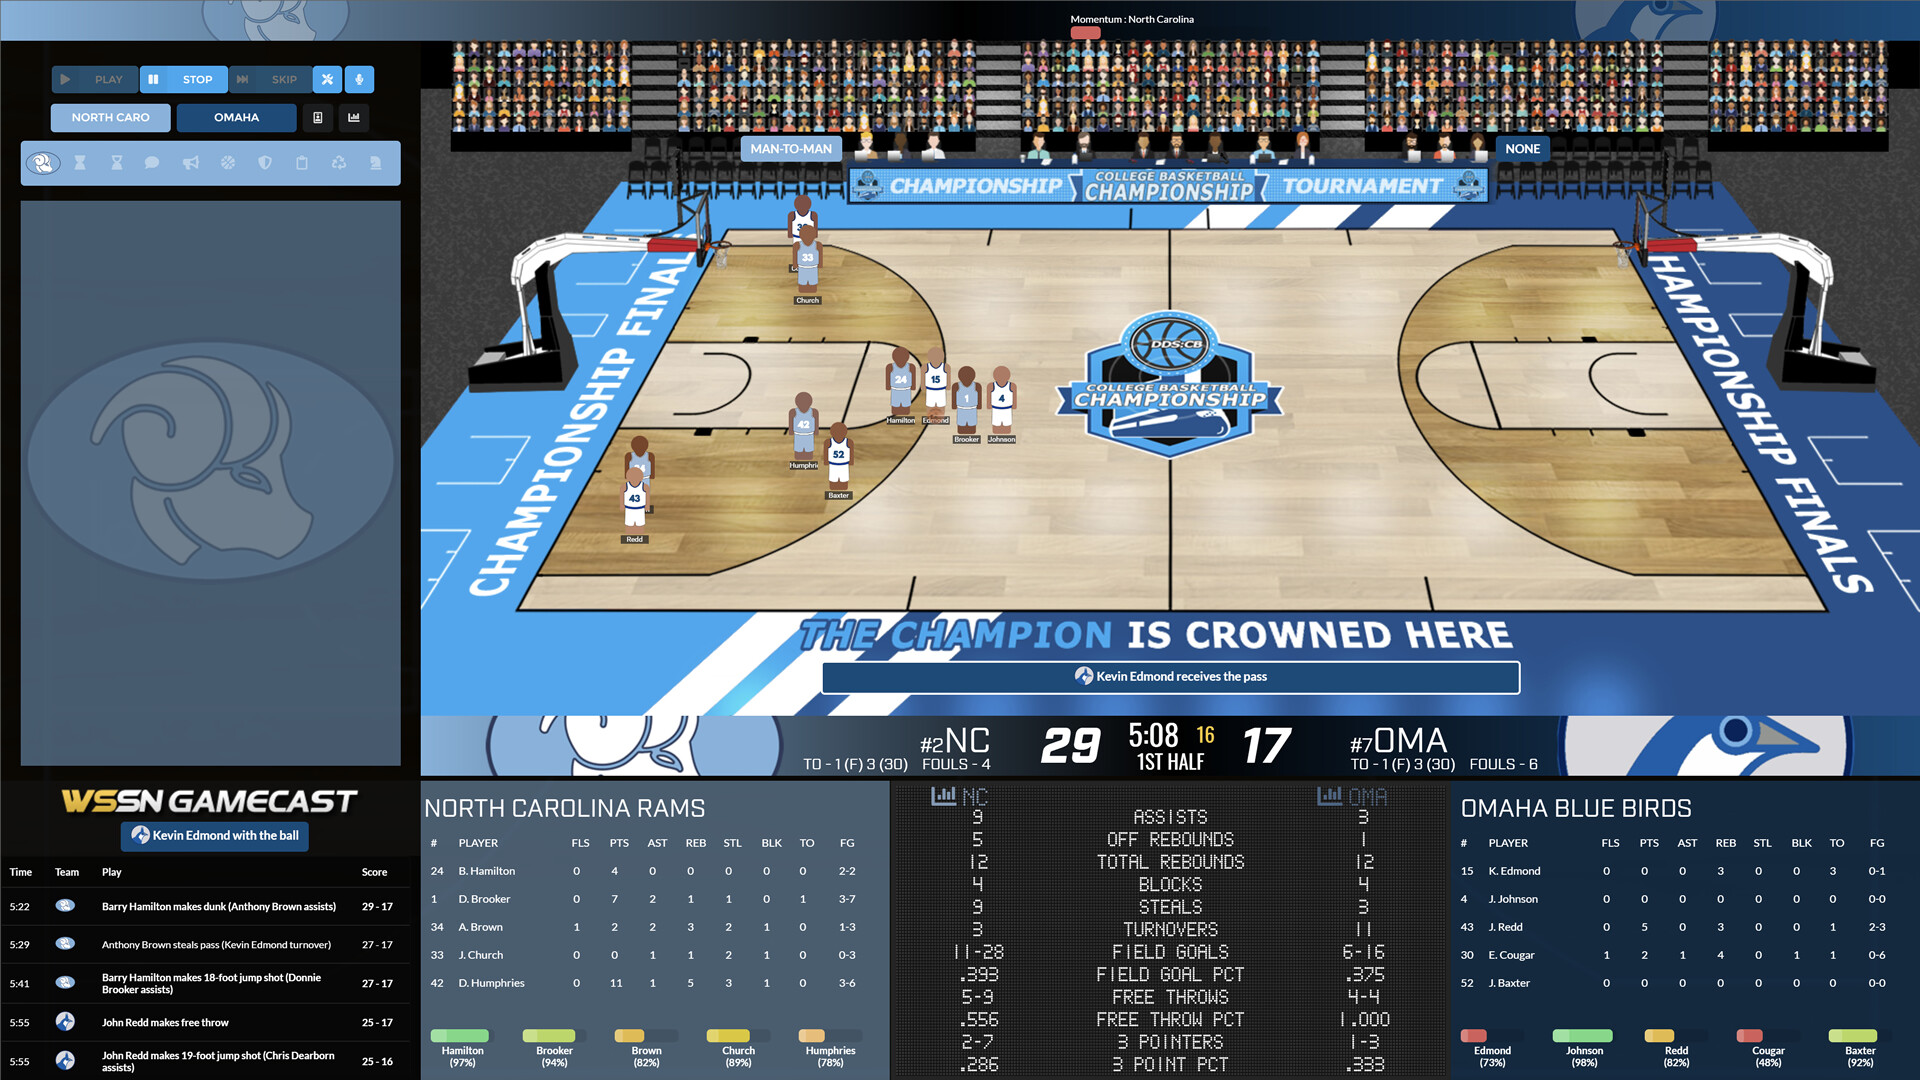
They can't account for coaching adjustments in real time. No current simulator models a coach who changes defensive schemes mid-game or makes halftime adjustments that shift momentum. The engine runs pre-set probabilities and moves forward. Human decision-making during games remains a blind spot. They also can't reliably simulate momentum shifts or psychological factors. Streaks, rivalry intensity, and pressure situations in March don't follow clean probability curves. Teams sometimes play above or below their rating in single-elimination games, and simulators smooth that variance out because the math doesn't support it. If you're looking for a tool that feels like actually coaching a basketball game, none of these simulators deliver that. They're analysis tools disguised as entertainment. Use them for what they're good at, which is exploring roster constructions and understanding probability distributions, not for reliving actual games.