What These Reports Actually Look Like When You Dig Into Them
Most people who request police call logs from a municipality like Topeka expect one thing: a spreadsheet with timestamps, addresses, and incident types. What you get instead is something messier. The data is real, but it is assembled by different agencies over many years, often with slightly different column names and inconsistent coding. The numbers you see at face value will not tell you the actual story unless you understand what was included, what was excluded, and how the raw calls were classified. I have pulled several batches of Topeka call data over the years, sometimes through open records requests and sometimes from publicly posted crime dashboards. The work is not glamorous. It is mostly about matching code sheets to actual report entries and figuring out why a single street address can show up as five different incident types depending on which desk sergeant was on shift.
Shocking Crime Rates In Topeka Unpacking The Numbers Behind The Ross Topeka Police Calls Reports
The phrase you see floating around comes from people reacting to the raw volume of calls in certain neighborhoods. Volume is not the same thing as severity. A district with a high call count can actually have fewer violent incidents than a district with a much lower count. That is because service calls, welfare checks, and traffic stops make up the bulk of municipal police work. Understanding that distinction is the first step before anything else. Topeka police reports and call logs are maintained by the Topeka Police Department, with data that sometimes flows into state-level reporting systems. What you will notice immediately is that the structure shifts. A field that was called Dispo one year becomes Disposition the next. Dates get formatted differently. Address fields lose consistency. These are not anomalies you can ignore, because ignoring them is how you double-count incidents or miss entire categories. Here is what most people miss when they start pulling this data: the difference between a 911 dispatch, a non-emergency call, and a self-initiated officer activity. Each category has a different weight. If you are comparing year-over-year crime rates and your dataset only captures 911 calls, you are missing a large chunk of enforcement activity. If you only look at arrest reports, you are missing the calls that were logged but never escalated. The truth sits somewhere in the middle, and you have to pull from multiple sources to approximate it.
How I Actually Process These Reports (Step By Step)
I do this manually at first, then automate the repetitive parts. Here is the exact workflow I use when I get a new batch of Topeka police call data: Step one: map the columns. Open the file and write down every unique column name. Create a master reference sheet that tracks which column maps to call type, date, time, address, response type, clearance status, and officer unit. If the file uses abbreviations like MVT for motor vehicle theft or BKA for burglary, write those down now. You will thank yourself later. Step two: standardize the dates and times. Police logs frequently mix 12-hour and 24-hour time formats. I convert everything to UTC immediately so cross-referencing with other datasets does not break. Addresses get normalized by splitting street number, street name, and suffix into separate columns. This sounds tedious, but it is the only way to do meaningful geographic analysis.
Get the Full Details

Step three: deduplicate using overlapping records. A single call can generate multiple entries. A domestic dispute might spawn a separate entry for the initial response, a follow-up investigation, and an eventual arrest. I use a composite key of date + time window + address + primary offense type to identify which rows belong together. This step usually collapses the dataset by about 15 to 30 percent, depending on the time period. Step four: classify by severity tier. I group everything into tiers: violent felony, property felony, misdemeanor, traffic, and service call. This is where the real insight appears. A lot of the noise disappears once you stop treating every row as equally important.
A Real Problem I Ran Into (And How I Fixed It)
While working with one batch of Topeka call data, I hit a specific edge case that almost ruined my analysis. The dataset had approximately 12,000 records spanning eighteen months. When I cross-referenced addresses against city GIS boundary data, I noticed that roughly 8 percent of the calls had no geocode match at all. Most of them were blank or listed as intersection or parking lot descriptions instead of actual street addresses. I nearly discarded the entire subset, which would have introduced a real bias toward commercial and public-space incidents. The workaround was straightforward but took hours. I manually entered the unmatched records into Google Maps and OpenStreetMap one by one until I found their coordinates, then mapped them back to the nearest police beat. It was slow. There is no automation that handles this well because the raw text varies too much. But skipping it would have made the final numbers inaccurate. I now budget about two to three hours per ten thousand unmatched records for manual geocoding. It is not fast, but it is honest.
Common Pitfalls That Make These Numbers Look Worse Or Better Than They Are
The biggest mistake I see people make is comparing raw call counts across districts without adjusting for population and area. A residential zone will naturally generate more calls than a sparse industrial zone. Second, people treat attempted and completed crimes as identical in their analysis. They are not. Third, people assume a downward trend in crime means the department is doing something right, when in reality it can simply mean a change in reporting policy or staffing levels that reduced the number of logged calls. Another thing nobody talks about enough is the lag effect in clearance rates. A burglary that happens in January might not show a clearance until April because the investigation drags. If you slice the data by calendar quarter, you will make it look like clearances are spiking when they are just clearing old cases. Always anchor your time windows to the report date, not the incident date, when tracking clearance trends.

What The Data Actually Shows About Topeka
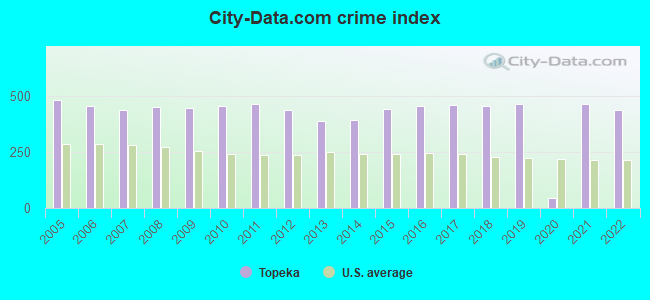
From what I have seen across multiple pulls, Topeka's patterns are fairly typical for a mid-sized Kansas city. Property crime makes up the largest share of call volume, with theft and burglary consistently topping the lists. Violent crime is concentrated in a small number of beats and does not fluctuate wildly from year to year. The seasonal variation is real but modest. Winter months tend to show slightly higher property crime, while summer months show modest upticks in disorder calls and noise complaints. What stands out is how much the non-crime service calls inflate the raw numbers. Mental health checks, welfare welfare, and civil disputes make up a significant portion of what the public interprets as crime data. If you strip those out, the underlying crime trend tells a very different story than the headline numbers suggest.
Tools I Actually Use Instead of Fancy Software
I do not need expensive dashboards for this. My toolkit is simple: a CSV file, a spreadsheet program with pivot tables, and a basic mapping utility like QGIS for spatial work. For people who want to go further, Python with pandas and geopandas will handle larger batches faster, but the learning curve is steep if you are only doing this occasionally. The spreadsheet route is slower but less prone to breaking when the source data changes format mid-project. If you want raw access, the Topeka Police Department publishes some data through its public portal, and additional records can be requested under Kansas open records statutes. Some years the data is available as a clean CSV. Other years it arrives as a PDF scan you have to manually transcribe. I have done both. The PDF versions take roughly four times longer to process and introduce transcription errors that you will spend days hunting down.
When This Approach Fails Completely
There are honest limits to what you can learn from publicly available call data. You cannot determine recidivism patterns without longitudinal tracking of individuals, which this data does not provide in a usable way. You cannot assess police conduct or use-of-force incidents from call logs alone. You cannot accurately measure unreported crime because by definition those incidents do not appear in the data. And you cannot reliably compare Topeka to another city unless both jurisdictions use the same classification standards, which they rarely do. For those questions, you need supplemental sources: court records, jail intake data, victim surveys, and independent audit reports. Call logs are a starting point, not a conclusion.
Bottom Line On How To Read These Numbers
Read the methodology before you read the headline. Check what is included and what is missing. Adjust for population and geography. Separate service calls from criminal incidents. Be skeptical of any single year because annual fluctuations are normal. And remember that the most useful insight from this data is often not the crime rate itself, but the gap between what the public assumes the data says and what the data actually shows.