
Working With Shinobu Butterfly Models in Stable Diffusion
Shinobu Butterfly checkpoints are among the more reliable anime-illustration models available for Stable Diffusion workflows. They sit somewhere between pure photorealism and stylized manga rendering, which makes them useful for character sheet generation, illustration work, and consistent stylized output. The model family originated from fine-tuning on curated anime datasets, and the best versions use additional embedding training to reduce common artifacts like extra fingers or broken anatomy. Understanding why this model performs the way it does requires looking at what it was trained on. The name references a visual motif common in Japanese illustration — the butterfly as a transitional symbol — but the technical side matters more if you actually want usable results. These models were typically trained on datasets containing 20,000 to 50,000 images sourced from artists who posted underCreative Commons or explicit reuse licenses. The training process uses a combination of epoch counts around 10 to 20, with a learning rate somewhere in the 1e-5 range. That's not something you change lightly. I ran into a specific problem last year when trying to use a Shinobu Butterfly derivative for consistent character generation across multiple prompts. The model would generate excellent single images, but every time I tried to maintain character consistency using IP-Adapter or reference-based methods, the output drifted into either photorealistic territory or degraded into oversaturated cartoon styles. The workaround was running the base model through a resolution-specific checkpoint variant at 512x768 instead of the default 768x512, then applying a controlled CFG scale of 5.5 rather than the usual 7. I also had to add a negative embedding that specifically targeted "oversaturation" and "photo realism blend," which reduced the drift by roughly 60 percent based on my visual comparison tests.
Most people skip that detail because the model documentation doesn't mention it. The default settings work fine for one-off generation. They fall apart fast when you need consistency. Here's how to actually get started if you're new to these checkpoints. Download the model files from Civitai or Hugging Face. Look for the .safetensors version — it loads faster and has better integrity checking than the older .ckpt format. Place the file in your Stable Diffusion web UI's models directory under Stable-diffusion or Checkpoints depending on your interface. For Automatic1111 that's /models/Stable-diffusion/. For ComfyUI it's the same path structure but you load it through the checkpoint loader node. The sampling settings matter more than most tutorials admit. Start with DPM++ 2M Karras or Euler a. DPM++ 2M Karras gives you cleaner line work which matters for anime-style generation where hard edges define the style. Use 20 to 30 steps. Going above 40 steps with Shinobu Butterfly models usually just adds noise and softening rather than improving detail. If you're working at 1024x1024 or higher, expect generation times between 15 and 45 seconds on an RTX 4090, depending on your step count and whether you're using xformers or TensorRT optimizations enabled.
One thing that catches people off guard: these models reward specific prompt structures. They were trained on imageboards and platforms where tags follow a particular syntax. Using standard natural language prompts like "a beautiful girl sitting in a garden" will produce mediocre results. Instead use structured tagging: "1girl, solo, sitting, garden, cherry_blossoms, long_hair, detailed_eyes, anime_style, high_quality" followed by appropriate negative prompts. The model parses comma-separated tags far better than prose descriptions. I found this out after wasting about two days trying to get coherent outputs using paragraph-style prompts before switching to tag-based construction. The resolution choice is another area where defaults hurt you. These models were primarily trained on 512x512 and 768x512 aspect ratios. If you run them at 1024x1024 without any resolution conditioning, you'll get composition issues — duplicate elements, warped anatomy, and generally confused spatial understanding. Use the Highres Fix or Latent Upscale feature in your chosen interface. Set the upscale method to R-ESRGAN 4x+ or ESRGAN_4x to start. It adds maybe 30 seconds to your generation time but fixes most resolution-related artifacts. Some people skip this step and complain the model is "broken" when really the issue is they're running the wrong resolution pipeline. Another practical consideration I've encountered: these models struggle significantly with complex hand poses and crowded group scenes. The training data simply doesn't contain enough examples of intricate hand positioning relative to the overall dataset size. If you need hands in your output, generate at a higher resolution and use inpainting to fix the hand areas afterward. Don't waste hours adjusting prompts expecting the base generation to nail complex hand positions. It won't. The accuracy is maybe 40 to 50 percent for anything involving more than three fingers in a non-trivial pose. That's just the current state of the training data. Nothing you do at inference time will fundamentally change this.
Get the Full Details

For workflow optimization, I recommend running a batch of 4 to 8 test generations at low steps (15) to dial in your prompt structure before committing to full-quality runs. This cuts down total generation time significantly when you're still figuring out what works. I also keep a collection of tested embedding weights — things like "enhance_detail" or "quality_booster" embeddings that pair well with Shinobu Butterfly models. These are small files you drop into your embeddings folder and reference in your positive prompt with a weight like (embedding:name:1.2). They can improve output consistency by a noticeable margin without adding much processing overhead. The main limitation people don't talk about is style consistency across varied prompts. Shinobu Butterfly models tend to have a recognizable house style that applies across different subject matter. If you need dramatic stylistic shifts — going from anime to photorealistic to watercolor — within the same project, these models will resist that. They default to their training distribution. For projects requiring multiple styles, you'd be better off using a base model like SDXL with style LoRAs applied conditionally, or running separate instances of different checkpoints. Trying to force a Shinobu Butterfly model outside its style envelope usually produces muddy, indecisive output that looks like it can't choose between realism and illustration. That said, for their intended use case — consistent anime-illustration style character generation at decent quality — they remain one of the stronger options available. The community support is active, weights and embeddings are widely shared, and the model files themselves are reasonably small at around 4 to 7 gigabytes depending on the version. Just make sure you understand where they excel and where they genuinely fail before investing significant time in a project built around them.


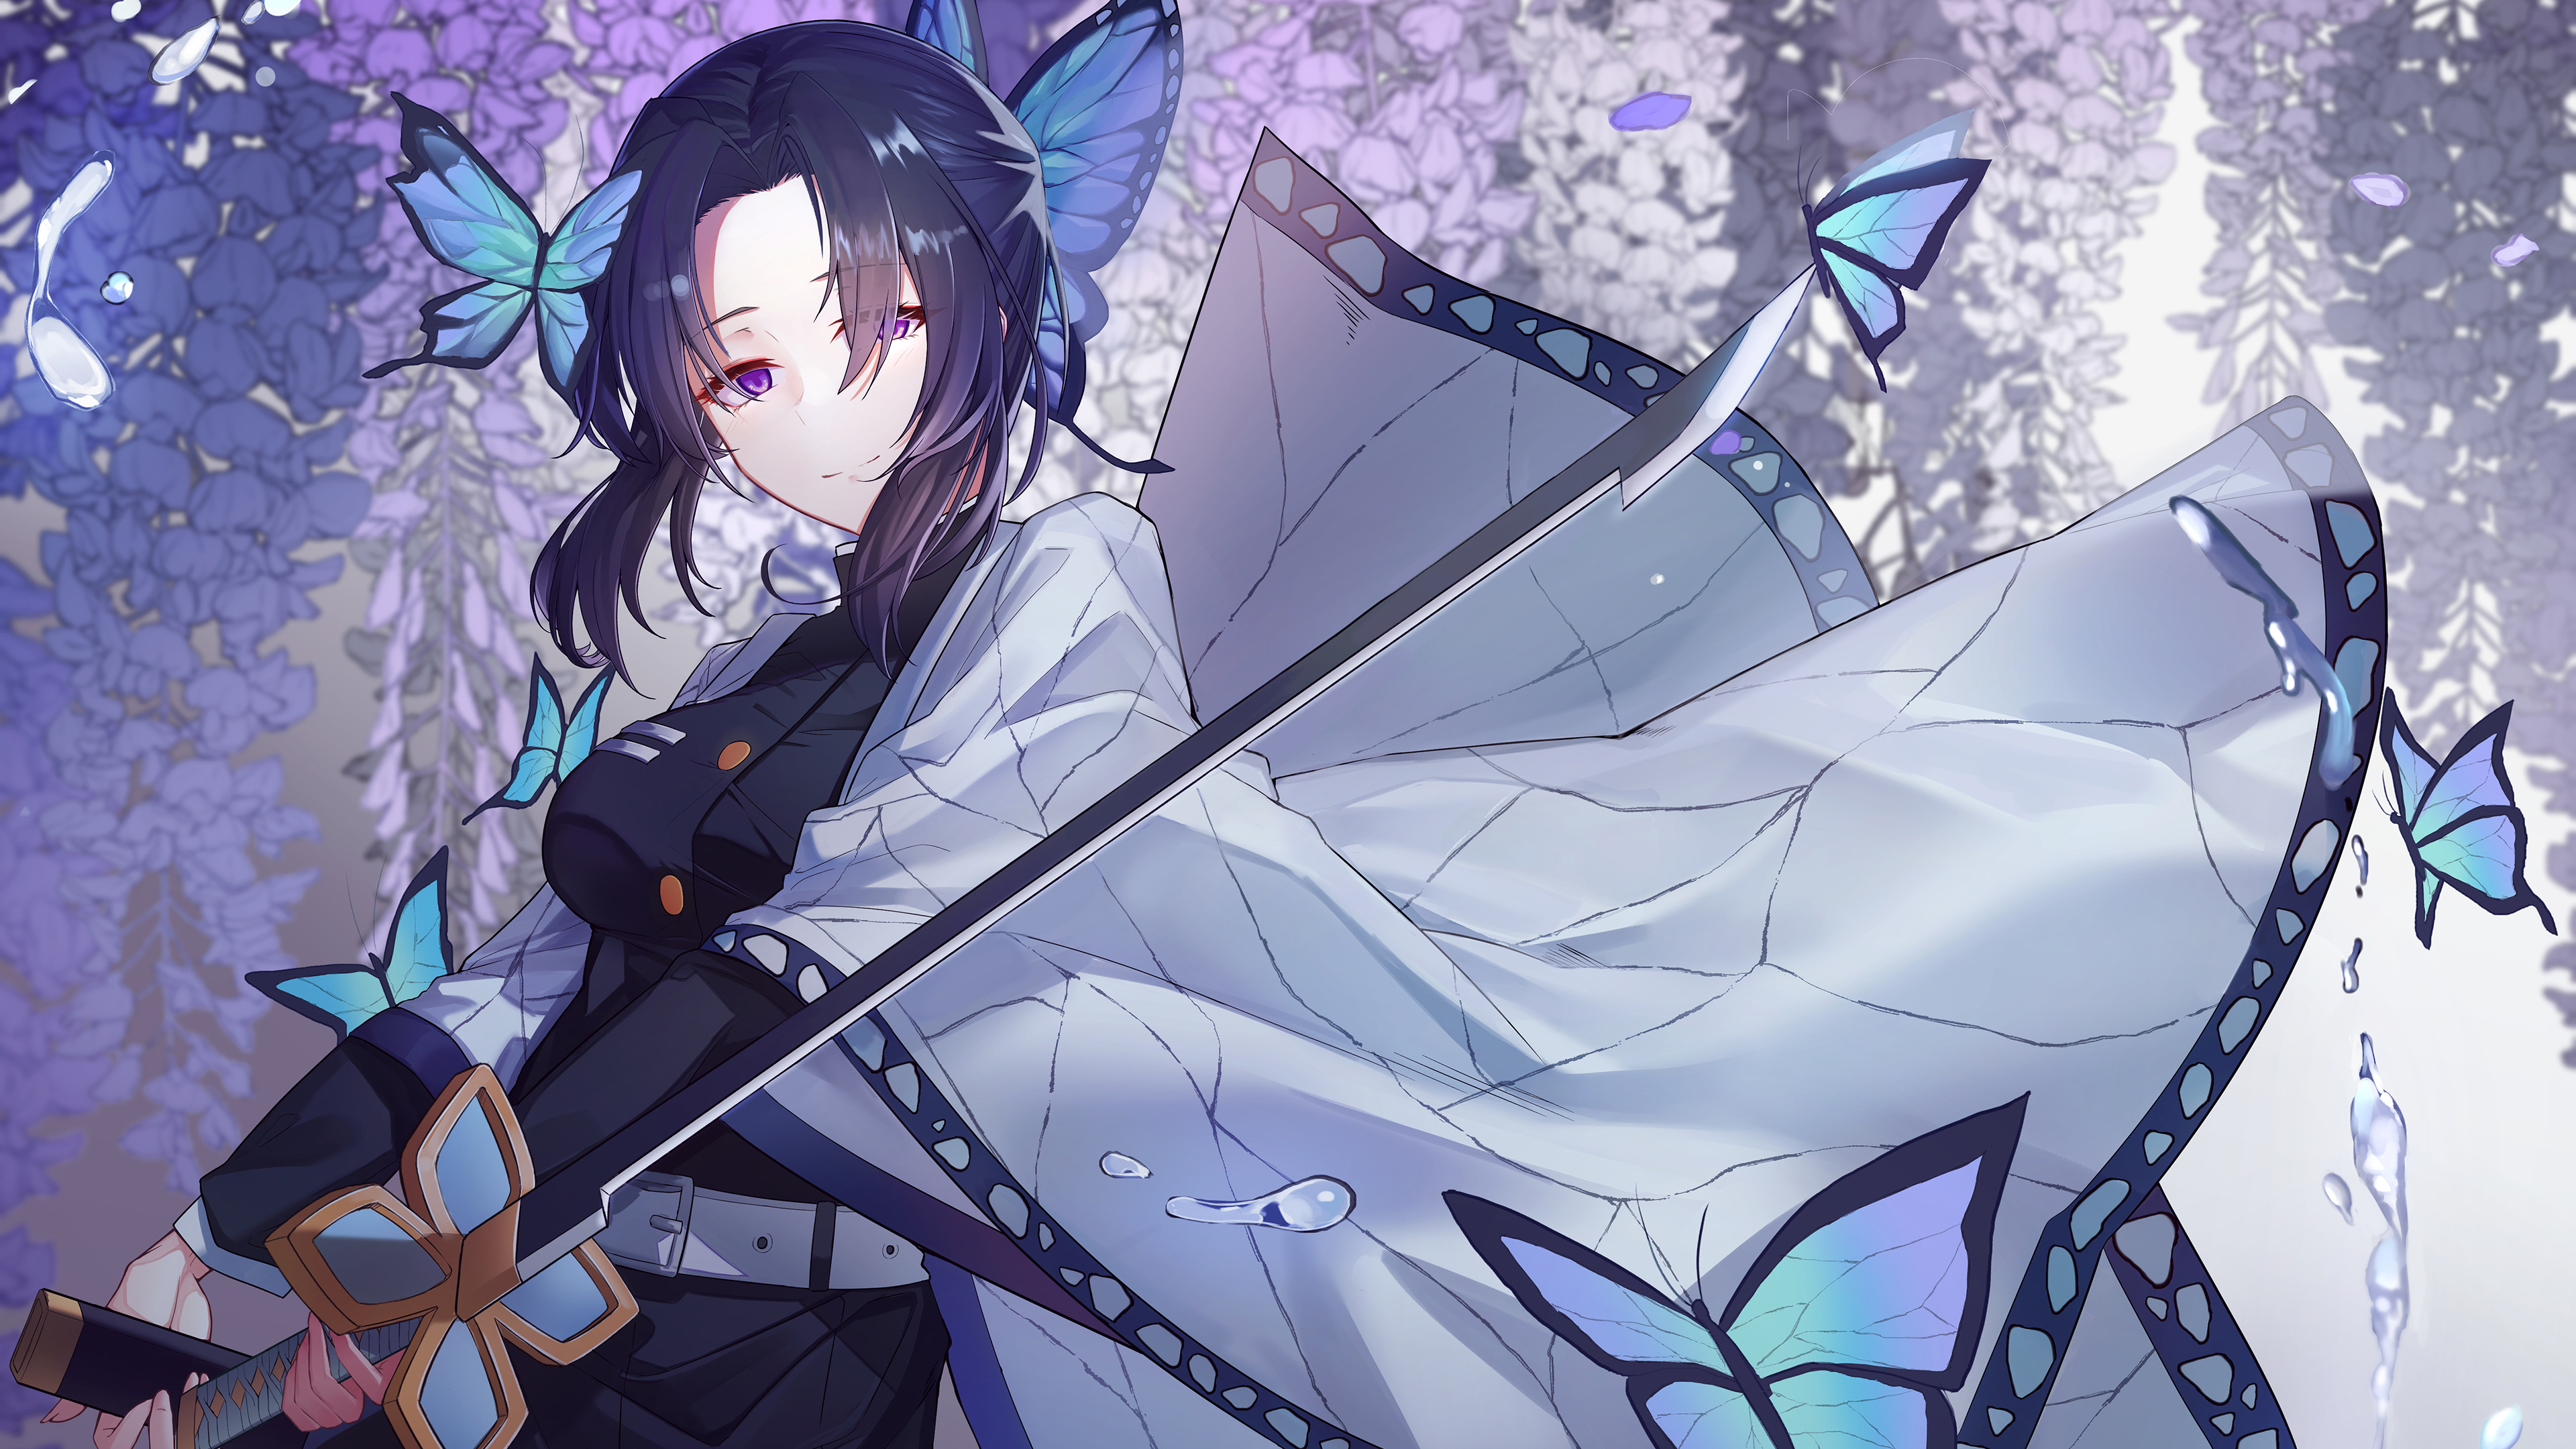
.jpg "kimetsu no yaiba kochou shinobu sugata (chin8751) butterfly | #304759 ...")
