What You Need to Know Before You Actually Use Shiftselect Atrium
Most people who come across enterprise efficiency tools get excited, then spend three weeks trying to force it into their existing stack. Shiftselect Atrium doesn't care about your excitement. It cares about data structure, API consistency, and whether you've actually mapped your workflows before you start integrating. I ran a migration for a mid-size logistics firm last year where they tried to plug Atrium into a legacy ERP without doing the preliminary architecture review. The system kept returning 422 errors on batch inserts. Turns out their SKU taxonomy had twelve different variations of the same product code, and Atrium's validation layer rejected anything that didn't match a normalized schema. We ended up writing a pre-process script that de-duped and mapped those fields before the main sync. Cost us about a day of development, saved them from a two-month support ticket spiral.
Shiftselect Atrium The Hidden Architecture Powering Enterprise Efficiency
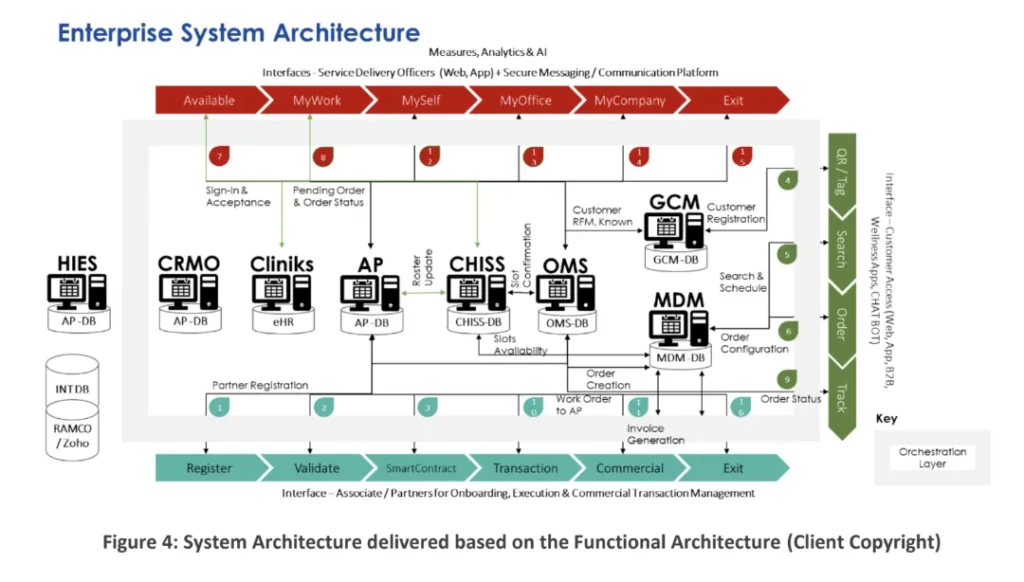
The platform isn't magic. It's a structured orchestration layer that sits between your various business systems—ERP, CRM, WMS, BI—and normalizes the data flowing between them. The "hidden" part most people miss is that it doesn't replace your existing tools. It quietly standardizes how they talk to each other. Here's what that looks like in practice. You configure your source systems, define transformation rules, set up scheduling, and let the platform handle reconciliation. The configuration time varies wildly depending on how messy your data is. Clean environments take maybe an afternoon. Messy ones? Plan a week minimum.
How to Actually Set It Up Without Losing Your Mind
Start with a current-state audit. List every system that touches operational data. Map which fields overlap. Identify where duplicate entries appear across platforms. Most teams skip this and go straight to configuring connectors, which is the fastest way to build technical debt. Once you have that map, begin with one workflow. Don't try to connect everything at once. I recommend starting with something low-stakes like expense report processing or inventory count reconciliation. Get the pipeline working end to end. Then move to the critical stuff. The API documentation is decent but assumes you already understand RESTful patterns and JSON payload structures. If you're coming from a SOAP-based background, budget extra time for the learning curve. The authentication flow uses OAuth 2.0 with tenant-level isolation, which is standard but the initial token setup gave our team a headache the first time around.
Get the Full Details

Common Pitfalls People Miss
One thing nobody warns you about: field mapping drift. As your source systems update their schemas, your Atrium mappings can silently break. You won't know until a job fails at 3 AM and you discover a date format changed from MM/DD/YYYY to ISO 8601 somewhere in your ERP. Set up monitoring alerts for mapping failures. Check them weekly at minimum. Another issue is volume estimation. Atrium handles batches well, but if you're pushing more than 50,000 records per cycle through a single connector, you'll start seeing throttling. We learned this the hard way during a quarter-end close when the finance team dumped an entire month's transactions in one run. The system processed about 30,000 records before throttling kicked in. We ended up splitting the batch by department and running them sequentially. Still took longer than it should have. There's also the licensing model to consider. It's consumption-based, which sounds reasonable until you realize that every failed validation attempt still counts against your quota. A malformed payload doesn't just error out silently. It deducts from your allocation. Make sure your error handling is solid before you go live with a high-volume pipeline.
When It Doesn't Work
Shiftselect Atrium isn't a fix for broken business processes. If your underlying workflows are inefficient, automating them just makes the inefficiency scale faster. We saw this with a manufacturing client who wanted to automate a procurement approval chain that required seven manual sign-offs. Atrium handled the automation perfectly. The process itself was the problem. They ended up cutting six of those seven approvals after implementing the tool, which was the actual win. It also struggles with unstructured data. Receipt images, free-text notes, scanned documents—those don't play nicely with Atrium's structured pipeline approach. You'll need a separate document processing layer feeding into it if your operations depend on that kind of input. For teams looking for a lighter alternative, some of our smaller clients use Zapier or Make for basic integrations and only bring in Atrium when they outgrow those platforms. That's a perfectly valid path. Don't adopt enterprise tooling because you think you should. Adopt it when your current setup is actively costing you money through errors or delays.
The platform itself is available through the Shiftselect website. Pricing is tiered based on transaction volume and connector count. I'd recommend requesting a demo with your actual data samples rather than relying on generic sandbox environments. The demo data never reflects the edge cases your real data will throw at it.