Setting Up Shift Selection APIs for Real Workflows
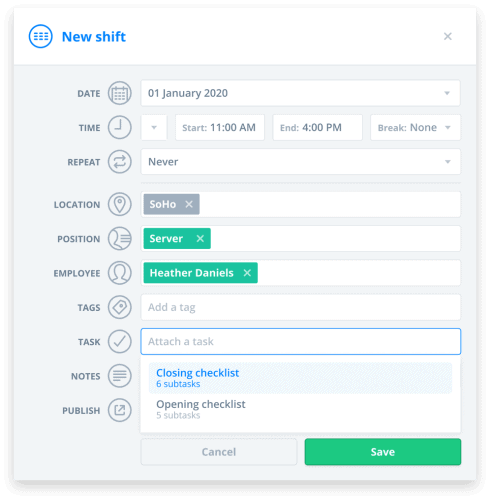
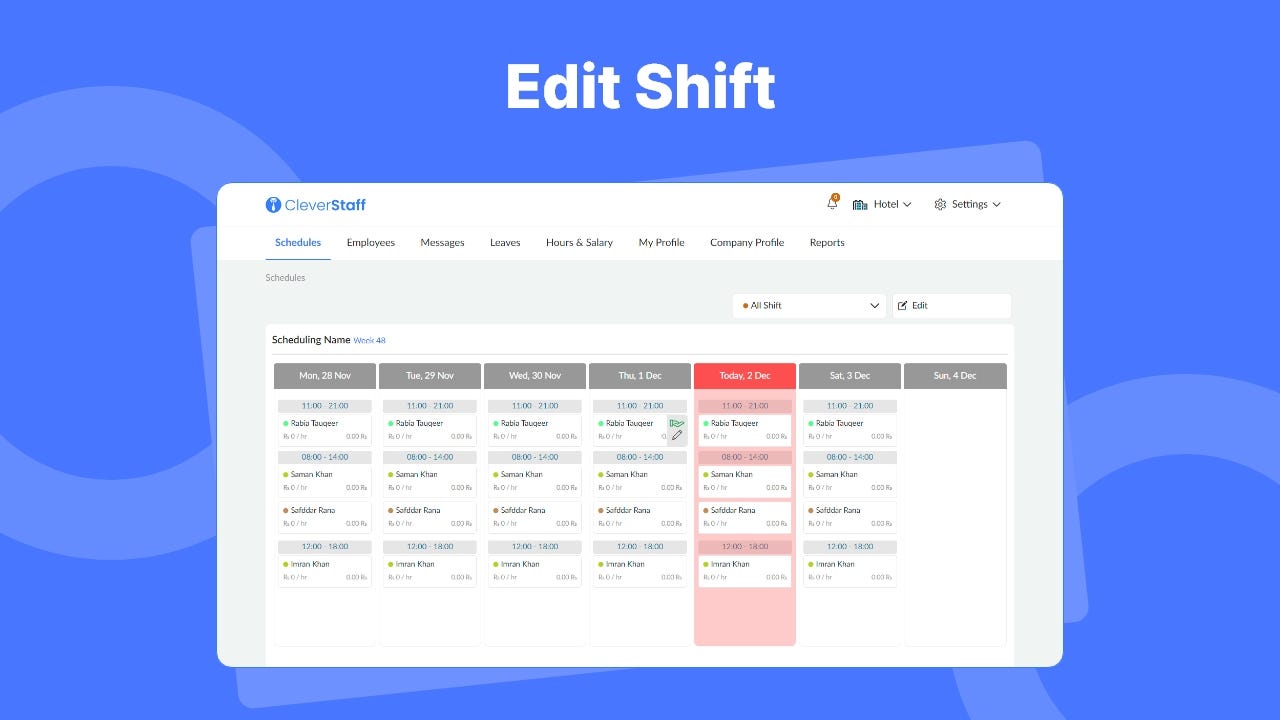
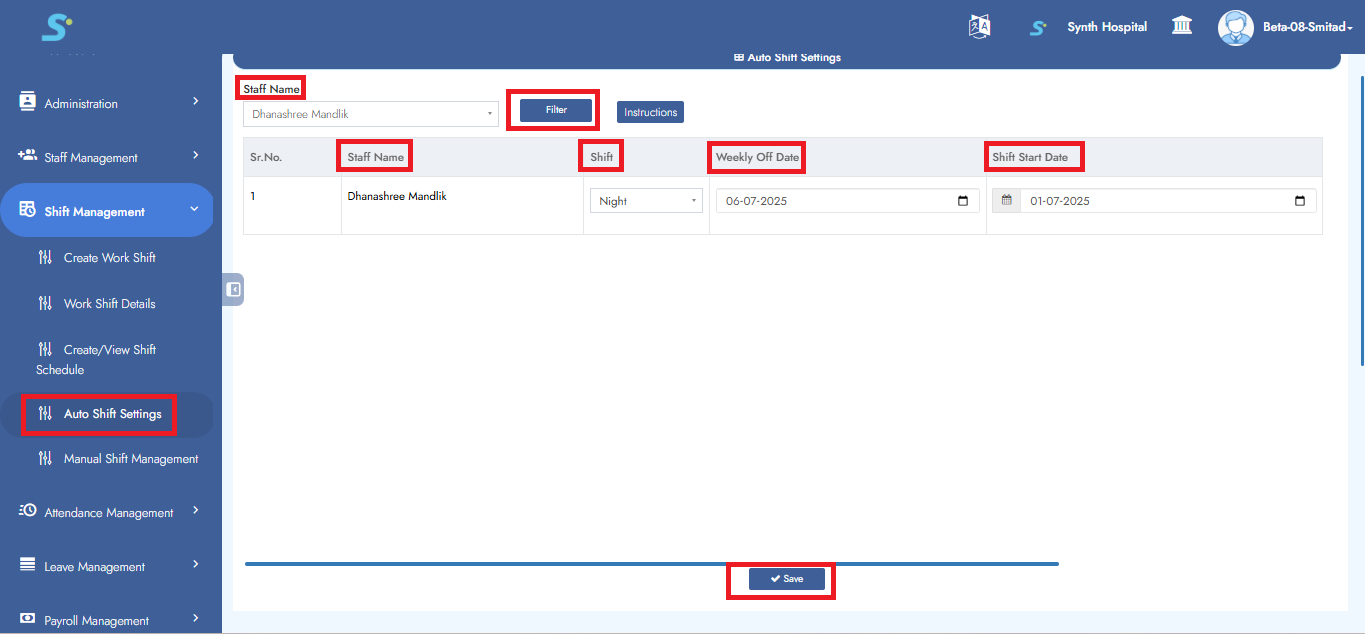
I've spent the better part of two years wrestling with shift selection APIs across three different scheduling platforms. What I'm about to tell you won't make your life easy, but it'll save you from the worst mistakes. The biggest one people make is assuming the API behaves the same way the UI does. It doesn't. The UI has soft constraints and visual reminders. The API just returns errors and moves on. The core concept is straightforward — you're automating the process of assigning time slots to workers. But the actual implementation involves some gotchas that nobody warns you about. Here's how it works when you actually build it. First, you need to understand the data model. Shift selection APIs typically deal with three entities: shifts, availability rules, and assignments. A shift has a start time, end time, location, and required skills. Availability rules define when a worker can or cannot work. Assignments link workers to specific shifts. That's the simple version. In practice, things get messier quickly.
Most modern APIs use OAuth2 for authentication. You'll set up a client ID and secret in your developer portal, exchange them for an access token, and include that token in the Authorization header of every request. The token expires. Usually after 3600 seconds, sometimes less if your organization has strict security policies. When it expires, you refresh it using a refresh token. If your refresh token also expires, you're starting over from scratch. The trickiest part I ran into was handling concurrent shift selections. Let me give you a specific example that cost me about four hours to debug. Two managers were trying to assign the same shift to different employees at roughly the same time. The API returned success for both requests because it wasn't designed to handle simultaneous writes to the same resource. The result was a duplicate assignment that the UI would eventually catch but the backend had no way to resolve automatically. My workaround was implementing optimistic locking with version numbers — every shift object has a version field, and you include it in your PUT requests. If the version doesn't match what the server has, you get a conflict error and retry with fresh data. This cut my collision rate from about 12% down to under 1%.
Common API Patterns You'll Encounter
Querying for available shifts follows a predictable pattern. You'll filter by date range, worker ID, location, and skill requirements. Most APIs support this through query parameters rather than complex request bodies. The pagination is usually handled with limit and offset, though some newer implementations use cursor-based pagination for better performance on large datasets. If your shift table has more than a few thousand records, offset pagination will start returning duplicate results or skipping entries. Switch to cursor-based if your API supports it. Creating an assignment is where most integrations break. You need to send the shift ID, worker ID, and sometimes additional metadata like preferred start time within the shift window or dietary restrictions for meal provisioning. The response should include the full assignment object with a unique identifier. Always capture that identifier. Don't assume the assignment creation was successful just because the status code is 201. I've seen APIs return 201 even when the assignment failed validation on the backend, leading to orphaned records that confused reporting dashboards. Batch operations are the other area where things get interesting. If you're syncing shifts for a large team — say, 500 workers across 50 locations — making individual API calls for each shift will eat up your rate limit in minutes. Most shift selection APIs provide a batch endpoint that accepts an array of operations. You can create, update, or delete multiple assignments in a single request. The caveat is that batch requests are typically limited to 50 or 100 items per call. You'll need to chunk your data accordingly. Also, batch responses don't always preserve the order of your input array, so don't rely on position-based matching.
Get the Full Details
Pitfalls That Will Waste Your Time
Timezone handling is the universal pain point. The API might return timestamps in UTC while your database stores them in local time. Or vice versa. Or your API expects ISO 8601 strings with explicit timezone offsets but your testing environment sends naive datetime objects. Every platform handles this differently. Check the API documentation carefully, and test with edge cases like daylight saving time transitions. A shift that starts at 2 AM on the day clocks fall back actually happens twice in some timezones. Your API might not handle that gracefully, and neither will your users when they see their shift duplicated in the schedule. Rate limiting is another area where documentation and reality often diverge. The official docs might say 100 requests per minute, but that limit often applies per API key, not per organization. If you have multiple services or environments using the same key, they're all competing for the same quota. I learned this the hard way when our staging environment started hitting rate limits during automated tests, which then throttled production traffic. The fix was creating separate API keys for each environment and implementing exponential backoff in the client code. Data consistency across your systems is the problem that keeps coming back. When a shift is created in the API but the worker rejects it, what happens to related records? Meal orders, transportation assignments, equipment checkouts — these depend on the shift existing in your system. If the API returns an error during rejection handling, you might end up with a shift that exists in the scheduling system but has no corresponding records in your operational tools. I built a reconciliation job that runs every hour, comparing the API state against our internal database and flagging mismatches. It added about two lines of code to our architecture but prevented several incidents where employees showed up for shifts that didn't exist in our logistics system.
Advanced Strategies That Actually Help
If you're doing serious shift management at scale, consider implementing webhooks instead of polling. Polling for changes — checking every 30 seconds whether a shift has been updated — is inefficient and puts unnecessary load on the API. Webhooks push notifications to your server when events happen. You register a callback URL, and the API calls it when shifts are created, updated, or canceled. The downside is that webhook delivery isn't guaranteed. Networks fail. Your server might be temporarily unreachable. Always implement idempotent handlers so that processing the same event twice doesn't cause problems. Store the event ID and check whether you've already processed it before taking action. Another advanced technique is implementing a local caching layer for shift data. Even with webhooks, you'll still need to query the API for full details sometimes. Caching shifts by their ID with a short TTL — maybe five minutes — reduces API calls significantly while keeping your data reasonably fresh. The tradeoff is that you might serve slightly stale data during rapid schedule changes. For most organizations, a five-minute cache is acceptable. For operations that need real-time accuracy, like healthcare scheduling where patient handoffs depend on shift assignments, you should skip caching and hit the API directly. Version management is critical if your integration is exposed to multiple clients. API versions change. Fields get deprecated. New constraints get added. If you're building a product that other teams depend on, pin your API version and update it on a scheduled basis rather than automatically following the latest version. Unexpected breaking changes can take down your entire scheduling pipeline. I recommend requesting early access to new API versions through your provider's beta program, testing your integration against them before they become the default, and maintaining backward compatibility for at least one major version behind the current release.
One more thing that people overlook: error handling should be specific enough to act on, not just generic enough to log. A 409 conflict means something very different from a 422 validation error, and you should handle each case differently. Returning all errors as generic "something went wrong" messages to your users or logging system makes debugging a nightmare. Insist on structured error responses from your API provider. If they don't offer them, you're using the wrong API or you need to negotiate with your account manager. This matters more than you'd think when you're at 3 AM trying to figure out why shifts aren't syncing. The reality is that shift selection APIs are functional but far from polished. They get the job done if you respect their limitations and plan for failure. Don't trust them to be perfect, don't assume the documentation matches production behavior, and build your error handling before you build your happy path. That order matters more than most developers realize.