Using Odds Shark for College Football Betting Research
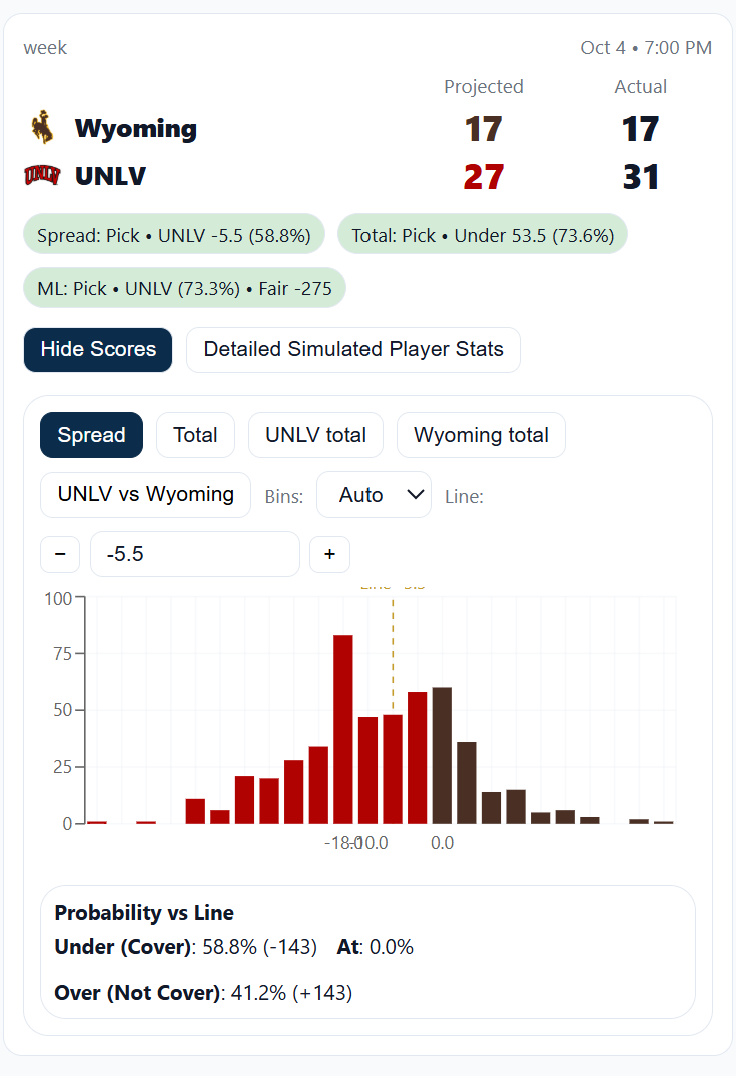
Most people treat sports betting sites as places to just glance at odds before placing a wager. That is a waste of a perfectly good data source. Odds Shark has a section dedicated to college football that can actually make your spreadsheets sharper if you know where to look. The interface is dated, the ads are obnoxious, but underneath the clutter there is raw statistical material that most bettors completely overlook. Here is how to actually use it. Odds Shark for college football aggregates line movement, betting percentages, and historical spreads from major sportsbooks. The site tracks over/unders, moneylines, and point spreads across platforms like DraftKings, FanDuel, and BetMGM. What makes it useful for spreadsheet work is the historical trend data. Instead of guessing whether a number moved for value or for market noise, you can pull the actual timeline of line movement and cross-reference it with public betting percentages. That gap between where the line actually is and where the money is going is where edge lives, or at least where you stop making obvious mistakes. I built my first college football model around 2018 and spent months manually pulling spreads from different books just to compare closing lines. Once I found Odds Shark's historical archives, that process dropped from roughly three hours a week to about twenty minutes. The tradeoff is that the site does not export data cleanly. You have to scrape it yourself or copy by hand. I wrote a simple Python script using BeautifulSoup that hits their game pages and pulls the spread, over/under, and percentage data for each week. It runs in under ten seconds and spits out a CSV that I merge into my main tracking spreadsheet. The script breaks occasionally when they redesign the page structure, which happens without warning, so factor in occasional debugging time when you build something on top of it.
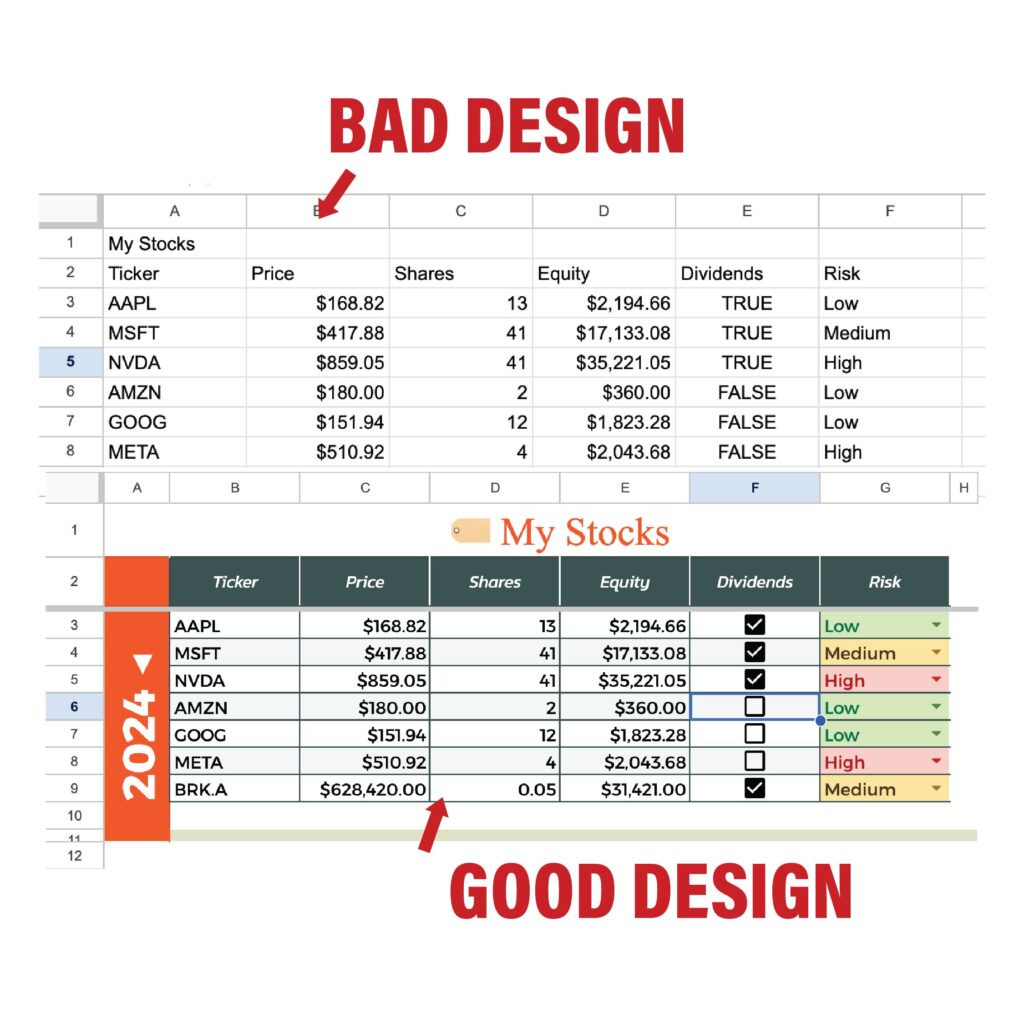
One specific edge case I ran into was when Odds Shark would show different closing numbers depending on which sportsbook you selected in the dropdown. The default view is usually the sharpest book, but I once used the wrong default for an entire season and my entire closing line database was off by half a point on average. It did not affect my model dramatically, but it made every comparison slightly unreliable. The fix was straightforward: I stopped using the dropdown entirely and hardcoded the URL to pull from a single book consistently. If you need to compare books, pull each one separately and note which source you used in a column. Transparency matters more than convenience here. Another thing most beginners miss is that the percentages shown on Odds Shark are not the same thing as true market probability. The site displays public betting percentages, which means they show where the recreational money is going, not where the smart money is. A line might move from minus 3 to minus 4 even though the majority of bets are still on the underdog side. That is a classic indicator that a few large sharp bets drove the line, not broad public action. If you are feeding this data into a spreadsheet model, label those columns clearly as public percentages, not implied probabilities. Mixing them up will corrupt your analysis. The reverse direction also happens often enough that you should watch for it. You will see heavy public money on a team, but the line stays flat or moves against that team. That tells you the oddsmakers are resisting the public influence, usually because their internal projections differ significantly from where the recreational crowd is leaning. Those resistant lines are often stronger signals than lines that move freely with public money. I use a simple conditional formatting rule in my spreadsheet: green when the line moves with the public percentage, red when it moves against it, and yellow when there is a large percentage divergence with no line movement. That third category gets extra attention because it is where the market is telling you something counterintuitive.
Odds Shark also has a trends section that shows record data like how a team performs as a home underdog in November or how certain conferences trend over the under. That raw record data is useful but dangerous without context. A team might be 8-2 straight up as a home dog this season, but if two of those wins came against FCS opponents or empty-stadium games during the pandemic, the trend means less than it appears. I always add a filter column to my spreadsheet that flags games where the sample includes non-FBS opponents or unusual circumstances. If the trend record is small or polluted, I either drop it or weight it less heavily. Never let a clean-looking streak override sample size reality. The site also publishes prop bet trends and player-specific data for college football, which is less reliable than their spread and total data. Player props fluctuate wildly based on injury reports and lineup changes that Odds Shark does not always update quickly. I use their spread and moneyline history extensively but only reference their prop data when cross-checking against other sources. Relying on their prop numbers alone would introduce noise faster than signal. There are also limitations you need to accept. Odds Shark does not cover every game or every sportsbook. Smaller conference games sometimes have sparse data or missing lines entirely. International books that offer different lines are not represented, which matters if you are looking for arbitrage opportunities across different jurisdictions. The historical data goes back several years but not infinitely, and some older seasons have incomplete records. If you need comprehensive historical data going back further than what they provide, you will need to supplement with other sources like Sports Insights or Vegas Insider archives.
Get the Full Details
Another practical bottleneck is latency. Odds lines update in real time at the sportsbooks, but Odds Shark refreshes on their own schedule. During live betting windows, the delay between when a line moves at the book and when it appears on Odds Shark can be anywhere from thirty seconds to several minutes. That is negligible for pregame analysis but meaningful if you are trying to track in-game line movement patterns. For live tracking, you would be better off connecting directly to a sportsbook API or using a service built for real-time line feeds. Odds Shark is a research and postgame analysis tool, not a live tracking platform. My recommendation for anyone trying to use this is to start with a single metric and build from there. Do not try to import every number on the page at once. Pick closing line value and public betting percentage divergence, put those two columns in your spreadsheet, and see how they correlate with your results over twenty to thirty games. Once you understand how those variables behave in your model, layer in additional data points. Adding everything at the beginning just creates noise you cannot parse. The biggest mistake I see people make is treating Odds Shark data as truth instead of treating it as one input among many. The site is a aggregator and an archive, not an oracle. The numbers there reflect what was posted and where the public bet, not what should have been bet. Use it to reduce your research time and spot market patterns, but never stop validating what you find against your own projections and other independent sources. The spreadsheet gets sharper when you treat the data as raw material rather than final answer.