What Actually Happens When You Try To Connect Multiple Data Sources
I spent about three months configuring a pipeline that pulls customer data from a CRM, stitching it together with order history from a payment processor and behavioral events from a frontend application. The architecture looked clean on paper. It broke in production within a week. That was my first lesson in how little most integration platforms actually protect you from schema drift and API rate limits. Most tools advertise themselves as plug-and-play. They aren't. The gap between the documentation and the real world is where people waste money and time. I ended up switching approaches entirely after my initial setup failed to handle timezone normalization across nine different endpoints. The data came in, but it was useless because one source was using UTC timestamps and another was sending local time with no offset metadata attached.
Seriesonlineac The Powerhouse Behind Modern Web Data Integration And Analytics
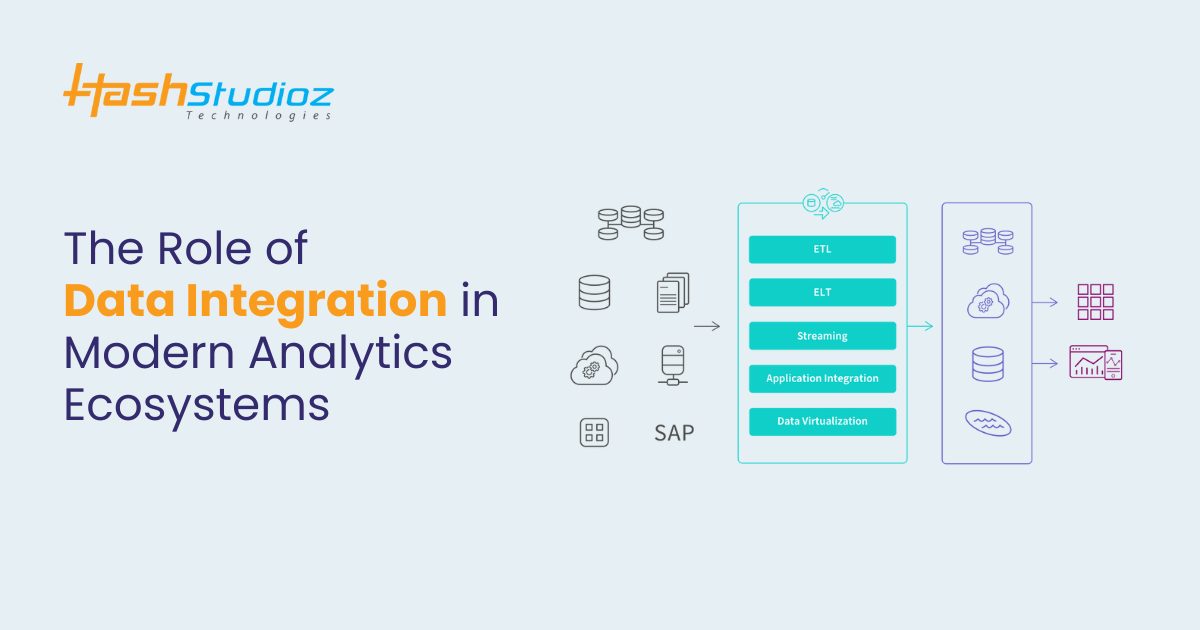
This is the platform that eventually made sense of the mess. It is not the most elegant solution you will find. It is also not the most overpriced one. The core value is that it handles the ugly parts of web data integration without making you write custom ETL scripts for every connector. Most integration work is just translating between formats that should have been compatible ten years ago. The interface runs on a visual workflow builder. You drag endpoints in, define transformation rules, and map fields. But the real capability is underneath. It has built-in handling for common issues like pagination, authentication rotation, and partial response failures. When a webhook drops half its events because the source throttled you, the platform retries and reconciles instead of silently losing data. I have seen that happen on other platforms and it always ends badly.
Setting Up Your First Integration
Start by creating a project and connecting your first data source. The platform supports REST APIs, SOAP endpoints, webhooks, and database connections. CSV and JSON file uploads work too if you are working with legacy exports from older systems. Click the Add Source button in the upper right corner and select your connection type. Most people pick REST first because it is the most common format. Enter your endpoint URL. Add headers for authentication if your API requires them. The platform stores credentials encrypted. Do not share your API keys in publicly accessible areas even though the interface makes it easy to copy them. I learned that the hard way when someone on my team pasted a production key into a Slack channel by accident. After connecting the source, you need to define the trigger. This is when the platform pulls or receives data. For APIs, you can schedule pulls on intervals. For webhooks, you set up an incoming endpoint and the platform listens. Webhooks are faster but they require a publicly reachable URL. Scheduling is simpler but introduces latency that can range from a few seconds to several minutes depending on your interval settings.
Get the Full Details
Transforming Data Without Writing Code
Once data flows in, you need to shape it before it reaches your destination. The transformation editor lets you create rules without any scripting. Add a field mapping step to rename columns. Add a filter step to remove rows that do not meet certain conditions. Add a format step to change data types or apply calculations. Here is something most tutorials miss. You can chain transformations and the platform processes them in order. But if one step fails on a row, the entire batch does not necessarily stop. By default, the platform skips failed rows and logs them. You can change this behavior in the error handling settings. I recommend keeping the default setting and reviewing error logs daily instead of stopping everything on the first failure. Silent failures cause more damage than skipped rows. One specific transformation technique that saved me repeatedly is the deduplication step. Data sources almost always send duplicate records. Orders come through once from the payment API and again from the fulfillment system. If you do not deduplicate before loading into your destination, your analytics will be wrong and you will waste storage space. Set the deduplication key to the primary identifier in your data, usually an order ID or user ID. The platform keeps the first record it sees and discards the rest.
Connecting To Destinations
The platform pushes data to databases, data warehouses, spreadsheets, and other applications. PostgreSQL, MySQL, Snowflake, BigQuery, and Redshift are all supported out of the box. For cloud storage, you can send data to S3 buckets and Google Cloud Storage. If your destination is not on the supported list, you can use a generic HTTP POST step to send data anywhere that accepts JSON payloads. When connecting to a database, you need the connection string and the target table. The platform can create the table automatically if it does not exist, but it only creates text and numeric columns. It cannot guess at your schema requirements. Define your table structure first, then let the platform write to it. I made the mistake of letting auto-create run on a project with transaction data and it turned every field into a text column. Converting those types afterward took longer than just defining the schema upfront.
Monitoring And Debugging
Data pipelines break. The platform gives you a monitoring dashboard showing run history, success rates, and error counts. Check this daily if you are running production integrations. Most issues show up as spikes in error rates or drops in row counts between runs. Here is a specific edge case I ran into. A client's e-commerce platform updated their API and changed a field name from customer_email to email_address. The integration kept running without errors because the platform was mapping to a field that now returned null. My dashboards showed zero new customer records for two days. The data was arriving, but the mapped field was empty so downstream queries filtered it out. The workaround was straightforward once I found it. I added a schema validation step early in the pipeline that checks for null values on critical fields and sends an alert when they appear. This caught the next source of issues immediately. The platform also has a data preview feature where you can inspect raw incoming records before transformations. Use it whenever you suspect a field mapping problem. It shows you exactly what the source is sending, nulls included.

Known Limitations
This platform handles most standard integration scenarios well. It struggles with high-volume streaming data. If you are processing more than a million records per hour, you will notice latency in the visual workflow builder and the retry queue can back up. For those cases, a dedicated event streaming platform like Kafka makes more sense. Seriesonlineac is not built for that scale. The scheduling precision is also limited to minute-level intervals on the standard plan. If your use case requires sub-minute updates, you will need the enterprise tier or a custom webhook setup. Another limitation is that custom scripting is restricted to the higher pricing tiers. If your transformations require complex logic that the visual editor cannot express, you will either pay more or find a different tool. Support response times are reasonable but not instant. Average response time on a support ticket is around four hours during business hours. If your pipeline breaks at 2 AM on a Saturday, you are waiting until Monday morning for a detailed response unless you have the priority support add-on.
Getting Started
You can sign up at the official website and start with the free tier, which includes five active workflows and ten thousand records per month. That is enough to test the platform and confirm it handles your data shapes correctly before committing budget. The onboarding wizard walks through creating your first pipeline in about twenty minutes if your data sources are standard REST APIs. The pricing scales with workflow count, record volume, and available features. Review the current plans on their site before upgrading. The jump from free to paid is smooth and you do not lose any existing configurations when you upgrade. Downgrades keep your workflows intact but active runs may pause if you exceed your new limits. Build your integrations slowly. Add one source at a time. Validate the output before connecting the next source. Most pipeline failures happen because people connect five sources simultaneously and then have no idea which one is causing the problem. Start simple, verify the data looks correct, then expand. The platform rewards that approach and it saves significant debugging time later.