Setting Up a Digital Textual Workflow for Jewish Sources
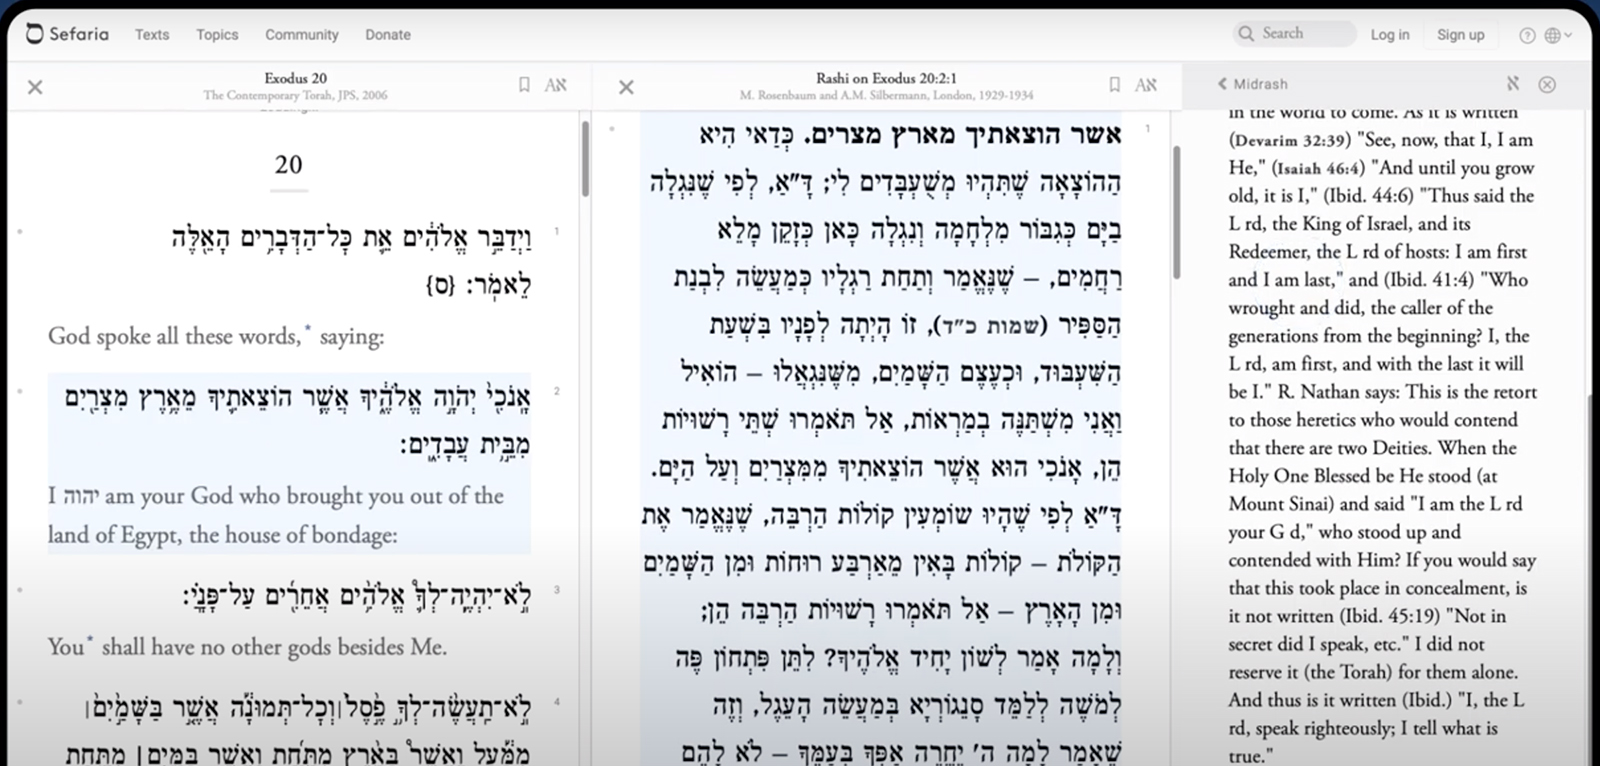
Sefer Web The Digital Revolution Reshaping How We Read Study And Preserve Jewish Texts is less a single product and more a cluster of tools, repositories, and methodologies that have quietly replaced physical volumes in most serious study environments over the last decade. I am not going to pretend this is seamless. It is functional, occasionally frustrating, and significantly faster than the alternative if you know what you are doing. At its core, digitized Jewish textual workflows rely on structured corpora. You have the Sefaria dataset, which is the largest openly licensed Hebrew and Aramaic text repository available. Then there are the commercial platforms, various university archives, and personal annotation layers. Sefer Web as a concept encompasses all of these together—the ability to query, cross-reference, annotate, and preserve across multiple sources from a single interface. The real shift happened when text became machine-readable with proper nikud, etchum (word-spacing), and canonical citation IDs. Before that, PDFs and scanned images were useful but dead ends for search and cross-referencing. Once texts got proper tagging, everything downstream changed.
How to actually use a digital textual platform
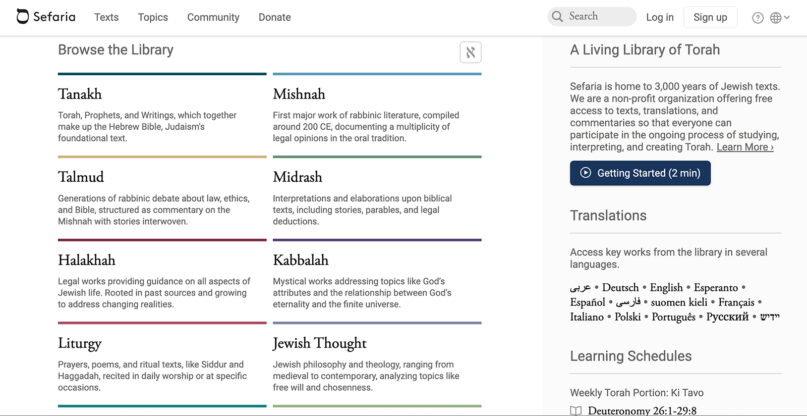
Start by picking a primary backend. Sefaria's API is free and covers Tanakh, Talmud, Rishonim, Acharonim, and much of the zoharic literature. If you need commentaries that Sefaria does not carry, you will layer in additional sources. Many people use a combination of Sefaria alongside a private Notion database or Obsidian vault for annotations. Here is a practical setup that works: Use Sefaria.org as your lookup engine. Install a browser extension like Sefaria Project or Hebray to add quick navigation. For deeper study, run a local instance of the data if you handle sensitive research or need offline access. The GitHub repository has the raw corpus, and loading it locally takes about twenty minutes on a standard machine.
I encountered a specific problem recently that exposed a real weakness in how most people approach this. I was working through a Talmudic sugya where the standard printed pagination did not match the digital text segmentation. The page breaks in digital editions follow the Vilna Shas pagination, but certain commentaries reference alternative pagination from different printings. Sefaria handles most of this, but not consistently across every commentary layer. My workaround was to write a small script that mapped the alternative pagination IDs to Sefaria's canonical references using a lookup table I built from a microfilm scan of the printed edition I had. It took about three hours to script and now runs automatically whenever I pull up those particular volumes.
Get the Full Details
Nikud, te'amim, and why most people skip it at their own risk
Most casual users turn off vocalization and cantillation marks because they slow down reading. This is a mistake if you are doing any serious textual work. Te'amim are not decoration. They encode syntactic structure, especially in Tanakh. In the Talmud, certain variant readings are preserved in the cantillation markers themselves. I have seen people miss entire textual variants because they were reading unpointed text and assuming one reading was the default. If you are studying law or narrative structure, keep te'amim enabled. Turn them off only when speed matters more than precision, and be aware of what you are losing.
Common pitfalls that beginners miss
The biggest issue is assuming digital text is authoritative. It is not. Digital editions are themselves editorial choices. Different platforms use different source manuscripts. Sefaria generally uses the Steinsaltz-aligned corpus for Talmud, but the Vienna manuscript tradition sometimes diverges on difficult passages. When two editions disagree, neither is automatically wrong. Cross-referencing at least two textual traditions before citing a digital edition is the minimum standard. Another issue is citation drift. Digital platforms assign IDs to passages, but those IDs can shift between versions. I have seen papers reference a Sefaria ID that was valid in 2021 and invalid by 2024 after a data restructure. Always record the platform version and date alongside your citation if this is going into anything permanent.
What does not work well
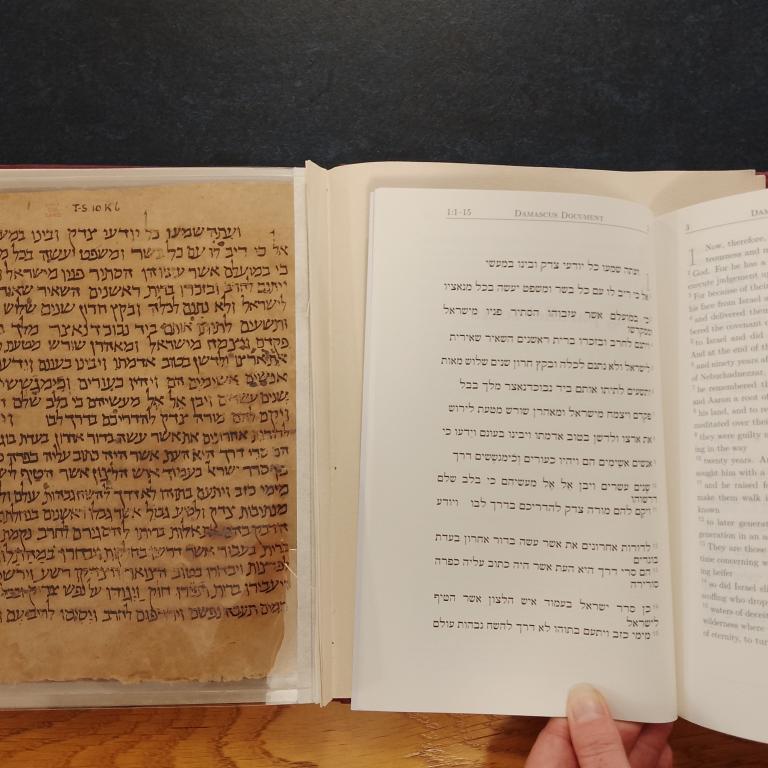
Digitized Hebrew and Aramaic textual workflows break down in several scenarios. Marginalia from handwritten manuscripts is almost never available digitally in a searchable format. If your research depends on manuscript variants from the Jewish National and University Library or the Bodleian, you are still mostly stuck with microfilm or visiting in person. The digital revolution has not reached the manuscript tier in any meaningful way. Another limitation is commentary depth. Core texts are well covered. But niche commentaries, especially regional or lesser-known Acharonim, are spotty. I ran into this when researching a specific 18th-century Galician commentary that had only ever been printed once. Sefaria did not carry it. The only digital copy was a low-resolution scan on a private collector's website with no OCR. I ended up photographing pages myself and running them through a Hebrew OCR tool, which got about sixty percent accuracy on the dense set-style printing. Workable but not elegant.
Preservation beyond the screen
Digital texts are fragile. Servers go down, platforms change licenses, APIs get deprecated. I maintain a local mirror of any corpus I use regularly. It takes extra storage and occasional sync checks, but it means my research does not depend on anyone else keeping a service running. The Sefaria data dump is large but manageable. I run a quarterly sync script that updates my local copy and flags any structural changes in the dataset. If you are doing institutional work, consider contributing annotated editions back to open repositories. The ecosystem only improves when people add to it rather than just consuming from it.
A practical daily workflow
Here is what my actual routine looks like on a typical research day. I open a digital platform, pull up the primary text, and keep a second window open with a parallel commentary. I take notes in a structured format with citations that include platform, version, and timestamp. When I find a textual variant or pagination discrepancy, I log it in a running spreadsheet rather than trying to remember it. Six months later, that spreadsheet is the only thing that saves you from reconstructing your sources from memory. The tools keep getting better. The fundamental challenges remain the same. Text is never neutral, digital or otherwise. Every encoding decision is an editorial decision. The people who understand that tend to get better results than the people who treat a digital platform as an oracle.