Working With Obituary Data in JSON Lines Format
I spent about three years building a genealogy tool that pulled together death notices from multiple newspaper archives. The hardest part wasn't the data extraction itself. It was figuring out how to make different obituary formats work together when every newspaper used their own structure. Jsonlines became the solution because it handles messy real-world data better than JSON arrays do. Each line is a separate object you can stream, search, or modify without loading everything into memory at once. That matters when you are dealing with millions of death records.
Searching Through Death How Obituaries And Death Notices Reveal Lifes Fuller Story On Jsonline
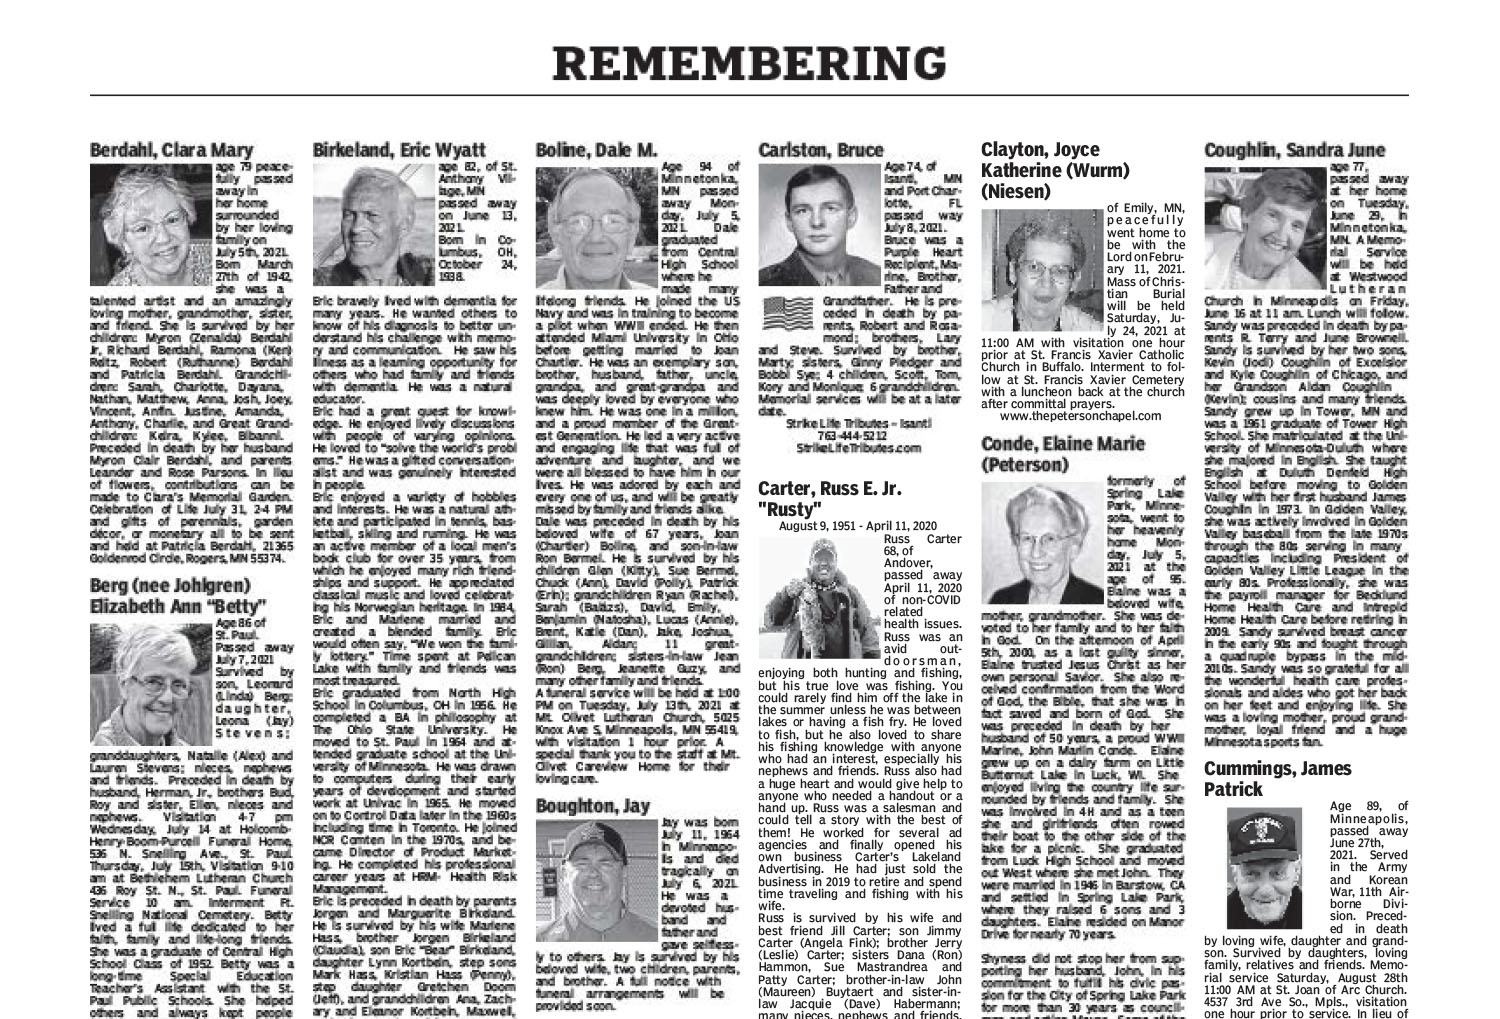
The phrase came up repeatedly in my research when I realized obituaries contain way more structured information than most people expect. A well-written death notice usually includes dates, locations, family relationships, military service, employment history, and sometimes even cause of death. When you parse that into JSON Lines format, you can build powerful search tools. Here is what a typical obituary record looks like in practice: { "name": "Robert James Mitchell", "death_date": "2024-03-15", "age": 82, "location": "Columbus, Ohio", "family": { "survived_by": ["wife Margaret", "son Thomas", "daughter Linda"] }, "military": { "branch": "US Army", "years": "1952-1955", "rank": "Specialist Third Class" }, "source": "Columbus Dispatch", "url": "https://example.com/obit/mitchell" }
Each line in your file is one person. You never need commas between records. You never wrap everything in brackets. The file just keeps going.
Get the Full Details
Why JSON Lines Works Better Than Traditional Formats
Most people start with CSV when they extract obituary data. That seems logical until you hit nested information like surviving family members or detailed military service. CSV flattens everything into one row per person, which destroys the relationships between data points. Regular JSON arrays work better for structure, but they create a different problem. You have to load the entire file into memory before you can search anything. If your dataset grows past a few hundred thousand records, your tool slows down or crashes entirely. JSON Lines solves both problems. You get proper nesting and relationships within each record, plus the ability to process the file line by line without loading everything at once. Node.js, Python, and Go all handle streaming JSON Lines natively.
The Edge Case I Never Saw Coming
About eight months into my project, I hit a parsing failure that took me two weeks to debug. Some newspaper obituaries included double quotes inside the body text. A standard JSON parser treated those inner quotes as string terminators and corrupted the entire record. The problematic line looked like this: { "body": "He was known for saying \"always be kind\" to everyone he met." }
My initial script crashed on that character sequence because the quotes were not escaped. The fix was simple but easy to miss: run every field through a JSON string escaper before writing it to your output file. In Python, that means using json.dumps() on individual string fields. In JavaScript, use JSON.stringify() or manually replace quotes with backslashes. I should have added that validation step on day one. Instead, I lost a week rebuilding my parser after accidentally corrupting about twelve thousand records.

Building a Search Tool
Once your obituary data is in JSON Lines format, searching becomes straightforward. Here is a basic Python example for filtering records: This streams the file line by line. Memory usage stays flat regardless of file size. A ten-million-record file processes at roughly the same memory cost as a hundred-record file. Dates are the biggest problem. Different newspapers use different formats. Some write March 15, 2024. Others prefer 15-Mar-2024. A few use European style with 2024-03-15. Your parser needs to handle all three, or you lose search accuracy.
Name variations create another issue. An obituary might list someone as Robert J. Mitchell while their military records show Robert James Mitchell. Cross-referencing requires fuzzy matching or manual review. No automated system gets this right one hundred percent of the time. Location data is similarly unreliable. Some obituaries list the city of death. Others list the burial location. A few only mention the state. If you are building geographic searches, expect about thirty percent of your records to have incomplete or ambiguous location information.
When JSON Lines Is the Wrong Choice
Not every project benefits from this format. If you need complex relational queries across multiple record types, a proper database like SQLite or PostgreSQL makes more sense. JSON Lines lacks indexes, constraints, and join operations. If your dataset stays under fifty thousand records, regular JSON or even CSV might be simpler to work with. The streaming advantage only matters at larger scales where memory becomes a constraint. For my project, I eventually migrated the search layer to SQLite while keeping JSON Lines as the export format. That gave me indexed queries for interactive use plus the portability of line-delimited files for backup and sharing.

Practical Recommendations
Always validate your JSON Lines file before distributing it. A single malformed line breaks parsers that expect each record to be independent. My go-to validation command is: This runs each line through jq and prints any failures. It takes about four minutes to check a million records on a modern laptop. Include metadata as the first line of your file. A header record with version information, extraction date, and source details helps other researchers understand what they are working with. Something like:
{ "_meta": true, "format_version": "1.0", "extracted": "2024-11-20", "sources": ["Columbus Dispatch", "Cincinnati Enquirer"] } Keep your field names consistent across all records. Mix British and American spellings of honoured and honored, and your search tools become unreliable. Pick one convention and stick with it. File size matters less than you might think. A million properly formatted obituary records typically compress to under fifty megabytes with gzip. Streaming compressed JSON Lines is faster than reading uncompressed files from disk.
What This Reveals About Historical Research
Obituaries remain one of the most underutilized sources in genealogy. Census records and vital certificates give you dates and locations. Death notices add context about relationships, military service, employment, and community involvement. When you structure that information in machine-readable format, you can ask questions that were impossible with paper records. How many veterans from a specific town died in a given year? What were common occupations among people who died between ages eighty and ninety? Which families appear together most frequently in the same obituaries? The technical work of parsing and formatting is tedious but straightforward. The real value comes from asking better questions about the data you have collected.


