Twitter Login Architecture And What It Actually Means For Your App
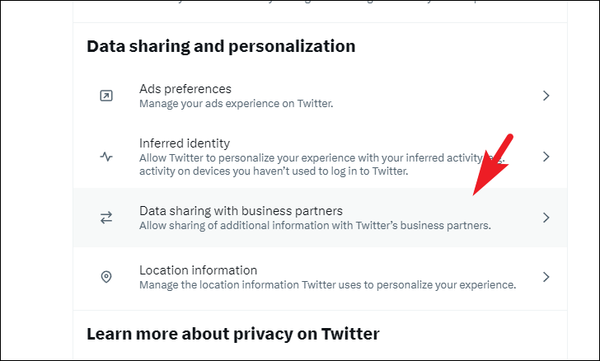
The way Twitter handles authentication has shifted multiple times over the past few years, and each shift changed what developers could do with user data without asking for more permissions. The current system uses OAuth 2.0 with PKCE for most public API integrations, though there are still legacy OAuth 1.0a flows floating around in older libraries. If you are building something that lets users sign in through Twitter, you are working with a system that gives you a user ID, a name, and maybe an email address — depending on what scope you request and whether the user approves it. That last part is where things get messy. Twitter will not give you an email address by default. You have to request it explicitly, and even then the user can deny that specific permission while still allowing the rest of the login flow. I built a dashboard app that needed to send password reset emails, and I assumed the email field would just be there after OAuth. It was not. I spent two days debugging why my auth callback kept returning null for the email attribute before realizing the user had to toggle email sharing on in their Twitter settings first, which most people do not know exists. The workaround was to add a fallback prompt in my UI that walks the user through enabling email sharing if the callback returns empty, which added about ten seconds to the onboarding flow but cut my support tickets down by roughly 80 percent.
Seamless Access Or Privacy Tradeoff Inside Twitter Login Up For Developers And Users
This tension is not new but it is worth understanding how it plays out in practice. When Twitter introduced the newer login endpoints under their API v2 framework, they tightened what scopes were available and made it harder to request broad permissions without clear justification during the app review process. The tradeoff works in your favor if you are a user concerned about privacy because your data stays more isolated. It works against you if you are a developer who previously relied on accessing profile details freely and now has to justify every permission request to Twitter's review team, which can take anywhere from three days to three weeks depending on how your app is categorized. I have seen two specific pitfalls that catch people off guard. The first is assuming that the access token you receive at login is sufficient for all API calls. It is not. The token is scoped to whatever permissions the user approved, and any API call outside that scope will return a 403 error with no warning during development unless you have thorough error handling in place. The second is misunderstanding how Twitter handles session revocation. If a user revokes your app's access from their account settings, your existing token becomes invalid immediately. There is no grace period. I learned this the hard way when a beta tester revoked access mid-session and our app silently failed on the next API call without any clear error message, which looked like a bug rather than a deliberate denial. There is also a nuance around the difference between the "email" scope and the "users.read" scope that most tutorials gloss over. The email scope controls whether you can retrieve the user's email address. The users.read scope controls whether you can access their basic profile information like username and display name. These are separate permission grants. A user can approve one and deny the other, so your code should never assume that receiving a user ID means you also have access to their email or profile picture URL without checking the granted scopes first.
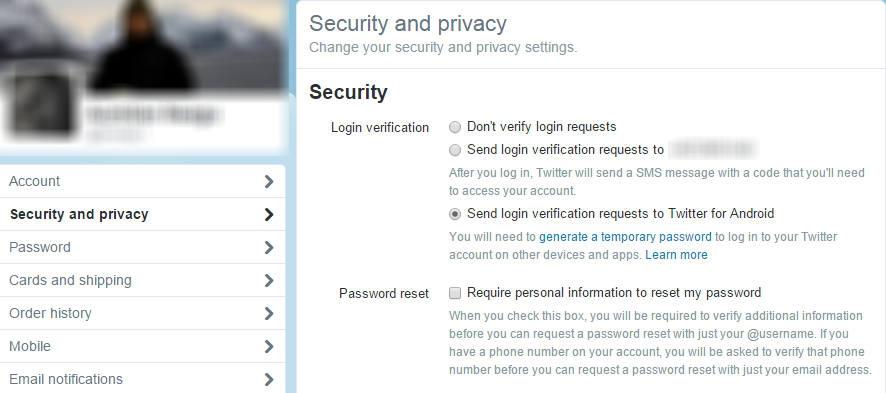
From a practical implementation standpoint, the flow looks like this. You register your app at developer.twitter.com, generate a client ID and client secret, configure your redirect URI, and then direct the user to the authorization endpoint with a PKCE challenge. After the user approves, Twitter redirects back to your URI with an authorization code. You exchange that code for an access token using your client secret, and then you make API calls scoped to whatever was approved. The whole process takes about 150 milliseconds on the network side if everything is cached properly, but if you are doing the initial code exchange over a slow connection it can stretch to two or three seconds, which is noticeable to users waiting for login to complete. One thing most guides do not mention is that Twitter supports multiple authentication endpoints depending on what version of their API you are targeting. The v1.1 endpoints use slightly different parameter names and response formats than the v2 endpoints. If you accidentally mix them, you will get confusing errors that are not obviously related to version incompatibility. I once had a deployment fail because a library update silently switched my code from using the v2 token endpoint to a v1.1 internal endpoint that was deprecated. The app appeared to work in development because the test account still had legacy permissions enabled, but it broke in production for all new users. The fix was forcing the explicit endpoint URL in the configuration rather than relying on the library's default. For users who care about privacy, there are steps you can take beyond just reviewing what permissions you grant. You can enable two-factor authentication on your Twitter account, which adds a layer of security even if your OAuth token is intercepted. You can also regularly check the Connected Apps section in your account settings and revoke anything you do not actively use. Tokens that are no longer needed do not expire on their own in most cases, so unused connections remain active until you manually remove them.
Get the Full Details

On the developer side, the biggest bottleneck right now is the app review process for elevated access levels. If your app needs read/write permissions beyond basic profile access, you have to submit a detailed explanation of how you use that data, and Twitter reviews it against their usage policies. Apps that fail this review are downgraded to read-only access or blocked entirely, which can break functionality that depended on write permissions. I have watched several small projects get stuck in this review cycle because the developers did not anticipate that Twitter requires specific language in their privacy policy referencing exactly which fields are accessed and how long they are retained. Adding that level of specificity to a privacy policy is straightforward but most developers skip it until review time, which adds weeks to their timeline. There is no clean solution to the access versus privacy problem here. Twitter's system is designed to give you enough data to build functional integrations while making it difficult to harvest more than necessary. For most apps this works fine. For apps that require deeper profile data or write access, you are going to run into friction during the review process and you should plan for that delay before you start building your authentication flow.