How Live Scoring Feeds Actually Work for College Football
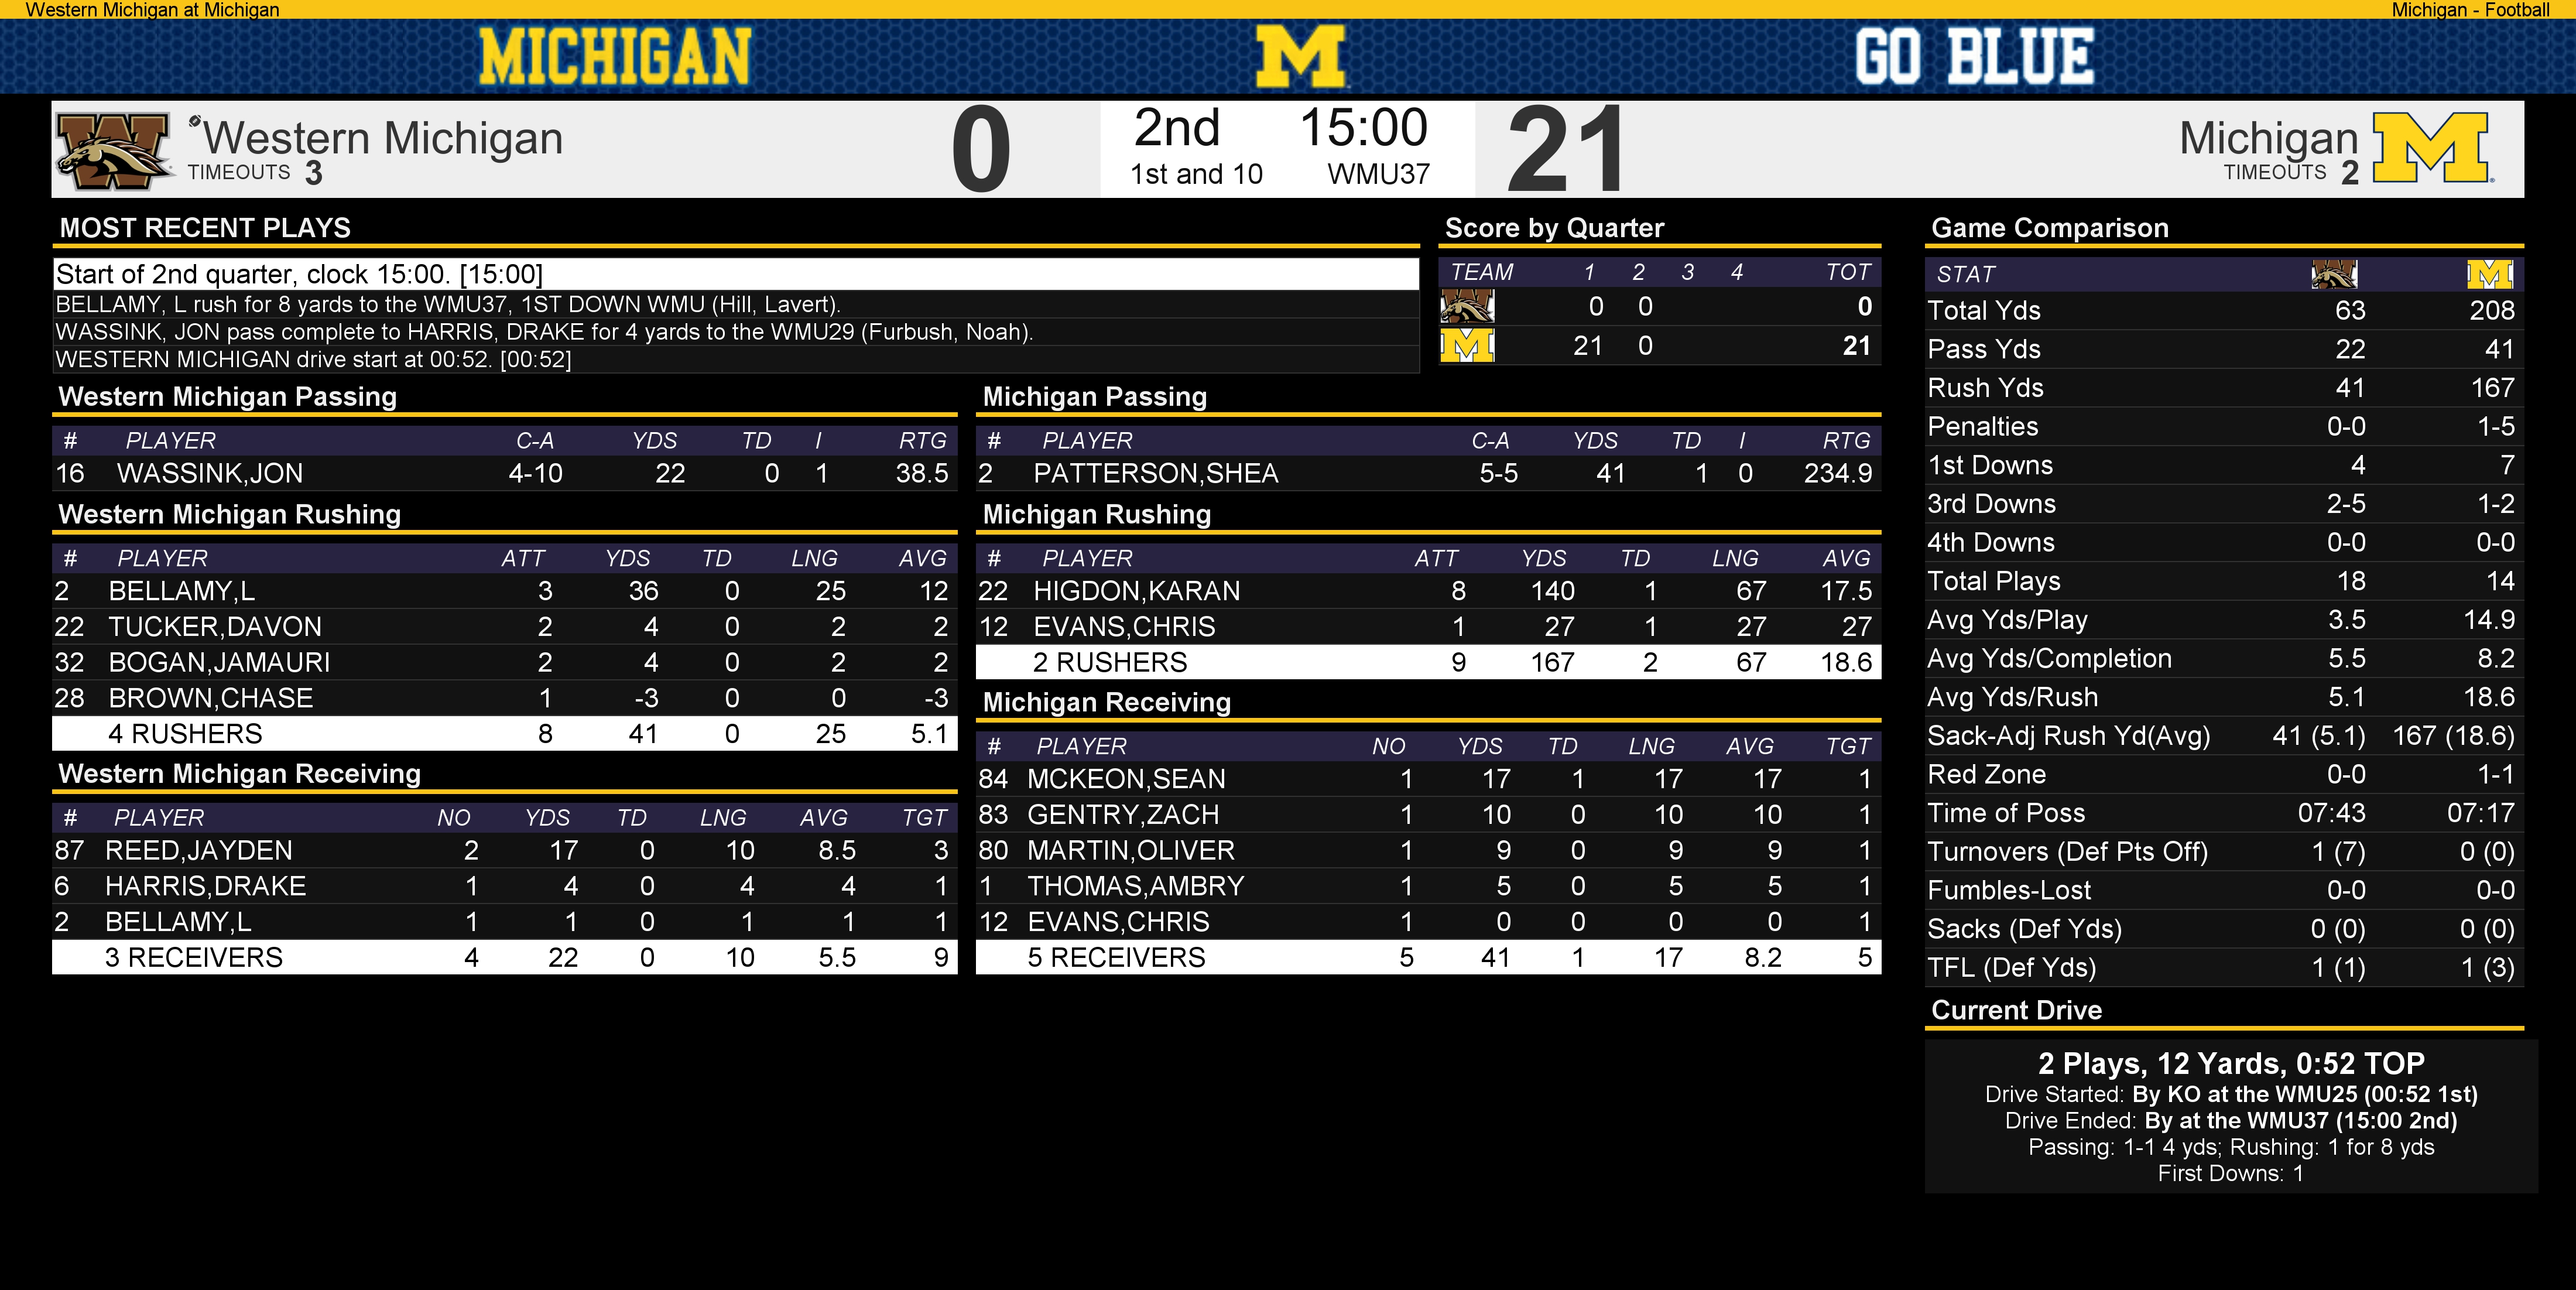
The modern college football scoring ecosystem runs on a mix of automated play-by-play feeds and human-reviewed corrections. When you're tracking Michigan's season in real time, you're usually getting data from providers like SportRadar, Stats Perform, or the NCAA's own data pipeline. These services feed into apps, websites, and betting markets. The raw input is a play-by-play log — down, distance, field position, result of each snap — and the output is whatever score or stat line you see on your screen. Most of the delays and inaccuracies people complain about come from latency between the stadium and the feed, or from conflicting source data that hasn't been reconciled yet. I spent several years managing data pipelines for sports analytics products, and the thing nobody tells you about real-time football scoring is that the raw feed is almost never wrong in a catastrophic way. The problems are in the details. A missed penalty flag doesn't get logged immediately. A coaching challenge can retroactively flip a completion into an incompletion. Turnovers get reclassified after video review. Each of these events has a delay between when it happens on the field and when it appears in the feed, and that gap is where the analysis gets messy.
Score For Michigan Football Realtime Updates Analysis And The Data Behind The Wolverines Season
If you want to build something that actually tracks Michigan's games with useful depth, you need to understand the data stack first. Here's what a working pipeline looks like in practice. You start with a provider API — SportRadar's NFL/college feed is the industry standard, though it costs money. Free alternatives exist through services like API-Football or the NCAA's public stats page, but they're slower and less complete. You pull the play-by-play JSON or XML, parse it into your database, and then calculate derived metrics on top of the raw plays. That's where the actual analysis lives. For Michigan specifically, the public box scores from the Big Ten network and the team's official site give you basic counting stats. What they don't give you is the granular play-level data you need for anything beyond surface-level analysis. That's where you'd look at Next Gen Stats-style tracking data, which isn't freely available for college football the way it is for the NFL. The workaround most people end up using is combining ESPN's play-by-play API with PFF's college data if they have a subscription, then merging the two datasets by game and play ID. It's clunky but it works. One edge case I ran into repeatedly was handling intra-game roster moves and injury designations. Michigan will announce a player is out mid-game, but the scoring feed often lags 30 to 90 seconds behind the official update. If you're building an alert system or a live odds model, that lag matters. My solution was to set up a secondary watch on the Big Ten's official injury report feed and cross-reference it against the scoring API. When the two disagree, I flagged the play as uncertain rather than accepting either source blindly. It added about ten minutes of processing time per game but cut my false-positive rate dramatically.
The counter-intuitive part of real-time football data is that more data points don't always mean better analysis. Play-by-play feeds for college games typically contain between 120 and 180 rows per game, each representing a single snap. That's manageable. But once you start layering in situational splits — third down, red zone, two-minute drill — the dataset balloons and the signal-to-noise ratio drops unless you have clean filtering logic. I've seen people build models that looked great in backtests and collapse in live games because they didn't account for context switching. A passing efficiency metric calculated over the first half of a game means something different when the opponent is resting its starters in the fourth quarter. Another thing beginners consistently miss is the difference between expected and actual outcomes in the data. Michigan might lose a game 17-10 but outperform their expected points differential by six points, which suggests they got unlucky rather than outplayed. Most scoring update apps just show the final result. Anyone doing real analysis needs to track EPA (expected points added) and WPA (win probability added) at the play level. Without those, you're just reading the scoreboard, not understanding the game. There are real limitations to this approach. The biggest one is that no free or cheap data source gives you complete, low-latency college football coverage. SportRadar's feed is comprehensive but expensive. The NCAA's own data is free but only covers nationally televised games through their partners. If you're tracking every Michigan game regardless of broadcast status, you'll find gaps. Another limitation is that college football doesn't have the same tracking infrastructure as the NFL — no chipped balls or player motion capture at scale — so advanced metrics like yards after contact or tightness of coverage simply aren't available in the public domain for most games.
Get the Full Details

If you're just looking to follow Michigan's season with decent updates, the most practical setup I've found is combining the ESPN app for live scoring with a custom script that pulls play-by-play data from their API and calculates situational splits. It takes maybe an hour to set up initially and then runs passively. For anything more serious, you'd need a paid provider API and some kind of database backend to store and query the data efficiently. There's no shortcut around the infrastructure cost if you want reliability.