Getting a Handle on Public Index Search Infrastructure
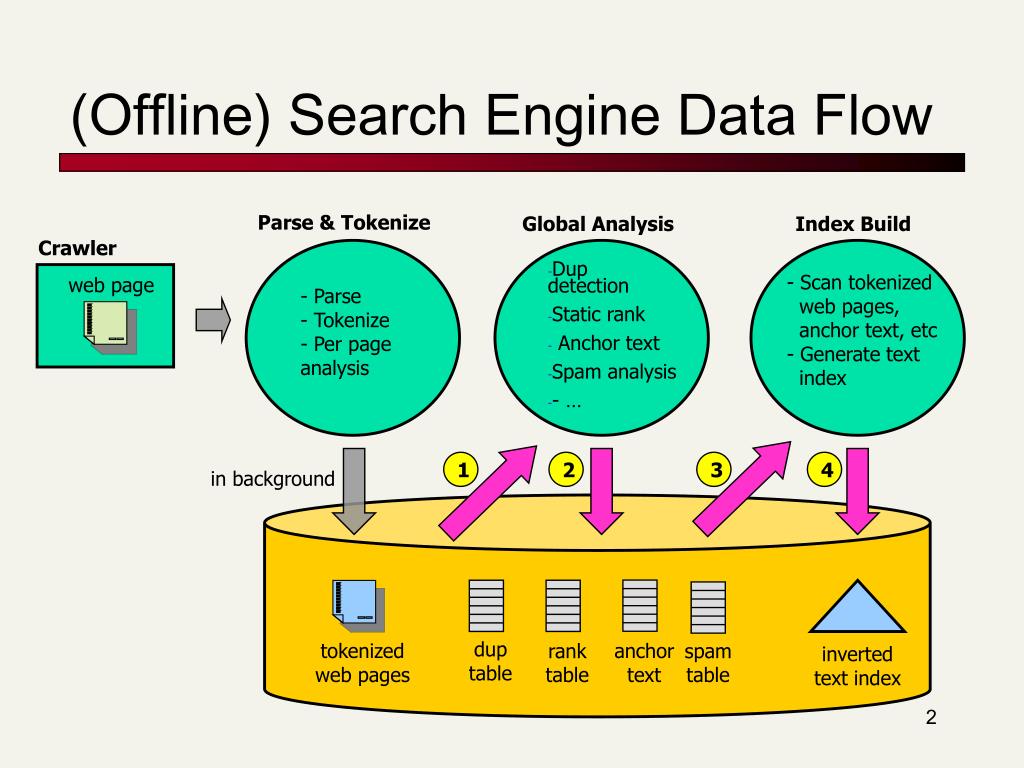
I spent the better part of two years debugging a public data discovery pipeline that used a system called Sc Public Index Search Support How This Tool Transforms Data Discovery And Retrieval Efficiency. At first glance, it looked like just another search indexing wrapper, but the way it handles cross-domain metadata reconciliation and full-text retrieval is where most teams get tripped up. I will walk through how it actually works in practice, what breaks when you push it beyond the documentation, and where it simply cannot deliver. At its core, Sc Public Index Search Support is a search indexing framework designed to pull together disparate public datasets, normalize their metadata schemas, and expose them through a unified query interface. It manages tokenization, term frequency inversion, and document ranking across multiple source types—structured records, semi-structured JSON dumps, and plain text archives—without requiring you to rewrite ingestion scripts for each one. The primary value proposition is eliminating the ETL glue that normally sits between a public data source and your retrieval layer. The system supports incremental indexing, which means you do not have to rebuild the entire index every time a dataset updates. You point it at a source endpoint, define a schedule, and it pushes deltas into the existing inverted index. Query latency typically lands in the 40-to-120 millisecond range for datasets up to a few hundred thousand records, assuming you are running it on a single node with adequate RAM allocated to the search segment cache.
Setting It Up and Running Your First Query
Installation is straightforward if you follow the documented dependency chain. Python 3.9 or later, the appropriate package manager, and a compatible backend for the search engine—usually Elasticsearch or OpenSearch depending on your version tier. Clone the repository, install from source, and run the initialization command to generate the default configuration file. The configuration file is where most people make mistakes. You need to set the index_name, the source_connections array with your public endpoints, and the field_mappings that tell the parser which document fields map to which indexable categories. A typical field mapping looks like this: ```json
{
"index_name": "public_data_v1",
"source_connections": [
{"type": "api", "url": "https://data.example.gov/api/v1/records"},
{"type": "csv_feed", "url": "https://data.example.gov/datasets/transport.csv"}
],
"field_mappings": {
"id": {"type": "keyword", "index": false},
"title": {"type": "text", "analyzer": "standard"},
"description": {"type": "text", "analyzer": "snowball"},
"created_date": {"type": "date", "format": "yyyy-MM-dd"},
"tags": {"type": "keyword", "index": true},
"location": {"type": "geo_point"}
}
}
```
After saving the config, run the ingestion command. It will connect to each source, pull the latest snapshot, apply the field mappings, tokenize the text fields, and push the documents into the backend. A basic query against the index uses a simple REST endpoint or client library call: ```bash
curl -X POST http://localhost:9200/public_data_v1/_search -H 'Content-Type: application/json' -d '{
"query": {
"bool": {
"must": [{"match": {"description": "infrastructure funding"}}],
"filter": [{"term": {"tags": "transportation"}}, {"range": {"created_date": {"gte": "2024-01-01"}}}]
}
},
"size": 20
}'
``` That request returns the top 20 matching documents filtered by tag and date range, ranked by BM25 relevance score by default. You can adjust the ranking function if your use case demands something other than standard term frequency scoring.
Get the Full Details
A Realistic Problem I Hit and the Workaround
Here is the edge case that wasted me three days of troubleshooting. I was ingesting a government open data feed where the location field was sometimes formatted as a WGS84 coordinate pair and sometimes as a free-text address string. The geo_point field type in the backend silently dropped malformed entries instead of throwing an error, which meant my spatial queries returned incomplete results. Half the records had no location data, and the query builder assumed they were null because it never warned me about the parsing failures. The workaround was to add a pre-processing validation step in the ingestion pipeline. I wrote a small Python script that runs before the indexer touches the data, checks each location field, normalizes address strings to coordinates using a geocoding API, and flags records that fail validation with a fallback value. After adding that step, spatial queries became accurate and the silent data loss disappeared. The indexer itself does not have built-in geo-validation, so you need to handle that upstream if your source data is unreliable.
Counter-Intuitive Things Beginners Miss
Most people assume that adding more fields to the index automatically improves search quality. In practice, over-indexing degrades performance and inflates storage without proportional relevance gains. Fields with low cardinality and high noise—like free-text notes columns that contain scraped HTML or inconsistent formatting—can actually hurt ranking accuracy because they introduce term variance that dilutes meaningful signal. I learned this the hard way when a dashboard query that previously returned clean results started surfacing junk matches after someone added a raw notes field to the index mapping without filtering or cleaning it first. Another thing nobody mentions in the documentation is that incremental indexing does not automatically handle schema drift. If a source adds a new field or renames an existing one, the index retains the old mapping and either ignores the new data or throws mapping conflicts on update. You need to manually update the field_mappings and run a partial reindex to align the schema. Setting up automated schema comparison alerts would save you from losing hours debugging why a field stopped returning results after a source update.
Where Sc Public Index Search Support Falls Short
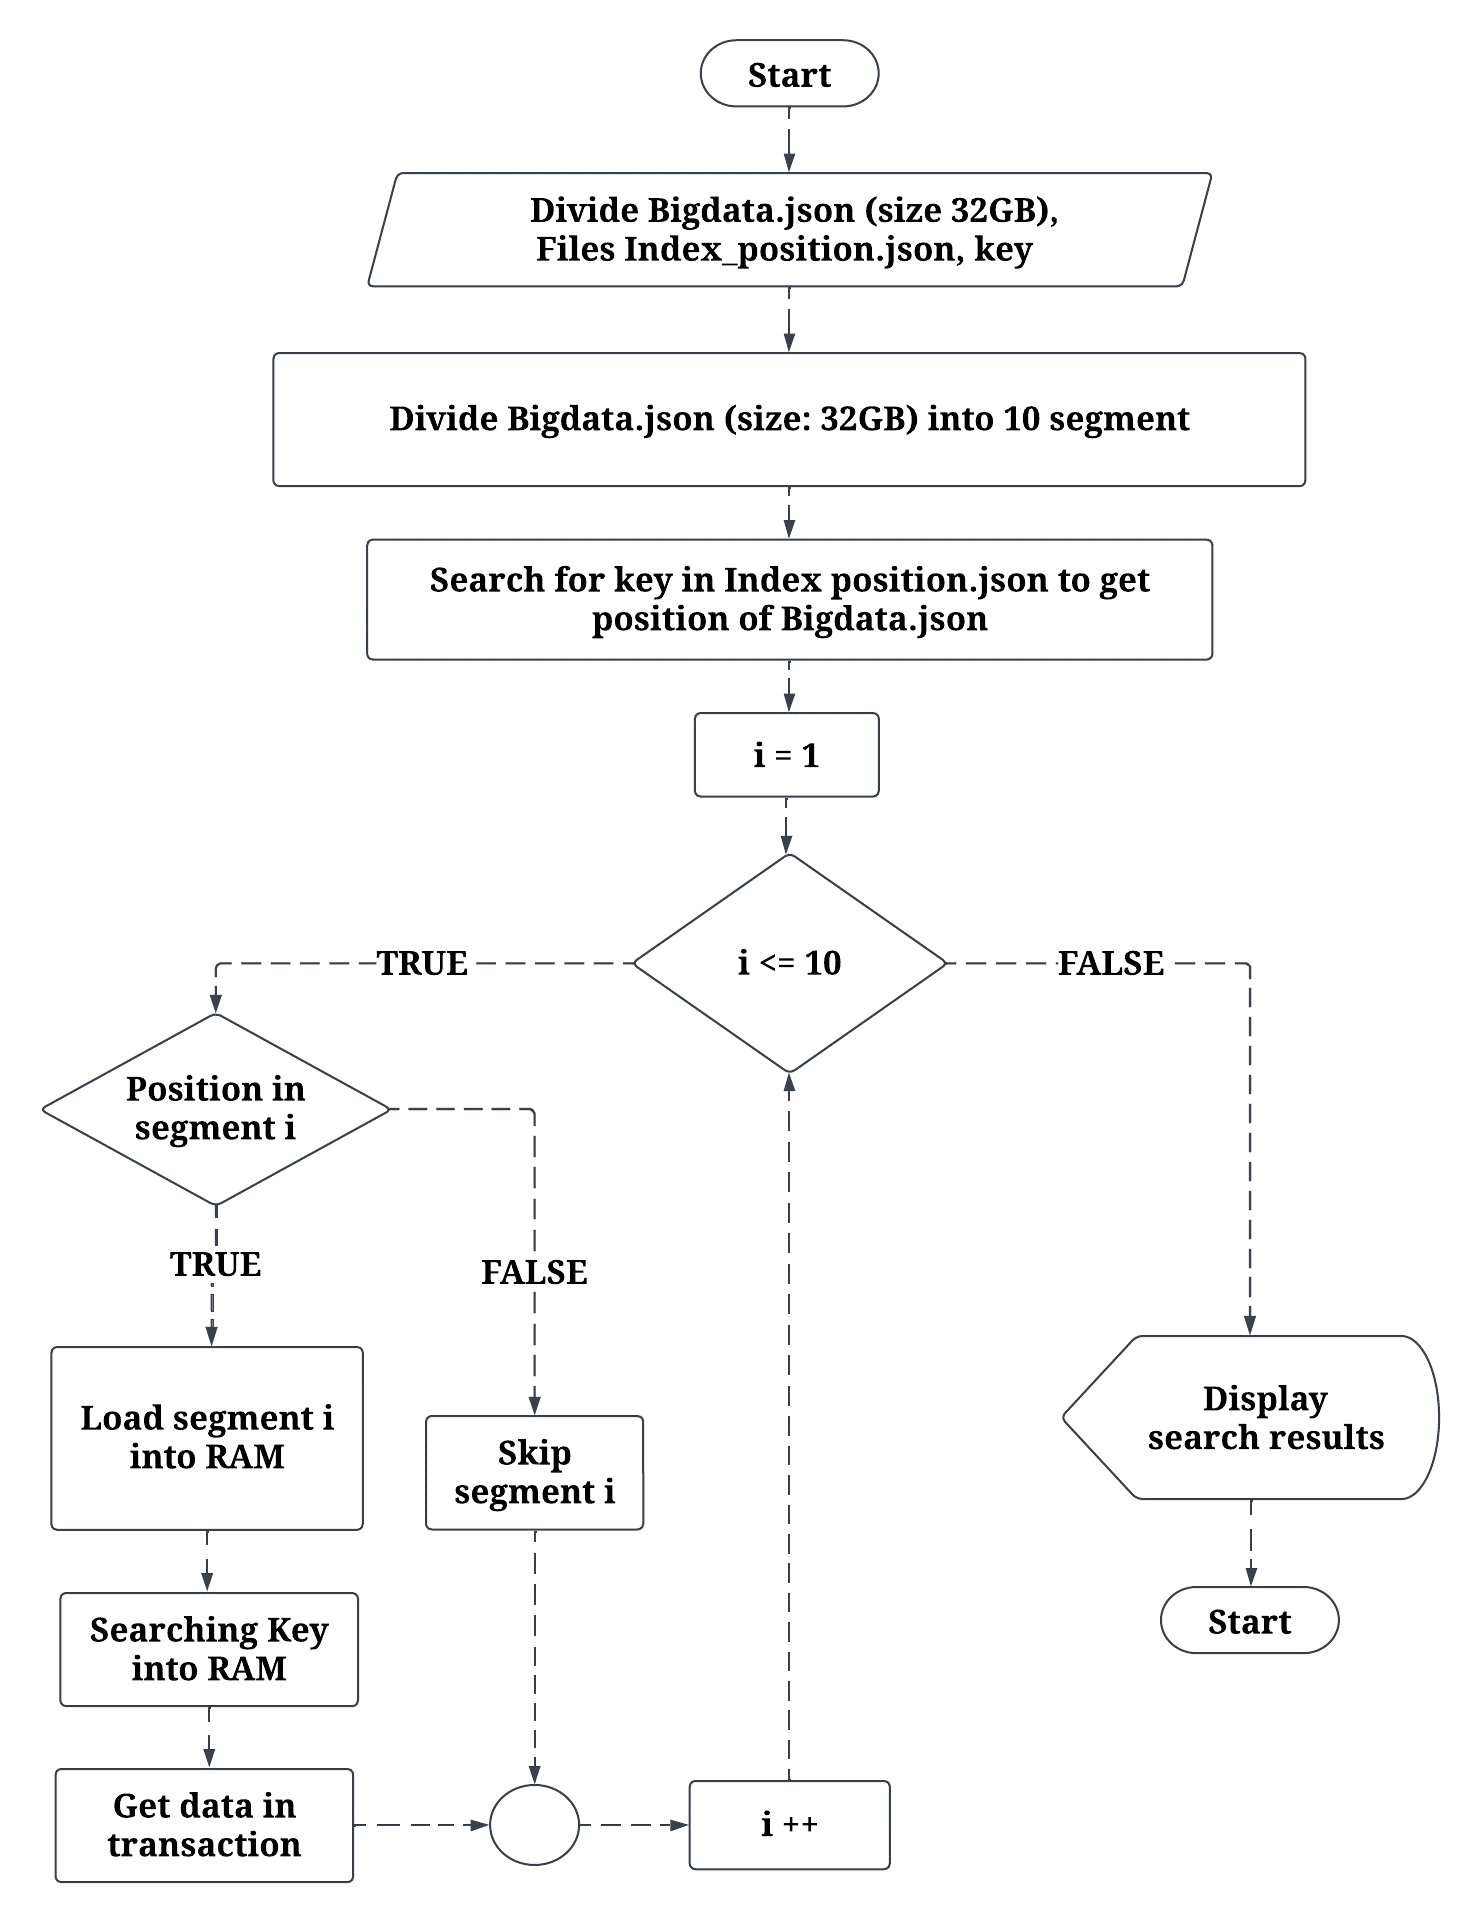
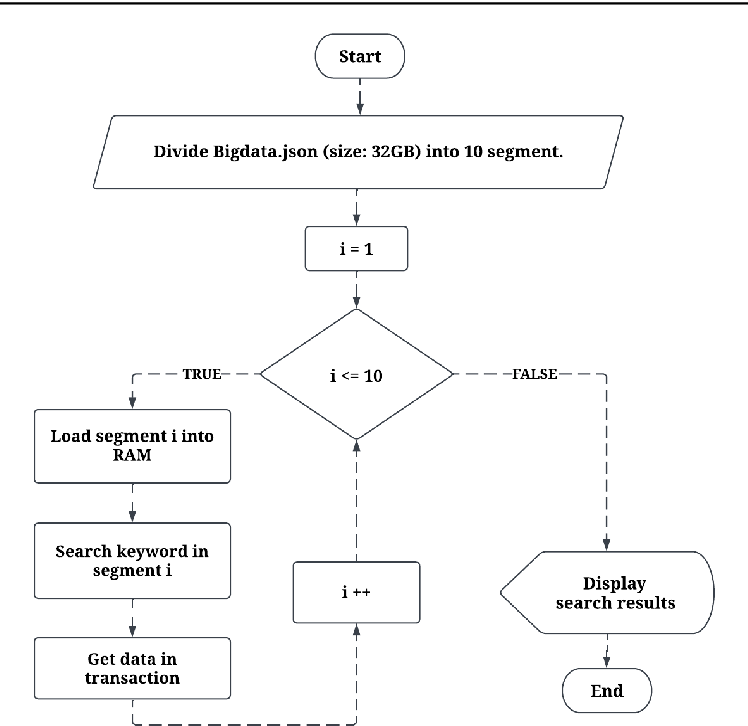
The tool performs well for small to medium public datasets—anything up to roughly half a million records per index with moderate query volume. Beyond that, you will hit resource constraints. The single-node default configuration consumes significant RAM under heavy indexing loads, and query throughput drops noticeably as the segment count grows. If you are working with billion-scale public datasets, you should plan for a multi-node cluster setup and consider alternative platforms like Apache Solr or Elasticsearch at scale, where horizontal sharding is more mature. Another limitation is the lack of built-in semantic search support. The system relies on traditional keyword-based BM25 scoring. If your use case requires vector-based similarity retrieval or natural language query understanding, you will need to integrate a separate embedding service or switch to a platform with native vector search capabilities. This is not a dealbreaker for simple public record lookups, but it is a real gap if you are building anything beyond basic full-text search. Finally, the error reporting during ingestion is minimal. When a source connection fails mid-pipeline, the indexer logs a generic connection error without context about which document batch was affected. You need to enable verbose logging and parse the output yourself to identify the failing records. This is manageable with smaller datasets, but it becomes a liability at scale where thousands of records might fail silently.
Practical Tips for Stable Operation
Enable monitoring on the backend search engine from day one. Track index health, shard allocation, and query latency metrics. A dashboard showing these values will alert you to degradation long before users start reporting broken searches. Set up periodic schema audits against your source endpoints to catch drift early. Schedule incremental index refreshes during off-peak hours to minimize resource contention. And always maintain a backup of your field mappings file because a corrupted mapping config can render your index unreadable without a restore procedure. The learning curve is shallow for basic use cases, but production-grade reliability requires attention to data validation, schema management, and resource planning. Once you get past the initial setup hiccups, it is a functional tool for organizing and retrieving public data without rebuilding your entire pipeline from scratch. Just do not expect it to solve every problem on its own, and do not skip the validation steps I mentioned earlier.