The Actual Mechanics of Converting Pages to Static Documents
Most people think saving a webpage as a PDF is just pressing Ctrl+P and hitting print. It works sometimes. It also breaks everything constantly. The render engine that generates a PDF from a browser is not the same engine that displays the page. That mismatch is where every problem starts.
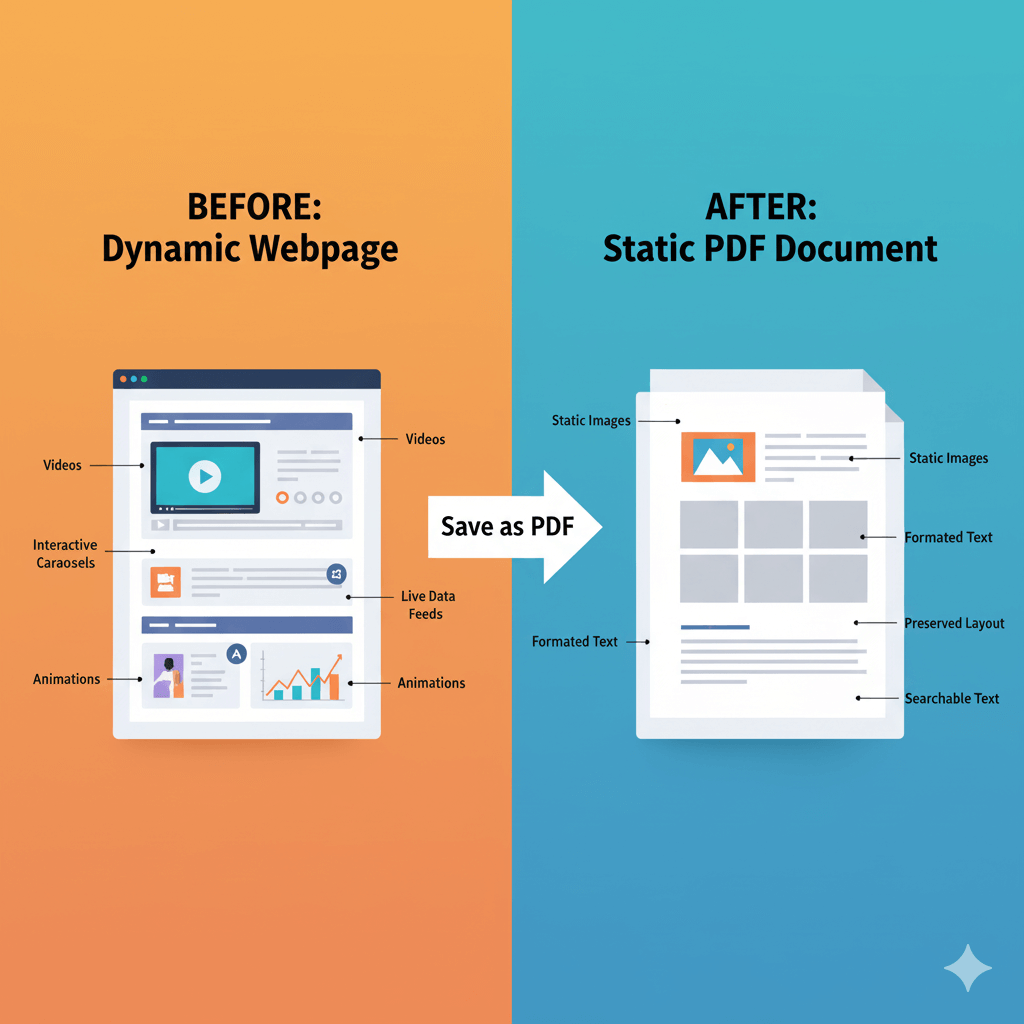
When you hit Print to PDF in Chrome, the browser takes a snapshot of the DOM at that moment. It does not execute JavaScript after the save begins. Any lazy-loaded images, infinite scroll content, or dynamically injected elements simply disappear from the output. I learned this the hard way last year when I tried to archive a research paper hosted on a university portal. The PDF came out missing the entire figures section because the images were loaded via Intersection Observer after the initial render. Took me forty minutes to build a script that forced the images to load before capturing.
Save Webpage As PDF The Definitive Guide To Archiving Sharing And Preserving Digital Content
For those situations, third-party tools become necessary.
PDFmyURL handles JavaScript rendering on their servers, but you are uploading sensitive content to a third party.
DocRaptor is similar and charges per conversion after a free tier.
Web2PDF.Convert is a free online option that works reasonably well for non-sensitive pages, though it injects watermarks on higher-resolution outputs. For local batch processing,
Node Webshot combined with a Puppeteer script gives you full control. I wrote a straightforward implementation that loops through a list of URLs, waits for specific selectors to appear, and captures full-page PDFs. Ran it against two hundred URLs in about twelve minutes on a decent machine. Not fast, but reliable.
File Size And Quality Tradeoffs
A raw screenshot of a page and a text-selectable PDF are completely different beasts. Browser print functions generate text-selectable PDFs by default, which are smaller and searchable. Some third-party services default to image-based PDFs instead, which means your file sizes can jump from 500 kilobytes to fifteen megabytes for the same page. That matters when you are archiving hundreds of documents.
Image quality settings inside the print dialog control resolution. Chrome defaults to medium DPI output. If you need publication quality, switching to high DPI roughly triples the file size but preserves fine text detail and sharpens embedded images.
Compression happens automatically in modern PDFs through algorithms like FlateDecode for text and JPEG for images. You cannot easily override this through the browser print function, but tools like
Ghostscript can compress already-created PDFs down significantly. Running a saved PDF through Ghostscript with appropriate compression flags typically reduces size by forty to sixty percent without visible quality loss on standard displays.
Archiving For The Long Term
A PDF is not a permanent archive format by itself. The specification has evolved, and a PDF created in 2024 may not open in software from twenty years ago. Using
PDF/A compliance solves this. PDF/A is an ISO-standardized subset that embeds all fonts, colors, and metadata into the file itself, making it self-contained and viewable regardless of external resources.
Most browsers do not export to PDF/A natively. You need a post-processing step.
Apester PDF/A Converter is a free desktop tool that checks compliance and converts existing PDFs.
Adobe Acrobat Pro does it during export with a single checkbox. For batch operations on a budget,
PDFarranger combined with command-line Ghostscript scripts works adequately.
Metadata is also critical for preservation. Title, author, creation date, and subject fields matter when you are building a retrievable collection. Browser print functions do not populate these. PDF editing tools like
PDF-XChange Editor or command-line
ExifTool can add metadata in bulk. I set up a pipeline where each archived PDF gets tagged with its source URL, capture date, and original page title automatically.
Legal And Technical Gotchas
Not everything you can access you can legally archive. Copyright applies regardless of whether the content is behind a login wall. Personal archival for reference is generally defensible under fair use in many jurisdictions, but redistribution or commercial use of archived PDFs crosses a line quickly. I have seen people get in trouble for archiving and redistributing paywalled journal articles, which is obviously wrong, but even openly published content can have reuse restrictions you should check.
Technical restrictions like DRM-protected content, CAPTCHA walls, and terms of service prohibiting automated downloading are real barriers. Bypassing them with scripts may violate the site's ToS and potentially computer fraud statutes depending on your jurisdiction. Proceed with appropriate caution.
Some sites implement anti-scraping measures that detect and block headless browser requests. User-agent rotation helps somewhat, but sophisticated implementations track behavioral patterns and session fingerprints. This is why manual exports through a regular browser session often remain the most reliable method for fragile or heavily protected content.
A Practical Workflow That Actually Works
For one-off conversions of simple pages, the browser print function with background graphics enabled and headers footers disabled handles the job adequately in under thirty seconds.
For JavaScript-heavy or dynamic sites, use Puppeteer with a waitUntil networkidle option and a selector-based readiness check. The script I referenced earlier took about an hour to set up initially but now runs without intervention for routine archiving tasks.
For long-term archival with compliance requirements, export to standard PDF first through whatever method works, then run it through a PDF/A converter and metadata tagging step. This three-stage pipeline produces archival-quality files consistently.
The whole process depends entirely on your source material. Static HTML pages convert cleanly ninety-five percent of the time without any tooling adjustments. Dynamic applications require the additional steps and scripting overhead described above. Understanding which category your content falls into before you start saves significant time compared to trying to force a one-size-fits-all approach.