San Antonio Crime Data and What It Actually Tells You
Most people open a crime map looking for a simple answer — which neighborhoods are safe and which aren't. The problem is that crime maps don't give clean answers. They give points on a grid, timestamps, and offense codes that require some effort to interpret correctly. I spent two years working with San Antonio crime data through a public safety analytics project. We built dashboards, pulled APIs, and sat through meetings where city planners wanted the data to say something it never could. Here's what I learned about using crime maps practically, not theoretically.
San Antonio Crime Map Navigating Safety In The Alamo City With Datadriven Insights
The San Antonio Police Department publishes crime incident data through their OpenData portal. You can access it at data.sanantonio.gov. The dataset includes GPS coordinates for each reported incident, offense type, date and time stamps, and the corresponding police district. Data typically lags 72 hours behind actual incidents, which matters more than most people realize. Pulling the data is straightforward. You can download CSV files directly, query via their REST API with filters for date range, offense category, and location. The API has rate limits of about 1000 requests per hour on the free tier. If you're pulling historical data going back several years, you'll hit that limit fast. My workaround was writing a Python script that chunked queries by month and added a five-second delay between requests. The full three-year pull took about 40 minutes instead of timing out after the first attempt. The fields you'll work with are standard: Incident ID, Offense Code, Location Type, Block Range, Street Name, Cross Street, Incident Date, Incident Time, and Latitude/Longitude. The offense codes follow a modified NIBRS system. Code 13A is aggravated assault. Code 12B is burglary. Code 31A is theft. You'll need a reference table because the map itself doesn't translate these codes for you.
What Crime Maps Get Wrong Right Away
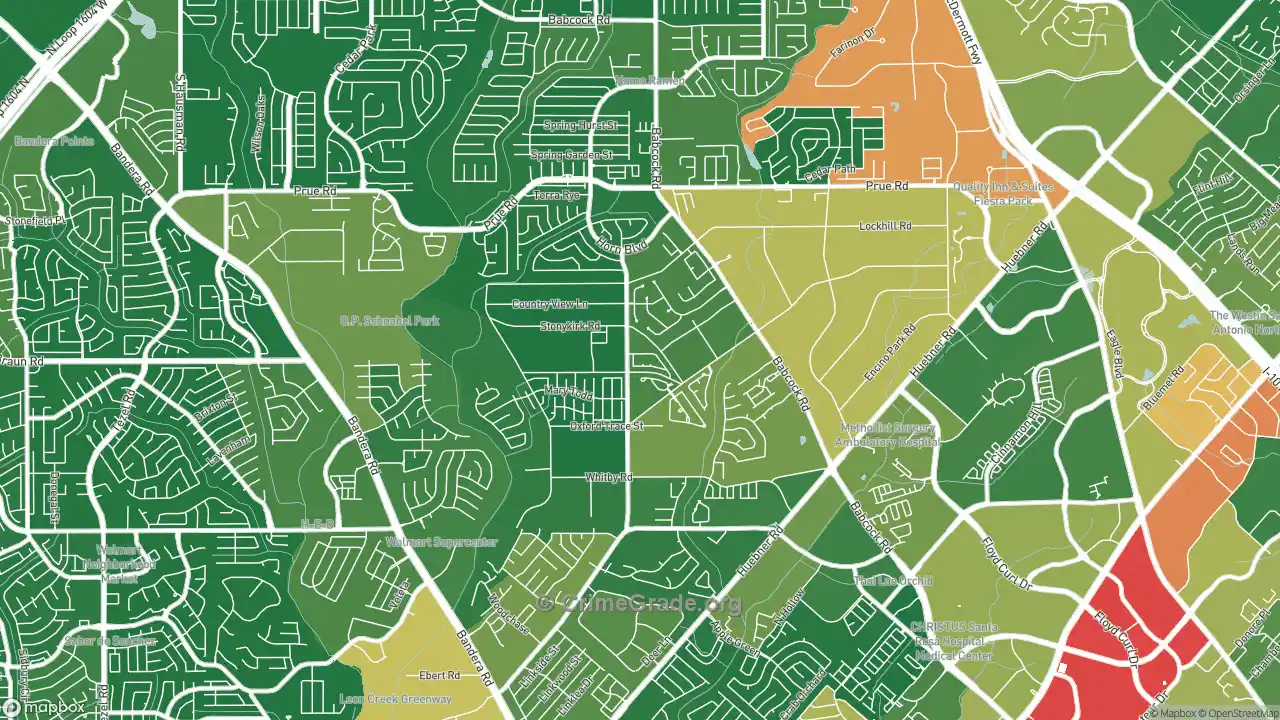
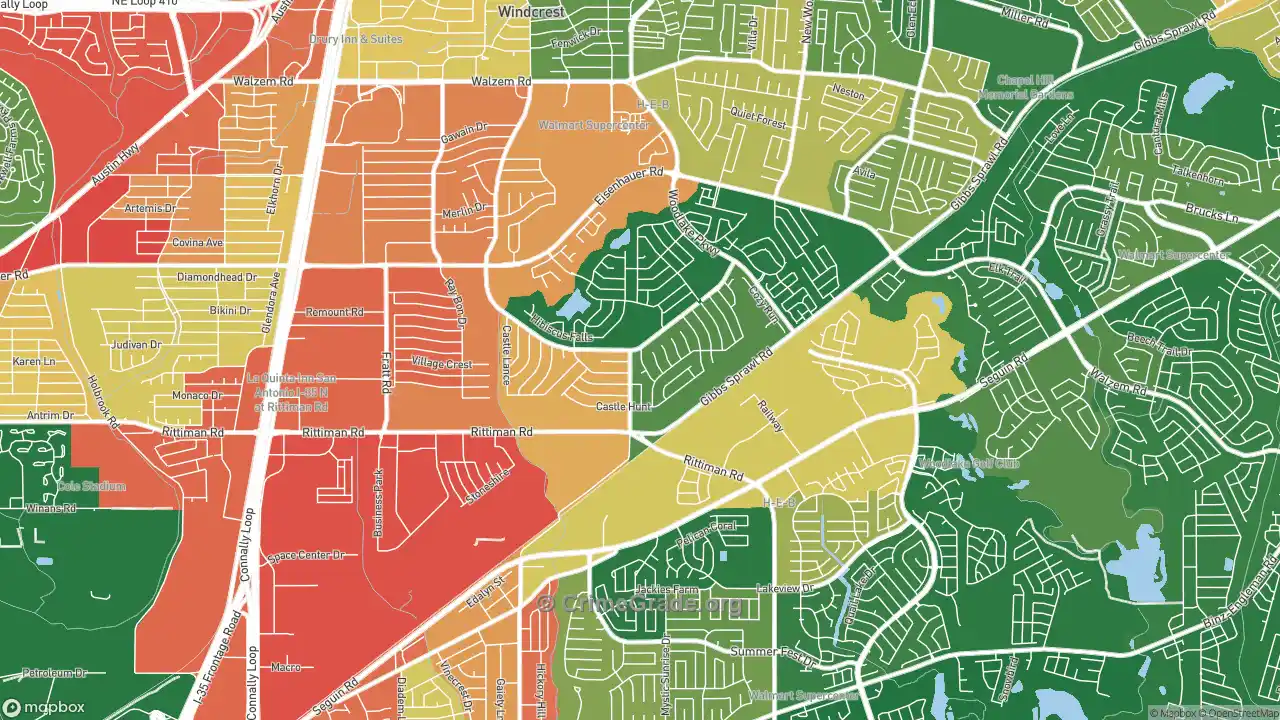
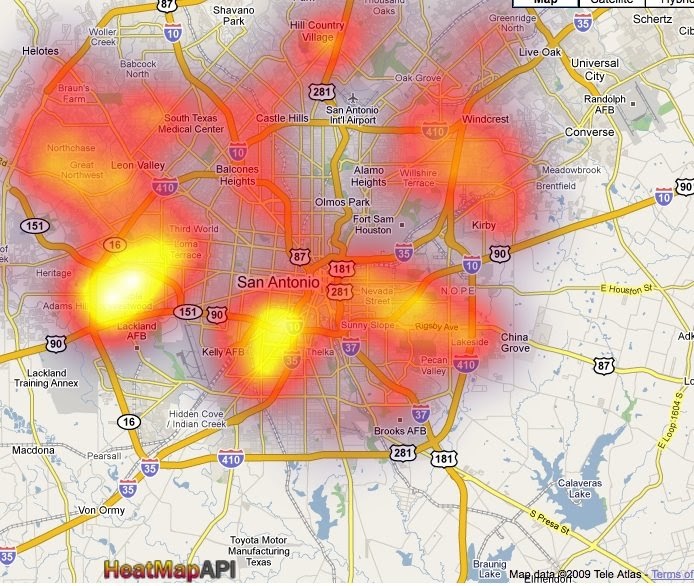
Crime maps show reported incidents, not actual crime rates. That distinction matters because reporting behavior varies dramatically across neighborhoods. Areas with higher homeownership rates and stronger community organizations tend to report more crimes simply because residents file more paperwork. A dense rental area like parts of East San Antonio may have identical or higher actual crime but fewer reports hitting the map. Another issue is geocoding accuracy. The SPDS data uses GPS coordinates from officer field reports or GPS units in patrol cars. Some incidents get coordinates snapped to the nearest address point, others are placed on centerlines, and a small percentage end up as approximate centroids from ZIP code or census tract aggregation. When I pulled data for a specific corridor along Fredericksburg Road, roughly 8% of records had coordinates that were clearly off — some placed incidents in parking lots or green spaces half a block away from where they actually occurred. You can clean this by cross-referencing with address geometry, but it takes time you may not have. Time decay is also a factor that trips people up. A crime map showing 47 incidents in a single quadrant over the past 90 days looks alarming. But many of those incidents cluster around a single recurring event — a weekend drug deal on a particular corner, or domestic disputes at a high-turnover apartment complex. The heatmap won't tell you that without digging into the raw incident details and groupings by exact address.
Get the Full Details

Building a Useful Layer From Raw Data
I stopped trying to read crime maps as-is and started building my own layers. The basic stack is: pull the CSV from OpenData, load it into a PostGIS database, filter out nuisance calls (suspicious persons, lost witness, property damage without theft), and aggregate by census block group with a rolling 12-month window. Filtering nuisance calls changed the picture significantly. In San Antonio, roughly 30 to 35 percent of all police dispatches fall into non-violent, non-property categories. Those get plotted on public crime maps alongside burglaries and assaults at equal visual weight. Once I removed them, the density heat maps shifted noticeably, especially in downtown and King William where service calls dominate the raw numbers. For aggregation, census block groups work better than ZIP codes because they're smaller and more stable over time. San Antonio has about 230 census block groups. A rolling 12-month window smooths out seasonal spikes without erasing real trends. I also weighted violent offenses — aggravated assault, robbery, burglary — at three times the count of property-only crimes when building my composite score. This is arbitrary but defensible, and it produces a map that aligns better with how people actually feel about safety.
Mapping tools matter too. ArcGIS Online handles this fine if you have a subscription. For a free option, I used Kepler.gl with GeoJSON exports from PostGIS. It renders tens of thousands of points without lag and lets you add your own filters on the fly. QGIS works as well if you prefer desktop and don't mind spending 20 minutes setting up the projection — WGS 84 for everything, no exceptions, or your coordinates will drift.
Edge Cases That Break Standard Approaches
The biggest edge case I ran into involved the Military Historic District and the Pearl District boundary. Crime coordinates near San Pedro Avenue and I-35 sometimes snap to either side of the interstate depending on which GPS signal the officer had at the time. A single incident could appear in two different quadrants on different map platforms. I resolved it by adding a 50-meter buffer dissolve around the I-35 centerline and merging overlapping points. This is niche but critical if you're analyzing that corridor, which sees disproportionate crime reporting due to its proximity to major thoroughfares and high-foot-traffic areas. Seasonal migration patterns also create noise. During the summer months, incidents spike in the Museum Reach and Market Square areas simply because more people are outdoors. In winter, the same areas flatten out. If you're comparing month-to-month without accounting for population flux, you'll flag false positives. I handled this by creating a baseline from the same month in the previous year and calculating deviation rather than using absolute counts. There's also the issue of police district boundaries shifting. San Antonio reconfigured several patrol districts in 2022, moving portions of South Side into the new District 8. Historical data before that date labels those addresses under the old District 6 designation. If you're pulling multi-year data and filtering by district, you'll misattribute incidents unless you maintain a boundary change log and reconcile accordingly.
What This Doesn't Tell You
Crime maps don't show clearance rates. An area with 60 reported burglaries per year and a 15 percent clearance rate is a very different place from one with 30 burglaries and a 55 percent clearance rate. The map looks worse in the first scenario, but the second area has more active, unresolved crime happening. The SPDS data doesn't include disposition or clearance information in its public feed, so you'd need to request supplementary data through a formal records request to get that layer. They also don't capture victimization accurately. Domestic violence incidents, especially in early stages, are severely underreported. Property crimes involving uninsured losses go unreported at higher rates in lower-income areas. The map reflects police activity as much as it reflects actual criminal behavior. Both matter, but they're not the same thing. Finally, crime maps show where incidents happen, not where risk exists. A quiet residential street near UTSA might have low incident counts but high vulnerability — poor lighting, minimal CCTV coverage, sparse foot traffic. None of that appears on a standard crime heatmap. If you're using this data for personal safety decisions, you need to layer in environmental design factors separately.
Practical Setup for Anyone Doing This Themselves
If you want to work with this data regularly, here's the stack I use. PostgreSQL with PostGIS on a small cloud instance — an 8GB RAM, 2-core setup handles a few years of San Antonio crime data without breaking a sweat. The initial import from CSV takes about six minutes for a full year of records, and indexing the spatial columns brings query time down to under two seconds for most aggregations. For querying, I use a simple view that converts offense codes to human-readable labels, aggregates by census block group with date rolling windows, and flags anomalous spikes using a standard deviation threshold of 1.5. The whole pipeline runs on a weekly cron job that pulls new data from the OpenData portal, deduplicates by incident ID, and refreshes the view. It takes about nine minutes total and requires zero maintenance after the initial setup. The portal URL is data.sanantonio.gov/City-of-San-Antonio/z3de-u25u. From there you navigate to Public Safety, then Crime Incidents, and export whatever date range you need. The API documentation is at data.sanantonio.gov/resource/ and supports standard OData filters. If you need bulk historical data going back beyond what the portal allows in a single download, you'll need to make multiple requests or contact the city's data team directly for a larger export.
The data is free and publicly accessible. The effort is in cleaning it, understanding what it leaves out, and building the right aggregations to make it useful. Most people skip the cleaning step and draw conclusions from raw plotted points. That's where the mistakes happen.