Where Your Data Actually Comes From
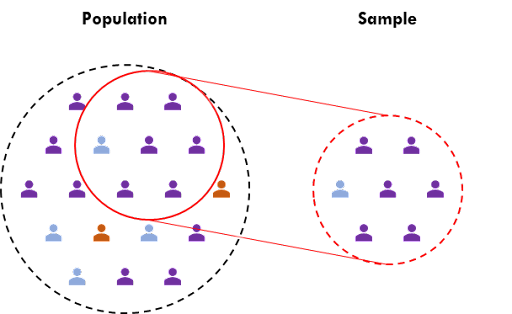
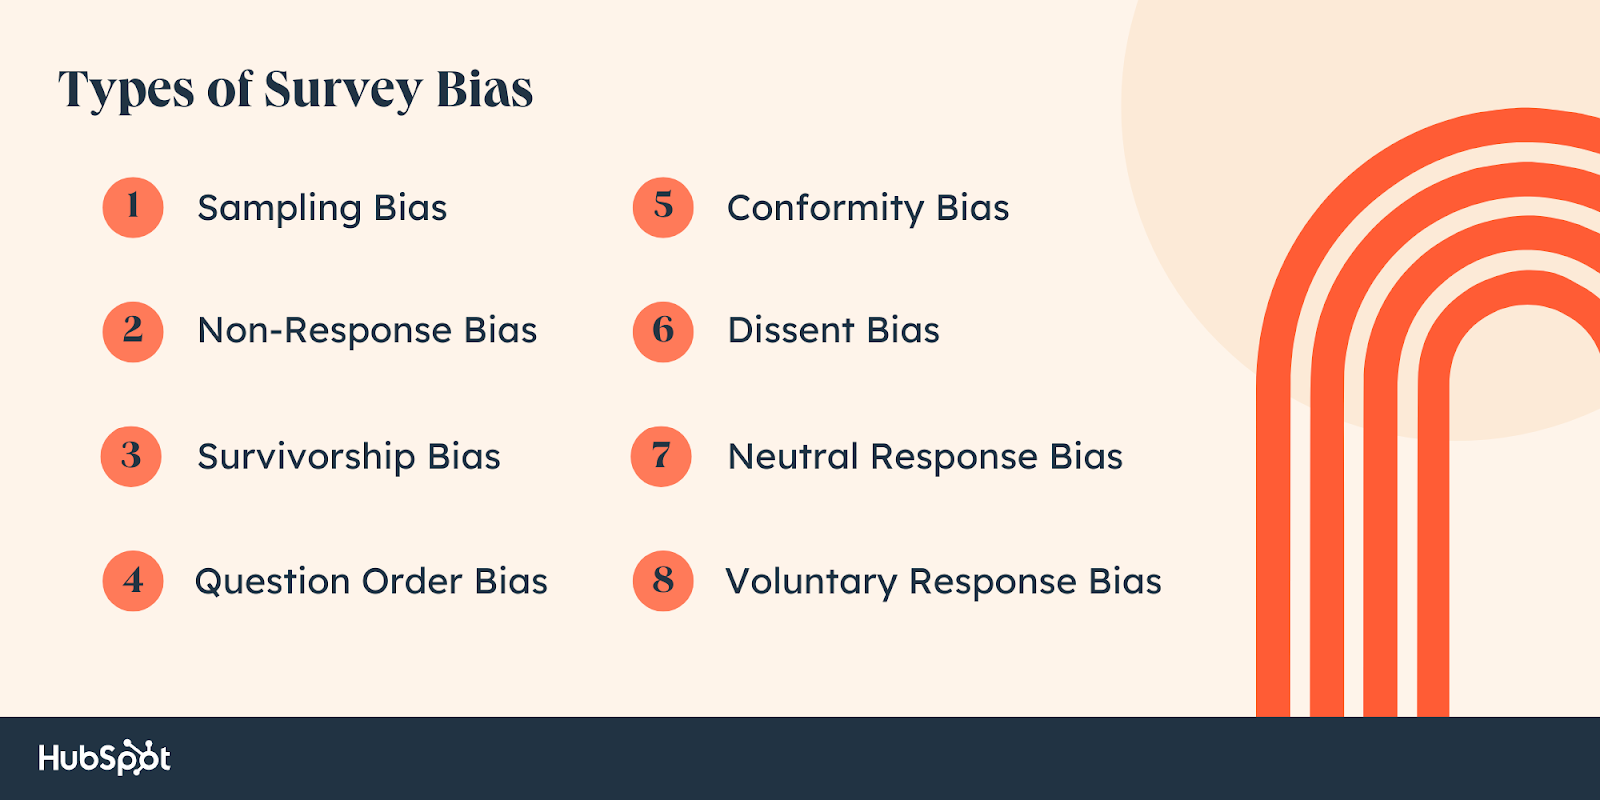
Sampling bias is one of those things that doesn't show up in any validation metric. You can run perfect cross-validation, your AUC looks great, your precision-recall curves are clean, and your model is still completely wrong because of how you collected the data. I learned this the hard way on a churn prediction project for a telecom company. We had 98.2% accuracy on our test set. The client called us three days after deployment to say the model was useless because it hadn't seen a single case of a customer leaving through the complaint channel—the dataset was entirely built from customers who had called retention to say they were thinking about leaving, which is exactly the group least likely to actually leave. The bias was baked into the collection method before any modeling happened. There are several distinct mechanisms by which sampling bias enters your work, and most of them don't look like bias when you're in the middle of collecting data. Self-selection bias is probably the most common. It happens whenever the people or items that end up in your dataset are the ones that chose to be there. Online surveys are the classic example, but it shows up everywhere. If you're building a sentiment analysis model for a product review system and you only scrape reviews from people who rated the product four or five stars, your model will learn that the product is universally loved. The one-star reviews went somewhere else. I spent two weeks debugging a model that kept predicting everything as positive, only to realize the training data had a 4:1 ratio of positive to negative reviews because we filtered out transactions below a certain dollar threshold, and low-value transactions happened to correlate strongly with negative sentiment customers who felt unheard. Survivorship bias is another one that quietly destroys models. You're analyzing data from entities that made it through some selection process, and you miss all the ones that didn't. In credit scoring, if you only train on customers who successfully repaid their loans, you never see the people who defaulted and were removed from the system. Your model learns what good repayment looks like but has no frame of reference for what failure patterns actually are. The workaround here is usually to reconstruct the denominator. You need to know how many people applied, how many were approved, and how the approved cohort compares to everyone who was eligible. I worked on a hiring algorithm where the training data came from employees who had already been promoted. The model kept recommending candidates who looked like promoted people because we'd lost all visibility into the people who were hired but never advanced, or who left within the first year. We ended up pulling HR records from five years back to reconstruct the full applicant pool, not just the promoted subset.
Time-based sampling issues come up more often than people expect. If you collect data during a specific window, seasonal effects or transient conditions contaminate your sample. I built a demand forecasting model for a retail client using data from November and December only because that's when their POS system had the cleanest records. The model worked beautifully for holiday season and completely failed in March. The sampling frame was restricted to a six-week period that represented perhaps 15% of annual demand patterns. We had to pull historical data from their legacy system, which meant dealing with a different schema and incomplete records from three years prior. It took two weeks of data engineering but it was the only way to get a representative sample across seasons. Geographic or accessibility bias is straightforward but often ignored until it's too late. If your data comes from a single region, a single platform, or a single data source, you're sampling a very narrow slice of the population. An app usage dataset from iOS users will look fundamentally different from Android users. A medical study conducted at a single hospital network will reflect that hospital's patient demographics, not the general population. The fix is usually stratified sampling, but you need to know what strata matter before you start collecting. In one project, we stratified by clinic location, patient age band, and insurance type simultaneously. The initial sample size requirements were brutal—about twelve thousand patients to get adequate representation across all three dimensions. Without the stratification, we would have missed the fact that our model performed 18% worse on Medicaid patients compared to private insurance patients because the training data was 73% private insurance by volume. One thing that trips people up is non-response bias, which is different from self-selection. This happens when a significant portion of your sampled units don't respond, and the non-responders differ systematically from responders. Mail surveys are terrible for this, but it shows up in digital contexts too. If you email a customer satisfaction survey and only 4% of recipients respond, those 4% are not representative of the whole. They're the people with strong opinions, usually negative ones. I've seen teams try to weight the responses to correct for this, but weighting assumes you know the true distribution of the non-responders, which you almost never do. The more reliable approach is to supplement with passive data—purchase history, support tickets, session recordings—that captures the silent majority without requiring them to fill anything out.
Here's a counter-intuitive point that most tutorials skip: sometimes the bias is in the labeling process, not the sampling. You can have a perfectly representative sample of the population and still introduce massive bias if the labels are assigned inconsistently. In a medical diagnosis model, if radiologists tend to label ambiguous cases as positive more often than negative (because missing a cancer is worse than a false alarm), your labels encode that tendency, not ground truth. The model then learns the radiologist's bias, not the actual disease signal. I caught this once by comparing label distributions across radiologists. Two doctors labeled the same batch of borderline scans with a 22% disagreement rate. The model's performance dropped by 14 percentage points when we removed the inter-rater noise by having a third radiologist arbitrate the disputed cases. The data wasn't biased. The labels were. Another thing worth noting is that oversampling techniques don't solve sampling bias. They solve class imbalance, which is related but distinct. If your dataset has 99% negative cases and 1% positive cases because that's how the population actually is, that's not a bias problem—it's a reality problem. SMOTE, random oversampling, or class weights will help your model learn the minority class pattern better, but they won't fix the fact that your positive cases came from a different underlying process than your negatives. I saw a fraud detection team apply SMOTE to a dataset where the fraud cases were all from a single geographic region and the non-fraud cases were distributed nationally. The model achieved decent recall on fraud but was completely worthless outside that region because the oversampling had amplified the regional pattern rather than teaching the model what fraud actually looks like across the population. The practical checklist I use now before I touch any dataset: First, document the sampling frame explicitly. Who or what was eligible to be included, and who or what was excluded, at every stage of collection. Second, compare your sample's marginal distributions against known population benchmarks. Age, gender, geography, transaction volume, whatever is relevant—check it. Third, if you're working with a proprietary dataset where you can't verify against external benchmarks, use sensitivity analysis. Perturb the sample composition and see how much your model's predictions shift. If a 5% change in demographic representation causes a 20% swing in predicted churn rates, you've got bias, plain and simple.
Get the Full Details

Undercoverage bias deserves a mention because it's the most common form in enterprise settings. Your sampling frame doesn't cover the entire target population. Employee surveys miss contractors. Web analytics miss desktop users who browse privately. Phone surveys miss people who only use text messaging. I worked on a project where the target population was all customers who had interacted with a brand in the past twelve months, but the data source was loyalty program members only. About 60% of customers never joined the program, and they turned out to be significantly higher value customers on average. The model trained on loyalty members underestimated customer lifetime value by roughly a third because it was blind to the non-members. The hard truth is that you can never fully eliminate sampling bias. You can only measure it, quantify its impact, and report it. Every dataset is a sample from some larger population, and the gap between your sample and that population is always present. The skill is in knowing how big that gap likely is and whether it matters for your specific use case. A model that's 85% accurate on your biased sample might still be useful if the bias is in a dimension that doesn't affect your decision threshold. But if the bias aligns with the outcome you're trying to predict, no amount of post-hoc correction will save you. The collection process is where the damage happens, and it's irreversible once the data is in hand. If you're starting a new data collection effort and want to avoid these problems from the beginning, the single most effective thing you can do is write a sampling protocol before you collect a single observation. Define the target population, the sampling frame, the inclusion and exclusion criteria, the expected response rate, and the planned checks for representativeness. Make it a living document that gets updated when the collection process deviates from the plan. I've seen projects where the original sampling protocol was lost and the team had no way to reconstruct what the data was supposed to represent. Six months later they were trying to publish results and couldn't justify their sample to reviewers because nobody could explain why the demographic distribution looked the way it did. The protocol would have taken two hours to write. Not writing it cost them six months.