Why Your Sample Size Decides Whether Your Study Lives or Dies
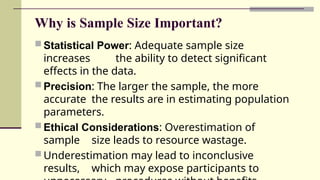
I spent three years trying to figure out why my survey results kept falling apart in peer review. The problem wasn't the questions or the analysis. It was the sample size. Specifically, whether I should treat my data as big N or little n. This distinction comes up constantly in research methodology discussions, and it is one of the most consequential choices you make before you even collect your first data point. The topic of Sample Size Big N Or Little N The Critical Debate Shaping Research Validity doesn't get nearly enough attention in practical research settings. Big N refers to large-scale datasets where you have hundreds or thousands of observations. Little N means you are working with maybe twenty, fifty, or occasionally a hundred cases. The labels sound academic but they map directly onto completely different methodological commitments. Big N studies rely on statistical power, significance testing, and generalizability claims. Little N studies lean on depth, context, mechanism tracing, and theoretical saturation. I once ran a regression on a dataset with n=847 and got a statistically significant coefficient at p
.001 for a variable that explained 0.3 percent of the variance. The result was real but practically meaningless. Conversely, I did a small-N process tracing study with twelve case studies that revealed a causal mechanism a team with five thousand survey responses had completely missed. Neither approach is superior. They answer different questions. The mistake researchers make is pretending one framework fits all research problems.
The Statistical Ground Rules Nobody Teaches Well
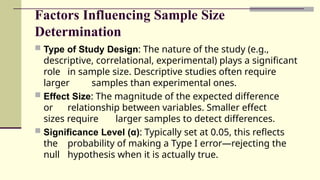
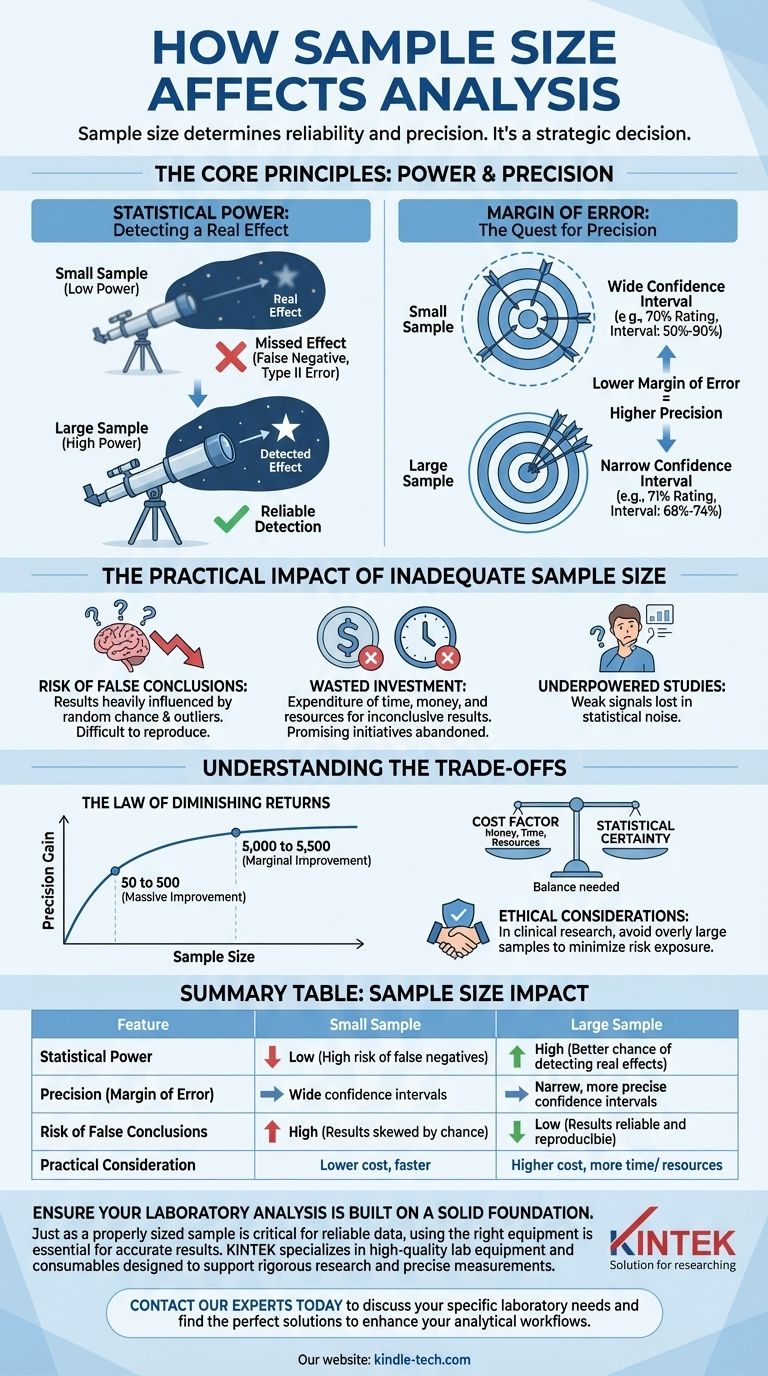
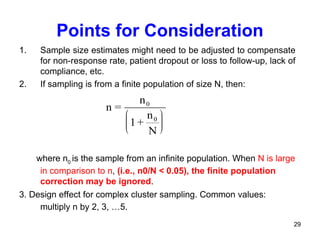
Power analysis is non-negotiable for big N work. If you are running regressions, factor analyses, or structural equation models with large samples, you need to know your minimum detectable effect size. Most researchers skip this. I use G*Power for standard tests and the pwr package in R for more complex designs. A typical multiple regression with five predictors and a small effect size (f² = 0.02) at 80% power requires roughly 394 participants. Forget that calculation and you risk a null result that looks like no effect when it is actually just underpowered noise. For little N research, the rules shift entirely. You are not trying to estimate population parameters. You are trying to build and test causal arguments. The relevant metric is not statistical power but analytical generalization. Your sample needs to be theoretically representative of the phenomenon, not demographically representative of a population. I typically aim for 6 to 15 cases depending on the complexity of the mechanism I am tracing. Beyond that, the marginal insight drops sharply and the time cost becomes unsustainable. The practical compromise I found useful was a nested design. I ran a quick big N screen on about 200 cases to identify which ones were outliers or key examples, then followed up with intensive little N process tracing on six of them. This cut the data collection time from something that would have taken eighteen months down to about seven, while preserving both breadth and depth. It is not perfect. You lose some granularity in the screening phase, and you still need solid qualitative skills to make the second phase work. But it is far better than choosing one approach blindly and hoping for the best.
Common Pitfalls That Wreck Both Approaches
Big N researchers frequently confuse correlation with causation and then publish confident claims about mechanisms they never actually tested. A large sample does not fix a bad research design. It just gives you more precise wrong answers. I have seen this happen repeatedly in organizational studies where researchers throw thousands of survey responses at a cross-sectional model and then claim to understand why things happen. They do not. They understand what is associated with what at a single point in time. Little N researchers make the opposite error. They assume that because they understood one case deeply, they can extrapolate broadly. Small-N work is vulnerable to selection bias and researcher confirmation bias in ways that big N work is not. The fix is explicit theoretical replication across cases and transparent documentation of every coding decision. I keep a detailed audit trail for every little N study because reviewers who know the method expect to see it. Those who do not know the method will not care either way, but the audit trail catches errors before they reach publication. Another issue specific to big N data is missingness. With large datasets, missing data is never random. It is almost always systematic. Listwise deletion in a dataset of ten thousand can silently remove forty percent of your sample if the missingness correlates with your dependent variable. I run MCAR tests first, then use multiple imputation with chained equations rather than mean substitution or single imputation. The difference in results can be substantial and the extra hour of computation is worth it.
Get the Full Details
When to Choose Each Approach
Use big N when your research question is about prevalence, distribution, or average effects across a defined population. Use little N when your question is about how and why something happens, especially when the mechanism is poorly understood or contested. The hardest decisions come in the middle territory where you want both generalizability and mechanistic insight. That is where the nested design I described earlier earns its keep. There is also a third option that gets ignored too often: moderate N with mixed methods. Twenty to fifty cases with structured comparison and some quantitative analysis can give you more than either extreme. The trade-off is that you need stronger methodological training and more time per case than pure big N or pure little N work allows. I have found that teams with at least one person experienced in both quantitative and qualitative methods handle this approach best. Solo researchers attempting moderate N without that background tend to produce shallow work on both sides. The sample size decision is not a technical footnote. It is the foundation of your entire design. Pick the framework that matches your question, not the one that looks more impressive on a resume. Your results will be more honest and your readers will have a clearer picture of what you actually know.