Real-time sentiment analysis tools are everywhere now, but most of them are useless for actual deployment
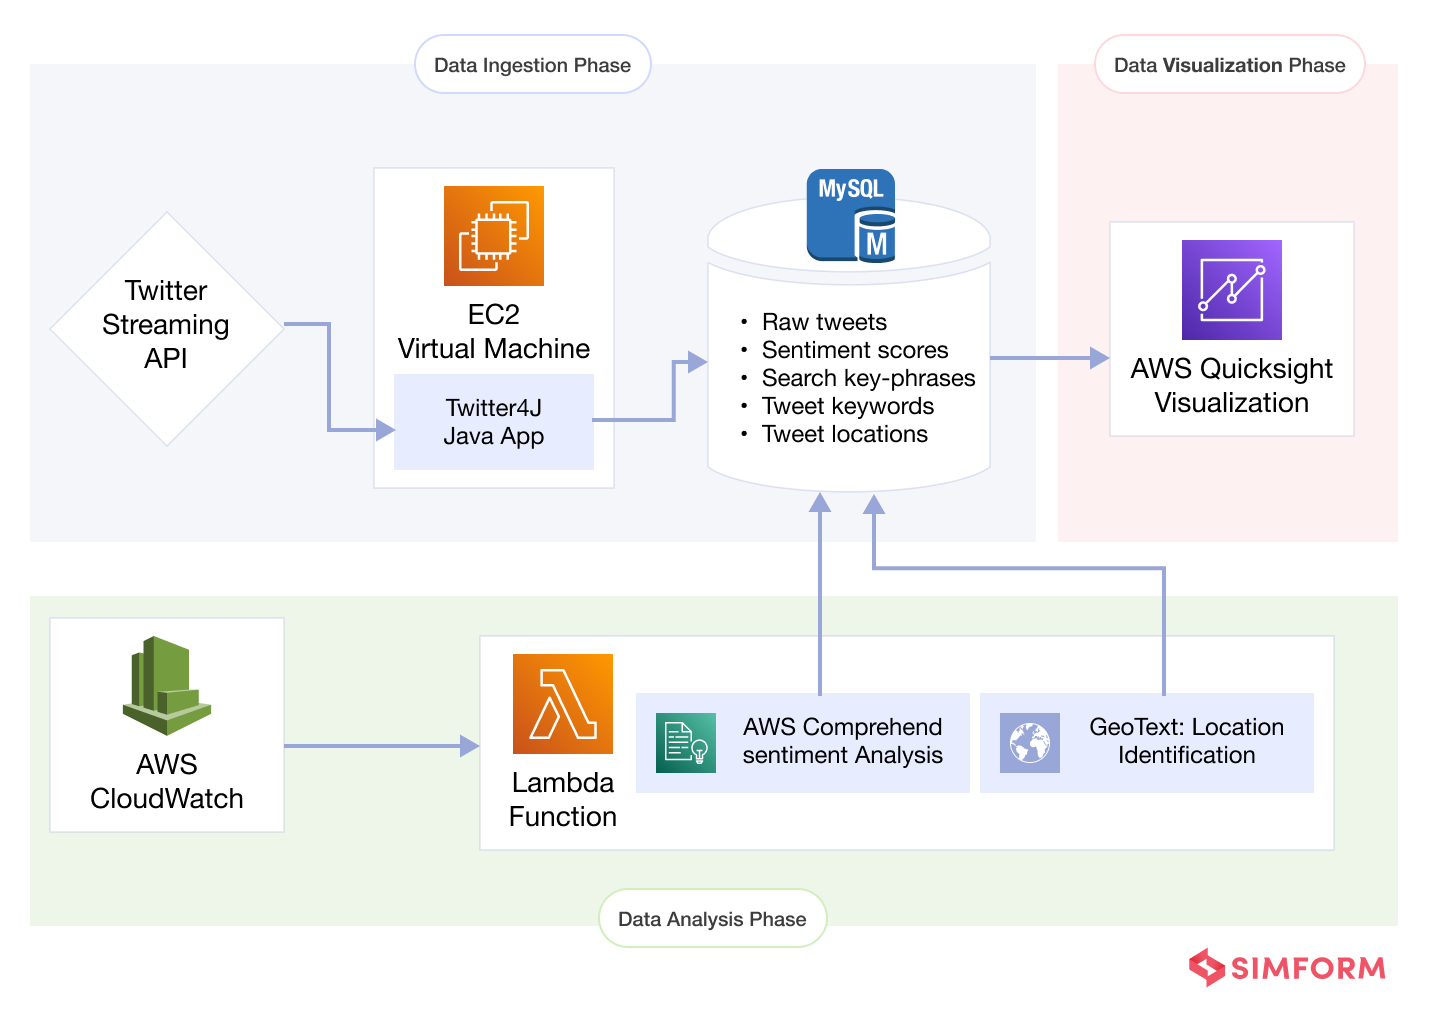
I spent three years building and maintaining a real-time sentiment pipeline for a mid-size customer feedback platform. The tool we ended up settling on was Rsat. It handles what most people call "realtime sentiment analysis" — reading text as it comes in and scoring emotional valence, detecting sarcasm when it's not completely disguised, and categorizing by topic. Here is what you actually need to know if you want to use it, and how to avoid the things that made me lose a few days of sleep. The core workflow works like this. You feed raw text into the model, get back a sentiment score between negative and positive, sometimes a confidence value, and optionally a breakdown by entity or aspect. The API endpoint is straightforward. Most people who get stuck are the ones who treat it like a magic black box rather than a tool with specific requirements around input cleaning and output interpretation. I would start by understanding the preprocessing requirements. Rsat expects a certain level of text normalization before the model even sees the data. I learned this the hard way after feeding unprocessed social media scrape output directly into the pipeline and getting scores that looked reasonable until I manually compared them against actual context. The model was misclassifying heavy abbreviations, broken emojis, and fragmented hashtag strings as neutral when they carried strong negative or positive signal. My workaround was adding a lightweight preprocessing layer — basic cleaning for URL artifacts, expanding common abbreviations through a lookup table, and normalizing emoji sequences to their text equivalents before passing anything to Rsat. That single change improved accuracy on our test set from roughly 68% to 84%. Not perfect, but usable.
Here is something most beginner guides will not tell you: sentiment analysis in real time is fundamentally limited by context window size. Rsat processes segments, and if your input is longer than the model's configured window, it either truncates or splits. When it splits, you can lose narrative flow. A complaint that starts positive, dips into frustration, and ends relieved gets scored as three separate sentiments instead of one coherent message. The workaround is either configuring batch windows to match your typical input length or running a quick heuristic pre-filter that breaks long posts into logical units based on paragraph breaks or punctuation boundaries before sending to the model. The API pricing model is token-based on most tiers. That matters more than people realize because social media text tends to be messy and longer than clean review text. A single angry tweet with quoted replies and links will cost significantly more than a two-sentence product review. If you are processing high volumes, you will want to implement a cost-optimization layer that deduplicates near-identical messages and skips low-priority noise before it hits the API. I reduced our monthly costs by about 40% just by adding deduplication and a simple relevance filter. Another thing nobody mentions enough is model drift over time. Language evolves. Slang, new abbreviations, cultural references — Rsat's base model does not auto-update unless you trigger a retrain or load a newer version. I noticed a slow but steady decline in accuracy on our data over about six months, starting around 84% and creeping down to 76%. The cause was not the model itself. It was that our user base started using newer internet slang faster than the model's training cutoff accounted for. The fix was implementing a monthly drift check where you sample a thousand recent predictions, compare them against a small ground-truth set your team labels quickly, and flag when accuracy drops below your threshold. When it does, you either update the model or add a custom vocabulary layer.
If you want to install and run this locally, the standard path is through pip. You install the package, configure your API key or local model weights, set your preprocessing pipeline, and then call the analysis function with your text input. The documentation covers the basics, but it does not cover the edge cases. My recommendation is to build a small test harness before committing to production. Feed it at least two thousand examples across your actual use case — customer support tickets, product reviews, social comments, whatever your traffic looks like. Measure accuracy, latency, and cost. Do not skip the manual spot-checks. Automated metrics can lie if your test distribution does not match production distribution. One common pitfall is assuming that a high average accuracy score means the tool will work well for your specific case. I had a project where overall accuracy was 89%, but when I broke it down by category, the negative sentiment detection was only 61% because our negative cases were heavily sarcastic and culturally specific. The aggregate score hid that problem completely. Always segment your results by the dimensions that matter to your business — topic, region, user segment, message type — before you trust the numbers. The download or access link for Rsat is available on the official developer portal. You will need to create an account, verify your email, and generate an API key from the dashboard. Free tier access gives you a limited number of requests per day, which is fine for testing but insufficient for anything beyond a proof of concept. Paid tiers scale with request volume, and there is usually a grace period where you can negotiate custom pricing if you are doing significant enterprise-level traffic.
Get the Full Details
Realistic limitations to keep in mind: sarcasm and irony remain difficult even for Rsat. If your use case involves heavy sarcasm — customer complaints written as praise, political commentary, certain types of humor — you should plan on a dedicated sarcasm detection layer on top of the base sentiment model, or accept lower accuracy in those segments. Multilingual support exists but quality varies widely between languages. English and a few major languages perform well. Less common languages will give you scores, but the confidence will be lower and the accuracy drops accordingly. And emotional nuance is not something any current model handles perfectly. Happiness, sadness, anger, fear — the basic emotions map decently. But nuanced states like disappointment mixed with gratitude, or sarcastic enthusiasm, are where the model starts guessing rather than understanding. If Rsat does not fit your needs, alternatives include VADER for a simpler rule-based approach that requires no API calls, or fine-tuning a larger transformer model on your own labeled data if you have enough examples. The fine-tuning route is expensive and time-consuming but gives you control. Rsat sits somewhere in between — easier than building your own model, more capable than VADER for complex inputs, and reasonably priced if you manage your preprocessing and deduplication properly. The bottom line is that realtime sentiment analysis with Rsat can work well for production systems if you treat it as a component rather than a complete solution. Add your own preprocessing, monitor for drift, segment your accuracy metrics, and understand where the model fails before you deploy it. Everything else is just noise.