Getting Started With Satellite Analytics Platforms
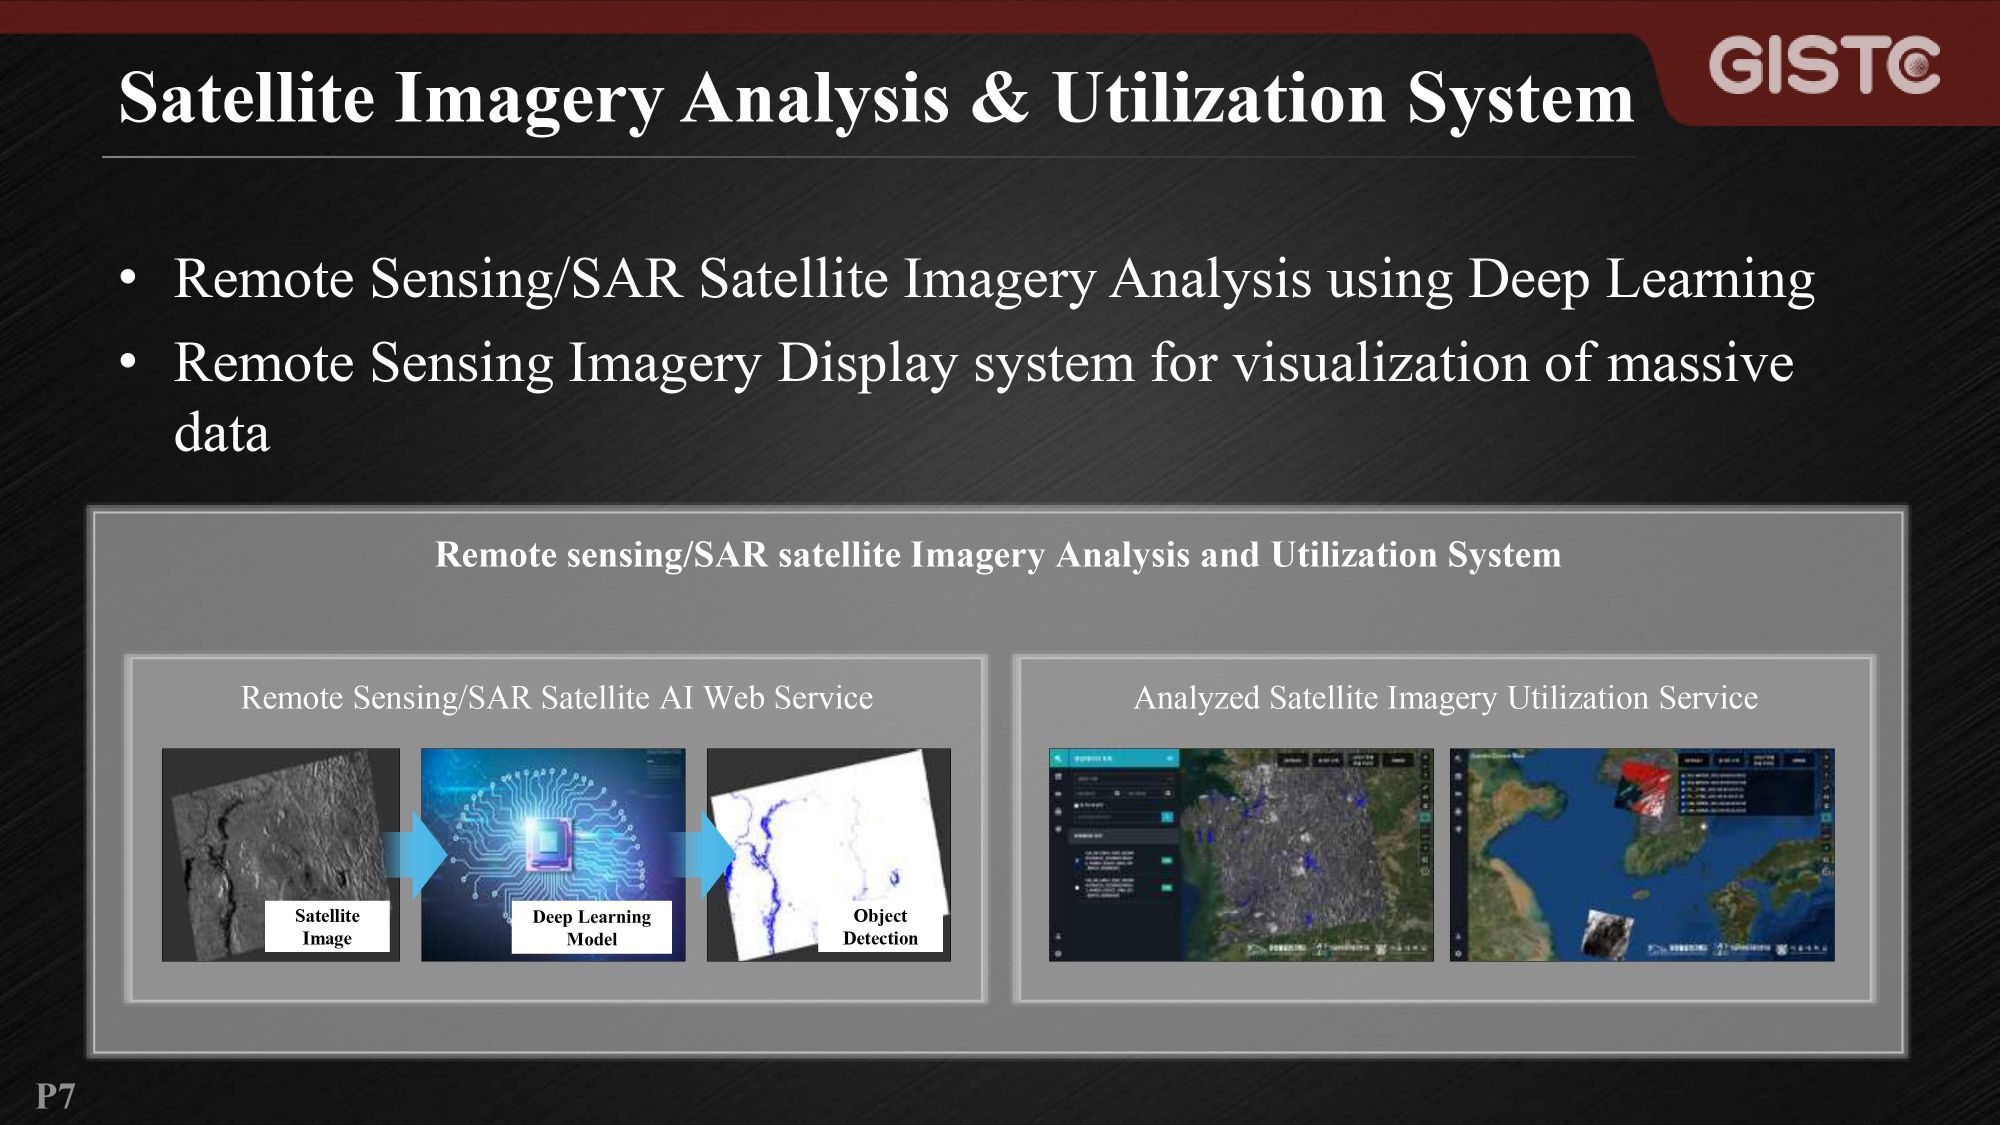
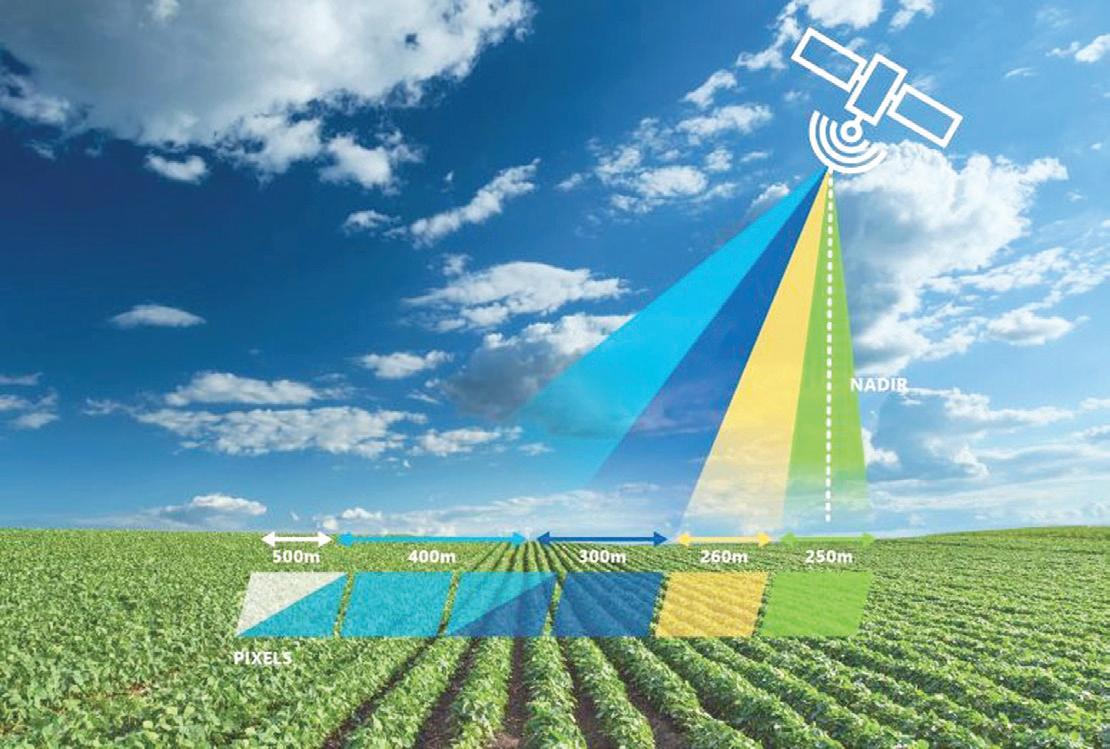
I spent three years building a land-use monitoring pipeline before I stopped trying to stitch together six different free tools and just looked for something that handled the whole chain. What I found was a platform that let you go from raw optical imagery to classified change maps without writing custom ETL scripts for every sensor mismatch. The approach it uses matters more than any single feature. The core idea is straightforward enough that people overcomplicate it. You ingest satellite imagery, run a model or statistical analysis over it, and output something actionable. The revolution part comes from reducing the time between ingestion and output from weeks to hours. That shift changes what projects are even worth attempting. Start with your cloud cover logic. Most beginners skip this and wonder why their accuracy numbers collapse later. A proper setup pre-filters your imagery catalog for acceptable cloud percentages before you even attempt to download or process anything. I once ran a workflow on 400 scenes only to find 73% were compromised by haze. The platform's cloud masking and compositing features cut that investigation down to a single query. The trick is learning how it constructs its composite layers. It doesn't just average pixels. It selects the lowest-cloud pixel per band across the date range and assembles a scene from those selections. That matters when you are tracking subtle vegetation index shifts over narrow windows.
Working With the Processing Pipeline
The pipeline is where most people waste time or create silent bugs. Every step needs validation at the output stage, not just at the end. I learned this the hard way after a forest disturbance project came back with what looked like perfect accuracy until someone flagged that the temporal sequence of the classifications was physically impossible. A pixel changed from forest to bare soil, then back to dense forest, then to water within a single growing season. That is not a real phenomenon. It was a sensor artifact mixed with misaligned atmospheric correction. The workaround was running a temporal smooth pass over the classification output and flagging any transitions shorter than the minimum mapping unit for the area. I set the minimum to 14 days based on the local growing season and re-ran. The impossible transitions mostly disappeared. The pipeline now runs that check automatically on every output. It adds about six minutes per scene but prevents hours of downstream debugging. Data Intelligence work in this space usually involves combining multiple sensor types. Optical gives you texture and color. Radar fills in the gaps when clouds persist and penetrates canopy slightly differently than visible light. I have seen people use just Sentinel-2 and call it sufficient until they hit the monsoon season in Southeast Asia or the persistent cloud deck over the Pacific Northwest. Having a multi-sensor fallback is not a luxury. It is how you keep a project alive year-round.
Model Selection And Accuracy Tracking
Random Forests still dominate this space for good reason. They handle mixed data types, they resist overfitting better than neural networks on small datasets, and they give you feature importance outputs that you can actually explain to a client. But they are not automatic. You need training data that covers the variability in your scene. If you train on flat agricultural land and then apply the model to hilly terrain with shadow effects, the model will confidently produce wrong answers. I keep an accuracy log for every run. Not just overall accuracy. Kappa, producer accuracy, user accuracy, and confusion matrix breakdowns per class. These numbers tell you where the model is lying to you. A high overall accuracy often masks terrible performance on a specific class. In one project I worked on, overall accuracy sat at 91% while the wetland class had a user accuracy of 34%. The model was labeling wetlands as cropland because the spectral signatures overlapped in the training data. I went back and added more wetland samples from early growing season, not late season when the crops looked similar. Accuracy on that class climbed to 78%. Nothing impressive, but workable. Neural networks do better when you have thousands of labeled samples. That is a big when. If you are working at a regional scale with limited ground truth, a well-tuned Random Forest will beat a poorly trained convolutional network every time. I have seen teams push for deep learning because it sounds more modern. Then they spend months collecting labels and still end up with worse results than the simpler approach.
Get the Full Details
Storage And Compute Costs
This is where the practical reality bites. Satellite imagery is heavy. Processing it at scale gets expensive fast. The platform I ended up using charges by processing minutes and storage gigabytes. A single Landsat scene in full resolution with all spectral bands is roughly 1.2 GB. Processing twenty scenes through a four-step pipeline on a monthly schedule for a year works out to significant cost if you do not optimize your regions of interest. Filter your areas of interest down to the actual polygon boundaries you need, not the whole tile. I used to process full Sentinel-2 tiles and then clip them, wasting about 40% of my compute budget. Switching to polygon-based processing dropped my monthly bill by nearly half. The platform supports that natively if you configure your workspace correctly from the start. Export formats matter too. GeoTIFF is the standard but it is not the most efficient for storage. COG files compress better and stream faster for web visualization. I migrated my main data lake from GeoTIFF to COG about a year ago. Storage dropped roughly 30% and the time to generate preview thumbnails for the dashboard went from twelve seconds per scene to about two seconds.
Where This Approach Falls Apart
I need to be honest about the limitations. Automated satellite analytics cannot replace field verification for high-stakes decisions. If you are using this for regulatory compliance, insurance claims, or environmental impact assessments, you need ground truth checks. The models will make mistakes. They always do. I have seen three separate misclassifications that would have been obvious to a field person in under five minutes. The model saw them all as something else with high confidence. Temporal resolution is another constraint. Sentinel-2 revisits the same location every ten days with two satellites, but cloud cover can stretch that to weeks in many regions. If your project depends on weekly observations, you need a different strategy or an additional data source. Planet Scope fills this gap somewhat but at higher cost and with different quality characteristics that require separate model calibration. The final piece most people underestimate is the documentation and reproducibility problem. A workflow that works today may break in six months when the platform updates an algorithm or changes a default parameter. I keep detailed records of every version, every parameter, and every output sample. When something shifts, I can reproduce the old results and compare. Without that trail, you lose the ability to prove your methodology was consistent.
The data landscape here is moving too fast to treat any single tutorial as permanent. The principles above have held up, but the tool implementations change regularly. What matters is building a workflow that you can audit, validate, and adjust when something drifts. That is the actual transformation happening. Not just faster analysis. More reliable, trackable analysis.