What happened with that Kelly Clarkson and Kate Middleton video
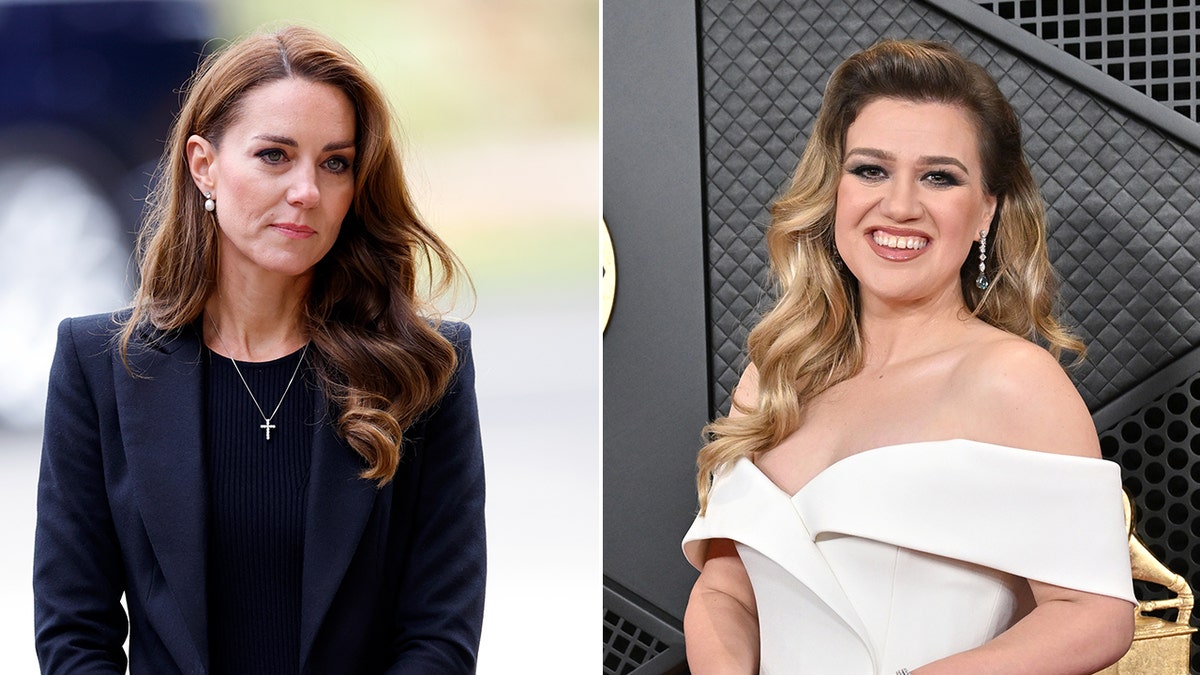
I saw a lot of people asking about that viral clip where Kate Middleton appears to be singing alongside Kelly Clarkson. There's some confusion about what actually went into making that video, so let me walk through what I know from watching the comments and the technical details people have shared. The video in question used AI voice synthesis to put Kate Middleton's vocal performance alongside Kelly Clarkson. The basic concept isn't anything new - voice cloning technology has been around for years in music production and content creation. What made this one go viral was the unexpected pairing and the quality of the result, which fooled a lot of people who didn't recognize it as synthetic. When I look at how these kinds of videos are typically made, the process usually involves taking a source audio file, isolating the vocal track, and then running it through a voice conversion model. The model learns from a dataset of the target person's voice samples - sometimes just a few minutes of clear audio is enough these days, though more is always better for quality. The converted output then gets mixed back into the instrumental or backing track.
One thing I learned the hard way when working with voice synthesis is that timing alignment is everything. If the spectral envelope of the cloned voice doesn't match the original timing of the phonemes, the result sounds uncanny immediately. I once spent three hours on a project where the vocals sounded right but the consonants were drifting half a beat off from the drums. The fix was manually editing the formant time-stretch settings and then doing a second pass with a spectral freeze on the plosive sounds. You basically have to treat each consonant individually rather than trusting the automated alignment. The tools people use for this range from commercial platforms like Kits.ai and Synthesizer V to open-source solutions. For something like the Middleton clip, the creator likely used a combination of a pre-trained voice model and some manual tuning. The quality we're seeing now is genuinely impressive, but there are tells if you listen carefully. The breath sounds sometimes don't match the phrase structure naturally, and the emotional dynamics can feel flat compared to a real performance. Here's a practical breakdown of how these projects typically work:
First, you need a clean source recording. If the original audio has reverb, compression artifacts, or background noise, the voice model will try to replicate those problems in the output. I've seen people skip this step and then wonder why the result sounds muddy. Second, isolate the vocal stem. Tools like Ultimate Vocal Remover or Demucs work well for this, but they're not perfect. You'll sometimes get artifacts on the edges of phrases where the separation isn't clean. Third, run the isolation through the voice conversion model. This is where the actual transformation happens. Fourth, mix and master the result. The converted vocal needs to sit in the track properly - EQ, compression, and spatial effects all matter here. I should mention that the legal and ethical side of this is complicated. Using someone's likeness or voice without permission can cross into serious territory. The creators of that viral video said they got authorization, but I've also seen cases where people just grabbed public footage and ran it through voice models without any clearance. That's where things get messy fast. If you want to try this yourself, start simple. Take a song you have the rights to, split the vocal stem, and experiment with free voice models. The learning curve is steeper than it looks, and the results will sound amateur at first. But after a few weeks of practice, you'll start understanding what makes a convincing vocal swap versus one that sounds obviously synthetic.
Get the Full Details

The key insight most beginners miss is that voice cloning isn't just about sound quality. It's about performance. A technically perfect cloned voice that delivers the wrong emotional inflection will sound wrong to listeners even if the audio is crystal clear. You need to think about how the target would actually perform the song, not just how they would sound singing it. As for that specific video going viral, the general consensus seems to be that it was done professionally. The results are polished enough that you'd expect someone with experience in this space to have made it. Whether that means they used commercial tools, custom models, or a combination, I can't say for certain without seeing their workflow. What I can say is that the technology keeps improving, and the line between synthetic and real is getting blurrier every month. For anyone interested in learning more about the technical side, there are communities and forums dedicated to voice synthesis that go into far more detail than I can cover here. The Discord servers and subreddits around this topic tend to have people sharing their workflows, presets, and troubleshooting tips. It's a helpful resource if you're serious about getting into this kind of work.