The Context Switch Tax Nobody Talks About
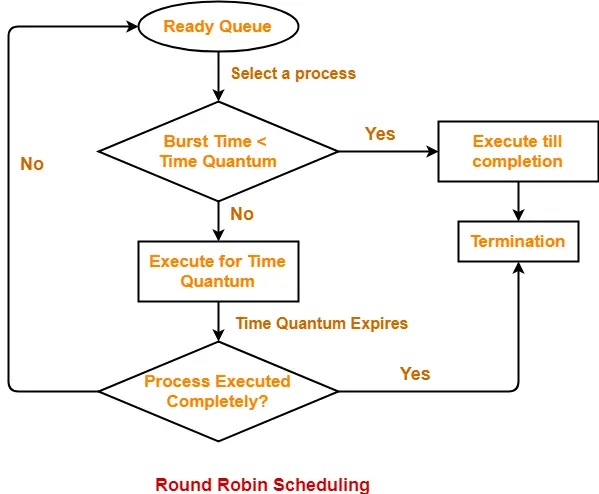
Round robin scheduling is the default CPU scheduler on most general-purpose operating systems because it is easy to reason about and reasonably fair. It assigns each ready-thread a fixed time quantum, rotates through the queue, and moves any thread that exhausts its quantum back to the tail. That is the textbook version. The real version lives in the kernel code, and it is uglier than people give it credit for. I spent three weeks debugging why a real-time audio processing thread would occasionally drop a buffer under load. The system was a standard Linux build with CFS (Completely Fair Scheduler) running alongside some PREEMPT_RT patches. The symptom looked like a scheduling bug. It was not. It was the time quantum interacting badly with interrupt latency and the way threads migrated between CPU cores during contention. This is the kind of thing you only notice when something breaks in production.
Round Robin Scheduling A Deep Dive Into Fairness Precision And Realtime Performance
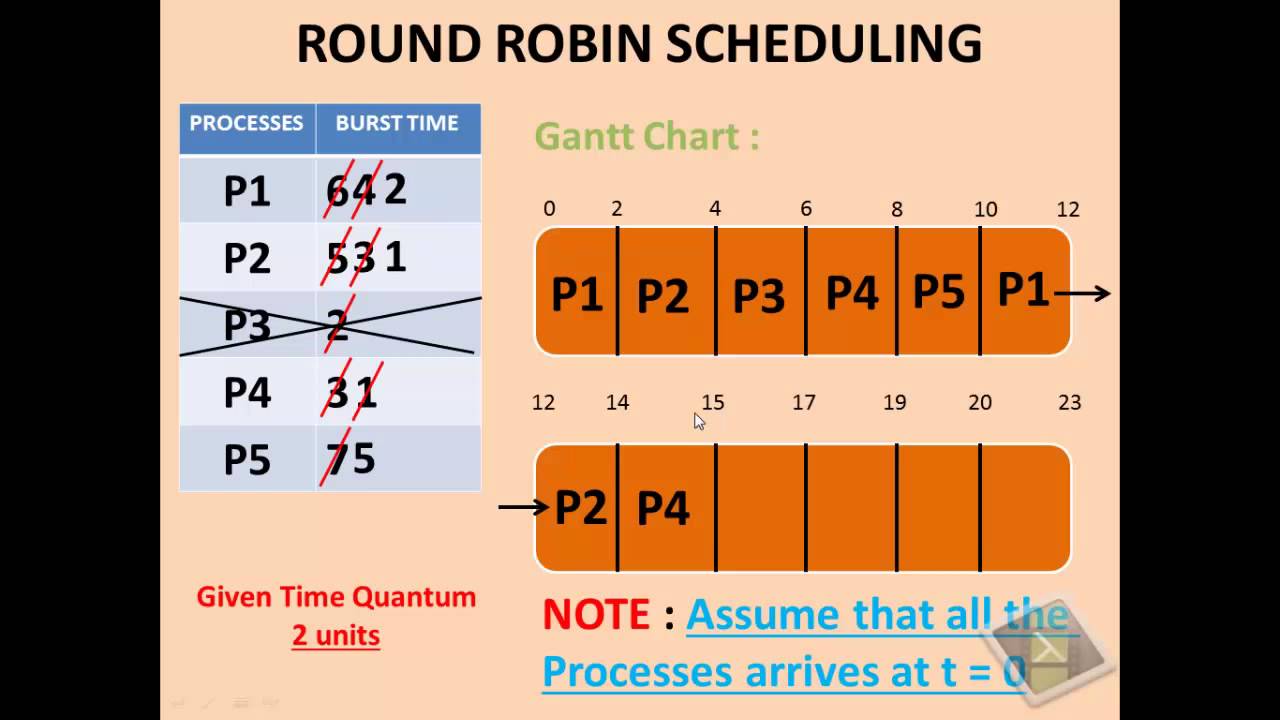
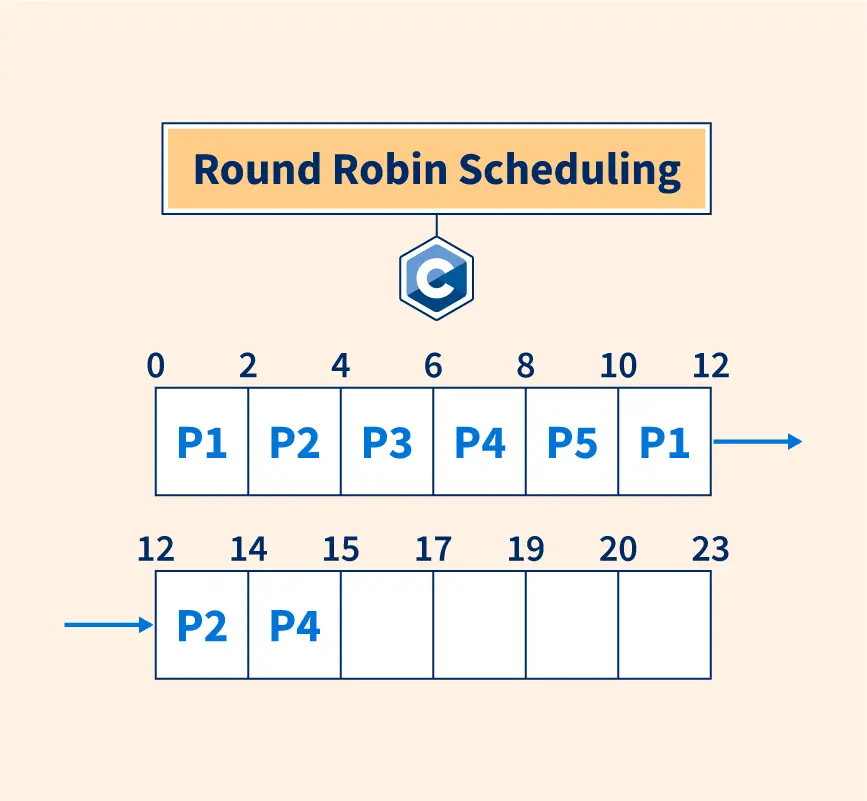
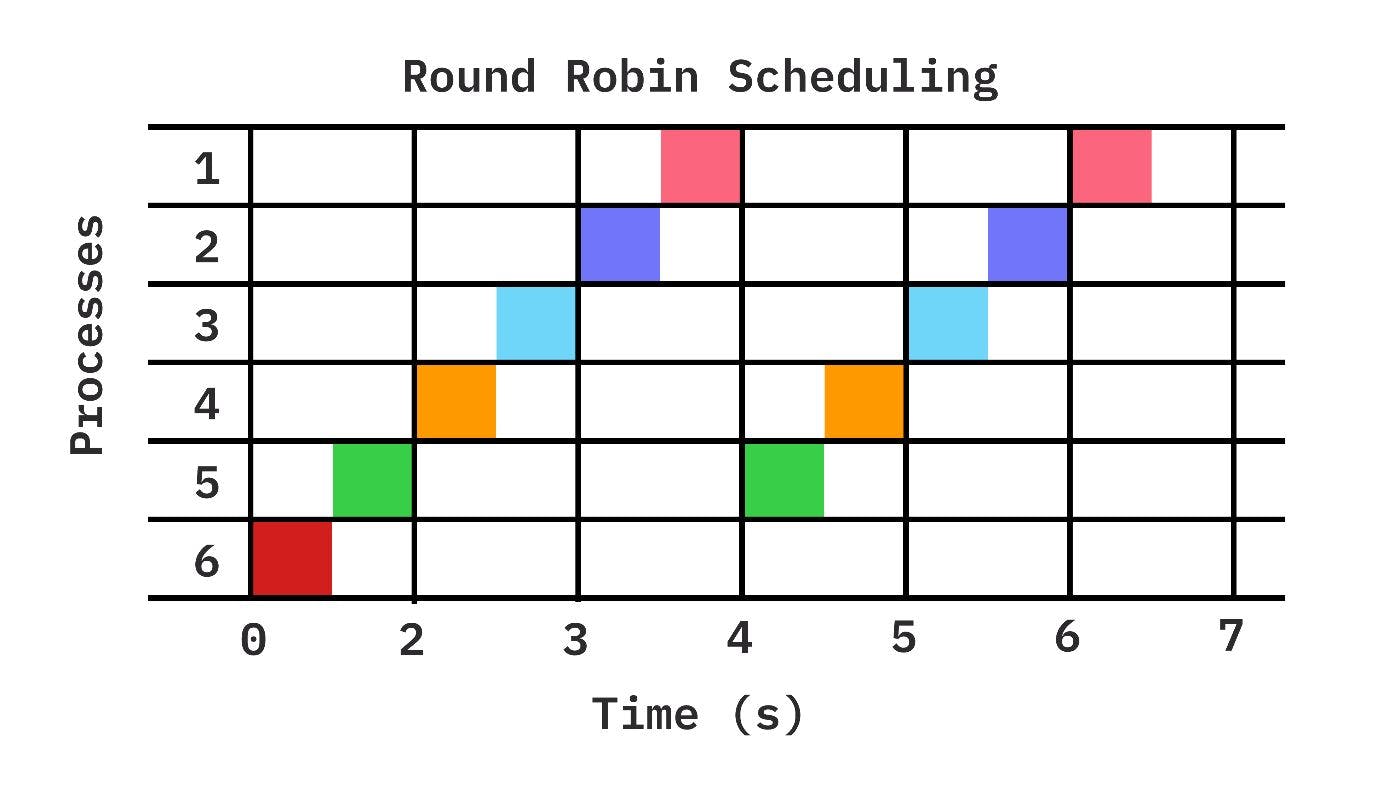
The core mechanism is a circular queue with per-thread time accounting. Each thread gets a slice of CPU time. When it expires, the scheduler performs a context switch to the next thread. The fairness guarantee is that no single thread can monopolize the processor indefinitely. Precision depends entirely on how small you make the quantum and how much overhead the context switch itself introduces. Here is where beginners get tripped up. A smaller quantum is not always better. Reducing the time slice from 10 milliseconds to 1 millisecond does not linearly improve responsiveness. It actually makes things worse because the context switch overhead becomes a significant fraction of each thread's execution window. On a typical x86 system, a context switch takes roughly 5 to 15 microseconds depending on cache state and whether the new thread hits cold page tables. If your quantum is 1 millisecond and your switch overhead averages 10 microseconds, you are wasting about 1 percent of CPU time on pure scheduling overhead. At 100 microseconds per quantum, that jumps to 10 percent. The math is straightforward but ignored. Fairness in round robin is distributional, not guaranteed. It assumes all threads areCPU-bound and of equal priority. As soon as you introduce I/O-bound threads, mixed-priority workloads, or threads that block on locks, the fairness model starts to distort. A thread that frequently blocks and re-enters the ready queue will appear more often than a thread that runs to completion each cycle. This is by design in most implementations. The scheduler rewards threads that yield the processor voluntarily.
I encountered a specific edge case that illustrates this distortion. We had a worker pool processing network packets where some threads were blocked waiting for DMA completion and others were purely computational. The I/O-bound threads were getting disproportionately more CPU time because they cycled through the queue faster. The fix was not to change the scheduler. It was to use scheduling priorities to separate the real-time packet processing path from the batch computation path, then allocate time quanta independently per priority class.
Get the Full Details

Real-Time Considerations
Standard round robin scheduling is inadequate for hard real-time systems. The latency variability introduced by the queue rotation means you cannot guarantee a maximum response time. If your thread is at the back of a queue with 31 other threads and each has a 1-millisecond quantum, your worst-case wait is 31 milliseconds before you get your first turn. That is unacceptable for audio streaming, industrial control loops, or any system with sub-millisecond timing requirements. Real-time operating systems address this by combining round robin within priority levels with strict priority preemption between levels. A real-time thread at the highest priority will preempt any round-robin scheduled thread at a lower priority, regardless of where it sits in the queue. Within its own priority level, it still gets a round-robin quantum, but the higher-priority work never has to wait for the lower-priority queue to drain. The tradeoff is complexity and the risk of priority inversion. If a low-priority thread holds a lock that a high-priority thread needs, the high-priority thread blocks until the low-priority thread gets scheduled. Round robin does not solve this problem. Priority inheritance protocols do, but they add overhead and are not enabled by default on most general-purpose kernels.
For soft real-time workloads, you can get acceptable performance without full RT patches. I have run production systems with time quants in the 4-to-8-millisecond range and achieved consistent response times under 50 milliseconds for latency-sensitive threads, provided the workload was homogeneous and the machine was not contending across CPU boundaries. Once you cross NUMA nodes or hit contention on shared caches, those numbers degrade unpredictably. Monitor your scheduler statistics. The ps -eo pid,comm,sched,pri,stat command shows you the scheduling policy and priority of every process. Check /proc/sched_debug on Linux for granular per-thread scheduling metrics including wait times, runtime, and quantum consumption.
Implementation Details That Matter
The exact behavior of round robin scheduling varies significantly between operating systems. Linux CFS does not implement pure round robin. It uses a virtual runtime model that approximates fair sharing while supporting variable time slices based on system load. Windows uses a priority-based scheduler with dynamic quantum adjustment. Older UNIX systems implemented pure round robin with fixed quanta. If you are writing software that depends on specific scheduling behavior, assume nothing about the implementation and test on your target platform. Setting scheduling parameters is straightforward on most modern systems. On Linux, you use the sched_setscheduler syscall or the chrt command-line tool. To set a thread to round-robin scheduling with a 5-millisecond priority, you would run: chrt -f 5 your_program
This sets the SCHED_FIFO policy, not round robin. For SCHED_RR you need chrt -r 5 your_program. The numeric value is the priority within that policy, ranging from 1 to 99 on Linux. Higher numbers mean higher priority. Only privileged processes can set real-time policies without capability changes, and even then you need appropriate capabilities or root access. When you set a thread to real-time round robin, the kernel will allocate a static time quantum based on system configuration. The default on many Linux builds is 100 milliseconds, but this can be tuned through /proc/sys/kernel/sched_rr_time_slice_ms. Changing this value affects all real-time round-robin threads system-wide. Do not treat this as a per-application setting. It is a global kernel parameter.
Common Pitfalls
The first pitfall is assuming that round robin scheduling solves resource contention problems. It does not. If two threads are fighting over a single mutex, rotating CPU time between them does not reduce the critical section hold time. It only changes the order in which they contend. Use proper concurrency primitives. Lock-free data structures where possible. Minimize critical section duration. Scheduling policy is a tool for managing CPU time distribution, not a substitute for correct synchronization. The second pitfall is overthinking quantum selection. Most workloads perform adequately with default scheduling parameters. I have seen engineers spend days tuning time slices and scheduler policies for systems that were already meeting their latency targets. The optimization budget is better spent on reducing work, improving data locality, and profiling actual bottlenecks. Benchmark before and after any scheduling change. Use tools like perf sched, pidstat -r, or htop with PID tracking to measure the impact. Raw numbers matter more than theoretical models. There is also a security consideration that rarely comes up. Real-time scheduling policies can be exploited for denial-of-service attacks. A malicious process with the right privileges can set itself to SCHED_RR at priority 99 and effectively starve all other processes on the system. Most Linux distributions disable the ability to set real-time policies for unprivileged users by default. Check your /etc/security/limits.conf and your ulimit -e settings if you are deploying multi-tenant systems. The defaults are usually sane but not everywhere.
Round robin scheduling remains relevant despite the sophistication of modern schedulers because it provides a predictable baseline for CPU time distribution. It is not the most efficient scheduler available. It is not the most precise either. But it is simple enough to understand, debug, and reason about when things go wrong. That matters more than people give it credit for. When your system is exhibiting unexpected behavior and you need to narrow down whether the problem is in your application logic or the OS scheduling layer, knowing how round robin actually works at the kernel level saves hours of investigation time.