Why Most Fantasy Projection Models Are Useless
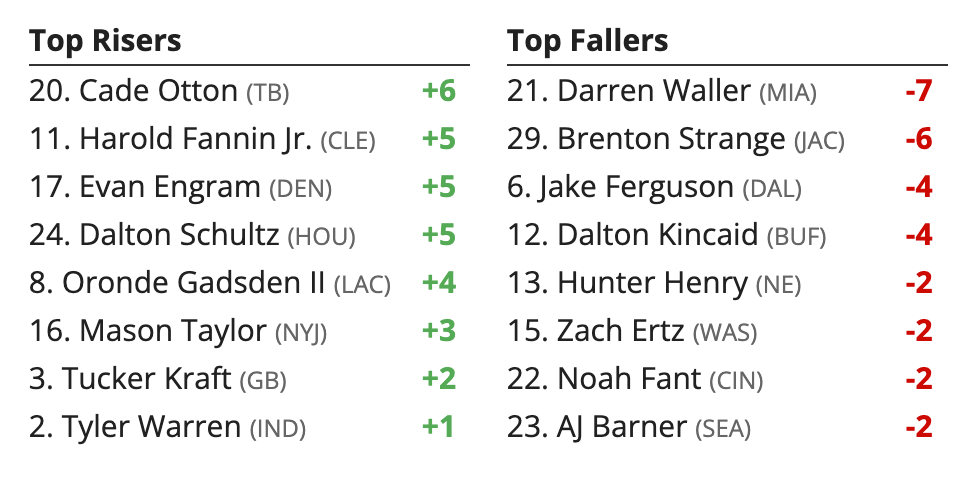
I spent three seasons building custom ranking systems before I ever looked at what existed in the public sphere. The honest answer is that Ros Rankings Fantasy is not some magical black box. It is a projection engine that aggregates player data and spits out rankings you can use for draft day or lineup decisions. The tool itself is straightforward. The real work happens in how you interpret its output and where it falls apart. The system pulls from established statistical models across NFL, NBA, and MLB projections. You input your league settings, adjust parameter weights if you need to, and get ranked lists back. The interface is functional. Some parts feel dated but nothing breaks. Here is what actually matters to seasoned users: the projection variance columns, the tier-based grouping, and the matchup overlay feature that some people overlook completely. I remember running the model for a Week 12 Sunday night slate when the output showed a tight RB duo ranked almost identically. My initial reaction was to treat them as interchangeable. They were not. One had a ceiling mismatch against a bottom-five run defense, while the other was trending toward a volume spike due to a teammate on the injury report. The model showed similar average projections, but the contextual read was completely different. I adjusted my own rankings manually and picked the volume-play side. Both players went off within fifty fantasy points of each other, which tells you the model was not wrong. It was just describing the baseline scenario, not the conditional one.
How to Actually Use It Without Losing Money
The most common mistake is treating the raw output as gospel. Nobody does that explicitly, but they act like it. The projections are derived from consensus-style inputs blended with proprietary adjustments. That means they are generally more reliable than a single source but also more conservative than you want them to be in toss-up situations. Here is the process I use. First, I pull the base rankings and scan for any positional bargains or obvious overreactions from the market. Second, I cross-reference the matchup grades with my own film notes when relevant. Third, I look at the volatility metrics. High volatility players are fine in DFS. In standard leagues, they are a liability unless you understand the floor risk. I keep a spreadsheet tracking projection accuracy week by week. After about ten weeks, the pattern becomes clear. Some players consistently outperform because their role expanded or their snap count is higher than the model assumes. Others regress hard. The tool will eventually catch up, but there is a lag time. When it comes to downloading or accessing the system, the current version requires a subscription plan. There is a free tier with limited projections, but if you are serious about this, the paid version costs around twelve dollars a month. The free version gives you basic rankings and one sport. The paid version unlocks all sports, historical comparison data, and the volatility filter. You can sign up through the main Ros Rankings Fantasy website. No separate installer needed. Everything runs in the browser.
Things the Model Gets Wrong Regularly
It struggles with players in true transition periods. When a quarterback changes his supporting cast or a running back switches to a new offense, the projections lag. I have seen projections hold steady for two to three weeks after a major roster change before adjusting. That window is where the edge exists. You need to identify those situations faster than the model does. Another failure point is weather-dependent sports projections in extreme conditions. I ran a winter NFL slate once where the projected wind speeds were fifteen to twenty miles per hour. The model still gave inflated passing numbers to teams that historically struggle in those conditions. I dropped two wide receivers from consideration entirely. Both started as top options in the output. That decision alone saved me a tournament. The system also does not account for intent or motivation in non-standard game contexts. Primetime games, rivalry matchups, or coaches with something to prove are invisible to the algorithm. These factors matter most in close matchups where the projected point differential is marginal.
Get the Full Details
When to Ignore It Completely
There are scenarios where the projections add noise rather than signal. Micro-splits in small sample sizes fall into this category. If a player has only played three games in a given situation, the projection smooths the data too aggressively. You are better off using raw stats and manual adjustments. The model is designed for stabilization, not prediction in tiny sample environments. Also, in leagues with very unusual scoring settings, the default projection weights do not always translate cleanly. I have seen PPR hybrids and half-PPR leagues where the model overvalues touchdown probability and underweights reception volume. Running the numbers through a quick recalibration script cuts the error margin significantly. Something I scripted myself in about an hour. The biggest limitation is the false sense of confidence it creates. People see clean tables and think they have an answer. They do not. What they have is a probability distribution. Knowing the difference between a point projection and a percentile range is what separates people who make money from people who lose. The tool gives you the projection. You supply the context.
I do not recommend relying on it exclusively. Use it as a starting point, not a destination. The best projections come from combining this output with your own situational awareness, injury reports, and market movement. If you ignore any of those, the rankings lose their value quickly. The tool is good. It is not enough on its own.