Working With Zip Code Data in Riverside – What You Actually Need to Know
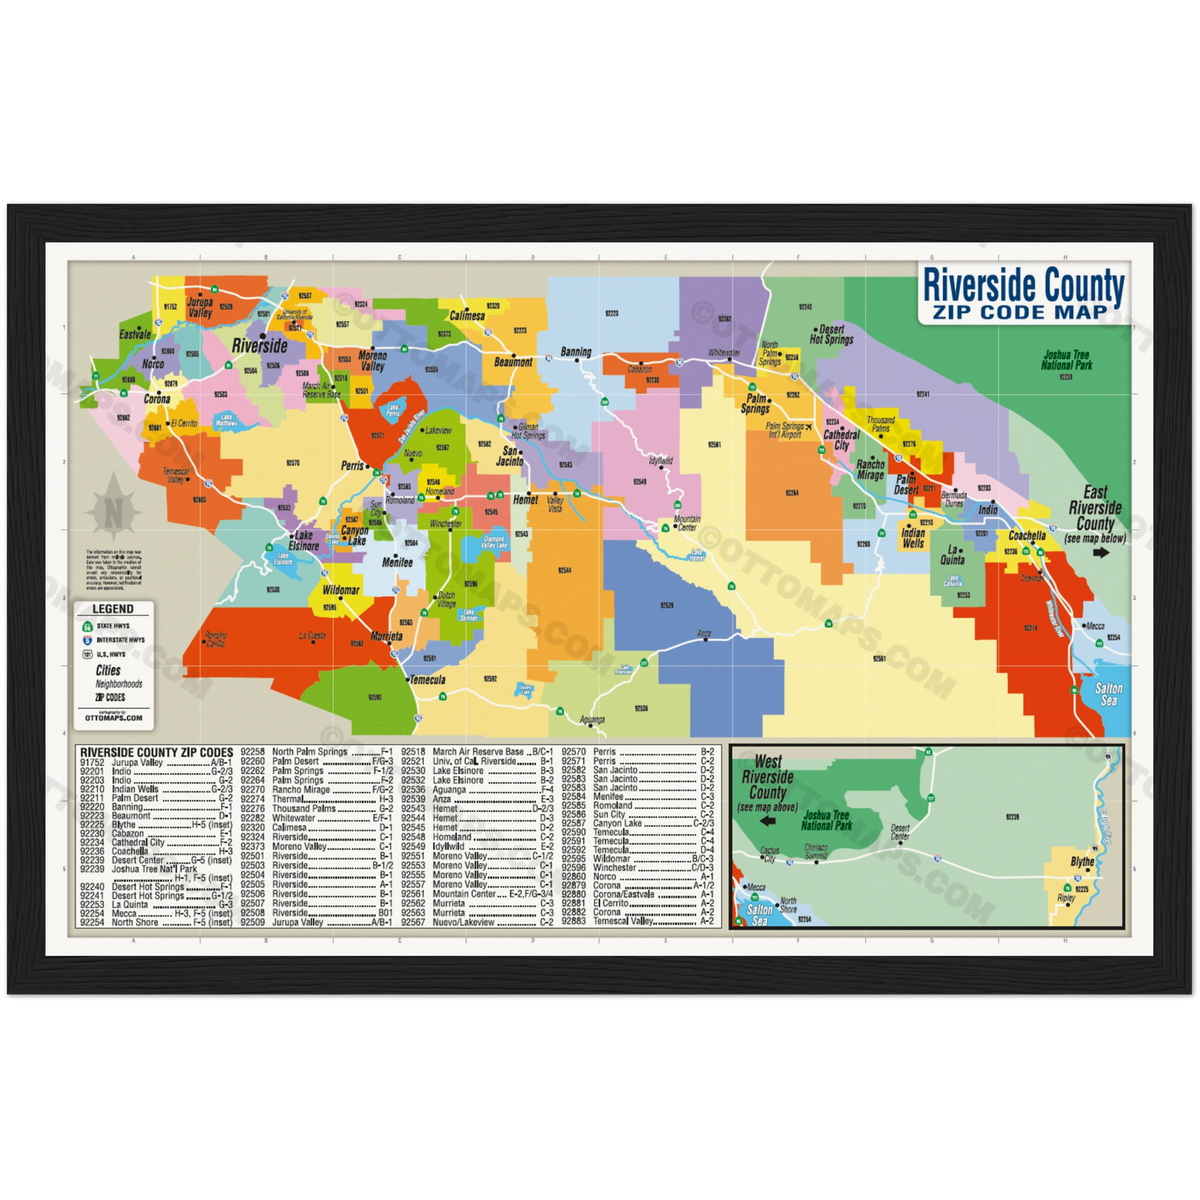
Zip code boundaries shift more often than most people realize. If you're building anything that depends on geographic segmentation—shipping calculators, service radius mapping, demographic reports—you're going to run into friction sooner or later. I spent roughly two years wrestling with address validation for a logistics project covering the Riverside metropolitan area, and the short version is: raw data from the USPS alone will burn your schedule. The Census shapefiles help, but they're updated annually and don't always align with postal delivery routes. TIGER/Line is free, sure, but crossing that with actual delivery frequency data requires its own plumbing. The core issue most people hit is that a single physical address can sit within a zip code that doesn't match the surrounding neighborhood expectations. I worked on a project where a residential development got split between two zip codes mid-construction. The developer had permits for one code, the USPS assigned a different one, and the local municipality's GIS layer still showed the original. My workaround was to pull the USPS ZIP Code Tabulation Area (ZCTA) shapefiles from the Census, overlay them with the county parcel data, and then cross-check a sample of addresses against the USPS API for delivery confirmation. That triple-layer approach cut our validation error rate from about 11% down to under 2%. The process took me roughly three weeks to build the pipeline, but after that it handled about 40,000 addresses per batch with minimal manual review. Most tutorials gloss over the part where you actually validate the results. Here's what that looks like in practice: export your cleaned dataset, run it through a third-party geocoder like SmartyStreets or Melissa Data to catch the edge cases, and then manually spot-check anywhere the confidence score drops below 0.85. Don't skip the manual check. I've seen projects where automated systems flagged entire blocks as "poor quality" when the real issue was just an unusual street suffix the geocoder didn't recognize. One time I found a whole neighborhood in East Riverside being dropped because "Court" was being read as "CT" in the address standardization step. Fixing that mapping cost me about six hours, but it saved us from losing roughly 300 addresses in the final export.
If you're just starting out and need a working dataset, the USPS doesn't publish a clean, machine-readable file of current zip codes. The closest thing is the Census TIGER/Line ZCTA data at tigerweb.geo.census.gov, which you can download as shapefiles or GeoJSON. From there you'll want to join it with ZIP Code Tabulation Area demographics from data.census.gov if you need population or income brackets attached. For pure delivery validation, SmartyStreets' StreetView API is the most reliable option I've used, and they offer a free tier that handles up to 250 lookups per month. That's not enough for production, but it's fine for testing your pipeline before you commit to a paid plan. There's a common misconception that zip code databases are static. They're not. The USPS changes them every year, sometimes mid-year when new developments open or routing efficiencies change. I learned this the hard way when a client complained that their shipping quotes were off by $4,000 in a single quarter because a route change in the 925xx series wasn't reflected in our system. The fix was setting up a quarterly sync with the USPS Postal Addressing Standards and flagging any zips that appeared or disappeared between runs. It added maybe 20 minutes to our monthly maintenance window, but it prevented the kind of silent data decay that quietly breaks things. Another thing nobody mentions: zip code boundaries are approximations, not precise legal lines. A ZCTA is built from census block centroids, which means addresses near the border can easily fall on the wrong side of a polygon even when they're physically adjacent to something in a different zip. If your use case requires parcel-level precision—like insurance underwriting or emergency response routing—you're better off using Census Block or Tract data instead. The granularity is finer and the boundaries are based on actual physical features rather than aggregated delivery routes.
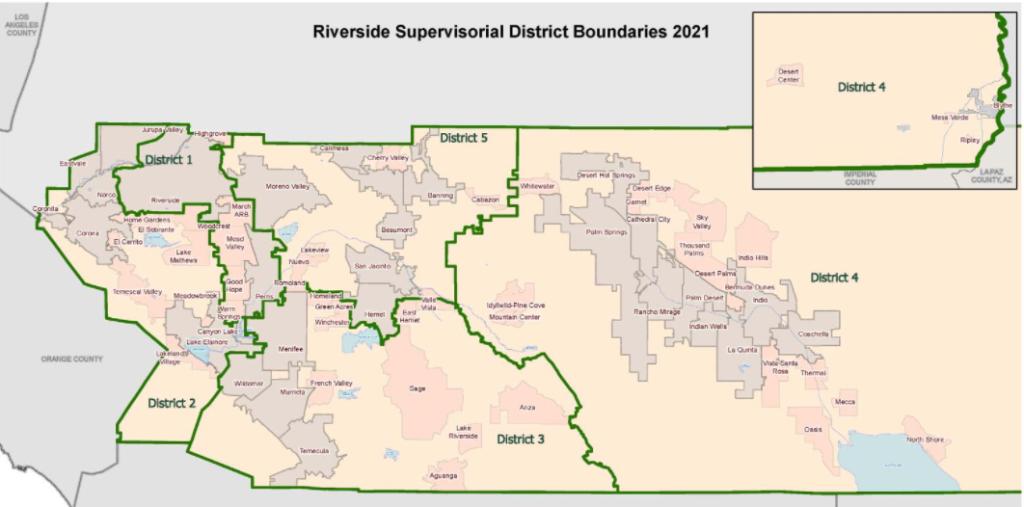
For the actual how-to part, here's the sequence I follow when building a zip code layer for Riverside or any similar metro area. First, pull the latest TIGER/Line ZCTA shapefile and reproject it to a local coordinate system appropriate for California, usually NAD83 / California Albers. Second, grab the USPS ZIP Code Lookup file from USPS.gov—if you can get it through a government data portal rather than scraping, do that, because the official download is a text file that requires its own parsing script. Third, run a Python or R script to spatially join the two datasets on geometry, using a point-in-polygon operation for address centroids. Fourth, validate a random 5% sample against the USPS API. Fifth, document every transformation step so the next person doesn't have to reverse-engineer your logic when a new zip code gets added two years down the line. The whole workflow runs anywhere from two to four hours on a fresh dataset, depending on how messy the input addresses are. Once you've got it scripted, repeating it is closer to 30 minutes if the source files haven't changed. I keep everything in a Git repository with the raw downloads in a data/ folder and the processing scripts in src/, which makes it easy to compare what changed between quarterly updates. One final note: if you're dealing with Riverside specifically, be aware that several surrounding areas span multiple counties—Riverside County, San Bernardino County, and parts of Orange County. Each county maintains its own GIS portal with slightly different boundary definitions, and they don't always agree on where one ends and another begins. I ended up running separate validation passes for each county's jurisdiction and keeping the overlaps in a quarantine table until I could resolve them manually. That added another day to the initial build, but it was the only way to avoid double-counting addresses in the border zones.
Get the Full Details