
Finding Reliable Demographic Data for Richmond Indiana
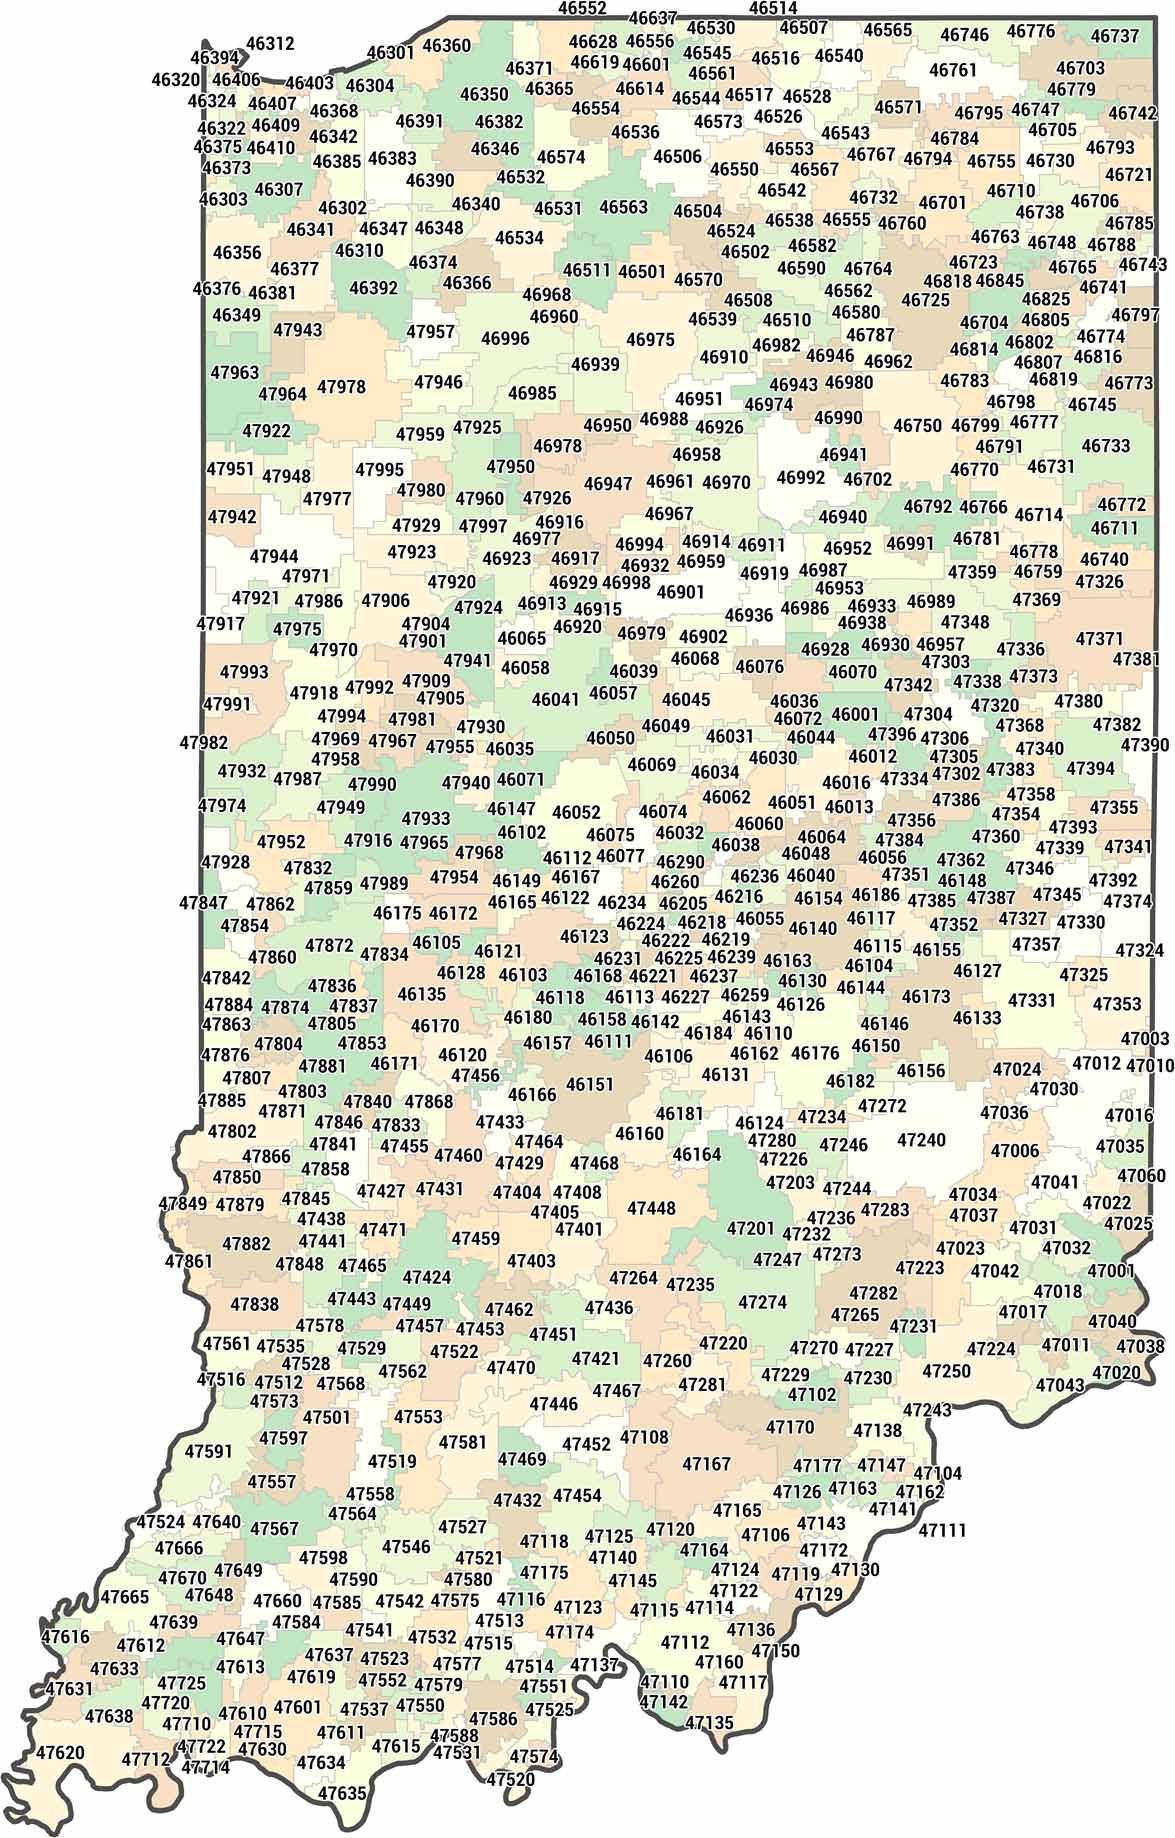
Richmond sits in Wayne County, Indiana, and its primary zip code is 47374. There are a few smaller overlay codes like 47362 and 47363 that cover parts of the surrounding area. Getting accurate numbers for anything past the basic population count is where things start to get fiddly. The most straightforward path is the U.S. Census Bureau's data.census.gov portal. You can pull American Community Survey estimates by zip code tabulation area. For Richmond, the 5-year estimates tend to be more reliable than the 1-year numbers because the sample sizes are bigger. The 1-year estimates for a city this size often come with margins of error wide enough to make them useless for anything precise. I once tried to build a detailed demographic profile for a client who wanted to open a medical facility near Richmond. They needed age brackets, income distribution, and insurance breakdowns. The ACS zcta data gave me the income and age stuff fine, but there was no insurance variable at the zip code level. I ended up cross-referencing the Census with Indiana Department of Health community health profiles and using block-group-level data from the Census Redistricting Data files. It took about four hours instead of the usual forty-five minutes, but the final numbers were solid enough to use in a grant application.
Another thing people miss is that zip codes don't map cleanly to census boundaries. A single zcta can span multiple county subdivisions or even multiple counties. Richmond's 47374 stays mostly within Wayne County, but if you look at nearby codes like 47362, parts of it bleed into Randolph County. That matters when you're comparing median household income against county-level benchmarks because the numbers will be off if you treat the zip code as coterminous with the county. Data sources I typically reach for in order: Census data.census.gov for population, income, education, and housing. Filter by zcta and use the 5-year ACS.
Esri Business Analyst if you have a license. It cleans up the zip-to-census mismatch problem and gives you visualizations that are easier to work with for presentations. Indiana Business Research Center at IUPUI for state-specific economic data and industry breakdowns that complement the federal numbers. U.S. Bureau of Labor Statistics for employment and wage data at the micropolitan statistical area level. Richmond falls inside the Richmond, IN Micropolitan Statistical Area, which includes all of Wayne County and parts of Randolph and Hancock counties.
Get the Full Details
The main limitation across all of these sources is that the ACS samples change year to year. If you're comparing 2018 data against 2023 data, some of the shift is real and some of it is methodological noise. The Census Bureau doesn't publish raw counts for small geographies anymore — everything comes as an estimate with a confidence interval. For Richmond's population around 36,000 to 38,000 depending on which year you look at, the margin of error on income estimates can run ±$2,000 or more at the zcta level. If you need granular neighborhood-level data for Richmond, you'll have to work at the block group level. That means the Census Bureau's Placing America's Communities on the Map tool or the TIGER/Line shapefiles combined with the ACS microdata. It's more work but the precision is significantly better. Free downloadable datasets are available directly from data.census.gov and data.gov. The Census also offers a data visualization tool called DataViewer that lets you export tables as CSV or Excel without writing any code. For people who just need a snapshot rather than an ongoing dashboard, that's usually the fastest route.
One practical tip: always note the vintage of the data you're pulling. ACS tables get revised annually when new samples come in. A number you grabbed in January 2024 might be slightly different from the same number in July 2024. It rarely changes the conclusion, but it matters if someone is going to challenge your methodology.
What the Numbers Actually Show for Richmond
Richmond's population has been slowly declining since the late 1990s peak, which sat around 41,000. Current estimates put it closer to 36,000 to 37,000. The age distribution skews older than the state average — a decent chunk of the population is over fifty-five, which makes sense given the industrial history and outmigration of younger workers over the past couple decades. Median household income in the 47374 zcta runs somewhere in the low to mid-$40,000 range depending on which ACS release you check. That's below the Indiana state median and well below the national median. Poverty rates are higher than both benchmarks, hovering in the high teens for the city overall. Educational attainment follows a similar pattern. A smaller share of residents hold a bachelor's degree compared to the state average, and the high school graduation rate is roughly in line with Indiana's but slightly below the national figure. These aren't surprises for a post-industrial city in east central Indiana.

Housing data tells a clearer story about the economic pressures. Owner-occupied rates sit around sixty percent. Median home values are modest — well under the state median. Rental vacancy and owner vacancy rates are both slightly elevated, which suggests a market that's softening rather than tightening. For anyone evaluating this area for business or development, that's a meaningful signal. If you're pulling this data together for a report or presentation, the biggest time sink is usually the cross-referencing between sources. Census income data doesn't always align with BLS wage data or Esri estimates because they use different methodologies and reference periods. I've found that sticking with one primary source and noting the discrepancies in a footnote saves more time than trying to force perfect alignment across three different datasets. There's also the question of how you define the area. Richmond the city, Richmond the zcta, Richmond the micropolitan area — they're close but not identical. The micropolitan area includes surrounding townships and unincorporated areas that pull the averages up slightly in some categories. Which definition you choose changes the numbers enough that it's worth being explicit about it in whatever document you're producing.
I keep a running folder of all the ACS table numbers I reference so I can go back and verify them if anything gets questioned. It takes about five minutes per dataset to log the table ID, year, geography, and download link. When a client or colleague asks where a specific figure came from three months later, having that trail saves a lot of unnecessary digging.


