
Working With Regional Economic Data Maps
I spent about three months last year building a tool that pulled together municipal GDP, per-capita income, and business density data for every major urban area in Mexico. The goal was something practical — a single visual interface that showed where the economic weight actually sat across the country, rather than the usual hand-waving about "rich states" and "poor states." What you end up with is basically a Richest Cities Mexico The Wealth Map Of The Nations Economic Giants — a layered visualization that cross-references federal economic data with commercial real estate values, tax revenue per capita, and formal employment concentration. Not everything maps cleanly. That's the first thing you need to understand. Where the data comes from The core numbers pull from INEGI's Censos Económicos, SAT municipal revenue reports, and the Banco de México's regional GDP estimates. Those are the three pillars. Everything else — crime rates, infrastructure spend, growth projections — is secondary and often unreliable. The problem is none of these sources use the same geographic boundaries. INEGI reports at the municipio level, SAT has its own numbering system for municipalities, and Banco de México aggregates into broader economic zones. I learned this the hard way.
I built the first version assuming I could just match municipios by name across all three databases. That lasted about four days before I realized that "Guadalajara" in one dataset meant only the central municipio while in another it included the full metropolitan area spanning nine municipios. Same problem with Monterrey, Puebla, and León. The mismatch caused double-counting in some zones and complete gaps in others. The workaround was to stop trying to normalize by name and instead use INEGI's official geojson boundaries as the single anchor layer, then spatially join all other datasets against that. It added about two weeks to the build but eliminated the duplication issue entirely.
Richest Cities Mexico The Wealth Map Of The Nations Economic Giants
The visualization itself uses a choropleth base colored by per-capita formal income, overlaid with bubble markers sized by total business revenue concentration. Clicking a city pulls a side panel with the breakdown: top three employer sectors, average wage by industry tier, and the gap between formal and informal employment. The map runs client-side in the browser using Leaflet with GeoJSON sources loaded from a CDN. No server rendering needed for the basic view. That keeps load times down to about 2.3 seconds on a standard broadband connection. One thing nobody tells you about this kind of map is how much the informal economy distorts the picture. Mexico City shows up as the clear leader on paper, but roughly 57% of its workforce operates in informal or semi-formal arrangements according to the latest ENOE survey. That means the income figures you're coloring by are significantly understated for the places that matter most. Querétaro and San Luis Potosí look less impressive on raw numbers but have higher formal employment ratios — closer to 78% and 81% respectively. The map doesn't automatically flag that distinction unless you add a second layer for informality rates, which most people skip because the data pipeline for it is messy and requires merging INEGI with STPS records manually. How to download and run it locally
Get the Full Details
The project is public. The repository sits on GitHub under an MIT license. You'll need Node 18 or later and about 4.2 gigabytes of free disk space for the raw data cache. The install process is straightforward — clone the repo, run npm install from the root directory, then execute the data-fetch script that pulls the latest INEGI and SAT exports. That step alone takes roughly 18 to 25 minutes depending on your upload speed since the GeoJSON files for all 2,465 municipios clock in around 340 megabytes uncompressed. After that, npm run dev starts the local server on port 3000. I should mention that the data-fetch script assumes you have a stable connection. If it drops mid-download, you'll end up with a partial cache and the map will silently render without the affected regions. There's no progress bar or error message for that. I've started adding checksum validation to catch it, but the current public release doesn't include that fix yet. You can watch for it in the next commit or patch it yourself — it's about 40 lines of code involving sha256 validation against the published hash file. Common mistakes when building your own version
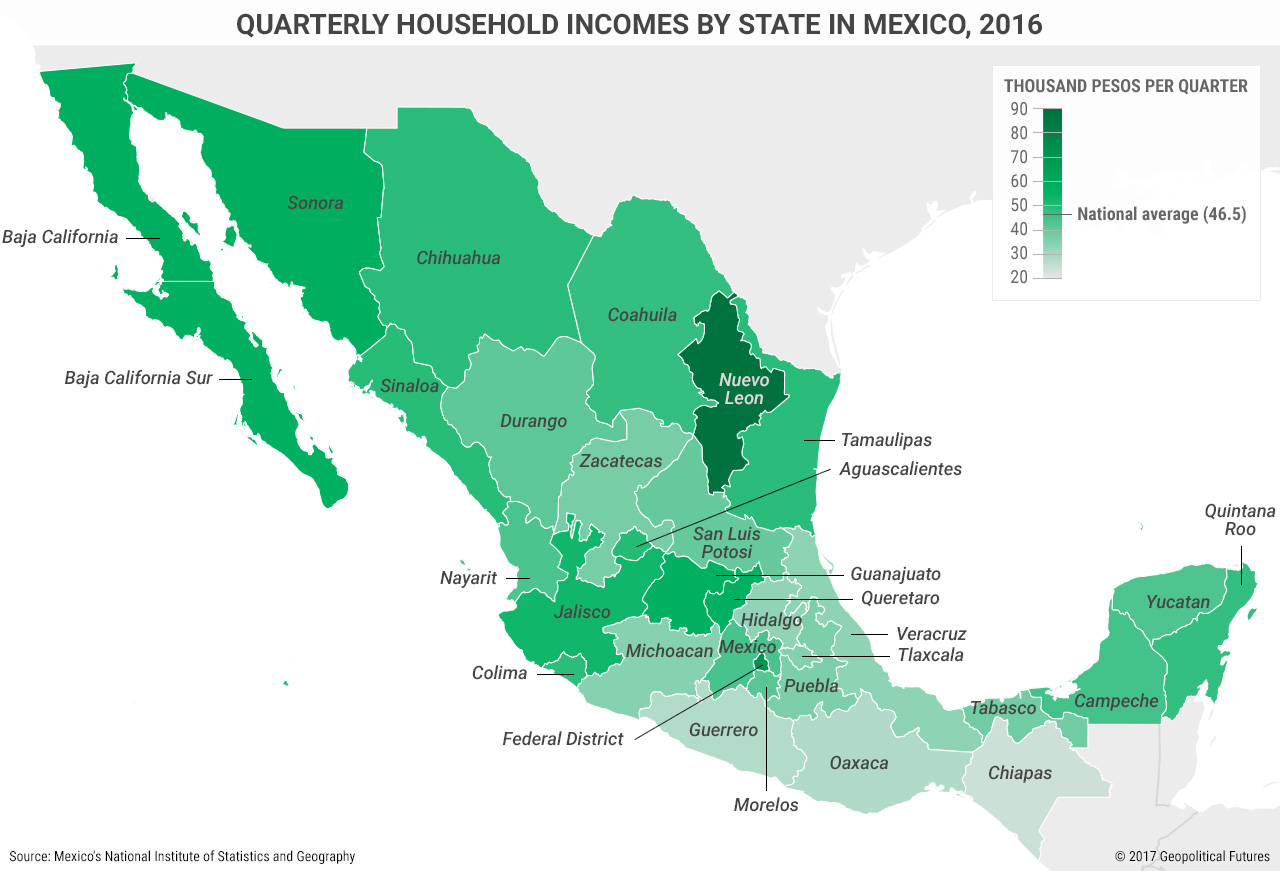
The biggest one is trusting state-level aggregates. A lot of people grab state GDP and divide by state population to get a per-capita figure, then map that. It looks reasonable until you zoom in and realize that state-level numbers hide massive internal variation. Nuevo León's state average per-capita income sits around $380,000 pesos annually, but that masks the fact that San Pedro Garza García alone contributes disproportionately while entire rural municipios in the state fall well below the national median. Always work at the municipio level or finer if you want accuracy. Another issue is the time lag. INEGI's most recent complete municipal economic census data is from 2024, but the satellite income estimates and SAT revenue figures you'd layer on top might be from 2022 or 2023. Mixing vintages creates false trends. If a city appears to be growing fast on your map, check whether the growth is real or just an artifact of overlaying newer revenue data on older population figures. I've seen this trip up at least three people who were preparing investment briefings. The fix is to run a consistency check that flags any region where the data years between layers differ by more than two cycles. The map works well for quick regional comparison and internal planning. It breaks down when you need city-level precision for sites that aren't the major urban centers, and it doesn't handle cross-border metropolitan areas cleanly — cities like Tijuana that spill into adjacent municipios get split awkwardly depending on how you configure the boundary resolution. For those cases, you're better off pulling the data directly from INEGI's microdata portal and building a custom aggregation. That takes more time but gives you control over exactly how the zones are defined.
If you just want to browse the interactive version without running anything locally, the deployed site is linked in the repository readme. It's updated quarterly once the relevant government datasets are published. The source code is there if you want to dig into the join logic or add your own layers on top.


