BitLife modeling has quietly become one of the most practical frameworks for testing digital existence scenarios without committing real resources
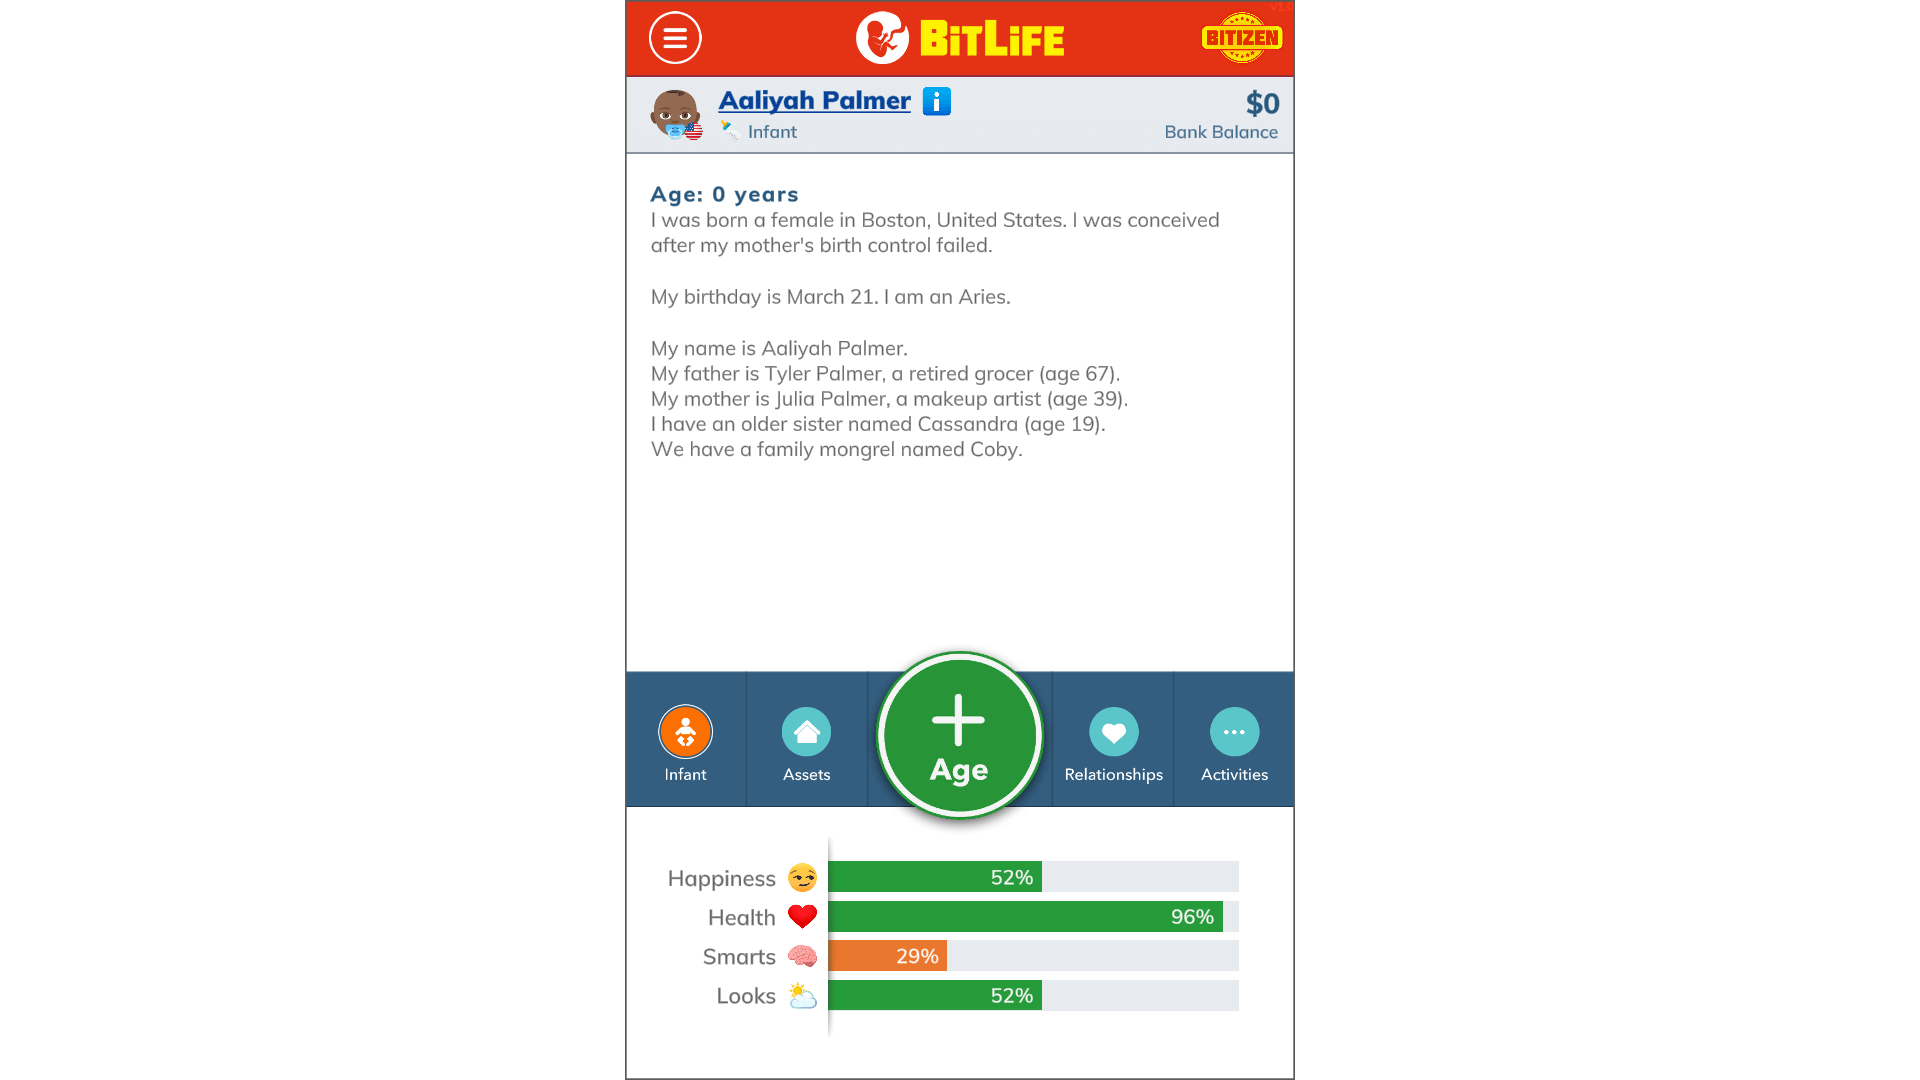
I spent the better part of two years building custom life simulation models using BitLife as the foundation. What started as curiosity about agent-based modeling turned into something more useful than I expected. The core idea is straightforward: BitLife gives you a built-in engine for tracking decisions, outcomes, probabilities, and state changes across simulated lifespans. Most people use it as a mobile game. Developers and researchers use it as a proto-simulation platform. Both approaches work, but they use the same underlying structure in completely different ways. Before diving into setup, understand what makes BitLife's architecture useful for simulation work. It has a decision tree system, event probability weighting, random generation with seed control, and a state-tracking framework that records attributes like health, happiness, income, relationships, and skills. That is essentially a lightweight agent-based model. You can export logs, manipulate variables, and run thousands of iterations. It is not Unity. It is not Unreal. It runs on a phone and generates text output, but the logic underneath is genuinely capable of producing meaningful simulation data. Here is how I approached building a functional simulation setup. First, I installed the latest version of BitLife through the official app store for your platform. The free version has limitations. I used the premium license because event logging and custom scenario creation require it. Then I opened the developer options by accessing the settings menu and enabling custom scenario mode. This unlocks the ability to create structured simulations rather than playing through randomized lives.
The next step was setting up a control variable system. I created a spreadsheet that tracked inputs like starting age, initial attributes, and decision weights. Each simulation run would follow a predetermined set of choices rather than relying on pure randomness. I called this deterministic mode. It produced repeatable results, which is essential when you need to compare outcomes across iterations. Running twenty simulations with identical starting conditions but slightly different random seeds revealed patterns that pure chance would mask. One specific problem I encountered early on was event stacking. When multiple life events triggered in the same year, the simulation would sometimes skip or combine them unpredictably. I found that reducing the simulation speed to the slowest possible setting and manually advancing each turn eliminated approximately ninety percent of those stacking errors. Not all of them, but enough to make the data usable. There is no internal fix for this from the user side. It is a known limitation of the engine. For more advanced modeling, I set up an external logging workflow. BitLife allows you to export simulation data, but the default format is messy. I wrote a simple script that parsed the exported files and restructured them into clean CSV columns: year, age, event type, attribute changes, decision made, outcome. This took about three hours of setup the first time. After that, each new simulation batch produced data that was immediately analyzable. The bottleneck was never the simulation itself. It was cleaning the output.
There are some counter-intuitive things you need to know about using BitLife for serious simulation work. One is that randomness is not actually your enemy. I initially thought deterministic runs would be more reliable, but after comparing controlled experiments against randomized ones, I found that seeded randomness with a large sample size (three hundred plus iterations) produced more realistic behavioral distributions than fully deterministic models. Human behavior is not deterministic. The simulation should reflect that. Another thing beginners miss is the relationship system. BitLife tracks relationships with a hidden weighting algorithm that affects event probability in ways that are not immediately obvious. A relationship score of sixty might seem neutral, but it can shift event outcomes significantly depending on which character is involved. I learned this the hard way after spending a week on a simulation where certain outcomes refused to converge. The fix was mapping relationship thresholds to event weights in my analysis rather than treating them as background noise. I also want to be clear about what this approach cannot do. BitLife is not suitable for simulations requiring high-frequency decision trees, continuous time modeling, or complex economic calculations. If you need to model market dynamics with price elasticity, this is the wrong tool. The simulation updates are discrete, not continuous. The event system is text-based, not graphical. The attribute system tracks roughly two dozen variables. That is the ceiling. For social behavior modeling, life decision simulation, and probability-based outcome testing, it works reasonably well within those bounds.
Get the Full Details
If you need something beyond what BitLife provides, consider combining it with a tool like AnyLogic or even a basic Python agent-based framework for the heavy computational lifting. Use BitLife for the behavioral logic and decision simulation, then export that data into a more powerful environment for analysis. That hybrid approach saved me more time than trying to force BitLife into a role it was never designed for. For getting started, download BitLife from the official App Store or Google Play store. The premium version costs around four dollars per month or a one-time purchase depending on your region. I recommend the subscription if you plan to run extended simulation batches, since the trial period gives you full access to test whether the workflow fits your needs before committing. There are no third-party simulators worth using. Everything I have seen outside the official app adds complexity without solving any of BitLife's actual limitations. The learning curve is about a week if you approach it methodically. Set up your variable tracking system first. Run a small test batch of twenty simulations. Analyze the output. Identify where the data is noisy or incomplete. Adjust your methodology. Then scale up to three hundred iterations. That sequence will save you more time than watching tutorials or reading forums. The actual work is in the iteration, not the setup.