Getting Your Synthesis Right Before You Even Think About Biology
The field around polymers of nucleic acids has moved from academic curiosity to something you can actually buy as a CDMO service in months. I spent years watching people try to skip the chemistry because they were excited about the biological readout. It never works out that way. When I first started working with chemically modified oligonucleotides, I assumed 2'-O-methylation was straightforward enough to gloss over. I ordered a 22-mer with phosphorothioate linkages, resuspended it, and ran it through a standard LNP formulation protocol. The particle size came back at 180 nanometers instead of the usual 85. The zeta potential was all over the place. I spent three weeks troubleshooting before I realized the supplier's quality control report showed a 4% failure to couple on the second nucleotide. That 4% was enough to wreck the entire formulation. What should have been a one-day experiment took a month. The industry standard now for therapeutic polynucleotide work involves a combination of backbone modifications, sugar modifications, and base modifications working together. You don't pick one and move on. You need the phosphorothioate backbone for nuclease resistance in serum, but then you also need 2'-fluoro or 2'-O-methoxyethyl modifications at specific positions to tune binding affinity and reduce off-target immune activation. The positions matter more than you'd think. Modifying the wrong nucleotide in a 20-mer can increase your IC50 by tenfold without any obvious change in melting temperature.
Revolutionizing The Future Of Medicine Unlocking The Potential Of Polymers Of Nucleic Acids
The practical work starts with defining what you actually need the polymer to do. Most people jump straight to sequence design, but that's the wrong order. You need to know your delivery route first. Intravenous delivery demands something very different from intrathecal or topical application. The chemistry that works for a liver-targeted siRNA through GalNAc conjugation falls apart completely if you're trying to get something across the blood-brain barrier or into lung tissue. For sequence design, the tools have improved dramatically. Tools like IDT's OligoAnalyzer or custom scripts using nearest-neighbor thermodynamics models can predict melting temperatures and secondary structure within a reasonable margin. But here's what most people miss: the models assume standard B-DNA geometry. Once you introduce locked nucleic acid modifications or peptide nucleic acid backbones, those predictions become unreliable. You need empirical validation at that point, not computational shortcuts. I run a simple check before committing any sequence to synthesis. I order a short primer panel for PCR-based cloning if I'm building longer constructs, and I always include a negative control with a known stable sequence from the literature. It costs maybe fifty dollars extra and saves you from discovering that your construct has formed a stable hairpin that no polymerase can read through. I've seen that error cost teams months of work because nobody checked the secondary structure before ordering custom genes.
The manufacturing side is where things get expensive fast. Solid-phase synthesis for oligonucleotides above 30 nucleotides has a hard limit on yield. Each coupling cycle runs somewhere between 96 and 99% efficiency. Stack those cycles and you're looking at 70% or less full-length product for a 40-mer. That's why most commercial antisense drugs stay under 30 bases. If you need longer constructs, you're moving into enzymatic synthesis or gapmer designs where you combine chemically synthesized regions with enzymatically produced spacers. Purification is non-negotiable. Reverse-phase HPLC is the standard for modified oligos, but it requires you to know your modification pattern before you run it. If you're doing a new modification, you'll need to characterize a test run by mass spectrometry first. MALDI-TOF gives you quick confirmation of molecular weight. Electrospray ionization LC-MS gives you better resolution for mixtures. Running purification blind on a new construct is a reliable way to lose your entire batch.
Get the Full Details
Delivery Systems and What Actually Goes Wrong
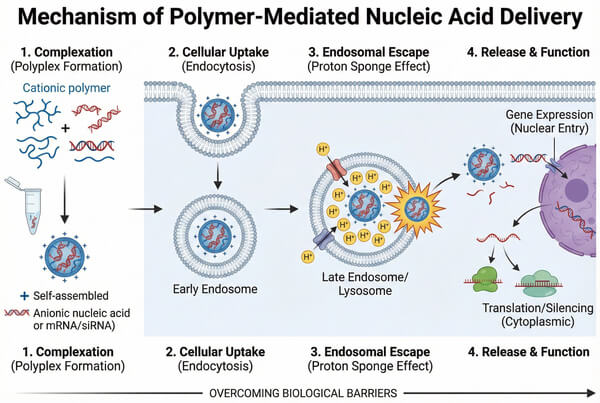
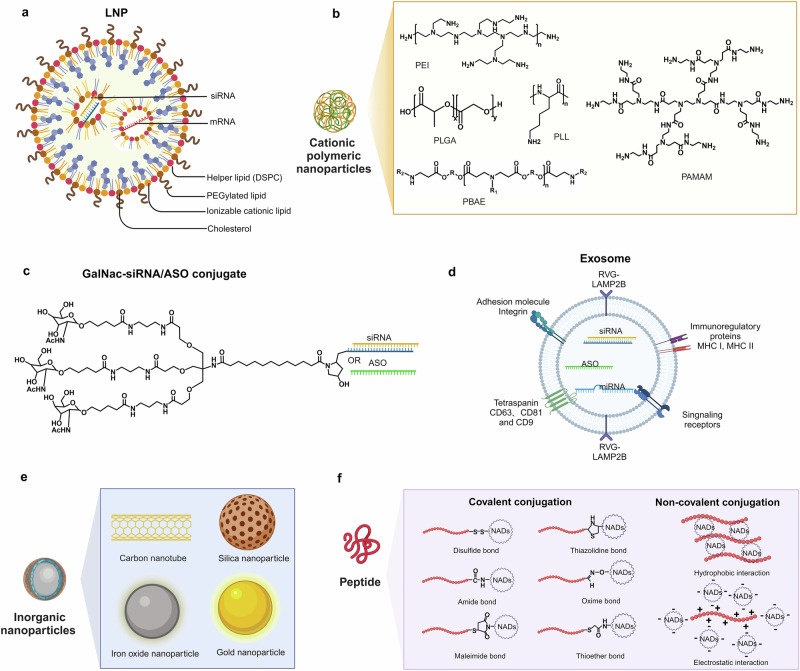
Lipid nanoparticles remain the dominant delivery platform for nucleic acid therapeutics. The standard formulation uses ionizable lipids that become positively charged at low pH during mixing, allowing them to associate with the negatively charged nucleic acid. Then you adjust the pH back to physiological range and the lipids neutralize, encapsulating the payload. It sounds simple. Getting reproducibility between batches is genuinely difficult. The microfluidic mixing approach has largely replaced manual syringe-based methods. You control the flow rates of the aqueous phase containing your nucleic acid and the ethanolic phase containing your lipids. The mixing ratio and total flow rate determine particle size. A typical setup runs the aqueous phase at 10 milliliters per minute and the lipid phase at 30 milliliters per minute through a T-junction micromixer. Those numbers will shift depending on your lipid composition and nucleic acid length. You need to empirically optimize for each new formulation. One thing nobody warns you about: the ethanol concentration matters more than the lipid-to-nucleic acid ratio. If your final ethanol concentration after mixing exceeds 10%, you'll see aggregation within hours. Most protocols dilute immediately after formation, but if you're working at scale, you need to account for the dilution factor in your initial volumes. I once ran a 100-milliliter batch and forgot to adjust the starting concentrations for the downstream dilution. Every particle in that batch was 200 nanometers or larger. It was unusable for injection.
For GalNAc-targeted delivery to the liver, the conjugate needs to be positioned correctly. You're not just attaching the targeting ligand to any position on your oligonucleotide. The triantennary GalNAc conjugate works best when attached to the 3' end of the sense strand through a spacer linker. Put it on the wrong end and your receptor binding drops significantly. I learned this the hard way when a collaborator moved the conjugate to the middle of the sequence "to reduce steric hindrance." The in vivo knockdown went from 90% to 15% overnight.
Immunogenicity and the Hidden Problems
Native unmodified RNA triggers innate immune pathways through Toll-like receptors and RIG-I-like receptors. That's why the early mRNA vaccine attempts failed to produce meaningful protein expression in vivo. The chemical modifications solve this problem, but they introduce their own complications. 5-methylcytidine and pseudouridine reduce immunogenicity, but they also shift your codon usage and can affect translation efficiency in ways that aren't obvious from sequence analysis alone. You need to test immunogenicity early, not after you've spent six months optimizing knockdown. I run a simple human peripheral blood mononuclear cell assay with cytokine profiling before moving to animal studies. TNF-alpha, IL-6, and IFN-alpha are the markers that tell you whether your construct is going to cause problems. A construct that looks perfect in a cell line will often trigger a strong cytokine response in primary human cells. The reverse is also true sometimes. Don't skip this step. There's a trade-off between modification density and potency that most papers don't emphasize. Fully modified backbones reduce immunogenicity but can reduce target binding affinity if you're not careful about which positions you modify. The consensus approach for antisense oligonucleotides is a gapmer design: chemically modified wing regions flanking an unmodified DNA gap. The DNA gap allows RNase H recruitment while the modified wings provide stability and reduce immune recognition. This architecture has become standard for good reason.

Quality Control Standards
You cannot skip endotoxin testing. Polymers of nucleic acids are routinely contaminated with bacterial endotoxins during synthesis and purification. Even trace amounts cause fever and inflammatory responses in vivo. The USP <85> test is the baseline, but it has limitations at very low endotoxin levels. For injectable therapeutics, you typically need to demonstrate endotoxin below 0.5 EU per milligram of product. I use the kinetic chromogenic method because it's more sensitive than the gel clot method and gives you actual numerical values instead of a binary pass-fail result. Sequence verification by Sanger sequencing works for cloned constructs. For chemically synthesized oligonucleotides, you need capillary electrophoresis and mass spectrometry. CE confirms purity and identifies truncated sequences. MS confirms the exact molecular weight including all modifications. Running both gives you confidence that your product matches what you ordered. I've had suppliers deliver products where the modification pattern was slightly wrong despite the certificate of analysis saying otherwise. Always verify independently. Storage conditions matter more than people expect. Lyophilized oligonucleotides are stable for years at minus 80 degrees Celsius. Once you resuspend them in buffer, the clock starts ticking. I store working aliquots at minus 20 degrees in TE buffer with 0.1 millimolar EDTA. Avoid repeated freeze-thaw cycles. Each cycle degrades maybe one percent of your sample over time, but if you're working with low-concentration therapeutics, that adds up. I keep master stocks at minus 80 and only aliquot what I need for a single experimental cycle.
Where the Field Is Actually Going
The next practical advance isn't a new modification chemistry. The current modifications already cover most use cases. The bottleneck is manufacturing scalability and cost. Producing a clinical-grade batch of a 25-mer chemically modified oligonucleotide can run anywhere from fifty thousand to two hundred thousand dollars depending on the modification complexity and purification requirements. That cost structure doesn't change much regardless of the therapeutic application. Enzymatic oligonucleotide synthesis is the technology most people are watching. It bypasses the solid-phase chemistry limitations entirely. You build sequences enzymatically using nucleotide triphosphates and polymerase variants. The yield per reaction is higher and the sequence length limit is less of a concern. But the technology isn't mature enough for routine GMP production yet. Most enzymatic synthesis products still require additional purification steps that add cost and reduce yield. It's promising but not ready for prime time in a clinical manufacturing setting. The application space is widening beyond gene silencing and replacement therapy. Aptamer therapeutics are seeing renewed interest because they don't require intracellular delivery. They work extracellularly by binding protein targets with antibody-like specificity but with much smaller molecular weight. MGX-102 targeting angiopoietin-2 for sickle cell disease is one example moving through clinical trials. The manufacturing challenges are different but not easier. Aptamers require different purification and stability considerations compared to antisense oligonucleotides.
If you're entering this space, start with a well-characterized sequence from the literature and reproduce the published results before modifying anything. The field is full of people who changed three nucleotides and wondered why their construct stopped working. The modifications are subtle. The biology is unforgiving of mistakes. I wish someone had told me that when I was starting out.