Setting Up Wmt Scheduler for Production Workloads
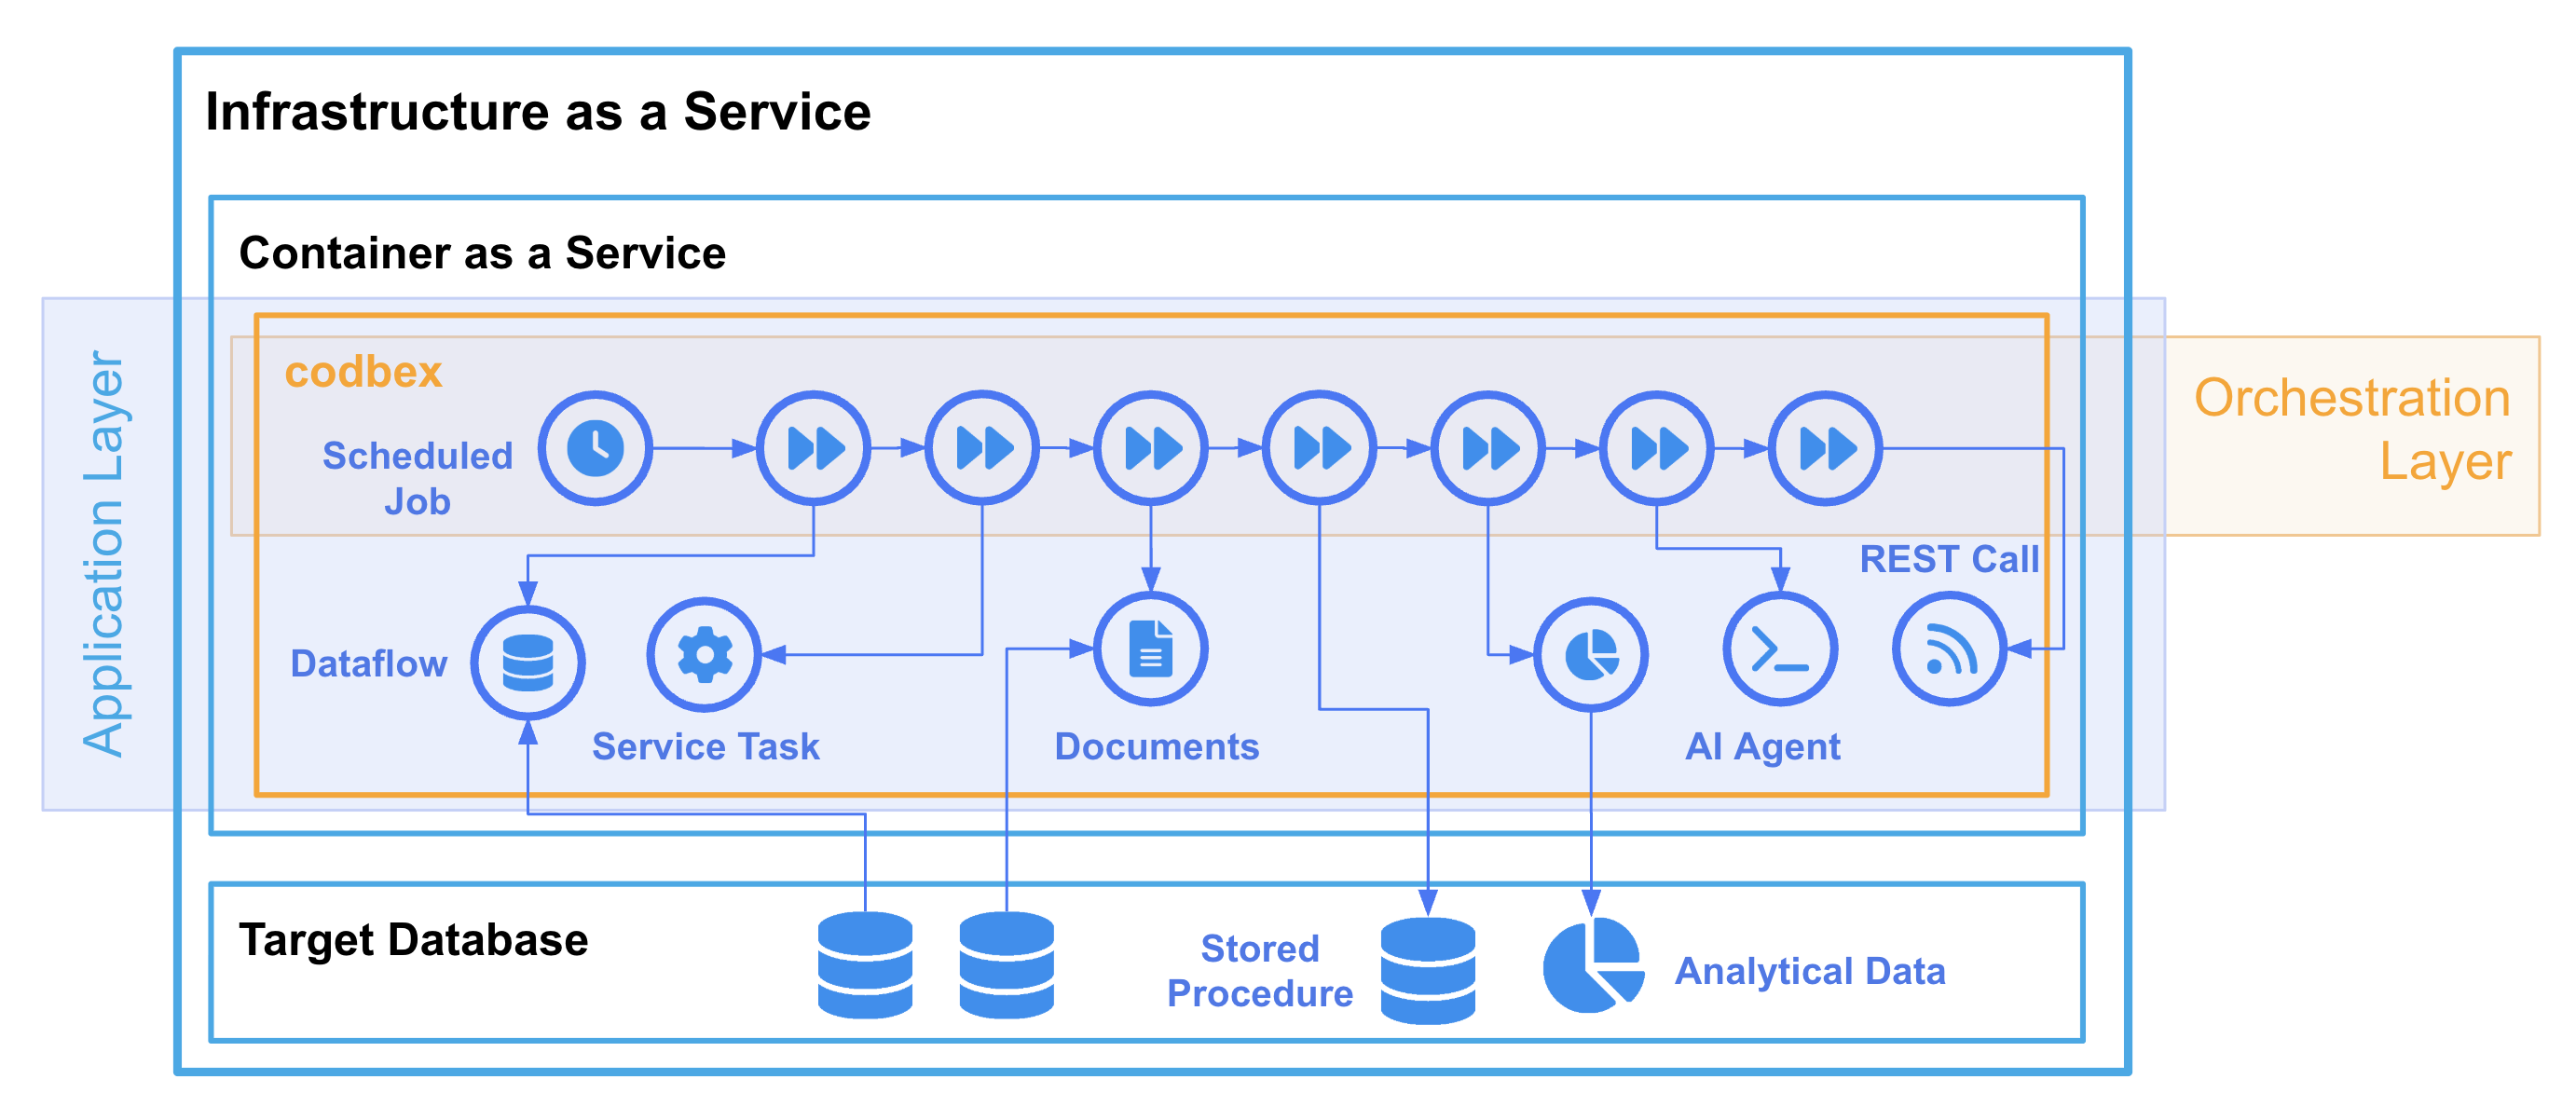
I've been wrestling with task orchestration tools since the days when we still manually configured cron jobs and hoped nothing collided. When Wmt Scheduler first came up on my radar, I was skeptical. Another orchestration layer on top of everything already running. But after actually deploying it across a fleet of servers handling thousands of daily workflows, it turned out to be one of the few tools that doesn't require a certification to operate. That's worth something. Wmt Scheduler works by building directed acyclic graphs of tasks, where each node represents an individual job and the edges define dependencies. Unlike some of the heavier platforms you'll see recommended everywhere, it stores these graphs in a compact JSON format and executes them using an internal worker pool. The configuration lives in what they call a workflow definition file, and you can version-control it alongside your codebase. I keep mine in the same repo as the application logic because deploying a workflow without seeing the code that backs it always leads to confusion down the line. The installation is straightforward on any standard Linux distribution. You pull the binary from their release page, drop it into your path, and run the init command to generate the default config. That config file sits at /etc/wmt/scheduler.yml by default, and it controls everything from worker count to retry policies. Don't skip reading through the full config before you start. The defaults are reasonable, but they assume a single-node setup, and if you're running anything larger than that, you'll want to adjust the concurrency settings immediately. I started with the defaults once and watched my disk I/O spike to 98% utilization because every worker was hitting the database at the same time.
One thing nobody tells you about Wmt Scheduler: the retry mechanism isn't the same as a simple backoff loop. When a task fails, Wmt checks whether the failure was transient or permanent based on the exit code and a set of failure heuristics you configure. A timeout gets retried with exponential backoff capped at 4 hours. A permission error does not get retried at all, which is the correct behavior but caught me off guard during a deployment when a service account had the wrong LDAP group membership. The scheduler just marked the task as failed and moved on, leaving me staring at an empty execution log wondering why nothing happened for three hours.
Configuring Task Dependencies and Scheduling
Defining dependencies in Wmt uses a declarative syntax inside the workflow definition. You reference upstream tasks by their unique ID, and the scheduler resolves the execution order at runtime. It's not a static plan, which matters because things fail in production and the graph adapts. If task B depends on task A, and task A is skipped due to a conditional, then task B gets skipped too. That's different from some other tools I've used where a skipped upstream still triggers downstream execution with empty inputs. For scheduling, you can use standard cron expressions or the built-in interval-based scheduler. The cron expressions work fine for fixed-time jobs. The interval scheduler is where Wmt actually earns its keep. It tracks wall-clock time between completions rather than wall-clock time between starts, which means if a task takes longer than expected, the next run doesn't get squeezed in prematurely. I've seen this catch other people off guard. There's a difference between "run every 6 hours" and "run 6 hours after the previous completion," and Wmt's interval mode does the latter by default. If you need the former behavior, you have to explicitly set the scheduling mode in the task config. Parameter passing between tasks happens through the workflow context object. Each task can read values written by upstream tasks, and you define the schema in the workflow definition. The context is immutable at the task level, so if your upstream task writes a value and your downstream task tries to modify it, the write silently fails. This is actually a feature, not a bug, because it prevents tasks from accidentally stepping on each other's data. But it means you need to plan your parameter flow carefully during the design phase. I learned this the hard way when a monitoring task started reporting stale metrics because a dependency had written the same key twice with different timestamps and the scheduler picked the first value.
Get the Full Details

Monitoring, Debugging, and What Breaks
The built-in dashboard gives you a timeline view of active and completed workflows. It's functional but not pretty. The API endpoint at /api/v1/executions returns structured JSON with execution metadata including start time, end time, duration, and failure reason if applicable. I write a thin wrapper around that endpoint that aggregates execution times across workflows and surfaces them in our existing monitoring stack. Took about half a day to build. Worth it. When things break, the execution log is your first stop. Each task invocation gets a unique trace ID that persists across retries and worker processes. Search by that ID and you can reconstruct exactly what happened. The log level is configurable in the scheduler config, but default to INFO and only switch to DEBUG when you're actively troubleshooting. The DEBUG logs are voluminous, and I mean really voluminous. A single workflow run with twenty tasks can generate megabytes of debug output in under a minute. I learned that lesson after a misconfiguration flooded our log rotation and took down the syslog daemon on the host. Here's a specific edge case: Wmt Scheduler doesn't handle long-running tasks well if you don't configure heartbeat timeouts properly. A task that runs for several hours without producing output will eventually trigger a worker timeout and get killed, even if it's still working correctly. The default heartbeat interval is 300 seconds, and the inactivity timeout is 600 seconds. If your task needs to run longer than that without writing to stdout, you either need to add periodic output or override those settings in the task config. I had a batch data migration task that ran for 4 hours and got killed at the 10-minute mark because it was reading from a slow source and producing no output during that window. Setting the heartbeat timeout to match the expected task duration fixed it, but it's the kind of thing that won't occur to you unless you've already lost data.
Scaling Beyond a Single Node
Multi-node deployments require a shared backend store for the execution queue. Wmt supports PostgreSQL and Redis out of the box. PostgreSQL is the safer choice if you need transactional guarantees on workflow state. Redis is faster but you lose some durability if the node goes down mid-execution. I run PostgreSQL in production and Redis only for development because the startup cost of the database is negligible compared to the cost of a corrupted execution log at 2 AM. Worker nodes connect to the central scheduler over TCP, and you configure the connection string in each worker's config file. There's no auto-scaling built in. If you need more throughput, you add workers manually or script it through your infrastructure tooling. The scheduler itself is mostly stateless once the queue backend is configured, so you can scale it horizontally too. I've seen setups with four scheduler instances behind a load balancer and twelve worker nodes without issues. The bottleneck is usually the backend store, not the scheduler or the workers. There are limitations worth being honest about. Wmt Scheduler doesn't have native support for GPU task prioritization, which matters if your workflows involve ML training or inference. It also lacks a visual workflow editor, so everything is defined in YAML. If your team prefers drag-and-drop interfaces, you'll be writing config files whether you like it or not. The plugin system exists but is relatively young, and third-party integrations are thinner than what you'd find in the more established platforms. For a core task orchestration layer handling ETL jobs, file transfers, and service orchestrations, it does the job reliably. For everything else, you'll probably need to build something custom or bolt on another tool.
If your workflows are straightforward sequential or branching DAGs with moderate complexity, Wmt Scheduler is a reasonable choice. The documentation is adequate, the community is small but responsive on their GitHub issues, and the binary itself is stable. If you need real-time collaborative editing of workflows, event-driven architectures with complex routing, or enterprise-grade audit logging out of the box, look elsewhere. But for teams that want something that gets out of the way and runs workflows without requiring a dedicated operations team to maintain it, this is one of the fewer options that actually delivers on that promise.